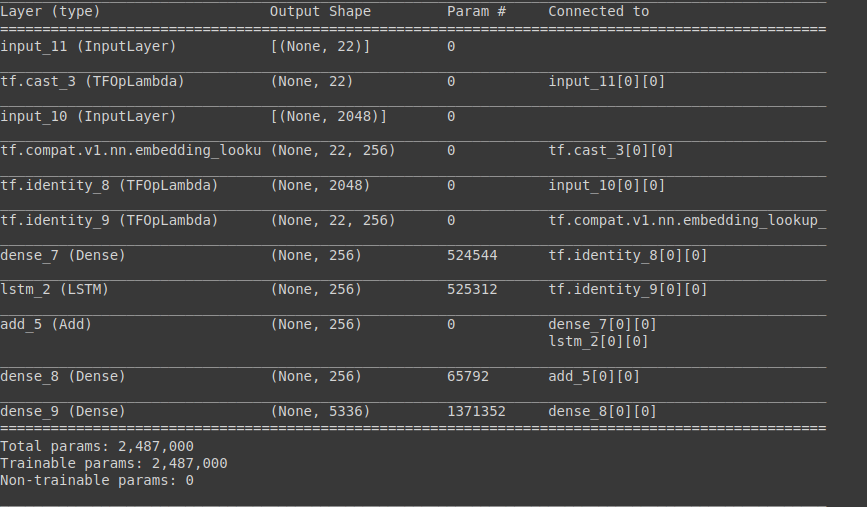
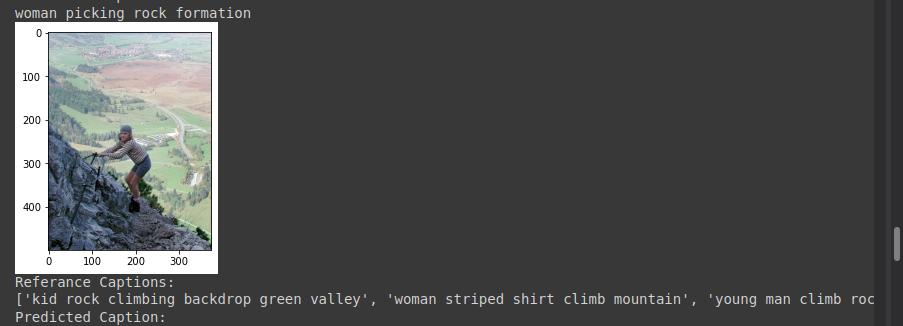
Image Captioning is one of those projcts that blends the Natural langauge Procssing and computer vision. It involves training of the neural networks on images and correspoding targets text sentences ( can be more than one). Further more this Models is trained on the flicker 8k dataset which Comprise of 80000 images and contains 5 captions for each image.
Dataset which is used comprises of different scences and all natural images. The captions in this dataset are around 40,000 which is 5 captions for each image. And all are natual spoken langauge regarding any scence or image. It was collected in 2015 to investigate multimodal learning schemes for unsupervised speech pattern discovery.
Dataset from Kaggle datasets:- https://www.kaggle.com/adityajn105/flickr8k/activity
-
1. Text Preprocessing * a. Text cleaning * b. Removing Punctuation ('!"#$%&'()*+) * c. Removing stopwords * d. Lemmatize the words * e. Tokenize the words of each captions * f. pad the seqences and create the numpy array -
2. Tokenizing the text to sequencs Using Tokennizer () -
3. Creating Word2Vec Embedding for embedding layer in Neural Network
a. Converting images to array of RGB using ResNet50 pretrained model just by removing the last layer of the model.