
Browse a computation as if it were a stored dataset: in any viewer, at any scale, before anyone has computed it.
chunkmirage serves virtual datasets that look, to any HTTP-capable viewer or library (Neuroglancer, BigDataViewer/Fiji, vizarr, napari, webKnossos, zarr-python, dask, tensorstore, ...), like ordinary Zarr v2, Zarr v3, N5 or Neuroglancer precomputed volumes, pyramid of levels included. Nothing exists on disk. Each chunk is computed when a viewer asks for it: read from a real source (zarr, N5, precomputed, HDF5, GeoTIFF; local, S3, GCS or HTTP) or generated, pushed through a pipeline of ops, encoded in the format the client asked for, and cached per stage. The chunks on screen are computed first, at the level shown, and work nobody waits for any more is dropped, which is what panning and zooming over an expensive op needs. Zoomed out, you see the ops run on that coarser level (an op bound to one resolution runs there and is downsampled), so a coarse view is a preview of the fine result, not its exact downsample. And since every stage is cached by what made it, changing a parameter recomputes only the stages after it, and viewers refetch.
▶ Try the demos in your browser, nothing to install. Every chunk on screen is computed in the page by chunkmirage's own Python, from public data, as the viewer asks for it.
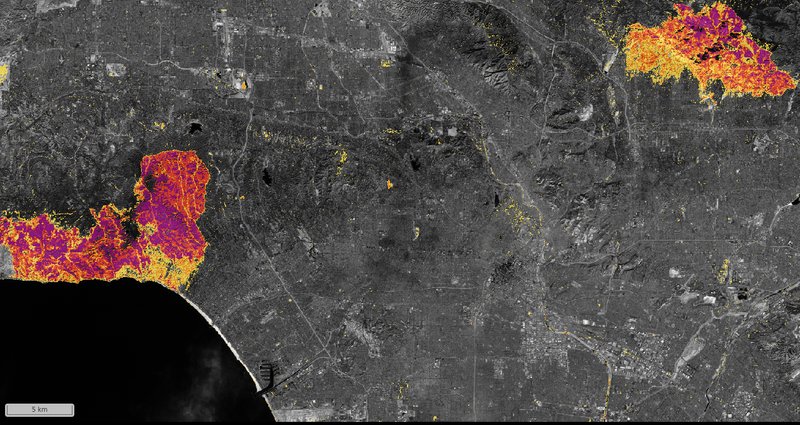
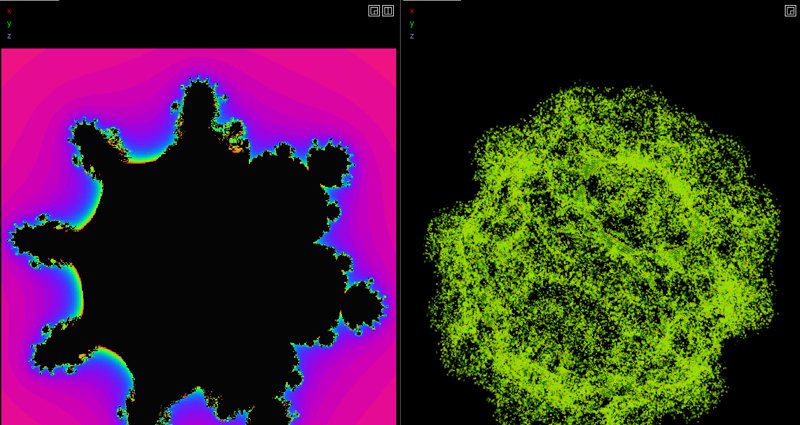
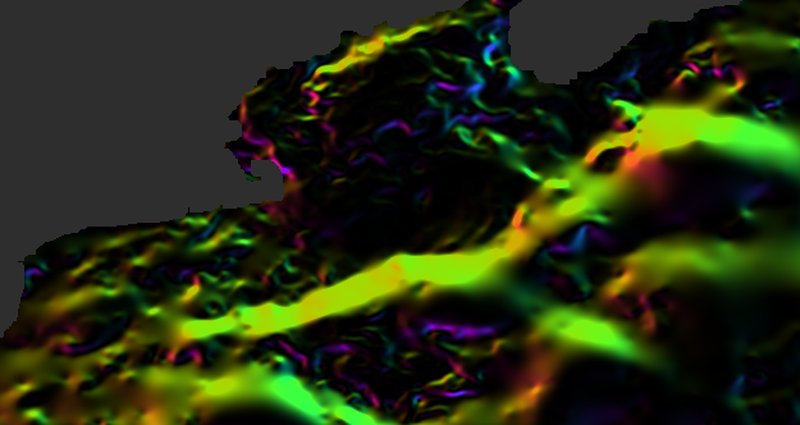
They include burn severity of the Los Angeles fires, the Gulf Stream's fronts and
hurricanes' cold wakes, landing slopes at the Moon's south pole, a 3-D fractal, microscope
tiles stitched by RANSAC, two fly brains registered on your GPU, organelle contact sites,
mRNA spots and nuclei tracked through a colony. The last is another project's page:
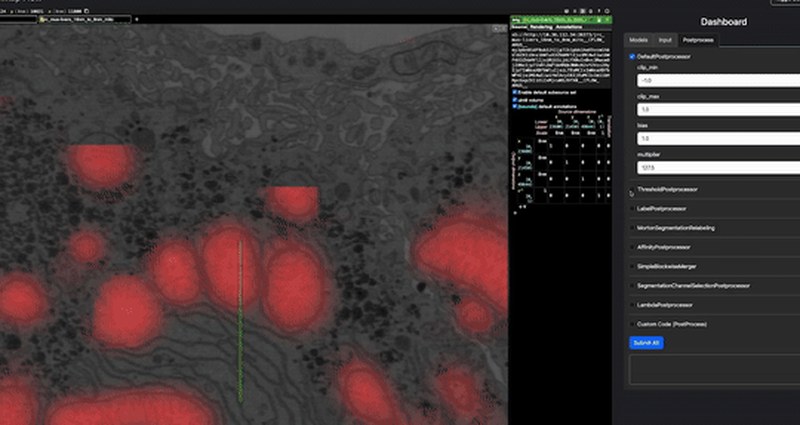
cellmap-flow runs on chunkmirage in both
its modes, serving a model's predictions over an electron-microscopy volume as you browse,
from a cluster's GPUs or, in its browser mode, from your own on chunkmirage's browser
engine. Each shows the chunkmirage serve command
that serves the same from Python, and most take Python of your own, run on a layer's chunks
in the page and edited live. The demos page lists them all, with the
Python examples.
viewer  --HTTP-->  chunkmirage  --tensorstore/h5py-->  real data (zarr/n5/precomputed/hdf5, file/s3/gcs/http)
                      |
                      +-- pipeline: source -> [op, op, ...] -> encoded chunk
                      +-- per-stage chunk cache keyed by pipeline hash
                      +-- frontends: n5 | zarr (v2) | zarr3 | precomputed, all served at once
                      +-- REST API for live pipeline edits, and plugins for ops, sources and routes
It was inspired by example-virtual-n5 and cellmap-flow, which grew out of it, and makes their trick general: any format, any source, any per-chunk computation, any client.
uv sync --extra all --group dev            # or: pip install -e ".[all]"
chunkmirage serve /path/to/data.zarr/em/fibsem-uint8 --op threshold:low=120
With no data at all, a generated 4096³ volume, segmented live:
uv run chunkmirage serve "synthetic://blobs+noise?shape=4096,4096,4096" \
    --op gaussian:sigma=1.5 --op threshold:low=110 \
    --op morphology:operation=open,radius=2 --op label:min_size=200 --python-viewer
Open the printed viewer link and pan and zoom: each chunk is computed as it comes on
screen, the level you are at first, and zooming out runs the same ops on the coarser
levels. Then open the control page (http://<your-ip>:8000/ui) and drag the threshold's
low slider: only the changed stage recomputes. Or point any viewer at one of these:
| viewer source URL | format |
|---|---|
n5://http://localhost:8000/<name>/n5 |
N5 |
zarr://http://localhost:8000/<name>/zarr |
Zarr v2 (+ OME-NGFF 0.4) |
zarr3://http://localhost:8000/<name>/zarr3 |
Zarr v3 (+ OME-NGFF 0.5) |
precomputed://http://localhost:8000/<name>/precomputed |
Neuroglancer precomputed |
Edit the pipeline without restarting:
curl -X PUT localhost:8000/api/datasets/<name> -H 'content-type: application/json' \
  -d '{"source": "/path/to/data.zarr/em/fibsem-uint8", "ops": [{"op": "threshold", "low": 150}]}'
More in getting started, including viewing from another machine.
from chunkmirage import Pipeline, open_source, create_app
from chunkmirage.ops import Op
from chunkmirage_contrib.ops import Threshold

class MyModel(Op):
    name = "my_model"
    halo = 16          # voxels of context read on every side
    cache = True       # keep this stage's output chunks

    def apply(self, block):
        return run_my_network(block)

pipe = Pipeline(open_source("s3://bucket/data.zarr/em/s0"), ops=[MyModel(), Threshold(low=120)])
app = create_app({"em": pipe})                   # a Starlette ASGI app
Ops, source schemes and HTTP routes from other packages register through entry points
(chunkmirage.ops, chunkmirage.sources, chunkmirage.routes), and the app can be mounted
inside another one. See pipelines and the
REST API.
- Sources: zarr v2/v3, N5, precomputed and HDF5 on file, S3, GCS or HTTP; xarray arrays
and GeoTIFFs; computed
synthetic://volumes,scene://resampling through OME-Zarr 0.6 transformations,register://deformable registration solved on a GPU,stitch://BigStitcher tiles stitched and fused as read, andwarp://,stack://andflip://. - Frontends: N5, Zarr v2, Zarr v3 and precomputed, all at once, and meshes made when fetched.
- Ops: pointwise, filters, morphology, connected components, spots, contacts, downsampling, slope and hillshade, with halos handled for you.
- Serving: per-stage cache, live REST edits, a control page, work ordered by what clients ask for and dropped when they stop waiting.
- In the browser: the same ops run in Pyodide, and registration on WebGPU.
- Your own Python: a
pythonop carries its code in the pipeline, edited live like a Neuroglancer shader, in the browser demos (where a chat writes it from a request, with your own key for Claude, OpenAI, Gemini or others) and on a server started with--allow-code. An op you will reuse is a class in your own package.
Not yet: GPU ops other than registration, an MCP server. See the roadmap.
https://janeliascicomp.github.io/chunkmirage/ (built from docs/; uv run mkdocs serve
locally). the design page explains the architecture and the choices behind
it.
BSD 3-Clause, Howard Hughes Medical Institute. Authors: TBD (collaborative project).