|
| 1 | +{ |
| 2 | + "cells": [ |
| 3 | + { |
| 4 | + "cell_type": "markdown", |
| 5 | + "id": "0", |
| 6 | + "metadata": {}, |
| 7 | + "source": [ |
| 8 | + "# Zarr Stores with Xarray\n", |
| 9 | + "\n", |
| 10 | + "## Learning Objectives:\n", |
| 11 | + "- Learn about the Zarr data format and xarray's \"zarr\" backend engine\n", |
| 12 | + "- Learn how to read a Zarr store with a hierarchical structure with `xr.DataTree`\n", |
| 13 | + "- Learn how to select dask arrays from a Zarr store\n", |
| 14 | + "- Explore how to use Zarr stores with xarray for computations and visualizations\n", |
| 15 | + "\n", |
| 16 | + "## What is Zarr?\n", |
| 17 | + "\n", |
| 18 | + "The Zarr data format is an open, community-maintained format designed for efficient, scalable storage of large N-dimensional arrays. It stores data as compressed and chunked arrays in a format well-suited to parallel processing and cloud-native workflows. Xarray’s Zarr backend allows xarray to leverage these capabilities, including the ability to store and analyze datasets far too large fit onto disk (particularly in combination with [dask](https://docs.xarray.dev/en/latest/user-guide/dask.html#dask)).\n", |
| 19 | + "\n", |
| 20 | + "### Zarr Data Organization:\n", |
| 21 | + "- **Arrays**: N-dimensional arrays that can be chunked and compressed.\n", |
| 22 | + "- **Groups**: A container for organizing multiple arrays and other groups with a hierarchical structure.\n", |
| 23 | + "- **Metadata**: JSON-like metadata describing the arrays and groups, including information about data types, dimensions, chunking, compression, and user-defined key-value fields. \n", |
| 24 | + "- **Dimensions and Shape**: Arrays can have any number of dimensions, and their shape is defined by the number of elements in each dimension.\n", |
| 25 | + "- **Coordinates & Indexing**: Zarr supports coordinate arrays for each dimension, allowing for efficient indexing and slicing.\n", |
| 26 | + "\n", |
| 27 | + "The diagram below from [the Zarr v3 specification](https://wiki.earthdata.nasa.gov/display/ESO/Zarr+Format) showing the structure of a Zarr store:\n", |
| 28 | + "\n", |
| 29 | + "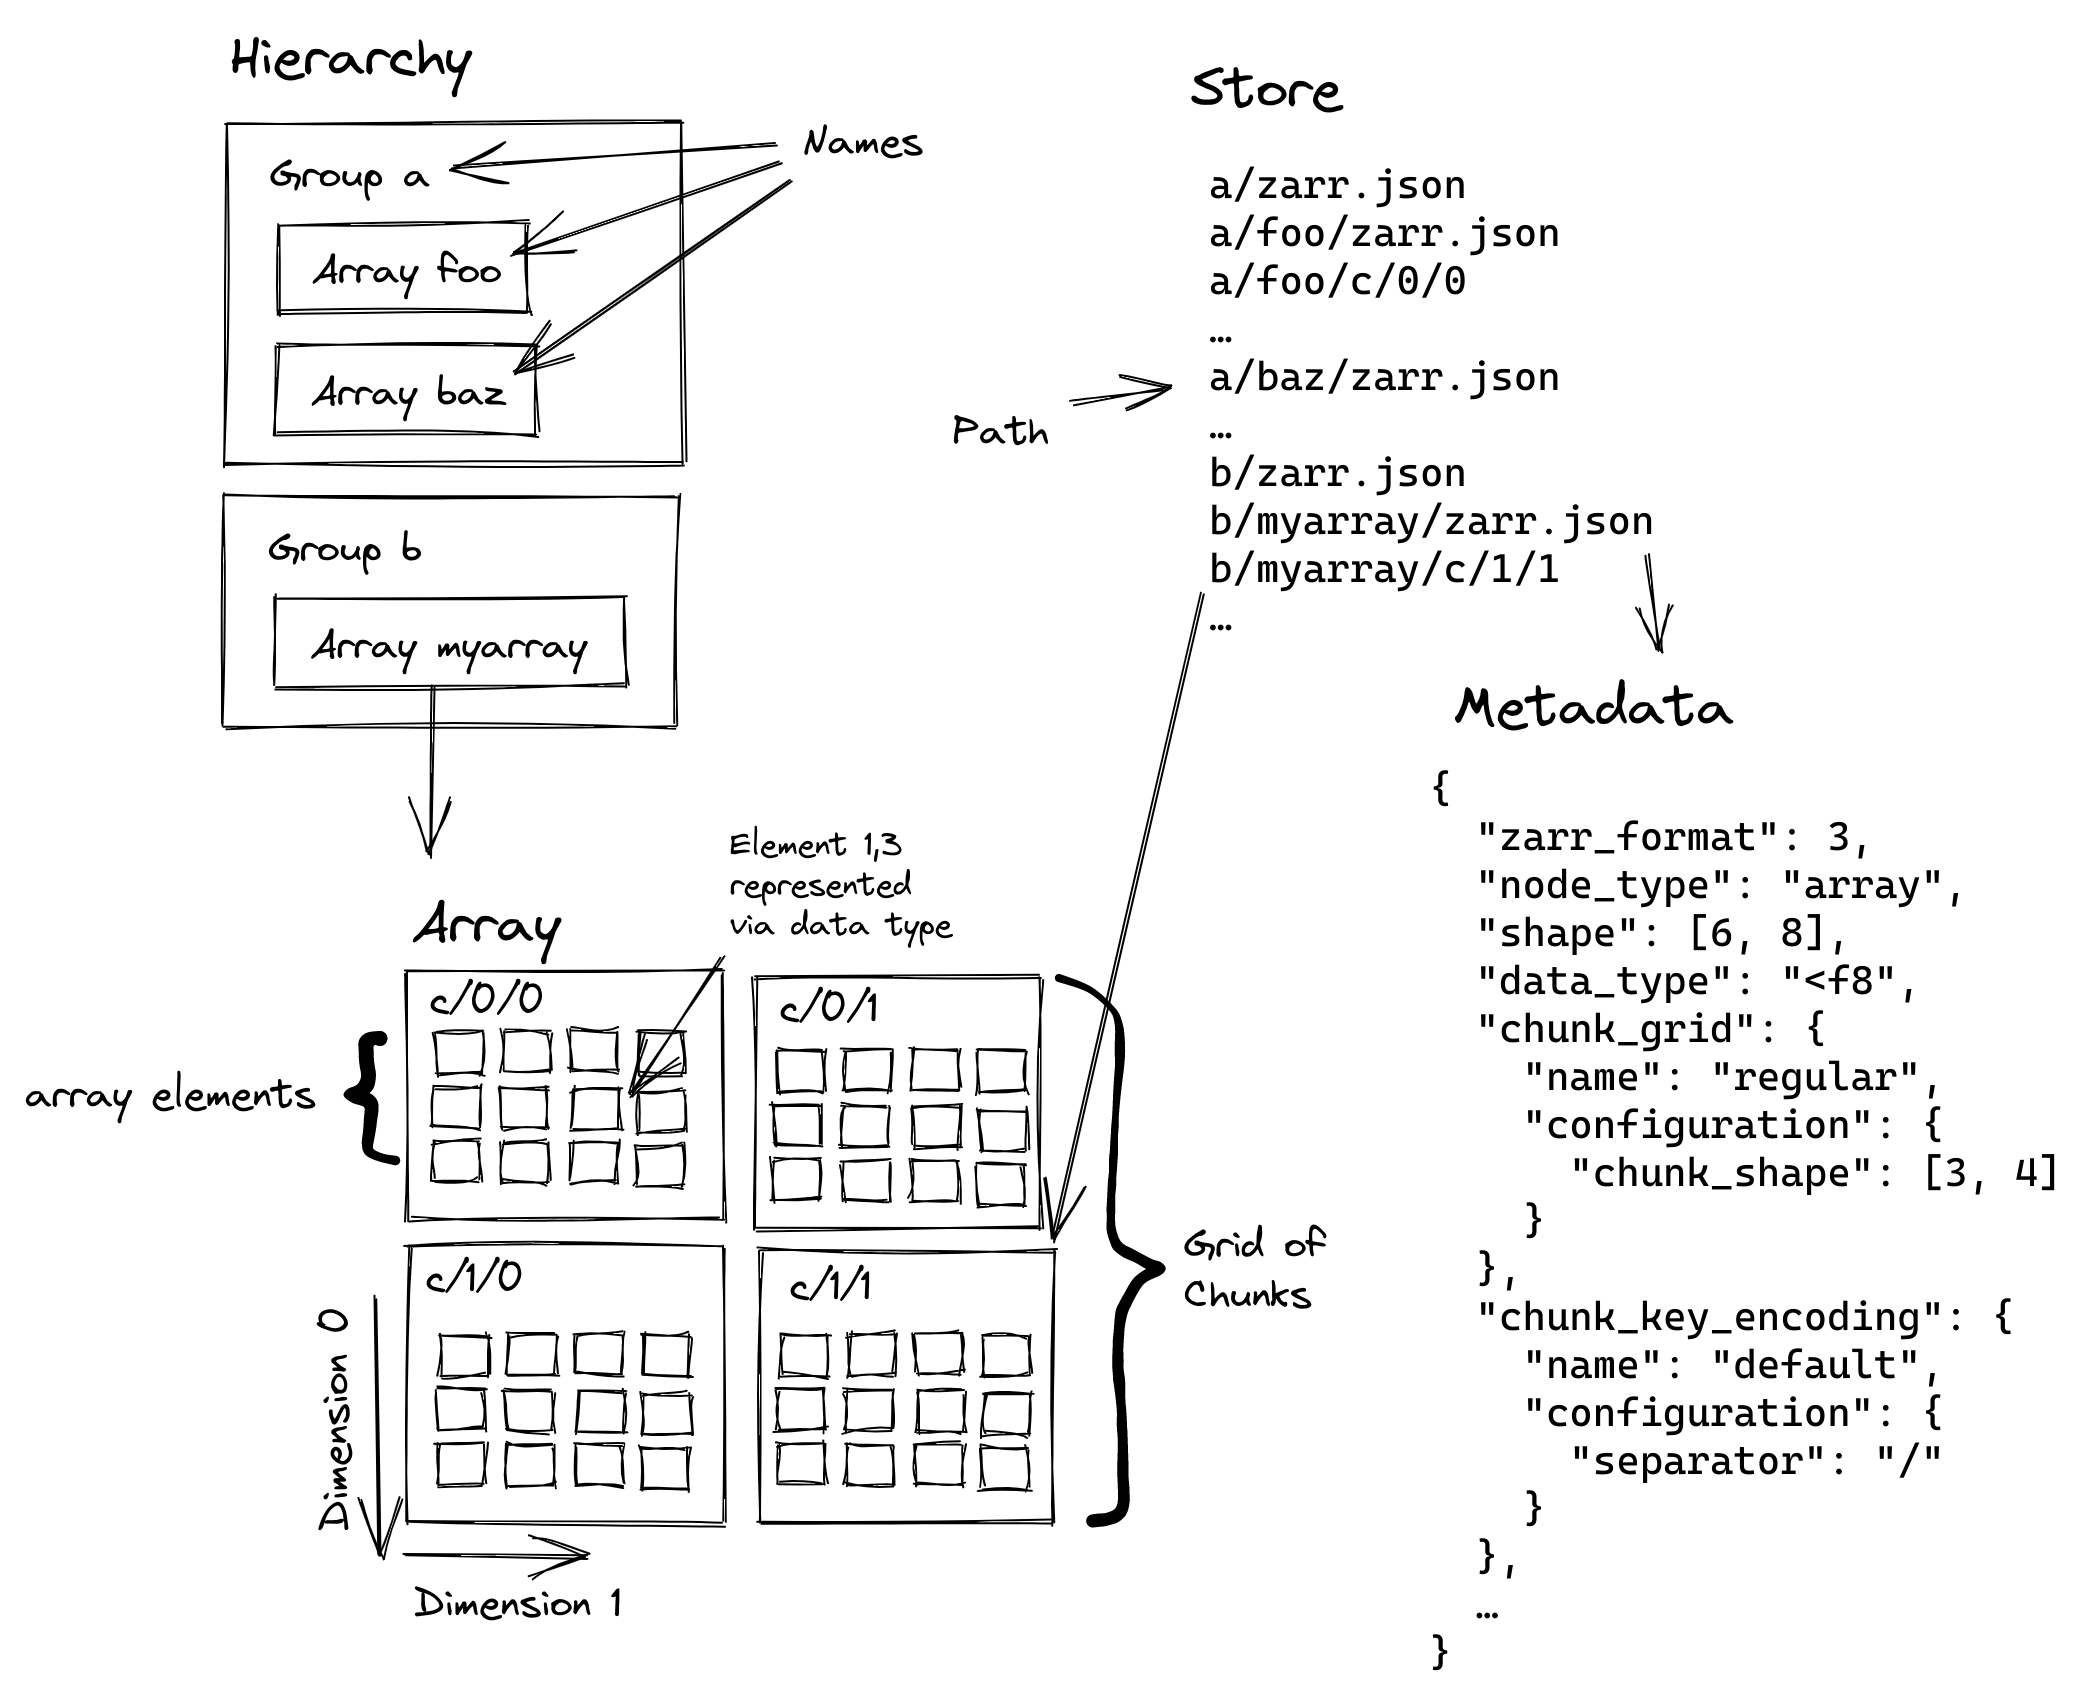\n", |
| 30 | + "\n", |
| 31 | + "\n", |
| 32 | + "NetCDF and Zarr share similar terminology and functionality, but the key difference is that NetCDF is a single file, while Zarr is a directory-based “store” composed of many chunked files, making it better suited for distributed and cloud-based workflows." |
| 33 | + ] |
| 34 | + }, |
| 35 | + { |
| 36 | + "cell_type": "markdown", |
| 37 | + "id": "1", |
| 38 | + "metadata": {}, |
| 39 | + "source": [ |
| 40 | + "## Reading a zarr store\n", |
| 41 | + "With xarray's \"zarr\" backend, we can read data remotely from cloud storage buckets. Since Zarr is a cloud-optimized format, our dataset is lazily-loaded as dask arrays.\n", |
| 42 | + "The Zarr store in this tutorial is in a public storage bucket and is a precipitation dataset with a group hierarchical structure. The groups: \"observed\" and \"reanalysis\", each contain a \"precipitation\" data variable derived from *[GPM_3IMERGHH_07](https://disc.gsfc.nasa.gov/datasets/GPM_3IMERGHH_07/summary)* and *[M2T1NXFLX_5.12.4](https://disc.gsfc.nasa.gov/datasets/M2T1NXFLX_5.12.4/summary)* products, respectively. The precipitation data variables in each group have different spatial resolutions that cannot be represented in a single group, so we need to read them as `DataTree` objects.\n", |
| 43 | + "\n", |
| 44 | + "Let's read in our zarr store with `xr.open_datatree`" |
| 45 | + ] |
| 46 | + }, |
| 47 | + { |
| 48 | + "cell_type": "code", |
| 49 | + "execution_count": null, |
| 50 | + "id": "2", |
| 51 | + "metadata": {}, |
| 52 | + "outputs": [], |
| 53 | + "source": [ |
| 54 | + "import xarray as xr\n", |
| 55 | + "\n", |
| 56 | + "precipitation_store = \"https://pub-45a1d62ac8d94c4c89f4dc63681a98ed.r2.dev/precipitation.zarr\"\n", |
| 57 | + "\n", |
| 58 | + "precip_dt = xr.open_datatree(precipitation_store, engine=\"zarr\", chunks={}, consolidated=True)" |
| 59 | + ] |
| 60 | + }, |
| 61 | + { |
| 62 | + "cell_type": "code", |
| 63 | + "execution_count": null, |
| 64 | + "id": "3", |
| 65 | + "metadata": {}, |
| 66 | + "outputs": [], |
| 67 | + "source": [ |
| 68 | + "precip_dt.observed.precipitation" |
| 69 | + ] |
| 70 | + }, |
| 71 | + { |
| 72 | + "cell_type": "markdown", |
| 73 | + "id": "4", |
| 74 | + "metadata": {}, |
| 75 | + "source": [ |
| 76 | + ":::{note} We selected `\"zarr\"` backend engine, which tells xarray to load and decode a dataset from a Zarr store. The `chunks={}` parameter is used to load the data into a dask array. And `consolidated=True` enables zarr’s consolidated metadata capability. This lets us read all of the metadata from a single file which can improve performance.\n", |
| 77 | + ":::" |
| 78 | + ] |
| 79 | + }, |
| 80 | + { |
| 81 | + "cell_type": "markdown", |
| 82 | + "id": "5", |
| 83 | + "metadata": {}, |
| 84 | + "source": [ |
| 85 | + "## Variable selection\n", |
| 86 | + "With our `DataTree` object, we can select variables from our Zarr store with either dictionary and or attribute like syntax." |
| 87 | + ] |
| 88 | + }, |
| 89 | + { |
| 90 | + "cell_type": "markdown", |
| 91 | + "id": "6", |
| 92 | + "metadata": {}, |
| 93 | + "source": [ |
| 94 | + "### Dictionary-like interface" |
| 95 | + ] |
| 96 | + }, |
| 97 | + { |
| 98 | + "cell_type": "code", |
| 99 | + "execution_count": null, |
| 100 | + "id": "7", |
| 101 | + "metadata": {}, |
| 102 | + "outputs": [], |
| 103 | + "source": [ |
| 104 | + "precip_dt[\"observed/precipitation\"]" |
| 105 | + ] |
| 106 | + }, |
| 107 | + { |
| 108 | + "cell_type": "markdown", |
| 109 | + "id": "8", |
| 110 | + "metadata": {}, |
| 111 | + "source": [ |
| 112 | + "### Attribute-like access" |
| 113 | + ] |
| 114 | + }, |
| 115 | + { |
| 116 | + "cell_type": "code", |
| 117 | + "execution_count": null, |
| 118 | + "id": "9", |
| 119 | + "metadata": {}, |
| 120 | + "outputs": [], |
| 121 | + "source": [ |
| 122 | + "precip_dt.observed.precipitation" |
| 123 | + ] |
| 124 | + }, |
| 125 | + { |
| 126 | + "cell_type": "markdown", |
| 127 | + "id": "10", |
| 128 | + "metadata": {}, |
| 129 | + "source": [ |
| 130 | + "### Dictionary and Attribute like access" |
| 131 | + ] |
| 132 | + }, |
| 133 | + { |
| 134 | + "cell_type": "code", |
| 135 | + "execution_count": null, |
| 136 | + "id": "11", |
| 137 | + "metadata": {}, |
| 138 | + "outputs": [], |
| 139 | + "source": [ |
| 140 | + "precip_dt.observed[\"precipitation\"]" |
| 141 | + ] |
| 142 | + }, |
| 143 | + { |
| 144 | + "cell_type": "markdown", |
| 145 | + "id": "12", |
| 146 | + "metadata": {}, |
| 147 | + "source": [ |
| 148 | + ":::{note} All of these variable selection options return the same \"precipitation\" `xr.DataArray` object, as a chunked `dask.Array`, from the \"observed\" group of our Zarr store.\n", |
| 149 | + ":::" |
| 150 | + ] |
| 151 | + }, |
| 152 | + { |
| 153 | + "cell_type": "markdown", |
| 154 | + "id": "13", |
| 155 | + "metadata": {}, |
| 156 | + "source": [ |
| 157 | + "## Time slicing\n", |
| 158 | + "\n", |
| 159 | + "We can index and subset by time on our `xr.DataTree` object. Each time slice in our Zarr store represents one hour of data with a total of 10 hours of data.\n", |
| 160 | + "\n", |
| 161 | + "Let's explore the different ways we can get the first 5 hours of data. " |
| 162 | + ] |
| 163 | + }, |
| 164 | + { |
| 165 | + "cell_type": "markdown", |
| 166 | + "id": "14", |
| 167 | + "metadata": {}, |
| 168 | + "source": [ |
| 169 | + "### Label-based indexing" |
| 170 | + ] |
| 171 | + }, |
| 172 | + { |
| 173 | + "cell_type": "markdown", |
| 174 | + "id": "15", |
| 175 | + "metadata": {}, |
| 176 | + "source": [ |
| 177 | + "Let's try getting the first 5 hours of data with `.sel(time=)`. \n", |
| 178 | + "\n", |
| 179 | + "Since the time slices are ordered we can get a subset of the array of our time coordinate and pass it to the `.sel` method." |
| 180 | + ] |
| 181 | + }, |
| 182 | + { |
| 183 | + "cell_type": "code", |
| 184 | + "execution_count": null, |
| 185 | + "id": "16", |
| 186 | + "metadata": {}, |
| 187 | + "outputs": [], |
| 188 | + "source": [ |
| 189 | + "time_index = precip_dt.time[0:5]\n", |
| 190 | + "precip_dt.sel(time=time_index)" |
| 191 | + ] |
| 192 | + }, |
| 193 | + { |
| 194 | + "cell_type": "markdown", |
| 195 | + "id": "17", |
| 196 | + "metadata": {}, |
| 197 | + "source": [ |
| 198 | + "### Datetime indexing\n", |
| 199 | + "We can also subset by time with a `datetime` string." |
| 200 | + ] |
| 201 | + }, |
| 202 | + { |
| 203 | + "cell_type": "code", |
| 204 | + "execution_count": null, |
| 205 | + "id": "18", |
| 206 | + "metadata": {}, |
| 207 | + "outputs": [], |
| 208 | + "source": [ |
| 209 | + "precip_dt.sel(time=slice(\"2021-08-29T07:30:00\", \"2021-08-29T16:30:00\"))" |
| 210 | + ] |
| 211 | + }, |
| 212 | + { |
| 213 | + "cell_type": "markdown", |
| 214 | + "id": "19", |
| 215 | + "metadata": {}, |
| 216 | + "source": [ |
| 217 | + "### Positional Indexing\n", |
| 218 | + "Or by the index of our time dimension `.isel(time=slice())`" |
| 219 | + ] |
| 220 | + }, |
| 221 | + { |
| 222 | + "cell_type": "code", |
| 223 | + "execution_count": null, |
| 224 | + "id": "20", |
| 225 | + "metadata": {}, |
| 226 | + "outputs": [], |
| 227 | + "source": [ |
| 228 | + "precip_dt.isel(time=slice(0, 5))" |
| 229 | + ] |
| 230 | + }, |
| 231 | + { |
| 232 | + "cell_type": "markdown", |
| 233 | + "id": "21", |
| 234 | + "metadata": { |
| 235 | + "vscode": { |
| 236 | + "languageId": "plaintext" |
| 237 | + } |
| 238 | + }, |
| 239 | + "source": [ |
| 240 | + "## Chunking\n", |
| 241 | + "Chunking is the process of dividing arrays into smaller pieces, which allows for parallel processing and efficient storage.\n", |
| 242 | + "\n", |
| 243 | + "To examine the chunks in our Zarr store, with `xarray` you can use the `chunks` attribute on the `xr.DataArray` object." |
| 244 | + ] |
| 245 | + }, |
| 246 | + { |
| 247 | + "cell_type": "code", |
| 248 | + "execution_count": null, |
| 249 | + "id": "22", |
| 250 | + "metadata": {}, |
| 251 | + "outputs": [], |
| 252 | + "source": [ |
| 253 | + "precip_dt.observed[\"precipitation\"].data.chunks" |
| 254 | + ] |
| 255 | + }, |
| 256 | + { |
| 257 | + "cell_type": "markdown", |
| 258 | + "id": "23", |
| 259 | + "metadata": {}, |
| 260 | + "source": [ |
| 261 | + "### Selecting by chunks\n", |
| 262 | + "\n", |
| 263 | + "Since we loaded our data as a `dask.Array`, we can access data from each chunked array in our Zarr store. \n", |
| 264 | + "\n", |
| 265 | + "Let's get the first chunk of the \"observed/precipitation\" variable in our zarr store." |
| 266 | + ] |
| 267 | + }, |
| 268 | + { |
| 269 | + "cell_type": "code", |
| 270 | + "execution_count": null, |
| 271 | + "id": "24", |
| 272 | + "metadata": {}, |
| 273 | + "outputs": [], |
| 274 | + "source": [ |
| 275 | + "precip_dt.observed[\"precipitation\"].data.blocks[0, 0, 0].compute()" |
| 276 | + ] |
| 277 | + }, |
| 278 | + { |
| 279 | + "cell_type": "markdown", |
| 280 | + "id": "25", |
| 281 | + "metadata": {}, |
| 282 | + "source": [ |
| 283 | + ":::{note}\n", |
| 284 | + "We added `.data` to our `xr.DataArray` to access the `dask.Array`. The `.blocks[]` method allows you to index by chunk and `.compute()` returns the `np.ndarray`. \n", |
| 285 | + ":::" |
| 286 | + ] |
| 287 | + }, |
| 288 | + { |
| 289 | + "cell_type": "markdown", |
| 290 | + "id": "26", |
| 291 | + "metadata": {}, |
| 292 | + "source": [ |
| 293 | + "## Exercise" |
| 294 | + ] |
| 295 | + }, |
| 296 | + { |
| 297 | + "cell_type": "markdown", |
| 298 | + "id": "27", |
| 299 | + "metadata": {}, |
| 300 | + "source": [ |
| 301 | + "::::{admonition} Exercise\n", |
| 302 | + ":class: tip\n", |
| 303 | + "\n", |
| 304 | + "Can you calculate and plot the mean precipitation, starting at 09:55 for the reanalysis group in this zarr store?\n", |
| 305 | + "\n", |
| 306 | + ":::{admonition} Hint\n", |
| 307 | + ":class: dropdown\n", |
| 308 | + "This is how you could calculate mean \"precipitation\"\n", |
| 309 | + "\n", |
| 310 | + "```python\n", |
| 311 | + "precip_dt.reanalysis['precipitation'].mean(dim='time')\n", |
| 312 | + "```\n", |
| 313 | + ":::\n", |
| 314 | + "\n", |
| 315 | + ":::{admonition} Solution\n", |
| 316 | + ":class: dropdown\n", |
| 317 | + "\n", |
| 318 | + "```python\n", |
| 319 | + "precip_dt.reanalysis['precipitation'].sel(time=slice('2021-08-29T09:55:00', '2021-08-29T16:30:00')).mean(dim='time').plot()\n", |
| 320 | + "```\n", |
| 321 | + ":::\n", |
| 322 | + "::::" |
| 323 | + ] |
| 324 | + } |
| 325 | + ], |
| 326 | + "metadata": { |
| 327 | + "language_info": { |
| 328 | + "codemirror_mode": { |
| 329 | + "name": "ipython", |
| 330 | + "version": 3 |
| 331 | + }, |
| 332 | + "file_extension": ".py", |
| 333 | + "mimetype": "text/x-python", |
| 334 | + "name": "python", |
| 335 | + "nbconvert_exporter": "python", |
| 336 | + "pygments_lexer": "ipython3" |
| 337 | + } |
| 338 | + }, |
| 339 | + "nbformat": 4, |
| 340 | + "nbformat_minor": 5 |
| 341 | +} |


0 commit comments