diff --git a/.vscodeignore b/.vscodeignore
index 7bc3fc3..e483338 100644
--- a/.vscodeignore
+++ b/.vscodeignore
@@ -72,3 +72,9 @@ docs/assets/**
# absolute raw.githubusercontent URL, exactly as it does the icon, so the Marketplace
# listing renders them without a megabyte of PNG riding along in every install.
docs/images/**
+
+# Benchmark fixtures. Six photographs, 3.6 MB, read only by `tools/bench-vision.js` on a
+# developer's machine. They shipped in no release — this rule was added the same day the
+# folder was, because `docs/**` is not ignored wholesale and a new subdirectory under it
+# is packaged by default. Anything else added there needs the same consideration.
+docs/test-images/**
diff --git a/CHANGELOG.md b/CHANGELOG.md
index 99682f9..f0719a5 100644
--- a/CHANGELOG.md
+++ b/CHANGELOG.md
@@ -5,6 +5,192 @@ All notable changes to HirayaCoder are documented here.
The format follows [Keep a Changelog](https://keepachangelog.com/en/1.1.0/), and this
project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).
+## [1.1.0] — 2026-08-21
+
+HirayaCoder can look at pictures. Attach a screenshot, a photo, or a sketch of a screen
+you want built, and what is in it becomes part of the conversation — in Ask mode as the
+subject of the answer, in Agent and Plan mode as part of the job.
+
+The release also cuts the README down to what a first-time reader needs and moves
+everything else into `doc/`.
+
+### Added — image recognition
+
+`core/imageRecognition` asks a vision model what is in an attached image and returns the
+answer as plain text. Three separate reasons that indirection exists, and each would be
+enough on its own:
+
+**Most models cannot see.** `llama3.2` is what a lot of people are actually running, and
+it has no vision capability at all. Attaching an image to it used to be refused outright.
+Now the picture goes to whichever installed model *can* see, the description comes back,
+and the coding model works from that. Nobody has to switch models to use a screenshot,
+and the attach button is gated on the machine having a vision model rather than on the
+selected one being it.
+
+**The picture does not survive the loop.** Images ride on the first message only —
+re-uploading 5 MB of base64 on every turn of an eight-step run spends more time on the
+upload than on the thinking. So by turn four the model was reasoning about an image it
+could no longer see. A description is a hundred tokens and is carried on every turn,
+which is why one is produced even for a model with perfectly good vision.
+
+**A description can be checked.** A model that hallucinates an image is invisible when
+the image is a blob on a message. As a paragraph in the transcript, the user reads "a red
+error dialog" over their green one and knows immediately.
+
+The describer is chosen automatically: the selected model when it can see, since that
+costs no extra load, and otherwise the **smallest** installed vision model. Smallest
+because Ollama holds one model resident at a time, so a second model is paid for in load
+time, and describing a picture is a read rather than a piece of reasoning.
+`hirayacoder.vision.describeModel` overrides the choice; `hirayacoder.vision.enabled`
+turns the pass off.
+
+### Added — you can see what it read
+
+Every message with an image gets a collapsed panel holding the exact description the
+vision model produced.
+
+This is the part that makes the feature usable rather than merely present. When an answer
+about a picture is wrong there are two causes — the picture was misread, or it was read
+correctly and the reasoning went wrong — and they need opposite fixes. Without the
+description on screen they are indistinguishable, and the user's only move is to try
+again and hope.
+
+### Fixed — a redraft that argued the model out of a correct answer
+
+`agentSession._rethink` sends a mismatched reply back for one correction. It was sending
+the context and **not** the images, so a reply written from a photograph was being
+corrected by a model that could not see the photograph. The redraft turned good answers
+into hedges about not being able to see anything. It now carries whatever the draft
+carried.
+
+### Fixed — "I cannot see this image", stored as the description
+
+Found by the new benchmark, once in twenty-four runs of `qwen3.5:0.8b`: a model that
+reports the `vision` capability, that was sent the image, and that had described the same
+photograph correctly one sample earlier, replied *"I cannot see this image. I am an AI
+model designed to process text…"*. A small model's text-only training reasserting itself
+over what it was actually handed.
+
+Left alone, that paragraph becomes the description — stored, put in front of the coding
+model as "what is in this picture", and shown in the panel. Reasoning from a statement
+that no image exists is worse than being told the read failed, so the shape is now
+recognised and reported as a failure.
+
+The detector is narrow on purpose. The recognition prompt asks the describer to say when
+it cannot make something out, so *"I cannot see the licence plate clearly"* is the
+instruction working. It requires a first-person inability **plus** a visual object, and
+examines only the opening 400 characters, so a real description that ends with a
+boilerplate disclaimer survives.
+
+### Added — every reply says which model wrote it and how long it took
+
+A small line under each answer:
+
+```
+minicpm-v4.6:latest • 25s
+```
+
+On this hardware the model is the main lever anyone has — a task is one to five minutes,
+and the only way to make it faster is to run something smaller — so choosing between them
+means comparing replies that are minutes and several messages apart. The status line
+could not serve that: it is per-tab and the next turn overwrites it, so it says what is
+happening and never what happened. Attached to the reply, the comparison is just
+scrolling.
+
+The duration is the run itself, not the wait: a turn queued behind another tab does not
+start its clock until it owns the lane, so the number is time spent on *this* model
+rather than on somebody else's.
+
+When a **different** model read an attached image, it is named separately:
+
+```
+llama3.2:latest • 17s + minicpm-v4.6:latest read the image, 8s
+```
+
+That is not decoration. It is where the extra eight seconds went, and without it the
+coding model looks like it got slower.
+
+### Fixed — the project description drowning the picture
+
+Found by trying the packaged build rather than by any test. In Ask mode on
+`minicpm-v4.6`, "describe the image" with a photograph of a dog attached returned a
+description of HirayaCoder.
+
+Not a vision failure: the same model and the same photograph score 24/24 in
+`tools/bench-vision.js`. It was an instruction-following failure, and the instructions it
+followed were ours. Ask mode's system prompt opens with *"everything below this line is
+what you know about the user's project… Answer from it"*, and underneath sat 2,500
+characters of project description and file listing with `Task: describe the image` on the
+last line. A small model resolves that conflict by weight, and forty file paths outweigh
+one line of task.
+
+Two changes. On a turn with no tools that carries an image, the project overview and the
+workspace listing are left out — they are orientation the model cannot act on, and they
+were the thing being answered from. And every prompt gains a short instruction saying an
+image is attached and is the subject of the question. After both, the user turn went from
+2,510 characters to 24 and the same model answered: *"a cheerful Corgi with a fluffy
+white and tan coat, lying comfortably in a sunlit grassy field… wears a green collar"*.
+
+The listing is kept in Agent and Plan mode, where it is load-bearing: a model asked to
+build the screen in a mockup needs to know which paths exist, and there the picture is a
+fact about the job rather than a competitor to it.
+
+`contextBuilder` already carried a comment describing this exact shape for the chat route
+— a model handed a project description and the message "Hello Hiraya" answers with the
+project description. Same bug, different trigger, and the connection was missed.
+
+### Added — the image-recognition benchmark
+
+`tools/bench-vision.js`, graded against six photographs in `docs/test-images/` on four
+axes: subject, detail, text read, and confusion. Confusion can only be lost, because
+vague is usable and wrong is worse than nothing.
+
+The 1.1.0 baseline, machine B, 24 graded descriptions per model:
+
+| Model | Params | Subject | Detail | Text read | Confused | Cold |
+|---|---|---|---|---|---|---|
+| `minicpm-v4.6` | 752M | **24/24** | 42/48 | 4/8 | 0 | 11s |
+| `qwen3.5:0.8b` | 873M | 23/24 | **46/48** | **8/8** | 0 | 13s |
+
+Naming the subject is solved at this size. Reading text is not, and it turns out to
+depend on the size of the *text* rather than of the model: all four of `minicpm-v4.6`'s
+text failures are the same photograph, whose only text is a small badge on a car grille,
+and it read a large clear airline logo on every attempt.
+
+The timings needed a `--cold` flag to mean anything. Ollama caches the tokenized prompt,
+and for these requests the prompt is mostly the image, so the second sample of a picture
+returned in one second where the first took fifteen — and the cache survived between
+runs, reporting one second for everything half an hour later. `--cold` unloads the model
+between samples. None of it touches the accuracy scores.
+
+### Changed — the README is a fifth of the size
+
+514 lines to 259, cut to what somebody deciding whether to install this needs: what it
+does, what it cannot do, whether their machine will run it, and four steps. Everything
+else moved, whole, into `doc/`:
+
+| New file | What moved into it |
+|---|---|
+| `doc/GETTING-STARTED.md` | The full first-run walkthrough |
+| `doc/USING-IT.md` | Modes, watching a run, request habits |
+| `doc/LIMITATIONS.md` | **New.** Everything it cannot do, by design and otherwise |
+| `doc/IMAGE-RECOGNITION.md` | **New.** Images, in full |
+| `doc/TROUBLESHOOTING.md` | When something goes wrong, and the command allow-list |
+| `doc/CHOOSING-A-MODEL.md` | Which model to download |
+| `doc/DEVELOPING.md` | The engineering, benchmarks, building, contributing |
+
+`LIMITATIONS.md` is the one worth calling out. The limits were previously spread across
+five sections and phrased apologetically where they were phrased at all, and the two
+kinds — deliberate design choices, and things a small model is simply not good at — were
+mixed together. They are separated now, because the first kind is the reason to choose
+this tool and the second is the reason not to.
+
+### Security
+
+Full report in `security/sast-report-2026-08-21-1.1.0.md`. Zero production dependencies,
+zero advisories, no Critical or High findings. One ordering hardening applied in
+`agentSession`, and the `imageRecognition` regex measured rather than assumed.
+
## [1.0.0] — 2026-08-20
The version number is the news, and it is a claim about stability rather than about
diff --git a/README.md b/README.md
index be1d893..682f6a8 100644
--- a/README.md
+++ b/README.md
@@ -5,454 +5,224 @@
-
+
*A local Filipino-inspired AI coder that brings imagination and speed to your VS Code workflow.*
-> **1.0.0 is here.** Everything described below is implemented, tested on Windows, macOS
-> and Linux in CI, and stable enough to put a 1.0 on. The one thing still missing is the
-> one-click install: the Marketplace listing is not up yet, so releases are published as
-> a `.vsix` on the
-> [Releases page](https://github.com/jaymar921/HirayaCoder/releases) and installed by
-> hand — [Step 4](#step-4--install-hirayacoder) has the one command it takes.
-
**HirayaCoder is a free AI coding assistant that runs entirely on your own computer.**
-You type what you want in plain English, and it writes and edits the files for you — no
+You type what you want in plain English, and it writes and edits the files for you. No
account, no subscription, no internet connection, and nothing you write ever leaves your
laptop.
-> **Hiraya** (Filipino) — imagination, aspiration, the spark of an idea before it becomes real.
-
----
-
-## New here? Start with this
-
-**You do not need to know how to code to try it.** You do need about twenty minutes and
-a computer with a bit of room to spare. Here is the honest version of what you are
-signing up for.
-
-### What it actually does
-
-You open a folder on your computer, type something like *"make me a webpage with a
-to-do list"*, and HirayaCoder creates the files, writes the code, and shows you what it
-changed before saving anything. You can then ask it to change things: *"make the buttons
-blue"*, *"add a delete button"*.
+> **Hiraya** (Filipino): imagination, aspiration, the spark of an idea before it becomes real.
-### What makes it different from ChatGPT or Copilot
-
-| | HirayaCoder | ChatGPT / Copilot |
-|---|---|---|
-| Cost | Free, forever | Usually a monthly fee |
-| Internet | Not needed after setup | Required |
-| Your code | Never leaves your computer | Sent to a company's servers |
-| Quality | Good, not great — see below | Better |
-| Speed | Seconds to minutes, depends on your PC | Fast |
-
-**The trade is real and you should know it before you start.** HirayaCoder runs a small
-AI model on your own hardware, and small models are not as clever as the big paid ones.
-It handles ordinary tasks well. It struggles with big, vague requests. If you ask for
-"a full social media app" you will be disappointed; if you ask for one page, one feature,
-or one fix at a time, it does a decent job.
-
-### Will it run on my computer?
-
-The main question is **how much RAM (memory) you have**. Here's a quick guide — you do
-not need a fancy graphics card.
-
-| Your computer | Will it work? | What to expect |
-|---|---|---|
-| 8 GB RAM | Yes, just barely | Slow, and only simple single-file tasks |
-| 16 GB RAM, no graphics card | **Yes — this is what it was built for** | A task takes 1–5 minutes. Very usable |
-| 16 GB+ with a gaming graphics card | Yes, comfortably | A task takes 20–60 seconds |
-| Mac with Apple Silicon (M1–M4) | Yes, very well | A task takes 10–30 seconds |
-
-To check on Windows: press `Ctrl+Shift+Esc`, click **Performance**, then **Memory**.
-On a Mac: Apple menu → **About This Mac**.
+> **Not on the Marketplace yet.** Releases are published as a `.vsix` on the
+> [Releases page](https://github.com/jaymar921/HirayaCoder/releases) and installed with
+> one command. See [step 4](#quick-start).
---
-## Getting started
-
-Four steps. Copy and paste the commands exactly.
-
-### Step 1 — Install VS Code
-
-If you do not already have it, download it free from
-[code.visualstudio.com](https://code.visualstudio.com). This is the program you will
-actually be working in. You need **version 1.85 or newer** — any download from this year
-is fine.
+## What it does
-### Step 2 — Install Ollama
+You open a folder, type *"make me a webpage with a to-do list"*, and it creates the
+files, writes the code, and shows you every change before saving anything. Then you keep
+talking to it: *"make the buttons blue"*, *"add a delete button"*.
-[Ollama](https://ollama.com) is the free program that runs the AI on your computer.
-Download it, install it, and leave it running in the background. It has no window — it
-just sits in your system tray or menu bar, and that is normal.
-
-### Step 3 — Download an AI model
+
+
+
-Open a terminal and paste one line. (On Windows press the Start button, type
-`PowerShell`, and hit Enter. On a Mac press `Cmd+Space`, type `Terminal`, and hit Enter.)
+It runs the AI model on your own hardware through [Ollama](https://ollama.com), so it
+works with your Wi-Fi switched off. That is the whole point of it.
-**Pick the line that matches your computer:**
+---
-```bash
-# 16 GB RAM or more — the best all-round choice, start here
-ollama pull gemma4:e2b
+## New in 1.1.0: it can look at pictures
-# 8 GB RAM, or if the one above is too slow — smaller and faster, but more limited
-ollama pull llama3.2:1b
-```
+Attach a screenshot, a photo, or a sketch to your message, and HirayaCoder reads it.
-This downloads a few gigabytes, so it takes a while on a slow connection. You only ever
-do it once.
+- **Ask a question about it.** *"What is this error saying?"*
+- **Give it a job.** *"Build the screen in this mockup."* The picture becomes part of
+ the task.
-### Step 4 — Install HirayaCoder
+The useful part is that **this works even if your coding model cannot see**. Most AI
+models only handle text. A few, called vision models, can also take an image. If the
+model you picked is a text-only one, HirayaCoder quietly hands the picture to a vision
+model instead, gets back a written description of what is in it, and passes that
+description to your coding model. You do not have to switch models.
-Download the `.vsix` file from the
-[Releases page](https://github.com/jaymar921/HirayaCoder/releases), then run:
+If nothing you have installed can read images, one command fixes it:
```bash
-code --install-extension hirayacoder-.vsix
+ollama pull minicpm-v4.6
```
-Replace `` with the number in the filename you downloaded.
-
-### You're ready
+That is 1.6 GB, and it sits alongside whatever you already use for coding.
-1. Open VS Code.
-2. Go to **File → Open Folder** and pick a folder — an empty new one is perfect for a
- first try. **This step is required**: HirayaCoder refuses to do anything without a
- folder open, so that it can never touch files outside it.
-3. Press `Ctrl+Shift+H` (`Cmd+Shift+H` on a Mac).
-4. Type something and press Enter.
+**You can always see what it read.** Under your message there is a panel showing the
+exact description the vision model produced. Open it when an answer looks wrong, because
+it tells you whether the picture was misread or the answer was.
-Good first things to type:
-
-- `make a webpage that says hello with a big blue button`
-- `create a simple to-do list app in one HTML file`
-- `explain what this project does` *(in a folder that already has code)*
-
-**If anything above is unclear once you are in there, press *Guide* in the chat header.**
-It opens the same four setup steps and — more usefully — what to expect: how long a task
-takes, why a refusal is usually the checks working, and what a small model is and is not
-good at.
-
-There is a longer, friendlier walkthrough in
-[TUTORIAL.md](https://github.com/jaymar921/HirayaCoder/blob/main/doc/TUTORIAL.md).
+Full detail, including what it is bad at, is in
+[IMAGE-RECOGNITION.md](https://github.com/jaymar921/HirayaCoder/blob/main/doc/IMAGE-RECOGNITION.md).
---
-## Using it day to day
-
-
-
-
-
-### Watching a run happen
-
-
-
-
-
-A local model can take the better part of a minute per step, so the panel shows you each
-one as it happens: what it is doing, which file, and the reason the model gave for it.
-It opens when the first step arrives and folds away when the turn ends — and if you open
-or close it yourself, it stays how you left it.
-
-That matters most when a run is going wrong. Six steps in, you can see it re-reading the
-same file or editing something you never asked about, and stop it — rather than finding
-out from the summary ten minutes later.
-
-### Small models that finish
-
-
-
-
-
-The classic failure of a very small model is not bad code — it is the same correct-looking
-action forever. HirayaCoder keeps its own record of every file the agent has read, written
-and deleted, every folder it has listed and every command it has run, and puts that record
-in front of the model on each turn.
-
-A repeated read is no longer fatal either. Asking twice for a directory listing used to end
-the run; now the agent is handed back what it already had, told what to do next, and only
-stopped if it asks a third time.
-
-### Long requests, one step at a time
+## Limitations
-
-
-
-
-If you paste in a long, structured request — headings, numbered steps, a folder tree —
-HirayaCoder works through it **one section at a time**, in your order, using your words.
-It does not ask the model to summarise your request first: your headings already are the
-plan, and reading them takes no guesswork, so this works the same on a 0.8B model as on a
-large one.
-
-Two details worth knowing, because they let you steer it:
+Read this part. It is the honest description of the tool, and it will save you an
+evening if this is not what you need.
-- **Draw the folder structure you want** and it will be read as real paths. `src/` plus
- `components/` plus `TodoItem.jsx` becomes `src/components/TodoItem.jsx`.
-- **Put a comment next to a file** — `TodoItem.jsx # one todo row, with edit and
- delete` — and that comment becomes the instruction for writing it. A file with a
- comment beside it may be rewritten if it already exists; a file without one is left
- alone. That is how you say "this one is yours to write" and "this one came from the
- scaffolding tool, don't touch it".
+**It is not as clever as a paid cloud assistant.** It runs a small model on your own
+hardware. Small models handle ordinary, specific tasks well and vague, large ones badly.
+Ask for one page, one feature, or one fix at a time and it does a decent job. Ask for
+"a full social media app" and you will be disappointed.
-A section that only states rules — "React functional components only, no UI libraries" —
-is not treated as a step. It is carried underneath every step instead.
+**It does not finish a whole application.** This is measured, not guessed. On a brief for
+a complete React app, a small model scaffolds the project, writes every file you named,
+and installs the dependencies. Then the build fails, and no model at this size finished
+the app in any of our test runs.
-Short requests are unaffected. "Fix the typo in the heading" runs exactly as it always
-did.
+**It is slow.** On a 16 GB laptop with no graphics card, expect one to five minutes for
+an ordinary task. A graphics card makes it faster, not smarter. A bigger model makes it
+smarter, not faster.
-### Asked the wrong way
-
-
-
-
+**It never goes online.** No cloud models, no looking things up, no fetching
+documentation. The only address it will connect to is your own machine.
-The smallest models have a problem that looks like incompetence and is not. Asked to
-choose a tool and fill in its arguments as JSON, a 1B model will reliably answer with the
-simplest thing that satisfies the format — often just "done". Asked in plain English to
-write a file, the same model writes it correctly.
+**It cannot leave the folder you opened,** and it only runs commands from a fixed list
+(`node`, `npm`, `git`, `pytest` and about twenty more). There is no shell, so `&&`, `|`
+and `>` are refused rather than interpreted.
-So for a file **your request named**, HirayaCoder stops asking the model what to do. The
-decision is already made: the action is a file write, the path came from your own
-request, and the only question left is what goes in the file.
+**Small models make specific mistakes.** They repeat themselves, they report success
+having written nothing, and they occasionally write a file that parses fine but has an
+export deleted. There are checks for each of these, and the checks catch most of it
+rather than all of it.
-It is worth being precise about what that does and does not allow, because it is the one
-place the model is not choosing:
+**Image reading is approximate.** Large text and obvious subjects are reliable. Small
+text in a screenshot, exact numbers, and precise layout are not, and a misread arrives
+as a confident paragraph rather than as an apology.
-- It can only ever write a file **you named** in your request.
-- It never touches `package.json`, lockfiles, `.env`, or anything inside `node_modules`,
- `dist` or `.git`.
-- It never replaces a file that already exists unless you put a comment next to it.
-- Every write still shows you the diff and waits for approval, exactly as before, and
- still goes in the audit log.
-
-When it writes a file, it first reads what the files around it actually export, so the
-imports line up rather than being guessed at.
-
-### The three modes
-
-There is a row of buttons at the top of the chat. You can ignore them at first —
-**Agent** is the default and is what you want most of the time.
-
-| Mode | Use it when |
-|---|---|
-| **Agent** | You want it to actually write or change files. The normal choice. |
-| **Plan** | You want to see what it *would* do first, without it touching anything. |
-| **Ask** | You just have a question. It will not change any files. |
+The full version, including everything that is a deliberate design choice rather than a
+shortcoming, is in
+[LIMITATIONS.md](https://github.com/jaymar921/HirayaCoder/blob/main/doc/LIMITATIONS.md).
-You do not have to switch to Ask to ask a question — if you say "hello" or "what does
-this file do", Agent mode notices and just answers you.
-
-### Nothing changes without your say-so
+---
-By default, every time it wants to write to a file, you get a prompt with a **Review
-diff** button showing exactly what changes. Nothing is saved until you approve.
+## Will it run on my computer?
-Once you trust it, you can turn on **Auto Edit** to skip those prompts. Deleting a file
-always asks, even then.
+The question that matters is **how much RAM you have**. You do not need a graphics card.
-### Tips that make a real difference
+| Your computer | Will it work? | What to expect |
+|---|---|---|
+| 8 GB RAM | Just barely | Slow, simple single-file tasks only |
+| 16 GB RAM, no graphics card | **Yes, this is what it was built for** | A task takes 1 to 5 minutes |
+| 16 GB+ with a gaming graphics card | Comfortably | A task takes 20 to 60 seconds |
+| Mac with Apple Silicon (M1 to M4) | Very well | A task takes 10 to 30 seconds |
-- **Ask for one thing at a time — or structure the big ask.** "Add a delete button" works
- far better than "add delete, edit, sorting, and dark mode" thrown in as one sentence.
- If you do want the big one, give it headings, numbered steps or a folder tree, and it
- will work through them one at a time — see
- [Long requests, one step at a time](#long-requests-one-step-at-a-time).
-- **Name the file** if you know it. "Change the title in index.html" beats "change the
- title".
-- **It remembers this conversation**, so you can say "make it bigger" and it knows what
- "it" is.
-- **Be specific about what is wrong.** "The button doesn't do anything when I click it"
- is much more useful than "it's broken".
+To check on Windows: press `Ctrl+Shift+Esc`, click **Performance**, then **Memory**. On
+a Mac: Apple menu, then **About This Mac**.
---
-## When something goes wrong
+## Quick start
-Small AI models make mistakes. HirayaCoder has built-in checks that catch the common
-ones, so a few of the messages below are the system **working**, not breaking.
+Four steps. The
+[full walkthrough](https://github.com/jaymar921/HirayaCoder/blob/main/doc/GETTING-STARTED.md)
+explains each one properly if you want it.
-### "It refused to write the file"
+**1.** Install [VS Code](https://code.visualstudio.com), version 1.85 or newer.
-**This is usually a good thing.** HirayaCoder checks the AI's work before saving and
-blocks writes that would damage your files — a half-written file, code with a missing
-bracket, or a rewrite that quietly deletes something other files depend on.
+**2.** Install [Ollama](https://ollama.com) and leave it running. It has no window. It
+just sits in your system tray, and that is normal.
-Just ask again. It usually gets it right the second time.
+**3.** Download a model. Open a terminal and paste one line:
-### "It said it was done but nothing changed"
+```bash
+# 16 GB RAM or more, the best all-round choice. Reads images too
+ollama pull gemma4:e2b
-A known habit of small models: reporting success without doing the work. HirayaCoder
-checks and will tell you plainly when this happens. Ask again, and include the exact
-file name this time.
+# 8 GB RAM, or if the above is too slow
+ollama pull llama3.2:1b
+```
-### "It's taking forever"
+**4.** Download the `.vsix` from the
+[Releases page](https://github.com/jaymar921/HirayaCoder/releases) and install it:
-Normal on a laptop with no graphics card — a few minutes per task is expected. If it is
-much worse than that, the model is probably too big for your RAM. Try `llama3.2:1b`.
+```bash
+code --install-extension hirayacoder-.vsix
+```
-### "The code it wrote doesn't work"
+Then open a folder in VS Code (this is required, it refuses to work without one), press
+`Ctrl+Shift+H`, and type something. Good first tries:
-Try, in order:
+- `make a webpage that says hello with a big blue button`
+- `create a simple to-do list app in one HTML file`
+- `explain what this project does`
-1. Paste the error message into the chat. It is quite good at fixing errors it can see.
-2. Ask for a smaller piece of the problem.
-3. Switch to a bigger model if your RAM allows it.
+There is a **Guide** button in the chat header that repeats all of this from inside the
+extension.
-### "It can't run my program"
+---
-HirayaCoder can only run programs already installed on your computer. If you ask it to
-run a Python script, you need Python installed. It will still *write* the code — it just
-cannot run it for you.
+## The three modes
-It also only runs a fixed list of well-known commands. **This is the whole list** —
-anything else is refused on purpose, so a mistake by the AI cannot damage your system:
+There is a row of buttons at the top of the chat. Agent is the default and is what you
+want most of the time.
-| For | It may run |
+| Mode | Use it when |
|---|---|
-| JavaScript / Node | `node`, `npm`, `npx`, `yarn`, `pnpm` |
-| Python | `python`, `python3`, `pip`, `pip3`, `pytest` |
-| Java | `java`, `javac`, `mvn`, `gradle` |
-| Go, Rust, .NET | `go`, `cargo`, `dotnet` |
-| Testing and formatting | `jest`, `mocha`, `vitest`, `ava`, `tsc`, `eslint`, `prettier` |
-| Other | `git`, `make`, `ollama` |
-
-Two things worth knowing before they surprise you:
+| **Agent** | You want it to write or change files. The normal choice |
+| **Plan** | You want to see what it *would* do first, without it touching anything |
+| **Ask** | You just have a question |
-- **Everyday shell commands are not on the list** — `rm`, `ls`, `mkdir`, `curl` are all
- refused. Creating files and folders happens through the safe file tools instead, so
- `mkdir` is never needed: writing a file creates the folders above it.
-- **No shell is involved.** Commands run directly, so `&&`, `|`, and `>` are refused
- rather than interpreted. One command at a time.
-
-You can add to the list in HirayaCoder's settings. The AI cannot add to it itself.
+You do not have to switch to Ask to ask something. If you say "hello" or "what does this
+file do", Agent mode notices and just answers.
---
## Your privacy
-This is the part worth being blunt about, because it is the main reason to choose this
-over the alternatives.
+This is the main reason to choose this over the alternatives, so it is worth being blunt.
- **Nothing you type or open is sent anywhere.** The extension only ever talks to
`127.0.0.1`, which is your own computer. A non-local address is rejected in the code
itself, before any connection is opened.
- **No account, no sign-up, no telemetry.** Nobody is counting your keystrokes.
-- **It works with your Wi-Fi off.** Try it — that is the proof.
-- **The AI cannot leave your folder.** Every file operation is confined to the folder you
- opened.
+- **It works with your Wi-Fi off.** Try it. That is the proof.
+- **The AI cannot leave your folder.** Every file operation is confined to the folder
+ you opened.
- **No third-party code ships in the extension.** Zero production dependencies.
-Full detail: [SECURITY.md](https://github.com/jaymar921/HirayaCoder/blob/main/doc/SECURITY.md).
+Full detail in
+[SECURITY.md](https://github.com/jaymar921/HirayaCoder/blob/main/doc/SECURITY.md).
---
-## Choosing a model
-
-Model names are confusing. Here is a plain-language ranking, based on
-[real measurements](https://github.com/jaymar921/HirayaCoder/blob/main/doc/MODELS.md)
-rather than on the descriptions.
-
-| Model | Download | Needs | Verdict |
-|---|---|---|---|
-| `gemma4:e2b` | 7.2 GB | 16 GB RAM | **Best starting point.** Fastest to a correct answer |
-| `qwen3.5:4b` | 3.4 GB | 8–16 GB RAM | Good, smaller download |
-| `llama3.2:1b` | 1.3 GB | 8 GB RAM | For low-spec machines. Simple single-file jobs only |
-| `gemma4:e4b` | 9.6 GB | 32 GB RAM or a Mac | The strongest, if you have room |
-| `qwen3.5:0.8b` | 1.0 GB | — | Last resort. Writes files correctly; does not finish an app |
+## Documentation
-### What a very small model will and will not do
-
-Worth setting expectations, because the honest answer is more useful than the
-encouraging one. Measured on a 98-line brief for a complete React app:
-
-- **A 0.8B model now scaffolds the project, writes every file the request named, and
- installs the dependencies.** In the previous release the same model spent its whole
- session listing the directory and wrote nothing.
-- **It does not get the app working.** The build still fails, and no model at this size
- finished the app in any of our runs.
-
-So a very small model is genuinely useful for *"write me this file"* and for the parts of
-a big request that are mechanical. Handing it a whole application and walking away is not
-something we can recommend yet, and the numbers behind that are in
-[the evaluation notes](https://github.com/jaymar921/HirayaCoder/blob/main/doc/SESSION-ANALYSIS-0.9.0.md).
-
-Switch models any time from the dropdown at the top of the chat — no reinstall needed.
-
-**One thing that surprises people:** a graphics card makes it *faster*, not *smarter*.
-A bigger model gives better answers; a better GPU gives the same answer sooner.
+| | |
+|---|---|
+| [Getting started](https://github.com/jaymar921/HirayaCoder/blob/main/doc/GETTING-STARTED.md) | The complete first-run walkthrough |
+| [Using it day to day](https://github.com/jaymar921/HirayaCoder/blob/main/doc/USING-IT.md) | Modes, watching a run, and the habits that make small models work |
+| [Reading images](https://github.com/jaymar921/HirayaCoder/blob/main/doc/IMAGE-RECOGNITION.md) | Attaching screenshots and photos |
+| [Limitations](https://github.com/jaymar921/HirayaCoder/blob/main/doc/LIMITATIONS.md) | What it cannot do, by design and otherwise |
+| [Troubleshooting](https://github.com/jaymar921/HirayaCoder/blob/main/doc/TROUBLESHOOTING.md) | When something goes wrong |
+| [Choosing a model](https://github.com/jaymar921/HirayaCoder/blob/main/doc/CHOOSING-A-MODEL.md) | Which one to download, in plain language |
+| [Tutorial](https://github.com/jaymar921/HirayaCoder/blob/main/doc/TUTORIAL.md) | A longer, friendlier walkthrough |
+
+**For developers:**
+[Developing](https://github.com/jaymar921/HirayaCoder/blob/main/doc/DEVELOPING.md) ·
+[Architecture](https://github.com/jaymar921/HirayaCoder/blob/main/doc/ARCHITECTURE.md) ·
+[Features and settings](https://github.com/jaymar921/HirayaCoder/blob/main/doc/FEATURES.md) ·
+[Measurements](https://github.com/jaymar921/HirayaCoder/blob/main/doc/MODELS.md) ·
+[Security model](https://github.com/jaymar921/HirayaCoder/blob/main/doc/SECURITY.md) ·
+[Benchmarks](https://github.com/jaymar921/HirayaCoder/blob/main/benchmarks/README.md)
---
-## For developers
-
-Everything above is the beginner's path. The rest is the engineering, and it is
-documented properly elsewhere.
-
-**Features and settings** — [FEATURES.md](https://github.com/jaymar921/HirayaCoder/blob/main/doc/FEATURES.md)
-· **How it is built** — [ARCHITECTURE.md](https://github.com/jaymar921/HirayaCoder/blob/main/doc/ARCHITECTURE.md)
-· **Measurements** — [MODELS.md](https://github.com/jaymar921/HirayaCoder/blob/main/doc/MODELS.md)
-· **Security model** — [SECURITY.md](https://github.com/jaymar921/HirayaCoder/blob/main/doc/SECURITY.md)
-
-### What is interesting about it technically
-
-- **Agentic on every model, down to 1B.** It plans, reads, edits, deletes, and runs
- scripts across multiple files on its own. Two loop strategies — native tool-calling for
- capable models, a constrained one-action-per-turn JSON loop for small ones — behind one
- driver, so the mechanism changes with the model but the reach never does.
-- **Three layers of local memory.** A plain-text session log, the conversation itself,
- and typed facts about the project that persist across sessions, so the second session
- does not rediscover what the first one paid for.
-- **"Done" has to be true.** A run that reports success having written nothing, or having
- left `// Implement this here` inside a function it just wrote, gets sent back once with
- the specific problem named. Completion is judged from what changed on disk, never from
- what the model says about itself.
-- **It learns from what actually happened.** Outcomes are recorded locally — counts and
- guard codes, never your code — and a model that trips the same guard three times gets
- the matching correction added to its prompt. It adapts what the model is *told*, never
- what it is *allowed to do*.
-- **Every guard names a real failure.** The write guards exist because four different
- models produced six damaged files in one seventeen-run sweep: deleted exports, a
- CommonJS module silently rewritten as ESM, an implementation replaced by an empty
- object. Every one of them parsed cleanly.
-
-### Benchmarks
-
-Measured on three named machines, with the delete declined at the prompt on purpose — a
-model that claims it deleted the file has failed the task whatever else it got right.
-There are four harnesses: editing an existing project, building one from an empty folder,
-wiring an existing project together, and — new in 0.9.0 — building a whole application
-from one brief and then **driving the finished thing**, either by clicking every control
-in a headless browser or by calling its service layer directly.
-
-That last harness runs four briefs, so a model's trouble with the work can be told apart
-from its trouble with the language it was asked to work in:
-
-| Brief | Stack | Graded by |
-|---|---|---|
-| TODO app | React + Vite + Tailwind | 12 features, clicked in a browser |
-| Contact manager | React + Vite + Vitest | 12 features, clicked in a browser |
-| Point of sale | Java + Swing + Maven | 8 features, through the service layer |
-| Point of sale | Python + Tkinter, stdlib only | 8 features, through the service layer |
-
-It exists because of a result worth stating plainly: a model passed the scaffold,
-structure, install and build checks, and shipped an app whose only button incremented
-Vite's demo counter. Four green gates and nothing that worked. The full
-tables, including what each model broke and how, are in
-[MODELS.md](https://github.com/jaymar921/HirayaCoder/blob/main/doc/MODELS.md) and
-[benchmarks/](https://github.com/jaymar921/HirayaCoder/blob/main/benchmarks/README.md).
-
-The finding worth repeating here: **the mocked test suite passes clean while a real model
-destroys a real file.** Nearly every serious bug in this project was found by running an
-actual model, never by the unit tests.
-
-### Building from source
+## Building from source
Needs Node.js 18 or newer.
@@ -462,53 +232,28 @@ npm run test:all # lint + unit + integration, against a real VS Code
npm run package # builds builds/v/hirayacoder-.vsix
```
-### Contributing
-
-Contributions are welcome, with **one hard rule: pull requests only — never push
-directly to `main`.** CI runs the suite on Ubuntu, macOS, and Windows, and that matrix is
-the only evidence this project has that anything works on the two platforms the
-maintainer does not own.
-
-Read [CONTRIBUTING.md](https://github.com/jaymar921/HirayaCoder/blob/main/CONTRIBUTING.md)
-first. The short version:
-
-- Branch and commit as `feat/…`, `fix/…`, `docs/…`.
-- `npm run test:all` must pass.
-- **If you touched the agent loop, prompts, translator, or tools, run a real model**
- (`node tools/bench-agent.js gemma4:e2b agent auto full`) and put the outcome in the PR.
-- Don't weaken a guard or a permission prompt to make something pass.
-- Comments explain *why*, not *what*.
-
-Security issues: please contact [jaymar921](https://github.com/jaymar921) directly rather
-than opening a public issue.
-
-### Repository layout
-
-```
-HirayaCoder/
-├── app/ # Extension source — agent loops, tools, security layer, webview
-├── test/ # Unit + integration tests
-├── doc/ # Architecture, features, models, tutorial, security, publishing
-├── setup/ # AI build prompt + versioned model/translator system prompts
-├── security/ # Threat model, SAST reports
-├── scripts/ # Packaging
-├── tools/ # Live-model benchmark harnesses
-└── builds/ # Packaged .vsix output, per version (gitignored)
-```
+Contributions are welcome, with one hard rule: **pull requests only, never push directly
+to `main`.** Read
+[CONTRIBUTING.md](https://github.com/jaymar921/HirayaCoder/blob/main/CONTRIBUTING.md)
+first, and see
+[DEVELOPING.md](https://github.com/jaymar921/HirayaCoder/blob/main/doc/DEVELOPING.md)
+for what is worth knowing before you change the agent loop.
---
## Built from an AI prompt
This project was scaffolded from a single structured specification designed for AI
-coding agents. See [PROMPT.md](https://github.com/jaymar921/HirayaCoder/blob/main/setup/PROMPT.md)
-for the full build order, feature list, and security requirements.
+coding agents. See
+[PROMPT.md](https://github.com/jaymar921/HirayaCoder/blob/main/setup/PROMPT.md) for the
+full build order, feature list, and security requirements.
## Author
-Built by [**jaymar921**](https://github.com/jaymar921) — practical, resourceful, and made
+Built by [**jaymar921**](https://github.com/jaymar921). Practical, resourceful, and made
for real hardware rather than top-spec dev machines.
## License
-Licensed under the terms in [LICENSE](https://github.com/jaymar921/HirayaCoder/blob/main/LICENSE).
+Licensed under the terms in
+[LICENSE](https://github.com/jaymar921/HirayaCoder/blob/main/LICENSE).
diff --git a/app/agent/agentSession.js b/app/agent/agentSession.js
index 5ca93c7..3bdc8f8 100644
--- a/app/agent/agentSession.js
+++ b/app/agent/agentSession.js
@@ -28,6 +28,7 @@ const fs = require('fs');
const logger = require('../utils/logger');
const pathGuard = require('../security/pathGuard');
const promptRouter = require('../core/promptRouter');
+const imageRecognition = require('../core/imageRecognition');
const requestPlan = require('../core/requestPlan');
const fileTree = require('../core/fileTree');
const fileSpec = require('../core/fileSpec');
@@ -194,6 +195,15 @@ class ChangeSet {
* @property {'agent' | 'plan' | 'ask'} mode
* @property {string[]} [plan] Plan-mode steps, ready for the checklist UI.
* @property {import('./todoList').TodoItem[]} [todos] Items and their outcomes, when a list was used.
+ * @property {string} [model] Which model produced this reply.
+ * @property {number} [ms] Wall clock for the run, excluding any queue wait —
+ * `run` is not entered until the turn owns the lane, so this is time the user spent
+ * watching *this* model rather than another tab's.
+ * @property {number} [modelMs] Of that, time spent waiting on Ollama.
+ * @property {{model: string, ms: number}} [vision] Set only when a *different* model
+ * read the attached images. Without it the headline duration silently includes a
+ * second model's load and inference, which is the one thing the footer exists to
+ * make visible.
*/
/** No item can succeed in fewer than a read, a write, and a finish. */
@@ -611,6 +621,46 @@ class AgentSession {
* trace and observations carry the conversation from there.
*/
this.images = Array.isArray(options.images) ? options.images : [];
+ /**
+ * The same images, with their names and their bytes, for recognition.
+ *
+ * `images` is base64 alone because that is the shape Ollama's message format wants.
+ * Describing one needs a name to put in front of the description — "screenshot.png:
+ * a login form" is readable where three unlabelled paragraphs are not — so the
+ * fuller records are carried alongside rather than reconstructed.
+ *
+ * Falls back to wrapping `images` when only those were given, which is what every
+ * existing caller and every older test does.
+ *
+ * @type {Array<{name?: string, base64: string}>}
+ */
+ this.imageFiles =
+ Array.isArray(options.imageFiles) && options.imageFiles.length > 0
+ ? options.imageFiles
+ : this.images.map((base64, index) => ({ name: `image ${index + 1}`, base64 }));
+ /**
+ * How an attached image is turned into words, and by which model.
+ *
+ * `{ enabled, describeModel }` — `describeModel` is the name chosen by
+ * `imageRecognition.pickDescriber`, resolved by the caller because only it has the
+ * list of installed models. Null or absent means no vision model is installed, in
+ * which case an image reaches the model only if the selected model can see it
+ * directly, and otherwise not at all.
+ *
+ * `activeCanSee` is stated separately rather than inferred from
+ * `describeModel === model`, because the two answer different questions: whether
+ * the raw picture may ride on the message, and who writes the description. A user
+ * who pins a describer in settings makes those diverge.
+ *
+ * @type {{enabled?: boolean, describeModel?: string | null, activeCanSee?: boolean} | null}
+ */
+ this.vision = options.vision || null;
+ /**
+ * This turn's descriptions, produced once and carried on every turn after.
+ *
+ * @type {import('../core/imageRecognition').ImageDescription[]}
+ */
+ this._imageDescriptions = [];
this.scriptTimeoutMs = options.scriptTimeoutMs;
/**
* Where this session's evidence goes, and where the previous ones' came from.
@@ -835,12 +885,19 @@ class AgentSession {
// "Read the README" should not be able to reach `run_script`, whatever the
// planner decides in between. See `intentRouter.isReadOnlyRequest`.
readOnlyTurn: intentRouter.isReadOnlyRequest(task, this.conversation),
+ // Changes the instruction, never the tools. See `promptRouter.IMAGE_SUFFIX`.
+ hasImages: this.imageFiles.length > 0,
});
if (activeRoute.readOnlyTurn) {
logger.info('This message asks to look, not to change; the mutating tools are not offered this turn.');
}
+ // Before the first context is built and before any loop starts, so every turn
+ // downstream sees the same words. Routed first because what the description is
+ // for — answering a question, or doing a job — depends on which strategy won.
+ const imageNotes = await this._describeImages(activeRoute, task, emit);
+
emit({
type: 'start',
mode,
@@ -854,7 +911,9 @@ class AgentSession {
// Ask mode, and Agent mode answering conversation: one response, no loop, no
// tools in existence.
if (activeRoute.strategy === 'none' || activeRoute.strategy === 'chat') {
- const askContext = await this._buildContext(task, activeRoute, options.editor);
+ const askContext = await this._buildContext(task, activeRoute, options.editor, {
+ imageDescriptions: imageNotes,
+ });
const summary = await this._answerDirectly(task, activeRoute, askContext);
// Nothing else records a conversational turn: no steps, no change set, no file
// history. Without this the whole exchange leaves memory empty.
@@ -892,7 +951,9 @@ class AgentSession {
client: this.client,
model: this.model,
task,
- context: await this._buildContext(task, activeRoute, options.editor),
+ context: await this._buildContext(task, activeRoute, options.editor, {
+ imageDescriptions: imageNotes,
+ }),
signal: this._controller.signal,
})
: null;
@@ -904,7 +965,9 @@ class AgentSession {
// Tier B budget is a measurable waste and reads to the model as emphasis it
// was never meant to carry.
const effectiveTask = plan && plan.length > 0 ? `${task}\n\nYour plan:\n${plan.join('\n')}` : task;
- const context = await this._buildContext(effectiveTask, activeRoute, options.editor);
+ const context = await this._buildContext(effectiveTask, activeRoute, options.editor, {
+ imageDescriptions: imageNotes,
+ });
const loop = activeRoute.strategy === 'native' ? nativeToolLoop : reactLoop;
const outcome = await loop.run({
@@ -919,7 +982,7 @@ class AgentSession {
verifyDone: mode === 'agent' ? this._doneVerifier(task, changeSet, 0) : undefined,
onEvent: emit,
signal: this._controller.signal,
- images: this.images,
+ images: this._visibleImages(),
});
await this._remember(outcome.steps);
@@ -1758,8 +1821,17 @@ class AgentSession {
.replace(/[.,;:!?)\]]+$/, '');
if (!target || seen.has(target)) continue;
seen.add(target);
- if (UNDICTATABLE.test(target)) continue;
+ // Length-bounded check first, then the pattern.
+ //
+ // Both are `continue` guards with no side effects, so the order is free to
+ // choose — and this way the only unbounded regex in this path never sees a string
+ // longer than `MAX_TARGET_PATH_CHARS`. `UNDICTATABLE` measures linear even on a
+ // 40,000-character adversarial input (0.03 ms), so this is not a fix for a live
+ // ReDoS; it is the cheap ordering that means one is never reachable here if the
+ // pattern is ever edited into an ambiguous one. `target` is model output, which
+ // is the input class this project does not extend trust to.
if (!isDictatableFilename(target)) continue;
+ if (UNDICTATABLE.test(target)) continue;
// You cannot fill in a project that has not been created yet.
//
@@ -2286,6 +2358,28 @@ class AgentSession {
const modelMs =
typeof this._modelMsAtStart === 'number' ? this._modelMsSoFar() - this._modelMsAtStart : undefined;
+ // Attached to the result as well as logged. The panel shows this under every reply
+ // so that switching models is a comparison rather than a guess — which is the whole
+ // reason anyone switches on this hardware.
+ //
+ // Mutating the caller's object rather than threading a return value through: every
+ // path in `run` awaits this before returning the same object, so there is exactly
+ // one place to set it.
+ result.model = this.model;
+ if (typeof ms === 'number') result.ms = ms;
+ if (typeof modelMs === 'number') result.modelMs = modelMs;
+
+ // Only when a *different* model did the looking. When the selected model described
+ // its own image there is no second cost to account for, and naming it twice reads
+ // as though there were.
+ const described = this._imageDescriptions.filter((entry) => entry.model !== this.model);
+ if (described.length > 0) {
+ result.vision = {
+ model: described[0].model,
+ ms: described.reduce((total, entry) => total + (entry.ms || 0), 0),
+ };
+ }
+
// Logged whether or not the ledger is on. Adaptation is a choice about whether the
// extension *learns*; how long a turn took is the first thing anyone needs when a
// session felt slow, and the output channel is where they will look for it.
@@ -2391,9 +2485,11 @@ class AgentSession {
* @param {string} task
* @param {import('../core/promptRouter').Route} activeRoute
* @param {object} [editor]
- * @param {{recallAbout?: string}} [opts] What this turn is about, for targeted
- * memory recall. Empty means recency, which is the behaviour everywhere but a
- * briefed step.
+ * @param {{recallAbout?: string, imageDescriptions?: string}} [opts]
+ * `recallAbout` is what this turn is about, for targeted memory recall; empty means
+ * recency, which is the behaviour everywhere but a briefed step. `imageDescriptions`
+ * is the rendered block from `_describeImages`, threaded through rather than read
+ * off the session so a briefed step can decide for itself whether to carry it.
* @returns {Promise}
* @private
*/
@@ -2428,7 +2524,23 @@ class AgentSession {
// twice in one session, once for a greeting and once for "I'm Jay". The chat
// route exists for messages that are not about the project, and giving it the
// one block that is guarantees the reply will be.
- projectOverview: activeRoute.strategy === 'chat' ? '' : projectOverview.build(this.workspaceRoot),
+ //
+ // Also dropped on a loopless turn that carries an image, which is the same
+ // failure with a different trigger. Measured on `minicpm-v4.6`: "describe the
+ // image" with a photograph attached returned a description of HirayaCoder. The
+ // picture was on the message and the model can see — it scores 24/24 on this
+ // exact photograph in `tools/bench-vision.js` — but it was handed 2,500
+ // characters of project description and file listing with the task on the last
+ // line, and a small model resolves that by weight.
+ //
+ // Only the loopless routes. In Agent and Plan the listing is load-bearing: a
+ // model asked to build the screen in a mockup needs to know which paths exist,
+ // and there the picture is not competing with the project, it is a fact about
+ // the job.
+ projectOverview:
+ activeRoute.strategy === 'chat' || (loopless && this.imageFiles.length > 0)
+ ? ''
+ : projectOverview.build(this.workspaceRoot),
// A model that has to discover the file tree spends steps on it and, worse,
// invents paths when it guesses. Seeding the listing costs a fraction of the
// budget and removes the most common failure on Tier B outright.
@@ -2439,7 +2551,14 @@ class AgentSession {
// routinely asked what is *in* the project, and with an empty listing it answered
// "There are no files listed in your workspace" — in a workspace of several
// hundred files. Naming what exists is not an action; it is the answer.
- workspaceFiles: await this._workspaceFiles(activeRoute),
+ // Suppressed alongside the project overview, and for the same measured reason: on
+ // a turn with no tools, the listing is orientation the model cannot act on, and
+ // forty file paths outweigh one line of task.
+ workspaceFiles: loopless && this.imageFiles.length > 0 ? [] : await this._workspaceFiles(activeRoute),
+ // Carried on every turn of the run, unlike the image itself. That is the whole
+ // point of producing it: the picture reaches turn one and the words reach all of
+ // them.
+ imageDescriptions: opts.imageDescriptions || '',
});
return built.text;
@@ -2582,6 +2701,9 @@ class AgentSession {
* @param {string} [opts.systemPrompt] Reused for the redraft, so the corrected answer
* is bound by the same mode rules as the draft. Falls back to a minimal instruction.
* @param {string} [opts.context] The context the draft was written from.
+ * @param {boolean} [opts.images] Re-attach this turn's images to the redraft.
+ * Set by the Ask path, where the draft was written from a picture; a redraft
+ * without it argues the model out of an answer it got right.
* @returns {Promise}
* @private
*/
@@ -2607,7 +2729,15 @@ class AgentSession {
opts.systemPrompt ||
'You are HirayaCoder. Answer the user\'s question directly and concisely, in prose.',
},
- ...(opts.context ? [{ role: 'user', content: opts.context }] : []),
+ ...(opts.context
+ ? [
+ {
+ role: 'user',
+ content: opts.context,
+ ...(opts.images && this._visibleImages().length > 0 ? { images: this._visibleImages() } : {}),
+ },
+ ]
+ : []),
{
role: 'user',
content:
@@ -2647,6 +2777,114 @@ class AgentSession {
}
}
+ /**
+ * The base64 images that may ride on an Ollama message this turn.
+ *
+ * Empty whenever the selected model has no vision capability. Sending an image to a
+ * model that cannot see one is not an error at the API level — it is silently
+ * dropped, after being uploaded — so the only effect is a slower turn. The picture
+ * still reaches such a model, as the description assembled by `_describeImages`.
+ *
+ * @returns {string[]}
+ * @private
+ */
+ _visibleImages() {
+ if (this.images.length === 0) return [];
+ // Absent vision config is the pre-1.1.0 shape, where the caller had already refused
+ // to attach an image to a model that could not see it. Trusting it keeps every
+ // existing caller and test working unchanged.
+ if (!this.vision) return this.images;
+ return this.vision.activeCanSee === false ? [] : this.images;
+ }
+
+ /**
+ * Turn this turn's attached images into text, once.
+ *
+ * ## Why Ask mode on a vision model skips this entirely
+ *
+ * There the picture itself goes on the message and the model answers from it
+ * directly. A description pass would be a second full generation — a minute or more
+ * on CPU — to produce a paraphrase that is strictly worse than the original for the
+ * one model that was going to look at the original anyway.
+ *
+ * Every other combination needs it. Agent and Plan run a loop whose later turns have
+ * no picture, and a model without vision has no picture on any turn.
+ *
+ * @param {import('../core/promptRouter').Route} activeRoute
+ * @param {string} task
+ * @param {(event: object) => void} emit
+ * @returns {Promise} The rendered prompt block, or '' when there is none.
+ * @private
+ */
+ async _describeImages(activeRoute, task, emit) {
+ this._imageDescriptions = [];
+ if (this.imageFiles.length === 0) return '';
+
+ const vision = this.vision || {};
+ if (vision.enabled === false) {
+ logger.info('Image recognition is turned off in settings; the attached image is not being read.');
+ return '';
+ }
+
+ const loopless = activeRoute.strategy === 'none' || activeRoute.strategy === 'chat';
+ const purpose = loopless ? 'answer' : 'task';
+
+ if (loopless && vision.activeCanSee !== false) return '';
+
+ const describer = vision.describeModel || (vision.activeCanSee === false ? null : this.model);
+ if (!describer) {
+ logger.warn('An image was attached but no installed model can read one.');
+ return '';
+ }
+
+ const started = Date.now();
+ this._imageDescriptions = await imageRecognition.describeAll({
+ client: this.client,
+ model: describer,
+ images: this.imageFiles,
+ purpose,
+ // Only the answering purpose gets the question. A task-purpose description is
+ // read by the loop on every turn, and steering it with turn one's wording makes
+ // it progressively less useful as the run moves on to the other items.
+ question: purpose === 'answer' ? task : '',
+ signal: this._controller ? this._controller.signal : undefined,
+ onProgress: ({ index, total, name }) => {
+ // A vision pass on CPU is thirty seconds to two minutes with no step counter
+ // moving, which reads as a hang. This is the only thing on screen during it.
+ emit({
+ type: 'status',
+ text:
+ total === 1
+ ? `Reading ${name} with ${describer}…`
+ : `Reading ${name} with ${describer} (${index} of ${total})…`,
+ });
+ },
+ });
+
+ const failed = this._imageDescriptions.filter((entry) => !entry.ok);
+ if (failed.length > 0) {
+ logger.warn(`${failed.length} of ${this._imageDescriptions.length} image(s) could not be described.`);
+ }
+
+ const readable = this._imageDescriptions.filter((entry) => entry.ok);
+ logger.info(
+ `Described ${readable.length} image(s) with ${describer} in ${Math.round((Date.now() - started) / 1000)}s.`
+ );
+
+ // Shown in the transcript rather than only logged: the description is the whole
+ // basis of the answer that follows, and a user who can read it can tell a
+ // misreading from a bad answer. That distinction is invisible otherwise.
+ if (readable.length > 0) {
+ emit({
+ type: 'images-described',
+ model: describer,
+ descriptions: readable.map((entry) => ({ name: entry.name, description: entry.description })),
+ });
+ }
+
+ return imageRecognition.renderForPrompt(readable);
+ }
+
/**
* Ask mode. One call, no tools offered at all.
*
@@ -2664,7 +2902,10 @@ class AgentSession {
messages: [
{ role: 'system', content: activeRoute.systemPrompt },
// Ollama takes images as base64 on the message itself.
- { role: 'user', content: context, ...(this.images.length > 0 ? { images: this.images } : {}) },
+ ...(() => {
+ const visible = this._visibleImages();
+ return [{ role: 'user', content: context, ...(visible.length > 0 ? { images: visible } : {}) }];
+ })(),
],
options: { temperature: 0.3 },
},
@@ -2673,7 +2914,16 @@ class AgentSession {
const draft =
String((response && response.message && response.message.content) || '').trim() || 'No answer was produced.';
// Nothing this path does can change a file, so a changelog here is always wrong.
- return this._rethink(task, draft, { changedFiles: false, systemPrompt: activeRoute.systemPrompt, context });
+ return this._rethink(task, draft, {
+ changedFiles: false,
+ systemPrompt: activeRoute.systemPrompt,
+ context,
+ // The redraft used to go out blind. A reply about a photograph, sent back to be
+ // corrected without the photograph, was rewritten into a hedge about not being
+ // able to see it — the check firing on a good answer and replacing it with a
+ // worse one. Whatever the draft could see, the redraft sees too.
+ images: true,
+ });
} catch (err) {
return `The model could not be reached: ${/** @type {Error} */ (err).message}`;
}
diff --git a/app/core/contextBuilder.js b/app/core/contextBuilder.js
index 254c983..77fa8be 100644
--- a/app/core/contextBuilder.js
+++ b/app/core/contextBuilder.js
@@ -16,7 +16,8 @@
*
* The priority order below encodes that judgment:
*
- * task > latest observation > session memory > selection > context files > open file
+ * task > latest observation > attached images > session memory > selection >
+ * context files > open file
*
* The task is non-negotiable. The latest observation ranks second because a ReAct
* loop that forgets what its last action returned will repeat it forever. Memory
@@ -48,6 +49,12 @@ const PRIORITY = {
// are the thing being referred to. Notes are a compression of the same material, so
// when only one survives the budget it should be the primary source.
conversation: 85,
+ // Above the conversation and everything below it, and only just below the last
+ // observation. When the selected model cannot see, this block is the *only* form the
+ // attached image takes — dropping it does not degrade the answer, it removes the
+ // thing the user was asking about. It is also small: a description is capped at
+ // ~1600 characters, so ranking it high costs little.
+ imageDescriptions: 88,
memory: 80,
// Above the selection and everything below it. This block is ~100 tokens that say
// what the project is in its author's own words, and without it the model answers
@@ -82,6 +89,7 @@ const PRIORITY = {
* @property {string} [contextFiles] Rendered block from contextFilesManager.
* @property {string} [observation] Result of the previous agent step.
* @property {string[]} [workspaceFiles] Nearby paths, for orientation.
+ * @property {string} [imageDescriptions] Rendered block from core/imageRecognition.
* @property {Array<{role: string, text: string}>} [conversation]
* Earlier turns of this chat, oldest first, excluding the message being answered.
*/
@@ -179,6 +187,30 @@ function build(request) {
}
}
+ if (request.imageDescriptions) {
+ sections.push({
+ name: 'Images',
+ // Redacted like every other block here, and for a reason that is easy to miss: a
+ // description is model prose, but the prose is *about a picture of the user's
+ // screen*. A screenshot of a terminal with `export OPENAI_API_KEY=sk-…` in it
+ // produces a description containing the key, and the recognition prompt asks the
+ // describer to copy visible text exactly — so this path does not merely permit
+ // that, it requests it.
+ //
+ // `redact` replaces the matched secret and leaves the sentence around it standing,
+ // so the description stays useful.
+ content: redact(request.imageDescriptions),
+ priority: PRIORITY.imageDescriptions,
+ // High, and higher than any other section's floor. A description trimmed to two
+ // sentences keeps "a screenshot of a form" and loses the error message on it,
+ // which is invariably the part the user attached it for. Better to drop the
+ // block whole and have the model say it was not given the image than to hand it
+ // a fragment it will answer confidently from.
+ minTokens: 120,
+ keep: 'head',
+ });
+ }
+
if (request.projectOverview) {
sections.push({
name: 'Project',
diff --git a/app/core/imageRecognition.js b/app/core/imageRecognition.js
new file mode 100644
index 0000000..168b0f7
--- /dev/null
+++ b/app/core/imageRecognition.js
@@ -0,0 +1,474 @@
+'use strict';
+
+/**
+ * Image recognition — turning a picture into words the rest of the agent can use.
+ *
+ * `features/imageContext` reads an image off disk and hands back base64. This module is
+ * the step after: it asks a vision model what the picture actually contains and returns
+ * that as plain text. Everything downstream — the ReAct loop, the native tool loop, Ask
+ * mode's single call, the summary — consumes text and nothing else, so a description is
+ * the only form in which an image can reach them.
+ *
+ * ## Why a description exists at all, when Ollama accepts images directly
+ *
+ * Three separate reasons, and each one on its own would be enough.
+ *
+ * **The picture does not survive the loop.** Images ride on the first message only —
+ * see `AgentSession.images` for why re-uploading 5 MB of base64 every turn is not an
+ * option. So on turn four of an eight-step run the model is working from a conversation
+ * about an image it can no longer see. A description is a hundred tokens and can be
+ * carried on every turn.
+ *
+ * **Most models cannot see.** `llama3.2` is the model a lot of people are actually
+ * running, and it has no vision capability at all. Before this, attaching an image to
+ * it was simply refused. Now the picture goes to whichever vision model is installed,
+ * the description comes back, and the coding model works from that. The user does not
+ * have to switch models to use a screenshot.
+ *
+ * **A description can be checked.** A model that hallucinates an image is invisible when
+ * the image is a blob on a message; when it is a paragraph of text in the transcript,
+ * the user reads "a red error dialog" over their green one and knows immediately.
+ *
+ * ## Why the active model is preferred even when it is the worse describer
+ *
+ * Ollama holds one model resident at a time. Describing with a different model evicts
+ * the coding model and pays its load time twice — on a 16 GB laptop with no GPU that is
+ * thirty to sixty seconds of nothing happening, before the actual request has started.
+ * When the selected model can see, using it is free; when it cannot, the smallest
+ * installed vision model is chosen, because a description is a read rather than a piece
+ * of reasoning and the smallest model that can do it is the one that finishes soonest.
+ *
+ * @module core/imageRecognition
+ */
+
+const crypto = require('crypto');
+
+const logger = require('../utils/logger');
+
+/**
+ * What the describer is asked for, per purpose.
+ *
+ * ## Why there are two of these and not one
+ *
+ * The two callers want genuinely different things out of the same picture, and a single
+ * prompt serves neither well.
+ *
+ * Ask mode is a person holding up a photograph. What matters is the subject, what it is
+ * doing, and how it looks — the answer to "what is this?" is a sentence about a dog, not
+ * an inventory of pixel regions.
+ *
+ * Agent and Plan mode are a coding agent that will act on what it is told. There the
+ * priority inverts: every character of text in the image outranks every adjective,
+ * because a misread identifier sends the agent to edit a file that does not exist, and
+ * a wrong colour costs nothing. So the task prompt puts transcription first and says
+ * plainly that guessing is worse than admitting the text is unreadable.
+ *
+ * Both are short and numbered on purpose. A 0.8B model given a paragraph of nuanced
+ * instruction answers the paragraph; given four numbered points it answers the points.
+ */
+const PROMPTS = {
+ answer: [
+ 'Look at this image and describe what is in it.',
+ '',
+ 'Cover these, in order:',
+ '1. The main subject, in a few words.',
+ '2. What it is doing, or how it is arranged.',
+ '3. The setting, the colours, and anything else that stands out.',
+ '4. Any text, numbers, or labels you can read, copied exactly.',
+ '',
+ 'Rules:',
+ '- Describe only what you can actually see. Do not guess at anything outside the frame.',
+ '- If you are unsure what something is, say so. A wrong confident answer is worse than an unsure one.',
+ '- Write plain prose, under 150 words. No headings and no bullet points.',
+ ].join('\n'),
+
+ task: [
+ 'You are the eyes of a coding agent. It cannot see this image. Your description is',
+ 'the only thing it will ever get, so write down what it needs in order to do the work.',
+ '',
+ 'Cover these, in order:',
+ '1. What kind of image this is — a screenshot, a diagram, a photo, a UI mockup, an error message.',
+ '2. Every piece of text, code, number, or label in it, copied exactly as written.',
+ '3. The layout: what is where, what is grouped with what, what is a button, a field, or a panel.',
+ '4. Colours, sizes, and spacing, where they look deliberate rather than incidental.',
+ '',
+ 'Rules:',
+ '- Point 2 matters more than the rest put together. A misread filename sends the agent to the wrong file.',
+ '- If text is too small or too blurred to read, write "unreadable" rather than guessing at it.',
+ '- Never invent a filename, an error code, or a line of code that is not visibly there.',
+ '- Describe only. Do not suggest what should be done about any of it.',
+ '- Under 250 words.',
+ ].join('\n'),
+};
+
+/**
+ * A describer denying that it can see.
+ *
+ * ## Why this is checked rather than trusted
+ *
+ * Found by `tools/bench-vision.js`, once in twenty-four runs of `qwen3.5:0.8b` — a
+ * model that reports the vision capability, that was sent the image, and that had
+ * described the same photograph correctly on the previous sample. The reply was:
+ *
+ * "I cannot see this image. I am an AI model designed to process text and provide
+ * information, but I do not have the ability to view or interpret visual content…"
+ *
+ * A small model's text-only training reasserting itself over what it was actually
+ * handed. Left alone, that paragraph becomes the description: it is stored, put in
+ * front of the coding model as "what is in this picture", and shown to the user in the
+ * panel. The coding model then works from a statement that no image exists, which is
+ * strictly worse than being told the read failed.
+ *
+ * So it is treated as a failed call, not as a description. `describe` already has an
+ * honest failure path, and this is one.
+ *
+ * The pattern is deliberately narrow. It requires a first-person inability *plus* a
+ * visual object, so an ordinary description containing "I cannot see the licence plate
+ * clearly" — which is exactly the hedging the prompt asks for — is not caught by it.
+ */
+const REFUSAL =
+ /\b(?:i (?:cannot|can't|can not|am unable to|don't have the ability to|do not have the ability to)|as an ai(?: model| language model)?,? i (?:cannot|can't))\b[^.]{0,80}\b(?:see|view|interpret|process|analyz|analys|look at|access)\w*\b[^.]{0,60}\b(?:image|images|picture|photo|photograph|visual|screenshot)/i;
+
+/**
+ * @param {string} text
+ * @returns {boolean}
+ */
+function looksLikeRefusal(text) {
+ // Only the opening matters. A model that produces a real description and then
+ // volunteers a disclaimer at the end has still described the picture, and discarding
+ // that would throw away a good answer over its last sentence.
+ return REFUSAL.test(text.slice(0, 400));
+}
+
+/**
+ * Hard ceiling on a stored description, in characters.
+ *
+ * A describer that ignores the word limit and free-associates for two thousand words
+ * would otherwise spend the whole Tier B prompt budget on one picture, evicting the
+ * task itself. Truncation is from the head, which is where the subject is.
+ */
+const MAX_DESCRIPTION_CHARS = 1600;
+
+/**
+ * Token ceiling for one description call.
+ *
+ * Roughly twice what the 250-word limit needs. Generous enough that a model that
+ * numbers its points is not cut off mid-sentence, tight enough that a model stuck in a
+ * loop stops rather than running to the request timeout.
+ */
+const DESCRIBE_NUM_PREDICT = 640;
+
+/**
+ * Descriptions already produced, keyed by image content plus purpose plus model.
+ *
+ * Attaching the same screenshot to three consecutive messages is completely ordinary,
+ * and each description is a full model call — thirty seconds or more on CPU. The key
+ * includes the model and the purpose because a different model or a different prompt is
+ * a different answer, not a cache hit.
+ *
+ * Bounded rather than unbounded: this lives for the lifetime of the extension host, and
+ * a base64 fingerprint is small but a description is not free.
+ *
+ * @type {Map}
+ */
+const cache = new Map();
+
+/** Descriptions kept before the oldest is evicted. */
+const CACHE_LIMIT = 32;
+
+/**
+ * @param {string} base64
+ * @param {string} purpose
+ * @param {string} model
+ * @returns {string}
+ */
+function fingerprint(base64, purpose, model) {
+ // sha256 of the bytes, not the whole base64 string as a key: the string is megabytes
+ // and would be held in the Map forever.
+ const digest = crypto.createHash('sha256').update(base64).digest('hex').slice(0, 32);
+ return `${model}${purpose}${digest}`;
+}
+
+/**
+ * @param {string} key
+ * @param {string} description
+ */
+function remember(key, description) {
+ // Re-inserting moves the entry to the end of the Map's insertion order, so a
+ // repeatedly used image is not the one evicted.
+ if (cache.has(key)) cache.delete(key);
+ cache.set(key, description);
+ while (cache.size > CACHE_LIMIT) {
+ const oldest = cache.keys().next();
+ if (oldest.done) break;
+ cache.delete(oldest.value);
+ }
+}
+
+/**
+ * Choose which model does the looking.
+ *
+ * @param {import('./modelDiscovery').DiscoveredModel[]} models Everything installed.
+ * @param {object} [opts]
+ * @param {string} [opts.activeModel] The model the user selected for coding.
+ * @param {string} [opts.preferred] From settings. Honoured only if it is installed
+ * and can actually see — a stale name in settings must not silently disable images.
+ * @returns {{name: string, reason: string, isActive: boolean} | null}
+ * Null when nothing installed can see, which is a real state and not an error.
+ */
+function pickDescriber(models, opts = {}) {
+ const installed = Array.isArray(models) ? models.filter((m) => m && m.name) : [];
+ const capable = installed.filter((m) => m.supportsVision);
+ if (capable.length === 0) return null;
+
+ const preferred = String(opts.preferred || '').trim();
+ if (preferred) {
+ const match = capable.find((m) => m.name === preferred);
+ if (match) {
+ return { name: match.name, reason: 'chosen in settings', isActive: match.name === opts.activeModel };
+ }
+ // Named but unusable. Worth a log line rather than silence: the user set this
+ // deliberately and is entitled to know it is not being honoured.
+ const installedButBlind = installed.find((m) => m.name === preferred);
+ logger.warn(
+ installedButBlind
+ ? `hirayacoder.vision.describeModel is set to ${preferred}, which is installed but cannot read images. Picking another.`
+ : `hirayacoder.vision.describeModel is set to ${preferred}, which is not installed. Picking another.`
+ );
+ }
+
+ const active = capable.find((m) => m.name === opts.activeModel);
+ if (active) {
+ return {
+ name: active.name,
+ reason: 'the selected model can read images itself',
+ isActive: true,
+ };
+ }
+
+ // Smallest first. A description is a read, not a piece of reasoning, and the whole
+ // cost of using a second model here is the time it takes to load and answer.
+ // `params` is null when Ollama did not report a size; those sort last rather than
+ // first, so an unknown quantity is never chosen over a known small one.
+ const smallest = capable
+ .slice()
+ .sort((a, b) => {
+ const left = typeof a.params === 'number' ? a.params : Number.POSITIVE_INFINITY;
+ const right = typeof b.params === 'number' ? b.params : Number.POSITIVE_INFINITY;
+ if (left !== right) return left - right;
+ return a.name.localeCompare(b.name);
+ })[0];
+
+ return {
+ name: smallest.name,
+ reason: `${opts.activeModel || 'the selected model'} cannot read images, so the smallest installed vision model does the looking`,
+ isActive: false,
+ };
+}
+
+/**
+ * @typedef {object} ImageDescription
+ * @property {string} name The file's basename, so the user can tell two apart.
+ * @property {string} description What the model saw, or the reason there is nothing.
+ * @property {string} model Which model produced it.
+ * @property {number} ms How long it took, for the status line and the benchmark.
+ * @property {boolean} ok False when the call failed; `description` is then the error.
+ */
+
+/**
+ * Describe one image.
+ *
+ * @param {object} options
+ * @param {import('./ollamaClient').OllamaClient} options.client
+ * @param {string} options.model
+ * @param {{name?: string, base64: string}} options.image
+ * @param {'answer' | 'task'} [options.purpose]
+ * @param {string} [options.question] What the user typed. Included for the `answer`
+ * purpose so a describer asked "what breed is this?" volunteers the breed rather
+ * than a generic caption that the answering model then cannot use.
+ * @param {AbortSignal} [options.signal]
+ * @returns {Promise}
+ */
+async function describe(options) {
+ const purpose = options.purpose === 'task' ? 'task' : 'answer';
+ const image = options.image || { base64: '' };
+ const name = image.name || 'the attached image';
+ const started = Date.now();
+
+ if (!image.base64) {
+ return { name, description: 'The image could not be read.', model: options.model, ms: 0, ok: false };
+ }
+
+ const key = fingerprint(image.base64, purpose, options.model);
+ const cached = cache.get(key);
+ if (cached !== undefined) {
+ logger.debug(`Reusing the description already produced for ${name}.`);
+ return { name, description: cached, model: options.model, ms: 0, ok: true };
+ }
+
+ // Appended rather than replacing the prompt: the four numbered points are what keeps
+ // a small model on task, and a question alone gets a one-word answer that is useless
+ // to anything downstream.
+ const question = String(options.question || '').trim();
+ // `purpose` is narrowed to one of two string literals at the top of this function,
+ // so this is a lookup of a constant key on a module constant.
+ // eslint-disable-next-line security/detect-object-injection
+ const basePrompt = PROMPTS[purpose];
+ const prompt =
+ purpose === 'answer' && question
+ ? `${basePrompt}\n\nThe user asked: "${question.slice(0, 300)}". Make sure your description covers whatever that question is about.`
+ : basePrompt;
+
+ try {
+ const response = await options.client.chat(
+ {
+ model: options.model,
+ messages: [{ role: 'user', content: prompt, images: [image.base64] }],
+ // A description is not a reasoning task, and on a hybrid model the thinking
+ // trace is pure cost here — it is not shown, not stored, and eats the token
+ // budget the description itself needs.
+ think: false,
+ options: {
+ // Low but not zero. At zero a small vision model repeats one clause until it
+ // hits the token ceiling, which is the single most common way these calls
+ // waste a minute.
+ temperature: 0.2,
+ num_predict: DESCRIBE_NUM_PREDICT,
+ },
+ },
+ { signal: options.signal }
+ );
+
+ let text = String((response && response.message && response.message.content) || '').trim();
+ if (!text) {
+ return {
+ name,
+ description: 'The model returned nothing for this image.',
+ model: options.model,
+ ms: Date.now() - started,
+ ok: false,
+ };
+ }
+
+ if (looksLikeRefusal(text)) {
+ logger.warn(`${options.model} replied that it cannot see images, having been sent one. Treating as a failed read.`);
+ return {
+ name,
+ description:
+ `${options.model} replied that it cannot read images, although it was sent one and reports ` +
+ 'that it can. Sending the message again usually works; a different vision model always does.',
+ model: options.model,
+ ms: Date.now() - started,
+ ok: false,
+ };
+ }
+
+ if (text.length > MAX_DESCRIPTION_CHARS) {
+ text = `${text.slice(0, MAX_DESCRIPTION_CHARS)}…`;
+ }
+
+ remember(key, text);
+ return { name, description: text, model: options.model, ms: Date.now() - started, ok: true };
+ } catch (err) {
+ const message = /** @type {Error} */ (err).message;
+ logger.warn(`Could not describe ${name}: ${message}`);
+ return {
+ name,
+ description: `This image could not be read (${message}).`,
+ model: options.model,
+ ms: Date.now() - started,
+ ok: false,
+ };
+ }
+}
+
+/**
+ * Describe several images, one after another.
+ *
+ * Sequential rather than parallel, and not as an oversight: Ollama serialises requests
+ * to one model anyway, so firing three at once produces three queued requests and one
+ * progress indicator that jumps from nothing to everything. In sequence the caller can
+ * say "reading screenshot 2 of 3", which on a minute-per-image machine is the
+ * difference between a slow feature and a broken one.
+ *
+ * @param {object} options
+ * @param {import('./ollamaClient').OllamaClient} options.client
+ * @param {string} options.model
+ * @param {Array<{name?: string, base64: string}>} options.images
+ * @param {'answer' | 'task'} [options.purpose]
+ * @param {string} [options.question]
+ * @param {AbortSignal} [options.signal]
+ * @param {(progress: {index: number, total: number, name: string}) => void} [options.onProgress]
+ * @returns {Promise}
+ */
+async function describeAll(options) {
+ const images = Array.isArray(options.images) ? options.images : [];
+ /** @type {ImageDescription[]} */
+ const out = [];
+
+ for (let index = 0; index < images.length; index += 1) {
+ // `index` is this loop's own counter over a local array.
+ // eslint-disable-next-line security/detect-object-injection
+ const image = images[index];
+ if (options.onProgress) {
+ options.onProgress({ index: index + 1, total: images.length, name: (image && image.name) || 'image' });
+ }
+ // Sequential on purpose; see the note above this function.
+ out.push(
+ await describe({
+ client: options.client,
+ model: options.model,
+ image,
+ purpose: options.purpose,
+ question: options.question,
+ signal: options.signal,
+ })
+ );
+ }
+
+ return out;
+}
+
+/**
+ * Render descriptions as the prompt block the context builder carries.
+ *
+ * ## Why the block says the agent cannot see the picture
+ *
+ * Without that sentence, a model handed "A screenshot of a login form with a red error
+ * reading 'Invalid credentials'" replies "I can see the error in your screenshot" — and
+ * then, one turn later, offers to look more closely at a part of it, which it cannot do.
+ * Naming the description as second-hand is what stops both.
+ *
+ * @param {ImageDescription[]} descriptions
+ * @returns {string} Empty when there is nothing to say, so the caller can skip the section.
+ */
+function renderForPrompt(descriptions) {
+ const usable = (descriptions || []).filter((entry) => entry && entry.description);
+ if (usable.length === 0) return '';
+
+ const plural = usable.length === 1 ? 'an image' : `${usable.length} images`;
+ const lines = usable.map((entry) => `${entry.name}:\n${entry.description}`);
+
+ return (
+ `The user attached ${plural}. You are not looking at ${usable.length === 1 ? 'it' : 'them'} — ` +
+ `what follows is a written description produced by a vision model, and it is everything you have. ` +
+ `Work from it, and do not offer to look at the ${usable.length === 1 ? 'image' : 'images'} more closely.\n\n` +
+ lines.join('\n\n')
+ );
+}
+
+/** Test seam. Nothing in the extension calls this. */
+function _clearCache() {
+ cache.clear();
+}
+
+module.exports = {
+ pickDescriber,
+ looksLikeRefusal,
+ describe,
+ describeAll,
+ renderForPrompt,
+ PROMPTS,
+ MAX_DESCRIPTION_CHARS,
+ _clearCache,
+};
diff --git a/app/core/promptRouter.js b/app/core/promptRouter.js
index 3726731..7c62bfc 100644
--- a/app/core/promptRouter.js
+++ b/app/core/promptRouter.js
@@ -138,6 +138,43 @@ answer; "I have no tools" is not, and on its own it is not even true of what you
Answer the question that was actually asked, directly and concisely.`;
+/**
+ * Appended to any prompt when the user attached an image to this message.
+ *
+ * ## Why a prompt was needed at all, when the image is right there on the message
+ *
+ * Because everything else in the turn is about the project, and it drowns the picture.
+ *
+ * Measured on `minicpm-v4.6` in Ask mode, "describe the image" with a photograph of a
+ * dog attached. The image reached the model. The reply described HirayaCoder. That is
+ * not a vision failure — the same model, the same photograph and a bare describe prompt
+ * scores 24/24 in `tools/bench-vision.js`. It is an instruction-following failure, and
+ * the instructions it followed were ours: Ask mode's prompt opens with "everything below
+ * this line is what you know about the user's project… Answer from it", and the context
+ * under it was 2,500 characters of project description and file listing with "Task:
+ * describe the image" on the last line.
+ *
+ * A small model resolves that conflict by weight, and the project block outweighs one
+ * short task line. `contextBuilder` is what stops the block from being there at all on
+ * this kind of turn; this is what re-points the instruction.
+ *
+ * The same shape is already documented in `agentSession._buildContext` for the chat
+ * route — a model handed a project description and the message "Hello Hiraya" answers
+ * with the project description. It is the same bug with a different trigger.
+ */
+const IMAGE_SUFFIX = `
+
+The user has attached an image to this message, and it is the subject of what they
+asked. Answer about the image.
+
+If you were given the picture itself, look at it. If you were given a written
+description of it instead, that description is everything you have — work from it, and
+do not offer to look at the image more closely.
+
+Do not answer with a description of this project, its files, or what it does unless the
+user's message actually asks about those. A question sent with a picture attached is
+almost always about the picture.`;
+
/**
* Agent mode, for a message that turned out to be conversation.
*
@@ -276,6 +313,8 @@ function renderEarnedHints(hints) {
* six-item TODO run does not re-detect it per step.
* @property {string[]} [earnedHints] Sentences from `agent/earnedHints`, already selected.
* @property {'chat' | 'task'} [intent] From `core/intentRouter`. Only consulted in Agent mode.
+ * @property {boolean} [hasImages] The user attached at least one image to this
+ * message. Changes the instruction rather than the tools — see `IMAGE_SUFFIX`.
* @property {boolean} [readOnlyTurn] From `intentRouter.isReadOnlyRequest`. Drops the
* mutating tools for one message. Only consulted in Agent mode — Plan has already
* dropped them, and Ask never had any.
@@ -317,7 +356,7 @@ function route(request) {
tools: [],
ollamaTools: [],
allowedActions: new Set(),
- systemPrompt: withIdentity(ASK_SYSTEM),
+ systemPrompt: withIdentity(ASK_SYSTEM) + (request.hasImages ? IMAGE_SUFFIX : ''),
budgets: { ...budgets, maxSteps: 0 },
readOnly: true,
// Read-only because the user chose a mode, not because this message was a
@@ -341,7 +380,7 @@ function route(request) {
tools: [],
ollamaTools: [],
allowedActions: new Set(),
- systemPrompt: withIdentity(CHAT_SYSTEM),
+ systemPrompt: withIdentity(CHAT_SYSTEM) + (request.hasImages ? IMAGE_SUFFIX : ''),
budgets: { ...budgets, maxSteps: 0 },
readOnly: true,
readOnlyTurn: false,
@@ -374,6 +413,7 @@ function route(request) {
withEnvironment(systemPrompt, request.environment, { mutating: toolMode !== 'plan' })
);
+ if (request.hasImages) systemPrompt += IMAGE_SUFFIX;
if (mode === 'plan') systemPrompt += PLAN_SUFFIX;
if (readOnlyTurn) systemPrompt += READ_ONLY_SUFFIX;
diff --git a/app/extension.js b/app/extension.js
index 97f3f63..efe631b 100644
--- a/app/extension.js
+++ b/app/extension.js
@@ -82,6 +82,8 @@ let lastActiveSessionId = null;
* @property {{autoEdit: boolean, autoApproveScripts: boolean}} permissions
* @property {boolean} statusBarEnabled
* @property {{enabled: boolean, hintThreshold: number}} adaptation
+ * @property {{enabled: boolean, describeModel: string}} vision
+ * Image recognition. See `core/imageRecognition`.
* @property {boolean} stepSessions Experimental; see `agent/stepBrief`.
* @property {import('./utils/logger').LogLevel} logLevel
*/
@@ -116,6 +118,13 @@ function readSettings() {
enabled: cfg.get('adaptation.enabled', true),
hintThreshold: cfg.get('adaptation.hintThreshold', earnedHints.DEFAULT_THRESHOLD),
},
+ vision: {
+ enabled: cfg.get('vision.enabled', true),
+ // Empty means "pick one", which is what almost everybody wants. A name here is
+ // honoured only if it is installed and actually reports vision — see
+ // `imageRecognition.pickDescriber`, which logs rather than silently substituting.
+ describeModel: cfg.get('vision.describeModel', ''),
+ },
stepSessions: cfg.get('experimental.stepSessions', false),
logLevel: cfg.get('logLevel', 'info'),
};
diff --git a/app/features/chatTab.js b/app/features/chatTab.js
index 2738e67..d7cfbe7 100644
--- a/app/features/chatTab.js
+++ b/app/features/chatTab.js
@@ -26,6 +26,7 @@ const { budgetsFor } = require('../core/modelCapability');
const { TranscriptStore } = require('../core/transcriptStore');
const { AgentSession, ChangeSet } = require('../agent/agentSession');
const { readImage, modelSupportsImages } = require('./imageContext');
+const imageRecognition = require('../core/imageRecognition');
/** Bytes of entropy behind the CSP nonce. */
const NONCE_BYTES = 16;
@@ -419,13 +420,59 @@ class ChatTab {
});
}
+ /**
+ * Who, if anyone, can look at an attached image right now.
+ *
+ * ## Why this is no longer just "does the selected model have vision"
+ *
+ * Until 1.1.0 the answer was exactly that, and the attach button was disabled on
+ * every text-only model. That was correct while an image could only reach the model
+ * on the message itself: a model without vision does not error on a picture, it
+ * ignores it and answers confidently from the text alone, which is worse than a
+ * refusal.
+ *
+ * It stopped being correct once `core/imageRecognition` existed. The picture now
+ * reaches a text-only model as a description written by whichever vision model is
+ * installed, so the real question is whether *any* installed model can see — and on a
+ * machine that has one, refusing the attachment denies a capability that is present.
+ *
+ * The button is still disabled when nothing installed can see, for the original
+ * reason, which has not changed.
+ *
+ * @returns {{supported: boolean, describer: string | null, viaOtherModel: boolean}}
+ * @private
+ */
+ _visionState() {
+ const models = this.app.models || [];
+ const active = models.find((m) => m.name === this.app.activeModel) || null;
+ const activeCanSee = modelSupportsImages(active);
+ const settings = (this.app.settings && this.app.settings.vision) || {};
+
+ if (settings.enabled === false) {
+ // Turned off deliberately. A model that can see for itself still can: that path
+ // costs no extra call, and the setting is about the recognition pass rather than
+ // about images.
+ return { supported: activeCanSee, describer: activeCanSee ? this.app.activeModel : null, viaOtherModel: false };
+ }
+
+ const pick = imageRecognition.pickDescriber(models, {
+ activeModel: this.app.activeModel,
+ preferred: settings.describeModel || '',
+ });
+
+ if (!pick) return { supported: false, describer: null, viaOtherModel: false };
+ return { supported: true, describer: pick.name, viaOtherModel: !activeCanSee };
+ }
+
/** @private */
_postVision() {
- const active = (this.app.models || []).find((m) => m.name === this.app.activeModel) || null;
+ const state = this._visionState();
this._post({
type: 'vision',
- supported: modelSupportsImages(active),
+ supported: state.supported,
model: this.app.activeModel,
+ describer: state.describer,
+ viaOtherModel: state.viaOtherModel,
});
}
@@ -496,13 +543,14 @@ class ChatTab {
/** @private */
async _attachImage() {
- const active = (this.app.models || []).find((m) => m.name === this.app.activeModel) || null;
- if (!modelSupportsImages(active)) {
- // Checked again on this side: the button being disabled is a convenience, not
- // a guarantee, and a text-only model would silently ignore the image.
+ const vision = this._visionState();
+ if (!vision.supported) {
+ // Checked again on this side: the button being disabled is a convenience, not a
+ // guarantee. The message names the whole machine rather than the selected model,
+ // because switching models is no longer the fix — nothing installed can see.
vscode.window.showWarningMessage(
- `HirayaCoder: ${this.app.activeModel || 'The selected model'} cannot read images. ` +
- 'Switch to a vision model such as gemma4 or qwen3.5.'
+ 'HirayaCoder: none of your installed models can read images. ' +
+ 'Pull one that can, such as `ollama pull minicpm-v4.6` or `ollama pull qwen3.5:2b`.'
);
return;
}
@@ -530,7 +578,22 @@ class ChatTab {
dataUri: result.image.dataUri,
},
});
- logger.info(`Attached image ${result.image.name} (${Math.round(result.image.bytes / 1024)} KB).`);
+ logger.info(
+ `Attached image ${result.image.name} (${Math.round(result.image.bytes / 1024)} KB), ` +
+ `to be read by ${vision.describer}.`
+ );
+ }
+
+ // Said once, after the picker, rather than as a warning before it: the user has
+ // already decided to attach something, and the useful information is that this will
+ // cost an extra model load — not that they picked the "wrong" model.
+ if (vision.viaOtherModel && this.pendingImages.length > 0) {
+ this._post({
+ type: 'status',
+ text:
+ `${this.app.activeModel} cannot read images, so ${vision.describer} will describe ` +
+ 'them first. That is one extra model load before the turn starts.',
+ });
}
}
@@ -634,6 +697,10 @@ class ChatTab {
const images = this.pendingImages.slice();
this.pendingImages = [];
+ // Snapshotted with the images rather than read when the session is built: a model
+ // switch between the two would otherwise describe this turn's picture with a model
+ // that was not the one the user was told about.
+ const imageVision = this._visionState();
// Set between the guard above and the queue below, so a message sent while this
// tab is still waiting for the lane is refused rather than queued behind itself.
@@ -695,6 +762,16 @@ class ChatTab {
environment: this.app.environment,
stepSessions: this.stepSessions,
images: images.map((image) => image.base64),
+ // The same pictures with their names attached, so a description can say which
+ // image it is describing. See `AgentSession.imageFiles`.
+ imageFiles: images.map((image) => ({ name: image.name, base64: image.base64 })),
+ // Resolved here rather than inside the session, because this is the only side
+ // that holds the list of installed models.
+ vision: {
+ enabled: !(this.app.settings && this.app.settings.vision && this.app.settings.vision.enabled === false),
+ describeModel: imageVision.describer,
+ activeCanSee: !imageVision.viaOtherModel && imageVision.supported,
+ },
// How the session reaches the user when it is stuck or the request was
// ambiguous. Bound to this tab, so the question appears in the conversation it
// came from rather than in whichever tab happens to be focused.
@@ -721,6 +798,15 @@ class ChatTab {
todos: result.todos || null,
changes: result.changeSet instanceof ChangeSet ? result.changeSet.list() : [],
plan: result.plan || null,
+ // Which model answered, and how long it took. Shown under every reply so that
+ // switching models is a comparison rather than a guess.
+ //
+ // `result.model` rather than `this.app.activeModel`: the user is free to change
+ // the dropdown while a turn is running, and the footer has to name the model
+ // that actually produced the words above it.
+ model: result.model || this.app.activeModel,
+ ms: typeof result.ms === 'number' ? result.ms : null,
+ vision: result.vision || null,
});
} catch (err) {
const message = /** @type {Error} */ (err).message;
@@ -792,6 +878,20 @@ class ChatTab {
// find out why.
case 'interpretation':
return this._post({ type: 'status', text: String(event.note || '').slice(0, 160) });
+ // What the vision model actually saw. Shown in the conversation rather than only
+ // logged, because everything the answer says about the picture is downstream of
+ // this paragraph — and a user who can read it can tell "the model misread my
+ // screenshot" from "the model read it and answered badly". Those two need
+ // different fixes and look identical without this.
+ case 'images-described':
+ return this._post({
+ type: 'images-described',
+ model: event.model,
+ descriptions: (event.descriptions || []).map((entry) => ({
+ name: String(entry.name || 'image'),
+ description: String(entry.description || '').slice(0, 2000),
+ })),
+ });
default:
return undefined;
}
diff --git a/app/webview/components/messageBubble.js b/app/webview/components/messageBubble.js
index d518b1b..c1636b5 100644
--- a/app/webview/components/messageBubble.js
+++ b/app/webview/components/messageBubble.js
@@ -59,6 +59,125 @@ export function appendImages(body, images) {
body.appendChild(row);
}
+/**
+ * Seconds, rounded the way a person reads a stopwatch.
+ *
+ * Sub-second turns are the cached ones and would otherwise read "0s", which looks like
+ * a bug rather than like a fast answer.
+ *
+ * Exported for the unit suite. `appendRunMeta` needs a document and is covered by the
+ * integration tests; this part is arithmetic and is worth pinning cheaply.
+ *
+ * @param {number} ms
+ * @returns {string}
+ */
+export function seconds(ms) {
+ if (ms < 950) return `${(ms / 1000).toFixed(1)}s`;
+ if (ms < 60000) return `${Math.round(ms / 1000)}s`;
+ const mins = Math.floor(ms / 60000);
+ return `${mins}m ${Math.round((ms % 60000) / 1000)}s`;
+}
+
+/**
+ * Which model produced this reply, and how long it took.
+ *
+ * ## Why this is on every reply rather than in the status line
+ *
+ * The status line is per-tab and is overwritten by the next turn, so it can say what is
+ * happening but never what happened. On this hardware a model swap is the main lever
+ * anyone has — a task is one to five minutes and the only way to make it faster is to
+ * run something smaller — and choosing between them means comparing replies that are
+ * minutes and several messages apart. Attached to the reply, the comparison is just
+ * scrolling.
+ *
+ * A second model is named only when a *different* one read an attached image. That is
+ * not decoration: it is where the extra twenty seconds went, and without it the headline
+ * number looks like the coding model got slower.
+ *
+ * @param {HTMLElement} body
+ * @param {{model?: string, ms?: number | null, vision?: {model: string, ms: number} | null}} meta
+ */
+export function appendRunMeta(body, meta) {
+ if (!meta || (!meta.model && typeof meta.ms !== 'number')) return;
+
+ const line = document.createElement('div');
+ line.className = 'run-meta';
+
+ const name = document.createElement('span');
+ name.className = 'run-meta-model';
+ // Model names come from Ollama. Data, not markup.
+ name.textContent = meta.model || 'unknown model';
+ line.appendChild(name);
+
+ if (typeof meta.ms === 'number') {
+ const dot = document.createElement('span');
+ dot.className = 'run-meta-sep';
+ dot.textContent = '•';
+ line.appendChild(dot);
+
+ const took = document.createElement('span');
+ took.textContent = seconds(meta.ms);
+ line.appendChild(took);
+ }
+
+ if (meta.vision && meta.vision.model) {
+ const via = document.createElement('span');
+ via.className = 'run-meta-via';
+ via.textContent = `+ ${meta.vision.model} read the image, ${seconds(meta.vision.ms || 0)}`;
+ line.appendChild(via);
+ }
+
+ body.appendChild(line);
+}
+
+/**
+ * What the vision model read out of the attached images.
+ *
+ * ## Why this is on screen at all, rather than only in the log
+ *
+ * Everything the reply says about a picture is downstream of this paragraph. When the
+ * answer is wrong, there are two very different causes — the describer misread the
+ * image, or it read it correctly and the answering model went wrong afterwards — and
+ * they need opposite fixes. Without the description on screen the two are
+ * indistinguishable, and the user's only move is to try again and hope.
+ *
+ * Collapsed by default and styled like the agent trace, because it is the same kind of
+ * thing: evidence for the answer, not the answer.
+ *
+ * @param {HTMLElement} body
+ * @param {string} model
+ * @param {Array<{name: string, description: string}>} descriptions
+ */
+export function appendVisionNote(body, model, descriptions) {
+ if (!descriptions || descriptions.length === 0) return;
+
+ const box = document.createElement('details');
+ box.className = 'trace vision-note';
+
+ const summary = document.createElement('summary');
+ summary.textContent =
+ descriptions.length === 1
+ ? `What ${model} saw in ${descriptions[0].name}`
+ : `What ${model} saw in ${descriptions.length} images`;
+ box.appendChild(summary);
+
+ for (const entry of descriptions) {
+ if (descriptions.length > 1) {
+ const name = document.createElement('div');
+ name.className = 'vision-name';
+ name.textContent = entry.name;
+ box.appendChild(name);
+ }
+ const text = document.createElement('p');
+ text.className = 'vision-text';
+ // Model output. `textContent`, never markup — see the note at the top of this file.
+ text.textContent = entry.description;
+ box.appendChild(text);
+ }
+
+ body.appendChild(box);
+}
+
/**
* What each tool call is called, in the language of the thing it does.
*
diff --git a/app/webview/main.js b/app/webview/main.js
index 9bcaeae..aa8897d 100644
--- a/app/webview/main.js
+++ b/app/webview/main.js
@@ -7,7 +7,15 @@
* nonsense and no more.
*/
-import { createMessage, appendImages, TraceView, renderTodos, renderChanges } from './components/messageBubble.js';
+import {
+ createMessage,
+ appendImages,
+ appendVisionNote,
+ appendRunMeta,
+ TraceView,
+ renderTodos,
+ renderChanges,
+} from './components/messageBubble.js';
import { ThinkingIndicator } from './components/thinkingIndicator.js';
import { renderPlanChecklist } from './components/planChecklist.js';
import { renderClarification } from './components/clarificationCard.js';
@@ -330,6 +338,9 @@ const handlers = {
else state.body.appendChild(fresh);
}
if (msg.changes && msg.changes.length > 0) state.body.appendChild(renderChanges(msg.changes));
+ // Last, so it reads as a footer on everything above it rather than as part of the
+ // answer.
+ appendRunMeta(state.body, { model: msg.model, ms: msg.ms, vision: msg.vision });
scrollToEnd();
},
@@ -355,14 +366,24 @@ const handlers = {
scrollToEnd();
},
+ 'images-described'(msg) {
+ if (!state.body) return;
+ appendVisionNote(state.body, msg.model || 'the vision model', msg.descriptions || []);
+ scrollToEnd();
+ },
+
vision(msg) {
el.addImage.dataset.unsupported = msg.supported ? 'false' : 'true';
el.addImage.disabled = !msg.supported || state.running;
- el.addImage.title = msg.supported
- ? 'Attach an image'
- : `${msg.model || 'This model'} cannot read images. Pick a vision model such as gemma4 or qwen3.5.`;
+ // Three states, not two. "Supported by another model" is the new one, and saying so
+ // up front is what stops the extra model load from looking like a stall later.
+ el.addImage.title = !msg.supported
+ ? 'No installed model can read images. Pull one, such as minicpm-v4.6 or qwen3.5:2b.'
+ : msg.viaOtherModel
+ ? `Attach an image — ${msg.model} cannot read one, so ${msg.describer} will describe it first`
+ : 'Attach an image';
if (!msg.supported) {
- // Images already staged would be silently ignored by a text-only model.
+ // Images already staged have nothing left that could look at them.
const dropped = attachments.filter((a) => a.kind === 'image');
if (dropped.length > 0) {
attachments = attachments.filter((a) => a.kind !== 'image');
diff --git a/app/webview/style.css b/app/webview/style.css
index 045de17..e2c9192 100644
--- a/app/webview/style.css
+++ b/app/webview/style.css
@@ -314,6 +314,72 @@ select.control {
content: '▾ ';
}
+/*
+ * Which model replied, and how long it took. One line, under everything else.
+ *
+ * Small but deliberately not faint: this is a number people compare across replies that
+ * are minutes apart, so it has to survive a glance. `--fs-xs` with the theme's own
+ * description colour is the same weight the attachment chips carry, which is the
+ * quietest step in this panel that is still meant to be read.
+ */
+.run-meta {
+ display: flex;
+ flex-wrap: wrap;
+ align-items: baseline;
+ gap: var(--sp-1);
+ margin-top: var(--sp-3);
+ padding-top: var(--sp-2);
+ border-top: 1px solid var(--border);
+ font-size: var(--fs-xs);
+ color: var(--muted);
+ /* A long model name must not widen the panel. */
+ overflow-wrap: anywhere;
+}
+
+.run-meta-model {
+ font-family: var(--vscode-editor-font-family, Consolas, monospace);
+ color: var(--vscode-foreground);
+}
+
+.run-meta-sep {
+ opacity: 0.6;
+}
+
+/* The second model, when a different one read an attached image. Set back a step so the
+ headline pair still reads first. */
+.run-meta-via {
+ margin-left: var(--sp-2);
+ opacity: 0.85;
+}
+
+/*
+ * What the vision model read out of an attached image. Same shape as the trace above,
+ * because it is the same kind of thing — evidence for the answer, kept out of the way
+ * until someone wants it.
+ */
+.vision-note > summary::before {
+ content: '▸ ';
+}
+
+.vision-note[open] > summary::before {
+ content: '▾ ';
+}
+
+.vision-name {
+ margin-top: var(--sp-2);
+ font-size: var(--fs-xs);
+ color: var(--muted);
+}
+
+.vision-text {
+ margin: var(--sp-1) 0 0;
+ font-size: var(--fs-sm);
+ line-height: 1.5;
+ white-space: pre-wrap;
+ /* A describer that emits one long unbroken line must not widen the panel. */
+ overflow-wrap: anywhere;
+}
+
.step {
display: flex;
gap: var(--sp-2);
diff --git a/benchmarks/README.md b/benchmarks/README.md
index 115fb2d..de1f43a 100644
--- a/benchmarks/README.md
+++ b/benchmarks/README.md
@@ -60,7 +60,7 @@ node tools/bench-build.js ornith:9b --machine C --lang java,python --keep
| `--out ` | Results root, default `benchmarks/results` |
Requires Ollama running with the model pulled. See
-[the requirements section of the README](../README.md#requirements).
+[Getting started](../doc/GETTING-STARTED.md).
### Recording the CPU/GPU split
@@ -199,6 +199,102 @@ The compiled, human-readable tables are generated from these files afterwards an
[README.md](../README.md) and [doc/MODELS.md](../doc/MODELS.md). Those are the derived
artefacts; this directory is the source of truth.
+## The image-recognition benchmark — `vision__*.json`
+
+*New in 1.1.0.* `tools/bench-vision.js`. Where every other harness here asks whether a
+model can do the work, this asks whether it can **see** — because 1.1.0 lets an attached
+image reach a text-only model as a written description, and if that description is wrong
+nothing downstream can tell.
+
+That is the failure worth designing a harness around. A vision model that cannot see does
+not error and does not hedge. It writes a fluent, confident paragraph about something
+else, that paragraph is stored as "what is in this picture", and the coding model works
+from it. So this benchmark exists to catch a describer that is **wrong while sounding
+right**.
+
+### The fixtures
+
+Six photographs in `docs/test-images/`, each with a hand-written expectation of what is
+actually in it. Written by looking at them rather than by reading the filenames:
+`dog-1.jpg` is one corgi and `dog.jpg` is two retriever puppies, and grading both against
+"dog" would hide a model that cannot count.
+
+### Four axes, because they fail separately
+
+| Axis | What it asks | How it is scored |
+|---|---|---|
+| **subject** | Did it name the right thing? | Any accepted synonym counts. `puppy` passes for `dog` |
+| **detail** | Colour, setting, count | One word from each expectation group has to appear |
+| **text** | Did it read the words printed in the image? | Only scored on the two fixtures that have any |
+| **confusion** | Did it assert something the photo contradicts? | Can only be lost. A cat called a dog fails outright |
+
+A confusion sinks the fixture whatever else it scored, and that is the distinction the
+harness exists for: **vague is usable, wrong is worse than nothing**, because the user
+cannot tell.
+
+Matching is a word list, deliberately. Grading one local model's output with another
+local model would make the benchmark's own reliability the thing in question, and a word
+list cannot be talked into a false positive. It is word-boundary matched, which is not
+pedantry: the first draft used `includes` and scored a description of a cat on a *carpet*
+as having identified a car.
+
+### The timings need `--cold`
+
+Ollama caches the tokenized prompt, and for these requests the prompt is mostly the
+image. So the second sample of a picture returns in about a second where the first took
+fifteen, **and the cache survives between runs** — re-running this harness half an hour
+later reported one second for everything, for a model that genuinely takes eleven.
+
+`--cold` unloads the model between samples, which makes the `cold` column mean what it
+says. Without it, treat that column as a lower bound and nothing more. None of this
+touches the accuracy scores: a cached answer is the same answer.
+
+### Running it
+
+```bash
+node tools/bench-vision.js --machine [options]
+
+node tools/bench-vision.js minicpm-v4.6:latest --machine B --purpose both --repeat 2 --cold
+node tools/bench-vision.js qwen3.5:2b --machine A --images cat,plane
+```
+
+| Flag | Meaning |
+|---|---|
+| `--machine ` | **Required.** Which device this is; picks the results directory |
+| `--purpose
` | `answer` (default), `task`, or `both`. The two prompts in `core/imageRecognition` |
+| `--images ` | Fixture ids, comma separated. Default: all six |
+| `--repeat ` | Samples per image, default 1. These models are not stable across samples |
+| `--cold` | Unload the model between samples. Slower, and the only way the timings mean anything |
+| `--notes "..."` | Free text stored in the record |
+| `--out ` | Results root, default `benchmarks/results` |
+
+A model that does not report Ollama's `vision` capability is refused **before** the run
+rather than scored zero, because a zero there would look like a capability result and is
+actually a configuration mistake.
+
+### The 1.1.0 baseline
+
+Machine B, `--purpose both --repeat 2 --cold`, so 24 graded descriptions per model.
+
+| Model | Params | Subject | Detail | Text read | Confused | Cold |
+|---|---|---|---|---|---|---|
+| `minicpm-v4.6` | 752M | **24/24** | 42/48 | 4/8 | 0 | 11s |
+| `qwen3.5:0.8b` | 873M | 23/24 | **46/48** | **8/8** | 0 | 13s |
+
+Two findings worth carrying forward, both of which changed the shipped code:
+
+- **`minicpm-v4.6` missed the same text every time.** All four of its text failures are
+ `car.jpg`, whose only text is a small BMW badge on the grille. It read `cebu pacific`
+ off the aeroplane, in a large clear typeface, on all four attempts. So the axis is not
+ measuring "can it read" but "how small is the text", which is exactly the limitation
+ [doc/IMAGE-RECOGNITION.md](../doc/IMAGE-RECOGNITION.md) now warns about.
+- **`qwen3.5:0.8b` denied having vision once in twenty-four.** Sent the image, reporting
+ the capability, having described the same photograph correctly one sample earlier, it
+ replied *"I cannot see this image. I am an AI model designed to process text…"*. Left
+ alone that paragraph becomes the description. `core/imageRecognition` now recognises
+ the shape and reports a failed read instead, which is how a benchmark is supposed to
+ earn its keep.
+
## The machines
The letters match the ones used throughout [doc/MODELS.md](../doc/MODELS.md):
diff --git a/benchmarks/results/B/vision__minicpm-v4.6-latest__2026-08-20T17-24-28.json b/benchmarks/results/B/vision__minicpm-v4.6-latest__2026-08-20T17-24-28.json
new file mode 100644
index 0000000..e31cba1
--- /dev/null
+++ b/benchmarks/results/B/vision__minicpm-v4.6-latest__2026-08-20T17-24-28.json
@@ -0,0 +1,617 @@
+{
+ "schemaVersion": 1,
+ "benchmark": "vision",
+ "model": "minicpm-v4.6:latest",
+ "machine": "B",
+ "params": "752.16M",
+ "capabilities": [
+ "completion",
+ "vision"
+ ],
+ "purposes": [
+ "answer",
+ "task"
+ ],
+ "repeat": 2,
+ "coldStart": true,
+ "startedAt": "2026-08-20T17:24:28.867Z",
+ "durationMs": 264238,
+ "notes": "Machine B, CPU-only, model unloaded between samples for honest timings.",
+ "summary": {
+ "graded": 24,
+ "passed": 24,
+ "failed": 0,
+ "confused": 0,
+ "detailScore": 0.875,
+ "detailGot": 42,
+ "detailMax": 48,
+ "textImages": 8,
+ "textRead": 4,
+ "errored": 0,
+ "skipped": 0,
+ "meanMs": 10809,
+ "coldMeanMs": 11039,
+ "coldSamples": 12,
+ "totalMs": 259414
+ },
+ "results": [
+ {
+ "id": "cat",
+ "file": "cat.jpg",
+ "purpose": "answer",
+ "attempt": 1,
+ "durationMs": 10644,
+ "ok": true,
+ "description": "A small tabby kitten with blue eyes lies on a green surface. It is arranged looking directly at the camera. The setting is colorful and soft, suggesting a cozy indoor or outdoor area. There is no visible text or numbers.",
+ "expected": "A tabby kitten lying down, head on a green surface, facing the camera.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "kitten"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "tabby",
+ "lies"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "cat",
+ "file": "cat.jpg",
+ "purpose": "answer",
+ "attempt": 2,
+ "durationMs": 10937,
+ "ok": true,
+ "description": "A small tabby kitten with blue eyes is lying on a green surface. It is arranged as if resting. The setting is colorful and soft, with a blurred background. There is no visible text or numbers.",
+ "expected": "A tabby kitten lying down, head on a green surface, facing the camera.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "kitten"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "tabby",
+ "lying"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "dog",
+ "file": "dog.jpg",
+ "purpose": "answer",
+ "attempt": 1,
+ "durationMs": 13393,
+ "ok": true,
+ "description": "Two fluffy puppies sit in a grassy field. They appear happy, with tongues out. The setting is colorful, with orange flowers and green grass. There is no visible text or numbers. The scene is bright and cheerful.",
+ "expected": "Two golden retriever puppies sitting in grass strewn with orange petals.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "puppies"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "two",
+ "grass"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "dog",
+ "file": "dog.jpg",
+ "purpose": "answer",
+ "attempt": 2,
+ "durationMs": 13444,
+ "ok": true,
+ "description": "Two fluffy puppies sit in a grassy field. They appear happy, with tongues out. The setting is colorful, with orange and yellow flowers. There is no visible text or numbers. The scene is bright and natural.",
+ "expected": "Two golden retriever puppies sitting in grass strewn with orange petals.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "puppies"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "two",
+ "field"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "dog-1",
+ "file": "dog-1.jpg",
+ "purpose": "answer",
+ "attempt": 1,
+ "durationMs": 10633,
+ "ok": true,
+ "description": "A happy dog lies in grass. It is arranged as if posing for a photo. The setting is colorful, with green and yellow hues. There is no visible text or numbers. The scene is bright and cheerful.",
+ "expected": "A single corgi lying in sunlit grass, wearing a green collar.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "dog"
+ ],
+ "detail": 1,
+ "detailTotal": 2,
+ "detailMatched": [
+ "grass"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "dog-1",
+ "file": "dog-1.jpg",
+ "purpose": "answer",
+ "attempt": 2,
+ "durationMs": 10691,
+ "ok": true,
+ "description": "A happy dog lies in grass. It is arranged as if posing for a photo. The setting is colorful, with green and yellow tones. There is no visible text or numbers. The scene is bright and natural.",
+ "expected": "A single corgi lying in sunlit grass, wearing a green collar.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "dog"
+ ],
+ "detail": 1,
+ "detailTotal": 2,
+ "detailMatched": [
+ "grass"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "car",
+ "file": "car.jpg",
+ "purpose": "answer",
+ "attempt": 1,
+ "durationMs": 12905,
+ "ok": true,
+ "description": "A yellow car is moving on a road. The background shows trees and a clear sky. The setting is outdoors with natural colors. There is no visible text or numbers.",
+ "expected": "A yellow BMW M4 coupe on a road, panning shot, bare trees behind.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "car"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "yellow",
+ "road"
+ ],
+ "readText": false,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "car",
+ "file": "car.jpg",
+ "purpose": "answer",
+ "attempt": 2,
+ "durationMs": 12699,
+ "ok": true,
+ "description": "A yellow car is moving on a road. The background has trees and a clear sky. The setting is outdoors with natural colors. There is no visible text or numbers.",
+ "expected": "A yellow BMW M4 coupe on a road, panning shot, bare trees behind.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "car"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "yellow",
+ "road"
+ ],
+ "readText": false,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "plane",
+ "file": "plane.jpg",
+ "purpose": "answer",
+ "attempt": 1,
+ "durationMs": 7033,
+ "ok": true,
+ "description": "A cebu pacific airplane is shown in flight. It is colorful with yellow, blue, and teal designs. The setting is a clear sky. There is no visible text or numbers. The image is credited to Jetphotos.",
+ "expected": "A Cebu Pacific Airbus A320 on approach, gear down, against grey sky.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "airplane"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "yellow",
+ "sky"
+ ],
+ "readText": true,
+ "textMatched": [
+ "cebu"
+ ],
+ "confused": []
+ },
+ {
+ "id": "plane",
+ "file": "plane.jpg",
+ "purpose": "answer",
+ "attempt": 2,
+ "durationMs": 7084,
+ "ok": true,
+ "description": "A cebu pacific airplane is shown in flight. It is colorful with yellow, blue, and teal designs. The setting is a clear sky. There is no visible text or numbers. The image is credited to Jetphotos and Berian Spotters.",
+ "expected": "A Cebu Pacific Airbus A320 on approach, gear down, against grey sky.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "airplane"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "yellow",
+ "sky"
+ ],
+ "readText": true,
+ "textMatched": [
+ "cebu"
+ ],
+ "confused": []
+ },
+ {
+ "id": "tree",
+ "file": "tree.jpg",
+ "purpose": "answer",
+ "attempt": 1,
+ "durationMs": 10697,
+ "ok": true,
+ "description": "A large tree stands in a grassy field. It is surrounded by soft colors. The setting is bright and natural. There is no visible text or numbers. The scene is vibrant with green and purple hues.",
+ "expected": "One large green tree alone in a grassy field at sunset, blue sky above.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "tree"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "field",
+ "green"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "tree",
+ "file": "tree.jpg",
+ "purpose": "answer",
+ "attempt": 2,
+ "durationMs": 10874,
+ "ok": true,
+ "description": "A large tree stands in a green field. It is surrounded by grass and small purple flowers. The setting is colorful with blue sky and golden light. There is no visible text or numbers.",
+ "expected": "One large green tree alone in a grassy field at sunset, blue sky above.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "tree"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "field",
+ "sky"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "cat",
+ "file": "cat.jpg",
+ "purpose": "task",
+ "attempt": 1,
+ "durationMs": 10995,
+ "ok": true,
+ "description": "A close-up photo of a tabby kitten with blue eyes on green fabric. Text is unreadable. Layout is natural, with focus on the kitten's face. Colors are soft and natural. No code or error messages present.",
+ "expected": "A tabby kitten lying down, head on a green surface, facing the camera.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "kitten"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "tabby",
+ "green"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "cat",
+ "file": "cat.jpg",
+ "purpose": "task",
+ "attempt": 2,
+ "durationMs": 10865,
+ "ok": true,
+ "description": "A close-up photo of a tabby kitten with blue eyes on green fabric. Text is unreadable. Layout is natural, with focus on the kitten's face. Colors are soft, with clear contrast between fur and background.",
+ "expected": "A tabby kitten lying down, head on a green surface, facing the camera.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "kitten"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "tabby",
+ "green"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "dog",
+ "file": "dog.jpg",
+ "purpose": "task",
+ "attempt": 1,
+ "durationMs": 13751,
+ "ok": true,
+ "description": "A screenshot of two playful puppies in a grassy field with orange flowers. Text is unreadable. Layout is natural, with puppies centered, flowers scattered. Colors are soft, with green and orange tones. No code or labels present.",
+ "expected": "Two golden retriever puppies sitting in grass strewn with orange petals.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "puppies"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "two",
+ "field"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "dog",
+ "file": "dog.jpg",
+ "purpose": "task",
+ "attempt": 2,
+ "durationMs": 13812,
+ "ok": true,
+ "description": "A photo of two playful puppies in a grassy field with orange flowers. Text is unreadable. Layout is natural, with puppies and flowers. Colors are soft, with green grass and bright orange petals. Spacing is deliberate, emphasizing the subjects.",
+ "expected": "Two golden retriever puppies sitting in grass strewn with orange petals.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "puppies"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "two",
+ "grass"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "dog-1",
+ "file": "dog-1.jpg",
+ "purpose": "task",
+ "attempt": 1,
+ "durationMs": 10928,
+ "ok": true,
+ "description": "A screenshot of a cheerful corgi in grass. The image is natural lighting. Text is unreadable. Layout is focused on the dog. Colors are warm and soft. Spacing is deliberate. No code or error present.",
+ "expected": "A single corgi lying in sunlit grass, wearing a green collar.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "dog"
+ ],
+ "detail": 1,
+ "detailTotal": 2,
+ "detailMatched": [
+ "grass"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "dog-1",
+ "file": "dog-1.jpg",
+ "purpose": "task",
+ "attempt": 2,
+ "durationMs": 914,
+ "ok": true,
+ "description": "A screenshot of a cheerful corgi in grass. The image is natural lighting. Text is unreadable. Layout is focused on the dog. Colors are warm and soft. Spacing is deliberate. No code or labels visible.",
+ "expected": "A single corgi lying in sunlit grass, wearing a green collar.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "dog"
+ ],
+ "detail": 1,
+ "detailTotal": 2,
+ "detailMatched": [
+ "grass"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "car",
+ "file": "car.jpg",
+ "purpose": "task",
+ "attempt": 1,
+ "durationMs": 10406,
+ "ok": true,
+ "description": "Screenshot of a yellow car in motion. Visible text and numbers are unreadable. Layout includes car, road, trees. Colors are distinct, sizes vary for emphasis. Spacing is deliberate.",
+ "expected": "A yellow BMW M4 coupe on a road, panning shot, bare trees behind.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "car"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "yellow",
+ "road"
+ ],
+ "readText": false,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "car",
+ "file": "car.jpg",
+ "purpose": "task",
+ "attempt": 2,
+ "durationMs": 14314,
+ "ok": true,
+ "description": "A screenshot of a yellow sports car in motion. The image is dynamic, with blurred background trees. Text and numbers are unreadable. Layout includes car, road, and forest. Colours are vibrant, sizes varied for emphasis. Spacing is deliberate. No code or error messages present.",
+ "expected": "A yellow BMW M4 coupe on a road, panning shot, bare trees behind.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "car"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "yellow",
+ "road"
+ ],
+ "readText": false,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "plane",
+ "file": "plane.jpg",
+ "purpose": "task",
+ "attempt": 1,
+ "durationMs": 8668,
+ "ok": true,
+ "description": "A screenshot of a cebu pacific airplane. Text \"cebu pacific\" is visible. Numbers like \"RP-C407\" are present. Layout includes panels and buttons. Colors are deliberate, with yellow, blue, and white. Spacing is clear and structured.",
+ "expected": "A Cebu Pacific Airbus A320 on approach, gear down, against grey sky.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "airplane"
+ ],
+ "detail": 1,
+ "detailTotal": 2,
+ "detailMatched": [
+ "yellow"
+ ],
+ "readText": true,
+ "textMatched": [
+ "cebu"
+ ],
+ "confused": []
+ },
+ {
+ "id": "plane",
+ "file": "plane.jpg",
+ "purpose": "task",
+ "attempt": 2,
+ "durationMs": 8936,
+ "ok": true,
+ "description": "Screenshot of an aircraft. Diagram showing layout. Text \"cebu pacific\" visible. Number \"RP-C407\" on tail. Colors yellow, blue, white, with wave patterns. Button not present. Field not visible. Panel not shown. Spacing deliberate. No code or error.",
+ "expected": "A Cebu Pacific Airbus A320 on approach, gear down, against grey sky.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "aircraft"
+ ],
+ "detail": 1,
+ "detailTotal": 2,
+ "detailMatched": [
+ "yellow"
+ ],
+ "readText": true,
+ "textMatched": [
+ "cebu"
+ ],
+ "confused": []
+ },
+ {
+ "id": "tree",
+ "file": "tree.jpg",
+ "purpose": "task",
+ "attempt": 1,
+ "durationMs": 12416,
+ "ok": true,
+ "description": "A landscape screenshot of a tree in a field. Text is unreadable. Layout includes tree, grass, sky, and field. Colors are natural, with green, blue, and yellow tones. Spacing is deliberate, emphasizing natural elements.",
+ "expected": "One large green tree alone in a grassy field at sunset, blue sky above.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "tree"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "field",
+ "sky"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "tree",
+ "file": "tree.jpg",
+ "purpose": "task",
+ "attempt": 2,
+ "durationMs": 12375,
+ "ok": true,
+ "description": "A landscape screenshot of a tree in a field. Text is unreadable. Layout includes tree, grass, sky, and horizon. Colors are natural, with green, blue, and yellow tones. Spacing is deliberate, emphasizing depth and contrast.",
+ "expected": "One large green tree alone in a grassy field at sunset, blue sky above.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "tree"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "field",
+ "sky"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ }
+ ]
+}
diff --git a/benchmarks/results/B/vision__qwen3.5-0.8b__2026-08-20T17-28-53.json b/benchmarks/results/B/vision__qwen3.5-0.8b__2026-08-20T17-28-53.json
new file mode 100644
index 0000000..429dba2
--- /dev/null
+++ b/benchmarks/results/B/vision__qwen3.5-0.8b__2026-08-20T17-28-53.json
@@ -0,0 +1,628 @@
+{
+ "schemaVersion": 1,
+ "benchmark": "vision",
+ "model": "qwen3.5:0.8b",
+ "machine": "B",
+ "params": "873.44M",
+ "capabilities": [
+ "vision",
+ "completion",
+ "tools",
+ "thinking"
+ ],
+ "purposes": [
+ "answer",
+ "task"
+ ],
+ "repeat": 2,
+ "coldStart": true,
+ "startedAt": "2026-08-20T17:28:53.238Z",
+ "durationMs": 309927,
+ "notes": "Machine B, CPU-only, model unloaded between samples for honest timings.",
+ "summary": {
+ "graded": 24,
+ "passed": 23,
+ "failed": 1,
+ "confused": 0,
+ "detailScore": 0.958,
+ "detailGot": 46,
+ "detailMax": 48,
+ "textImages": 8,
+ "textRead": 8,
+ "errored": 0,
+ "skipped": 0,
+ "meanMs": 12837,
+ "coldMeanMs": 12853,
+ "coldSamples": 12,
+ "totalMs": 308091
+ },
+ "results": [
+ {
+ "id": "cat",
+ "file": "cat.jpg",
+ "purpose": "answer",
+ "attempt": 1,
+ "durationMs": 8017,
+ "ok": true,
+ "description": "The main subject is a small kitten with striking blue eyes and tabby markings on its fur. It has long white whiskers and pink nose, giving it a curious expression as it lies down on a soft green surface. The kitten’s ears are perked up, suggesting attentiveness or alertness. Its body stretches out to the right side of the frame, while its head rests prominently in the foreground.\n\nThe setting appears to be indoors, with a blurred background that suggests an indoor environment like a living room or bedroom. The colors are muted but vibrant: greens dominate the lower portion of the image, contrasting with the brownish-gray tones of the kitten’s fur. There is no text visible in the frame.",
+ "expected": "A tabby kitten lying down, head on a green surface, facing the camera.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "kitten"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "tabby",
+ "rest"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "cat",
+ "file": "cat.jpg",
+ "purpose": "answer",
+ "attempt": 2,
+ "durationMs": 7827,
+ "ok": true,
+ "description": "The main subject is a curious kitten with striking blue eyes and tabby markings on its fur. It lies down on a soft green surface, possibly a blanket or mat, with its head resting gently against the edge. Its ears are perked up, and it appears to be looking directly at the viewer with an attentive expression. The background is softly blurred, drawing attention to the kitten's face and whiskers.\n\nThe kitten is lying down on a green surface, likely a blanket or mat. It has blue eyes and tabby markings on its fur. Its ears are perked up, and it appears to be looking directly at the viewer with an attentive expression. The background is softly blurred, drawing attention to the kitten's face and whiskers.",
+ "expected": "A tabby kitten lying down, head on a green surface, facing the camera.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "kitten"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "tabby",
+ "lying"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "dog",
+ "file": "dog.jpg",
+ "purpose": "answer",
+ "attempt": 1,
+ "durationMs": 23385,
+ "ok": true,
+ "description": "The main subject consists of two golden retriever puppies sitting side by side on a grassy field scattered with fallen autumn leaves. The puppy on the left has its tongue hanging out in a happy expression, while the one on the right is panting with its mouth open wide. Both dogs appear joyful and energetic, embodying innocence and playfulness.\n\nThey are arranged closely together, facing forward toward the viewer, creating an intimate and friendly composition. The background is softly blurred, emphasizing the subjects and adding depth to the image. The colors are warm and natural, dominated by greens from the grass and leaves, with golden hues reflecting the puppies' fur tones. There are no visible text or numbers in the frame.",
+ "expected": "Two golden retriever puppies sitting in grass strewn with orange petals.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "dog"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "two",
+ "grass"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "dog",
+ "file": "dog.jpg",
+ "purpose": "answer",
+ "attempt": 2,
+ "durationMs": 23090,
+ "ok": true,
+ "description": "The image features two golden retriever puppies sitting side by side on a grassy field scattered with fallen autumn leaves. The puppy on the left has its tongue out in a happy expression, while the one on the right also panting happily. Both dogs look joyful and energetic, embodying innocence and playfulness. The background is softly blurred green, suggesting an open outdoor space like a park or meadow during fall season. Colors dominate with warm yellows, oranges, and soft greens from the grass and foliage. There are no visible text or numbers in the frame.",
+ "expected": "Two golden retriever puppies sitting in grass strewn with orange petals.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "dog"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "two",
+ "grass"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "dog-1",
+ "file": "dog-1.jpg",
+ "purpose": "answer",
+ "attempt": 1,
+ "durationMs": 7542,
+ "ok": true,
+ "description": "The main subject is a cheerful Corgi lying on the grass, its ears perked up and mouth open in a happy expression. It wears a green collar with a buckle visible. The setting appears to be an outdoor park or field during the day, bathed in warm sunlight that creates a soft glow around the dog. The background features blurred greenery, suggesting trees or bushes, enhancing the peaceful atmosphere. Colors dominate the scene: vibrant greens from the grass and foliage, warm yellows and oranges from the sunlight, and the white fur of the Corgi. There are no text, numbers, or labels visible in the image.",
+ "expected": "A single corgi lying in sunlit grass, wearing a green collar.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "dog"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "grass",
+ "collar"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "dog-1",
+ "file": "dog-1.jpg",
+ "purpose": "answer",
+ "attempt": 2,
+ "durationMs": 7267,
+ "ok": true,
+ "description": "The main subject is a cheerful Corgi dog lying on green grass with its tongue out in a happy expression. The setting appears to be outdoors during the day, bathed in warm sunlight that creates a soft glow around the scene. The background features blurred trees and foliage, suggesting a natural park or garden environment. The colors are vibrant greens from the grass, tan and white fur on the dog, and golden hues from the sunlight. There is no visible text or numbers within the image itself.",
+ "expected": "A single corgi lying in sunlit grass, wearing a green collar.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "dog"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "grass",
+ "white"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "car",
+ "file": "car.jpg",
+ "purpose": "answer",
+ "attempt": 1,
+ "durationMs": 24097,
+ "ok": true,
+ "description": "The main subject is a vibrant yellow BMW M4 coupe in motion on a paved road. It features sleek headlights, distinctive kidney grilles, and aerodynamic design elements like side skirts and a front splitter. The car's glossy paint reflects sunlight, emphasizing its sporty appeal.\n\nIt appears to be driving at speed, as indicated by the blurred background trees and road markings. This creates a sense of dynamism and performance.\n\nThe setting is an open road with autumnal trees in the distance, suggesting a rural or suburban environment. The colors are dominated by the car's bright yellow, contrasting with the muted greens and browns of the foliage. A clear blue sky adds to the serene yet dynamic atmosphere.\n\nThere is no visible text or numbers within the image itself.",
+ "expected": "A yellow BMW M4 coupe on a road, panning shot, bare trees behind.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "car"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "yellow",
+ "road"
+ ],
+ "readText": true,
+ "textMatched": [
+ "bmw"
+ ],
+ "confused": []
+ },
+ {
+ "id": "car",
+ "file": "car.jpg",
+ "purpose": "answer",
+ "attempt": 2,
+ "durationMs": 23611,
+ "ok": true,
+ "description": "The main subject is a vibrant yellow BMW M4 coupe in motion on a paved road. It features sleek headlights, distinctive kidney grilles, and sporty alloy wheels. The car appears to be driving at speed, as indicated by the blurred background trees and road surface. This setup suggests an action shot capturing the vehicle's dynamic movement.\n\nThe setting is outdoors with a backdrop of tall, leafless trees under a clear sky. The colors are dominated by the bright yellow of the car against the muted greens and browns of the forest. There are no visible text or numbers in the image.",
+ "expected": "A yellow BMW M4 coupe on a road, panning shot, bare trees behind.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "car"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "yellow",
+ "road"
+ ],
+ "readText": true,
+ "textMatched": [
+ "bmw"
+ ],
+ "confused": []
+ },
+ {
+ "id": "plane",
+ "file": "plane.jpg",
+ "purpose": "answer",
+ "attempt": 1,
+ "durationMs": 5359,
+ "ok": true,
+ "description": "The main subject is a Cebu Pacific airplane in flight against a clear sky backdrop. The aircraft features distinctive yellow and blue livery with the airline's name prominently displayed on its fuselage. Its wings are extended, suggesting it may be preparing for landing or has just taken off. The tail fin displays a vibrant gradient of yellow to blue, complemented by teal accents along the side. Text visible includes \"CP-4407\" near the rear of the plane and \"Image Copyright Javier Rodriguez - BERIAN SPOTTERS\" at the bottom right corner.",
+ "expected": "A Cebu Pacific Airbus A320 on approach, gear down, against grey sky.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "plane"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "yellow",
+ "sky"
+ ],
+ "readText": true,
+ "textMatched": [
+ "cebu"
+ ],
+ "confused": []
+ },
+ {
+ "id": "plane",
+ "file": "plane.jpg",
+ "purpose": "answer",
+ "attempt": 2,
+ "durationMs": 5558,
+ "ok": true,
+ "description": "The main subject is a Cebu Pacific airplane in flight against a clear sky backdrop. It appears to be flying at low altitude with landing gear deployed. The aircraft features distinctive branding with the airline name prominently displayed on its fuselage in blue lettering. The livery includes yellow and teal accents along the tail fin, wings, and engine area. Text visible on the side reads \"RP-C407\". The overall composition highlights the plane's design and branding while emphasizing its operational status within the aviation industry.",
+ "expected": "A Cebu Pacific Airbus A320 on approach, gear down, against grey sky.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "plane"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "yellow",
+ "sky"
+ ],
+ "readText": true,
+ "textMatched": [
+ "cebu"
+ ],
+ "confused": []
+ },
+ {
+ "id": "tree",
+ "file": "tree.jpg",
+ "purpose": "answer",
+ "attempt": 1,
+ "durationMs": 7959,
+ "ok": true,
+ "description": "The main subject is a majestic oak tree with sprawling branches and lush green foliage, standing prominently in the foreground of a serene landscape. It stands alone amidst vibrant fields of wildflowers, creating a striking contrast between its ancient form and the natural beauty surrounding it. The tree casts long shadows across the grassy field, indicating that the sun is low on the horizon, suggesting either sunrise or sunset.\n\nThe setting features expansive open fields bathed in warm sunlight, with distant hills faintly visible under a clear blue sky. The colors are vivid: deep blues of the sky, rich greens of the tree and grass, golden hues from the sunlight, and delicate purple blooms scattered throughout the meadow. There is no text or numbers present in the image.",
+ "expected": "One large green tree alone in a grassy field at sunset, blue sky above.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "tree"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "field",
+ "sky"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "tree",
+ "file": "tree.jpg",
+ "purpose": "answer",
+ "attempt": 2,
+ "durationMs": 8064,
+ "ok": true,
+ "description": "The main subject is a majestic oak tree with sprawling branches, standing alone in a vibrant field bathed in golden light. It appears to be thriving, its leaves glistening under the sun's rays. The tree dominates the foreground, while the expansive grassy landscape stretches out behind it, dotted with wildflowers and other small plants.\n\nThe setting is a serene countryside scene, characterized by lush greenery and open fields. The sky above is a brilliant blue, transitioning to a soft yellow near the horizon where the sun appears to be setting or rising. This warm light casts long shadows across the field, enhancing the tranquil atmosphere of the moment.\n\nThere are no visible text, numbers, or labels in the image. The colors are vivid: deep blues, lush greens, and golden yellows create a harmonious and peaceful composition.",
+ "expected": "One large green tree alone in a grassy field at sunset, blue sky above.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "tree"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "field",
+ "sky"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "cat",
+ "file": "cat.jpg",
+ "purpose": "task",
+ "attempt": 1,
+ "durationMs": 9362,
+ "ok": true,
+ "description": "The image captures a close-up portrait of a young tabby kitten with striking blue eyes and white markings on its muzzle. The kitten is lying down, resting its head on a soft, textured green surface that appears to be a rug or blanket. Its ears are perked up, and it gazes directly at the camera with an alert expression.\n\nThe background is softly blurred, drawing focus to the kitten's face. This shallow depth of field creates a sense of intimacy and immediacy. The lighting is natural and diffused, highlighting the texture of the fur and the vibrant blue of the eyes.\n\nIn terms of layout, the kitten dominates the frame from left to right. Its head occupies the upper portion, while its body extends diagonally into the lower right corner. The green surface serves as a base for the composition, anchoring the subject below. There are no buttons or panels visible; instead, the focus is entirely on the animal's features and expression.\n\nThe color palette consists primarily of earthy tones—browns, greys, and greens—with a pop of blue from the kitten’s eyes. The green surface provides a contrasting base that makes the kitten stand out. The overall composition feels calm and serene, capturing a quiet moment in nature.",
+ "expected": "A tabby kitten lying down, head on a green surface, facing the camera.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "kitten"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "tabby",
+ "lying"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "cat",
+ "file": "cat.jpg",
+ "purpose": "task",
+ "attempt": 2,
+ "durationMs": 7480,
+ "ok": true,
+ "description": "I cannot see this image. I am an AI model designed to process text and provide information, but I do not have the ability to view or interpret visual content like screenshots, photos, or UI elements. Therefore, I cannot identify what kind of image this is, extract any text or code from it, describe its layout, or analyze its colors and spacing.\n\nIf you can provide the text describing this image (e.g., a screenshot description), I would be happy to help you with that.",
+ "expected": "A tabby kitten lying down, head on a green surface, facing the camera.",
+ "passed": false,
+ "subject": false,
+ "subjectMatched": [],
+ "detail": 0,
+ "detailTotal": 2,
+ "detailMatched": [],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "dog",
+ "file": "dog.jpg",
+ "purpose": "task",
+ "attempt": 1,
+ "durationMs": 24525,
+ "ok": true,
+ "description": "The image is a photograph of two golden retriever puppies sitting on grass scattered with fallen autumn leaves. The puppy on the left has its tongue hanging out, while the one on the right is panting with its mouth open. Both dogs are looking towards the camera. The background is a soft-focus green field, and the foreground features vibrant orange and yellow flowers.\n\nThe layout places the two puppies in the center of the frame, flanking each other. They occupy the middle ground, while the grass and flowers fill the foreground. The background extends to the edges of the image, creating depth through blur. There are no buttons, fields, panels, or UI elements visible. No text, code, numbers, or labels appear in the image.\n\nThe dominant colors are shades of green (background), golden yellow (puppies and flowers), and orange (leaves). The puppies' fur is a light golden color, contrasting with the darker brown leaves. The overall composition suggests a peaceful outdoor scene, likely taken during fall.",
+ "expected": "Two golden retriever puppies sitting in grass strewn with orange petals.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "dog"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "two",
+ "grass"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "dog",
+ "file": "dog.jpg",
+ "purpose": "task",
+ "attempt": 2,
+ "durationMs": 24630,
+ "ok": true,
+ "description": "The image is a photograph of two golden retriever puppies sitting on the grass in a field with scattered orange and yellow flowers. The background is a soft, out-of-focus green. The dogs are positioned side by side, facing forward but looking slightly to the right. Both have their tongues hanging out, appearing happy or panting. The lighting is bright and natural, suggesting daytime.\n\nThe layout consists of two main subjects (the puppies) in the foreground, with a blurred background behind them. There are no buttons, fields, panels, or UI elements visible. No text, code, numbers, or labels appear anywhere in the image. The colors are primarily green, yellow, orange, and brown tones.\n\nThe image is a photo of two golden retriever puppies sitting on the grass in a field with scattered flowers.",
+ "expected": "Two golden retriever puppies sitting in grass strewn with orange petals.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "dog"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "two",
+ "grass"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "dog-1",
+ "file": "dog-1.jpg",
+ "purpose": "task",
+ "attempt": 1,
+ "durationMs": 7391,
+ "ok": true,
+ "description": "The image is a screenshot of a photo of a Corgi dog lying on grass in the foreground, with a blurred background of trees and foliage. The text \"Corgi\" appears above the dog's head. There are no code snippets or UI elements visible. The layout shows the dog centered in the frame, with its ears perked up and mouth slightly open, conveying a happy expression. The lighting is soft and warm, suggesting it was taken during the day.",
+ "expected": "A single corgi lying in sunlit grass, wearing a green collar.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "dog"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "grass",
+ "ears"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "dog-1",
+ "file": "dog-1.jpg",
+ "purpose": "task",
+ "attempt": 2,
+ "durationMs": 7428,
+ "ok": true,
+ "description": "The image shows a Corgi lying on green grass with its tongue out in a happy expression. The background is blurred, suggesting depth of field. The dog has a collar and large ears. There are no buttons, fields, panels, or UI elements visible. No text, code, numbers, or labels appear anywhere in the image.",
+ "expected": "A single corgi lying in sunlit grass, wearing a green collar.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "dog"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "grass",
+ "collar"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "car",
+ "file": "car.jpg",
+ "purpose": "task",
+ "attempt": 1,
+ "durationMs": 23860,
+ "ok": true,
+ "description": "The image is a photograph of a yellow BMW M4 coupe in motion on a paved road, captured with a panning shutter effect to emphasize speed. The car features a prominent front grille, sleek headlights, and aerodynamic bodywork. Trees and foliage are blurred in the background, indicating movement. The scene is well-lit, likely during daylight hours.\n\nThe layout centers the car prominently in the frame, with the road stretching into the distance. The composition uses motion blur to convey speed, while the car's details remain sharp. No text, code, or labels are present.",
+ "expected": "A yellow BMW M4 coupe on a road, panning shot, bare trees behind.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "car"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "yellow",
+ "road"
+ ],
+ "readText": true,
+ "textMatched": [
+ "bmw"
+ ],
+ "confused": []
+ },
+ {
+ "id": "car",
+ "file": "car.jpg",
+ "purpose": "task",
+ "attempt": 2,
+ "durationMs": 24606,
+ "ok": true,
+ "description": "The image is a photograph of a yellow BMW M4 Coupe in motion on a paved road, with blurred trees and sky in the background indicating speed. The car features a black front grille, sleek headlights, and silver multi-spoke wheels. It appears to be a screenshot from a video or photo album capturing the vehicle's dynamic performance.\n\nThe layout places the car centrally in the frame, angled slightly towards the left. The road occupies the lower portion of the image, while the background consists of out-of-focus trees and sky. There are no buttons, fields, panels, or UI elements visible. No text, code, numbers, or labels appear anywhere in the image.\n\nThe colors are predominantly yellow for the car, black for the grille and mirrors, silver for wheels, and muted tones for the background foliage and sky. The spacing is natural, with the road stretching horizontally across the bottom and the tree line forming a backdrop behind the vehicle. The overall composition emphasizes motion and speed through the use of blur in the background elements.",
+ "expected": "A yellow BMW M4 coupe on a road, panning shot, bare trees behind.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "car"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "yellow",
+ "road"
+ ],
+ "readText": true,
+ "textMatched": [
+ "bmw"
+ ],
+ "confused": []
+ },
+ {
+ "id": "plane",
+ "file": "plane.jpg",
+ "purpose": "task",
+ "attempt": 1,
+ "durationMs": 5188,
+ "ok": true,
+ "description": "The image is a screenshot of a Cebu Pacific airplane in flight against a gray sky. The text on the fuselage reads \"cebu pacific\" in blue letters. The aircraft has landing gear deployed, and its registration number appears to be RP-C4407. The layout groups the text on the fuselage with the plane's body and wings. The colors are yellow, white, and blue. The image is a photo of an airplane.",
+ "expected": "A Cebu Pacific Airbus A320 on approach, gear down, against grey sky.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "plane"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "yellow",
+ "sky"
+ ],
+ "readText": true,
+ "textMatched": [
+ "cebu"
+ ],
+ "confused": []
+ },
+ {
+ "id": "plane",
+ "file": "plane.jpg",
+ "purpose": "task",
+ "attempt": 2,
+ "durationMs": 5313,
+ "ok": true,
+ "description": "The image is a screenshot of a commercial airplane in flight against a gray sky. The text on the fuselage reads \"cebu-pacific\" in blue letters. The aircraft has yellow and blue livery with a wave design. The landing gear is deployed, indicating the plane is either taking off or landing. The photo captures the entire aircraft from front to back.",
+ "expected": "A Cebu Pacific Airbus A320 on approach, gear down, against grey sky.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "plane"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "yellow",
+ "sky"
+ ],
+ "readText": true,
+ "textMatched": [
+ "cebu"
+ ],
+ "confused": []
+ },
+ {
+ "id": "tree",
+ "file": "tree.jpg",
+ "purpose": "task",
+ "attempt": 1,
+ "durationMs": 7550,
+ "ok": true,
+ "description": "1. A photo of a large tree in a field under a blue sky.\n2. \"large tree\", \"field\", \"blue sky\", \"tree trunk\".\n3. The tree is the main subject, with branches spreading out to the left and right.\n4. The tree is positioned on the left side of the image.\n5. The grassy field extends from the bottom to the horizon line.\n6. The sky takes up the top half of the image.",
+ "expected": "One large green tree alone in a grassy field at sunset, blue sky above.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "tree"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "field",
+ "sky"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ },
+ {
+ "id": "tree",
+ "file": "tree.jpg",
+ "purpose": "task",
+ "attempt": 2,
+ "durationMs": 8982,
+ "ok": true,
+ "description": "1. A photograph of a solitary tree in a field under a clear blue sky.\n2. The tree has green leaves and a thick trunk.\n3. The image is a screenshot of a landscape scene.\n4. Colors are vibrant greens, blues, and yellows. Spacing is natural with no deliberate borders or buttons.",
+ "expected": "One large green tree alone in a grassy field at sunset, blue sky above.",
+ "passed": true,
+ "subject": true,
+ "subjectMatched": [
+ "tree"
+ ],
+ "detail": 2,
+ "detailTotal": 2,
+ "detailMatched": [
+ "field",
+ "sky"
+ ],
+ "readText": null,
+ "textMatched": [],
+ "confused": []
+ }
+ ]
+}
diff --git a/doc/CHOOSING-A-MODEL.md b/doc/CHOOSING-A-MODEL.md
new file mode 100644
index 0000000..605b2ae
--- /dev/null
+++ b/doc/CHOOSING-A-MODEL.md
@@ -0,0 +1,60 @@
+# Choosing a model
+
+
+Model names are confusing. Here is a plain-language ranking, based on
+[real measurements](https://github.com/jaymar921/HirayaCoder/blob/main/doc/MODELS.md)
+rather than on the descriptions.
+
+| Model | Download | Needs | Verdict |
+|---|---|---|---|
+| `gemma4:e2b` | 7.2 GB | 16 GB RAM | **Best starting point.** Fastest to a correct answer |
+| `qwen3.5:4b` | 3.4 GB | 8–16 GB RAM | Good, smaller download |
+| `llama3.2:1b` | 1.3 GB | 8 GB RAM | For low-spec machines. Simple single-file jobs only |
+| `gemma4:e4b` | 9.6 GB | 32 GB RAM or a Mac | The strongest, if you have room |
+| `qwen3.5:0.8b` | 1.0 GB | — | Last resort. Writes files correctly; does not finish an app |
+
+## What a very small model will and will not do
+
+Worth setting expectations, because the honest answer is more useful than the
+encouraging one. Measured on a 98-line brief for a complete React app:
+
+- **A 0.8B model now scaffolds the project, writes every file the request named, and
+ installs the dependencies.** In the previous release the same model spent its whole
+ session listing the directory and wrote nothing.
+- **It does not get the app working.** The build still fails, and no model at this size
+ finished the app in any of our runs.
+
+So a very small model is genuinely useful for *"write me this file"* and for the parts of
+a big request that are mechanical. Handing it a whole application and walking away is not
+something we can recommend yet, and the numbers behind that are in
+[the evaluation notes](https://github.com/jaymar921/HirayaCoder/blob/main/doc/SESSION-ANALYSIS-0.9.0.md).
+
+Switch models any time from the dropdown at the top of the chat — no reinstall needed.
+
+**One thing that surprises people:** a graphics card makes it *faster*, not *smarter*.
+A bigger model gives better answers; a better GPU gives the same answer sooner.
+
+---
+
+---
+
+## If you want to attach images
+
+Reading a picture needs a model with the **vision** capability, and it does not have to
+be the model you code with. See
+[IMAGE-RECOGNITION.md](IMAGE-RECOGNITION.md#which-model-does-the-looking).
+
+| Model | Download | Reads images | Notes |
+|---|---|---|---|
+| `minicpm-v4.6` | 1.6 GB | Yes | Built for this. The recommended second model |
+| `qwen3.5:2b` | 2.7 GB | Yes | Codes and reads images |
+| `qwen3.5:4b` | 3.4 GB | Yes | Same, larger |
+| `gemma4:e2b` | 7.2 GB | Yes | The all-round recommendation already reads images |
+| `llama3.2` | 2.0 GB | No | Pair it with `minicpm-v4.6` |
+
+---
+
+## Next
+
+- [The measurements behind the ranking](MODELS.md)
+- [What a small model cannot do](LIMITATIONS.md)
diff --git a/doc/DEVELOPING.md b/doc/DEVELOPING.md
new file mode 100644
index 0000000..5667e7f
--- /dev/null
+++ b/doc/DEVELOPING.md
@@ -0,0 +1,122 @@
+# Developing HirayaCoder
+
+Everything the README's beginner path leaves out: what is interesting about the design,
+how it is measured, and how to build and contribute to it.
+
+---
+
+
+Everything above is the beginner's path. The rest is the engineering, and it is
+documented properly elsewhere.
+
+**Features and settings** — [FEATURES.md](https://github.com/jaymar921/HirayaCoder/blob/main/doc/FEATURES.md)
+· **How it is built** — [ARCHITECTURE.md](https://github.com/jaymar921/HirayaCoder/blob/main/doc/ARCHITECTURE.md)
+· **Measurements** — [MODELS.md](https://github.com/jaymar921/HirayaCoder/blob/main/doc/MODELS.md)
+· **Security model** — [SECURITY.md](https://github.com/jaymar921/HirayaCoder/blob/main/doc/SECURITY.md)
+
+## What is interesting about it technically
+
+- **Agentic on every model, down to 1B.** It plans, reads, edits, deletes, and runs
+ scripts across multiple files on its own. Two loop strategies — native tool-calling for
+ capable models, a constrained one-action-per-turn JSON loop for small ones — behind one
+ driver, so the mechanism changes with the model but the reach never does.
+- **Three layers of local memory.** A plain-text session log, the conversation itself,
+ and typed facts about the project that persist across sessions, so the second session
+ does not rediscover what the first one paid for.
+- **"Done" has to be true.** A run that reports success having written nothing, or having
+ left `// Implement this here` inside a function it just wrote, gets sent back once with
+ the specific problem named. Completion is judged from what changed on disk, never from
+ what the model says about itself.
+- **It learns from what actually happened.** Outcomes are recorded locally — counts and
+ guard codes, never your code — and a model that trips the same guard three times gets
+ the matching correction added to its prompt. It adapts what the model is *told*, never
+ what it is *allowed to do*.
+- **Every guard names a real failure.** The write guards exist because four different
+ models produced six damaged files in one seventeen-run sweep: deleted exports, a
+ CommonJS module silently rewritten as ESM, an implementation replaced by an empty
+ object. Every one of them parsed cleanly.
+
+## Benchmarks
+
+Measured on three named machines, with the delete declined at the prompt on purpose — a
+model that claims it deleted the file has failed the task whatever else it got right.
+There are four harnesses: editing an existing project, building one from an empty folder,
+wiring an existing project together, and — new in 0.9.0 — building a whole application
+from one brief and then **driving the finished thing**, either by clicking every control
+in a headless browser or by calling its service layer directly.
+
+That last harness runs four briefs, so a model's trouble with the work can be told apart
+from its trouble with the language it was asked to work in:
+
+| Brief | Stack | Graded by |
+|---|---|---|
+| TODO app | React + Vite + Tailwind | 12 features, clicked in a browser |
+| Contact manager | React + Vite + Vitest | 12 features, clicked in a browser |
+| Point of sale | Java + Swing + Maven | 8 features, through the service layer |
+| Point of sale | Python + Tkinter, stdlib only | 8 features, through the service layer |
+
+It exists because of a result worth stating plainly: a model passed the scaffold,
+structure, install and build checks, and shipped an app whose only button incremented
+Vite's demo counter. Four green gates and nothing that worked. The full
+tables, including what each model broke and how, are in
+[MODELS.md](https://github.com/jaymar921/HirayaCoder/blob/main/doc/MODELS.md) and
+[benchmarks/](https://github.com/jaymar921/HirayaCoder/blob/main/benchmarks/README.md).
+
+The finding worth repeating here: **the mocked test suite passes clean while a real model
+destroys a real file.** Nearly every serious bug in this project was found by running an
+actual model, never by the unit tests.
+
+## Building from source
+
+Needs Node.js 18 or newer.
+
+```bash
+npm install
+npm run test:all # lint + unit + integration, against a real VS Code
+npm run package # builds builds/v/hirayacoder-.vsix
+```
+
+## Contributing
+
+Contributions are welcome, with **one hard rule: pull requests only — never push
+directly to `main`.** CI runs the suite on Ubuntu, macOS, and Windows, and that matrix is
+the only evidence this project has that anything works on the two platforms the
+maintainer does not own.
+
+Read [CONTRIBUTING.md](https://github.com/jaymar921/HirayaCoder/blob/main/CONTRIBUTING.md)
+first. The short version:
+
+- Branch and commit as `feat/…`, `fix/…`, `docs/…`.
+- `npm run test:all` must pass.
+- **If you touched the agent loop, prompts, translator, or tools, run a real model**
+ (`node tools/bench-agent.js gemma4:e2b agent auto full`) and put the outcome in the PR.
+- Don't weaken a guard or a permission prompt to make something pass.
+- Comments explain *why*, not *what*.
+
+Security issues: please contact [jaymar921](https://github.com/jaymar921) directly rather
+than opening a public issue.
+
+## Repository layout
+
+```
+HirayaCoder/
+├── app/ # Extension source — agent loops, tools, security layer, webview
+├── test/ # Unit + integration tests
+├── doc/ # Architecture, features, models, tutorial, security, publishing
+├── setup/ # AI build prompt + versioned model/translator system prompts
+├── security/ # Threat model, SAST reports
+├── scripts/ # Packaging
+├── tools/ # Live-model benchmark harnesses
+└── builds/ # Packaged .vsix output, per version (gitignored)
+```
+
+---
+
+---
+
+## Next
+
+- [How it is built](ARCHITECTURE.md)
+- [Every feature and setting](FEATURES.md)
+- [The security model and threat model](SECURITY.md)
+- [Publishing a release](PUBLISHING.md)
diff --git a/doc/FEATURES.md b/doc/FEATURES.md
index 2b743f1..ec2fca6 100644
--- a/doc/FEATURES.md
+++ b/doc/FEATURES.md
@@ -99,9 +99,19 @@ models are GPU-resident this is worth re-trying.
- **`+` attaches reference files.** They are scanned for secrets and redacted *at
ingestion*, before truncation, so a credential cannot survive by sitting past the cut
and reappearing when the budget changes.
-- **Images** for vision-capable models — magic-number checked, 4 MB cap, first message
- only. The attach button is disabled for models without the capability, since such a
- model does not error on an image, it ignores it and answers from the text.
+- **Images**, on any model — magic-number checked, 4 MB cap. The raw picture rides on the
+ first message when the selected model has the `vision` capability, and never when it
+ does not: such a model would not error, it would ignore the image and answer from the
+ text alone.
+- **Image recognition** (`core/imageRecognition`, 1.1.0) is what makes the above work on
+ a text-only model. A vision model writes down what is in the picture and *that* goes
+ into the context, so a screenshot is usable on `llama3.2`. It is produced even for a
+ model that can see, because an agent loop outlives the picture: images ride on turn one
+ only, and the words are small enough to carry on all eight. The describer is the
+ selected model when it can see (no extra load) and otherwise the smallest installed
+ vision model. The attach button is gated on the *machine* having a vision model, not on
+ the selected one being it. Every attachment comes with a panel showing exactly what was
+ read. Full detail: [IMAGE-RECOGNITION.md](IMAGE-RECOGNITION.md).
- **Session memory** persists across turns as plain text you can read and clear
(**Show Session Memory**, **Clear Session Memory**). Notes are composed by the
extension from what actually happened, not written by the model, and a failed write or
@@ -388,6 +398,8 @@ where bare JSON mode managed **0 out of 6**.
| `hirayacoder.scripts.allowedBinaries` | `[]` | Extends the built-in allow-list. |
| `hirayacoder.scripts.timeoutMs` | `120000` | |
| `hirayacoder.security.protectedPaths` | `[".git", ".hirayacoder"]` | |
+| `hirayacoder.vision.enabled` | `true` | Read attached images into a written description. Off still sends images to a model that can see them. |
+| `hirayacoder.vision.describeModel` | *(automatic)* | Which model reads images. Honoured only if installed **and** reporting `vision`. |
| `hirayacoder.experimental.stepSessions` | `false` | Run each TODO item as a briefed, verified step. See above. |
| `hirayacoder.inlineCompletion.enabled` | `false` | |
| `hirayacoder.statusBar.enabled` | `true` | Connection, model, tier. |
diff --git a/doc/GETTING-STARTED.md b/doc/GETTING-STARTED.md
new file mode 100644
index 0000000..9f56d3c
--- /dev/null
+++ b/doc/GETTING-STARTED.md
@@ -0,0 +1,134 @@
+# Getting started with HirayaCoder
+
+The complete first-run walkthrough: what the extension is, whether your computer can
+run it, and the four steps to a working install. The
+[README](../README.md#quick-start) has the short version of the same four steps.
+
+---
+
+## New here? Start with this
+
+**You do not need to know how to code to try it.** You do need about twenty minutes and
+a computer with a bit of room to spare. Here is the honest version of what you are
+signing up for.
+
+### What it actually does
+
+You open a folder on your computer, type something like *"make me a webpage with a
+to-do list"*, and HirayaCoder creates the files, writes the code, and shows you what it
+changed before saving anything. You can then ask it to change things: *"make the buttons
+blue"*, *"add a delete button"*.
+
+### What makes it different from ChatGPT or Copilot
+
+| | HirayaCoder | ChatGPT / Copilot |
+|---|---|---|
+| Cost | Free, forever | Usually a monthly fee |
+| Internet | Not needed after setup | Required |
+| Your code | Never leaves your computer | Sent to a company's servers |
+| Quality | Good, not great — see below | Better |
+| Speed | Seconds to minutes, depends on your PC | Fast |
+
+**The trade is real and you should know it before you start.** HirayaCoder runs a small
+AI model on your own hardware, and small models are not as clever as the big paid ones.
+It handles ordinary tasks well. It struggles with big, vague requests. If you ask for
+"a full social media app" you will be disappointed; if you ask for one page, one feature,
+or one fix at a time, it does a decent job.
+
+### Will it run on my computer?
+
+The main question is **how much RAM (memory) you have**. Here's a quick guide — you do
+not need a fancy graphics card.
+
+| Your computer | Will it work? | What to expect |
+|---|---|---|
+| 8 GB RAM | Yes, just barely | Slow, and only simple single-file tasks |
+| 16 GB RAM, no graphics card | **Yes — this is what it was built for** | A task takes 1–5 minutes. Very usable |
+| 16 GB+ with a gaming graphics card | Yes, comfortably | A task takes 20–60 seconds |
+| Mac with Apple Silicon (M1–M4) | Yes, very well | A task takes 10–30 seconds |
+
+To check on Windows: press `Ctrl+Shift+Esc`, click **Performance**, then **Memory**.
+On a Mac: Apple menu → **About This Mac**.
+
+---
+
+## Getting started
+
+Four steps. Copy and paste the commands exactly.
+
+### Step 1 — Install VS Code
+
+If you do not already have it, download it free from
+[code.visualstudio.com](https://code.visualstudio.com). This is the program you will
+actually be working in. You need **version 1.85 or newer** — any download from this year
+is fine.
+
+### Step 2 — Install Ollama
+
+[Ollama](https://ollama.com) is the free program that runs the AI on your computer.
+Download it, install it, and leave it running in the background. It has no window — it
+just sits in your system tray or menu bar, and that is normal.
+
+### Step 3 — Download an AI model
+
+Open a terminal and paste one line. (On Windows press the Start button, type
+`PowerShell`, and hit Enter. On a Mac press `Cmd+Space`, type `Terminal`, and hit Enter.)
+
+**Pick the line that matches your computer:**
+
+```bash
+# 16 GB RAM or more — the best all-round choice, start here
+ollama pull gemma4:e2b
+
+# 8 GB RAM, or if the one above is too slow — smaller and faster, but more limited
+ollama pull llama3.2:1b
+```
+
+This downloads a few gigabytes, so it takes a while on a slow connection. You only ever
+do it once.
+
+### Step 4 — Install HirayaCoder
+
+Download the `.vsix` file from the
+[Releases page](https://github.com/jaymar921/HirayaCoder/releases), then run:
+
+```bash
+code --install-extension hirayacoder-.vsix
+```
+
+Replace `` with the number in the filename you downloaded.
+
+### You're ready
+
+1. Open VS Code.
+2. Go to **File → Open Folder** and pick a folder — an empty new one is perfect for a
+ first try. **This step is required**: HirayaCoder refuses to do anything without a
+ folder open, so that it can never touch files outside it.
+3. Press `Ctrl+Shift+H` (`Cmd+Shift+H` on a Mac).
+4. Type something and press Enter.
+
+Good first things to type:
+
+- `make a webpage that says hello with a big blue button`
+- `create a simple to-do list app in one HTML file`
+- `explain what this project does` *(in a folder that already has code)*
+
+**If anything above is unclear once you are in there, press *Guide* in the chat header.**
+It opens the same four setup steps and — more usefully — what to expect: how long a task
+takes, why a refusal is usually the checks working, and what a small model is and is not
+good at.
+
+There is a longer, friendlier walkthrough in
+[TUTORIAL.md](https://github.com/jaymar921/HirayaCoder/blob/main/doc/TUTORIAL.md).
+
+---
+
+---
+
+## Next
+
+- [Using it day to day](USING-IT.md) — the three modes, watching a run, and the habits that make small models work
+- [What it cannot do](LIMITATIONS.md) — read this before you decide whether it fits your work
+- [When something goes wrong](TROUBLESHOOTING.md)
+- [Choosing a model](CHOOSING-A-MODEL.md)
+- [A longer, friendlier walkthrough](TUTORIAL.md)
diff --git a/doc/IMAGE-RECOGNITION.md b/doc/IMAGE-RECOGNITION.md
new file mode 100644
index 0000000..d1cba06
--- /dev/null
+++ b/doc/IMAGE-RECOGNITION.md
@@ -0,0 +1,200 @@
+# Reading images
+
+*New in 1.1.0.*
+
+You can attach a picture to a message. HirayaCoder looks at it, writes down what is in
+it, and then uses that as part of the conversation. It works for photos, screenshots,
+error messages, and rough sketches of a screen you want built.
+
+This page explains how it works, what it is good at, and where it falls over.
+
+---
+
+## The short version
+
+1. Click the image button next to the message box.
+2. Pick a PNG, JPEG, WEBP, or GIF file.
+3. Type your message and send it.
+
+In **Ask** mode you get an answer about the picture. In **Agent** mode the picture
+becomes part of the job, so "build this screen" works with a mockup attached.
+
+---
+
+## What is actually happening
+
+This is worth understanding, because it explains most of the behaviour you will notice.
+
+An AI model is a program that predicts text. Most of them only handle text, in and out.
+A few of them, called **vision models**, can also take an image as input. The ones you
+have installed are listed by `ollama list`, and whether a given one can see is something
+Ollama reports about it.
+
+So there are two situations.
+
+**Your model can see.** The picture goes to it directly, along with your message. This
+is the simple case and costs nothing extra.
+
+**Your model cannot see.** This used to mean the image button was greyed out. Since
+1.1.0 it does not. Instead HirayaCoder sends the picture to a different model, one that
+*can* see, and asks it a single question: what is in this image? That answer comes back
+as a paragraph of ordinary text, and the paragraph is what your coding model receives.
+
+The second case is the interesting one. It means you can run `llama3.2` for the coding,
+which has no vision at all, and still hand it a screenshot. You do not have to switch
+models, and you do not have to give up the model you like.
+
+### Why a written description, even when the model can see
+
+There is a second reason this exists, and it applies even to a model that has vision.
+
+In **Agent** mode the model works in a loop. It reads a file, then decides what to do
+next, then writes a file, then decides again. That can be eight or ten rounds. The
+picture is only attached to the first one, because attaching it to all of them would
+mean uploading several megabytes over and over, and on a normal laptop that is slower
+than the actual thinking.
+
+So by round four, the model is working on your screenshot without being able to see it
+any more. The written description is small enough to carry on every single round, so it
+does not disappear. That is why Agent mode always produces one, even on a vision model.
+
+---
+
+## Which model does the looking
+
+By default HirayaCoder picks for you:
+
+1. If the model you selected can see, it does the looking itself. Nothing else loads.
+2. Otherwise, the **smallest** installed model that can see does it.
+
+Smallest, not best, and there is a good reason. Ollama keeps one model in memory at a
+time. Using a second model means unloading the first one, loading the second, then
+loading the first one back. On a 16 GB laptop with no graphics card that is thirty to
+sixty seconds of nothing visibly happening. Describing a picture is a simple job, so the
+smallest model that can do it is the one that gets you back to work soonest.
+
+If you want to choose yourself, set `hirayacoder.vision.describeModel` to a model name.
+It is honoured only if that model is installed and actually reports vision. If it does
+not, HirayaCoder picks automatically instead and writes the reason to the log, rather
+than silently turning images off on you.
+
+You can turn the whole thing off with `hirayacoder.vision.enabled`. A model that can see
+for itself still receives images; only the extra description step stops.
+
+### Getting a model that can see
+
+If nothing you have installed can read images, the button tells you so. One command
+fixes it:
+
+```bash
+ollama pull minicpm-v4.6
+```
+
+It is 1.6 GB, which is small, and it is built for exactly this. It sits alongside
+whatever you already use for coding.
+
+---
+
+## Seeing what it read
+
+Under your message there is a collapsed panel labelled **What *model* saw in *file***.
+Open it and you get the exact text the vision model produced.
+
+Please use it. It is the difference between two problems that look identical:
+
+- The vision model misread your picture, and everything after that was doomed.
+- The vision model read it correctly and the coding model went wrong afterwards.
+
+Those need opposite fixes, and without the panel you cannot tell them apart. If the
+description is wrong, the fastest repair is usually to say so in your next message:
+"that is a delete button, not a save button".
+
+---
+
+## What it is good at
+
+Measured against six photographs, on the two smallest vision models that exist. The
+numbers are in [MODELS.md](MODELS.md#image-recognition-110) and the raw runs are in
+[benchmarks/](../benchmarks/README.md).
+
+- **Naming the main thing.** Cat, dog, car, tree, aeroplane. This is reliable, including
+ on a 752M model, which is very small.
+- **Colour, setting, and count.** "Two puppies in grass", "a yellow car on a road".
+ Mostly right.
+- **Reading large text.** Signs, headings, big labels. Works more often than not.
+
+Applied to actual work, that translates to:
+
+- A screenshot of an error, so you do not have to retype it.
+- A mockup or a sketch of a screen, as the basis for building it.
+- A photo of a whiteboard, for the shape of a data model.
+- A screenshot of a UI you want changed, so you can point rather than describe.
+
+---
+
+## What it is not good at
+
+Be honest with yourself about this before you rely on it.
+
+- **Small text.** A 752M model reading a stack trace at normal screenshot resolution
+ will get some of it wrong, and it will not tell you which parts. Crop and zoom first,
+ or paste the text.
+- **Exact numbers.** Line numbers, hex colours, version strings, anything where being
+ one character off matters. Check them.
+- **Precise layout.** It knows a button is near the top. It does not know it is 24
+ pixels from the edge.
+- **Anything it has not seen.** It describes what is in front of it. It does not know
+ your design system or what your icons mean.
+
+The failure that costs you most is the quiet one. A model that misreads a picture does
+not say "I am unsure". It writes a confident, well formed paragraph about the wrong
+thing. This is why the description is shown to you rather than hidden.
+
+---
+
+## Limits and rules
+
+- **Formats:** PNG, JPEG, WEBP, GIF.
+- **Size:** 4 MB per image. The file is checked before it is read, so a huge one is
+ rejected rather than loaded into memory. Images get about a third larger when they are
+ encoded for sending, and a big one can take minutes on a CPU.
+- **The file type is verified.** A `.png` that is really something else is spotted by
+ looking at the actual bytes, not by trusting the name.
+- **Images belong to one message.** They are sent with the message you attached them to
+ and are not carried into the next one. Attached files, which are different, do stay.
+- **It is still completely offline.** The picture goes to Ollama on `127.0.0.1` and
+ nowhere else, exactly like every other thing this extension sends. Nothing about
+ images changes the privacy story.
+
+---
+
+## Speed
+
+Reading a picture is a full model call, so it takes about as long as an ordinary reply.
+On a CPU-only laptop that is roughly five to twenty seconds for a small vision model.
+The status line tells you which model is reading which file while it happens.
+
+If your coding model cannot see, add the time to load the second model on top. That is
+the one part of this that feels slow, and it is why the automatic choice prefers a model
+that is already loaded.
+
+Attaching the same picture twice in a row costs nothing the second time. The description
+is kept for the session.
+
+---
+
+## Settings
+
+| Setting | Default | What it does |
+|---|---|---|
+| `hirayacoder.vision.enabled` | `true` | Turn the description step off entirely |
+| `hirayacoder.vision.describeModel` | `""` | Name a model to do the looking. Empty means pick automatically |
+
+---
+
+## Next
+
+- [Using it day to day](USING-IT.md)
+- [Choosing a model](CHOOSING-A-MODEL.md)
+- [What HirayaCoder cannot do](LIMITATIONS.md)
+- [The measurements](MODELS.md#image-recognition-110)
diff --git a/doc/LIMITATIONS.md b/doc/LIMITATIONS.md
new file mode 100644
index 0000000..f2fff8b
--- /dev/null
+++ b/doc/LIMITATIONS.md
@@ -0,0 +1,199 @@
+# What HirayaCoder cannot do
+
+Every tool has a shape. This page is the honest description of this one's, so you can
+decide whether it fits your work before you spend an evening finding out.
+
+Two kinds of limit are listed here and it is worth keeping them apart:
+
+- **Limits by design.** Things HirayaCoder refuses to do because doing them would make
+ it a different and worse tool. These are not going to change.
+- **Limits of the technology.** Things a small model running on your own laptop is not
+ currently good at. Some of these will improve. Most of them will improve slowly.
+
+---
+
+## Limits by design
+
+These are choices. They are the reason the tool is worth using, and they cost real
+convenience.
+
+### It never talks to the internet
+
+The only address it will connect to is `127.0.0.1`, which is your own machine. A
+non-loopback address is rejected in code before any connection opens. This means:
+
+- No cloud models. No GPT, no Claude, no Gemini, whatever your subscription is.
+- No looking up documentation, no fetching a package from the web, no searching.
+- No sharing a session with a teammate.
+
+If your workflow depends on a frontier model, this is not the tool. That is a real
+answer, not a soft one.
+
+### It cannot leave the folder you opened
+
+Every read, write, and delete is confined to your open workspace folder. It cannot touch
+your home directory, a sibling project, or anything outside. There is no setting that
+turns this off.
+
+It also refuses to run in an untrusted workspace, and it does nothing at all until you
+have a folder open.
+
+### It runs only a fixed list of commands
+
+`node`, `npm`, `git`, `pytest`, `mvn`, and about twenty more. Everything else is
+refused. Notably:
+
+- **No shell.** Commands run directly, so `&&`, `|`, `>` and `$(...)` are refused
+ rather than interpreted. One command at a time.
+- **No `rm`, `ls`, `mkdir`, `curl`, `wget`.** File work goes through the safe file
+ tools instead.
+- **Anything that reaches the network or publishes code** (`git push`, `npm publish`)
+ asks for confirmation regardless of your settings.
+
+You can add binaries to the list in settings. The model cannot add to it.
+
+### It asks before it writes
+
+By default every file write shows you a diff and waits. You can turn that off with Auto
+Edit, and deletes still ask even then. If you want an agent that works unattended for an
+hour and shows you the result, that is not what this is.
+
+### It cannot see your running program
+
+There is no browser, no debugger attached, no screenshot of your app. It can run your
+build and read the output. It cannot click a button and see what happened.
+
+Since 1.1.0 you can [attach a screenshot yourself](IMAGE-RECOGNITION.md), which covers
+some of the same ground manually.
+
+### There is no telemetry, so there is no crash reporting
+
+Nobody sees your errors but you. If something breaks, the log in the output channel is
+the whole record, and an issue on GitHub is the only way we learn about it.
+
+---
+
+## Limits of small models
+
+This is the part people underestimate. HirayaCoder runs whatever model your laptop can
+hold, and that model is small. Small models are genuinely useful and genuinely limited,
+and the limits are specific rather than general.
+
+### It does not finish a whole application
+
+Measured, not guessed. On a 98-line brief for a complete React app:
+
+- A 0.8B model scaffolds the project, writes every file the request named, and installs
+ the dependencies.
+- It does not get the app working. The build fails, and **no model at this size finished
+ the app in any of our runs.**
+
+One model passed the scaffold, structure, install and build checks and shipped an app
+whose only button incremented the demo counter it started with. Four green gates and
+nothing that worked.
+
+So: one file, one feature, one fix at a time is where this tool earns its keep. A whole
+application handed over and walked away from is not something we can recommend yet. The
+numbers are in [SESSION-ANALYSIS-0.9.0.md](SESSION-ANALYSIS-0.9.0.md) and
+[MODELS.md](MODELS.md).
+
+### It is slow
+
+On a 16 GB laptop with no graphics card, expect one to five minutes for an ordinary
+task. Each step in an agent run is a separate model call, and a run can be eight steps.
+
+A graphics card makes it **faster, not smarter**. A bigger model makes it smarter, not
+faster. These are separate knobs and people mix them up constantly.
+
+### It repeats itself
+
+The classic small-model failure is not bad code, it is the same correct-looking action
+forever. HirayaCoder keeps a record of everything the agent has already done and puts it
+back in front of the model each turn, which fixes most of it. It does not fix all of it.
+
+### It reports success it did not achieve
+
+Small models say "I have created and tested the app" having written nothing. This is
+common enough that completion is checked against what actually changed on disk rather
+than against what the model says. When the check fires you are told plainly. When it
+does not fire, and the model was wrong anyway, you find out later.
+
+### It writes damaged files
+
+Four different models produced six damaged files in one seventeen-run sweep: deleted
+exports, a CommonJS module silently rewritten as ESM, an implementation replaced by an
+empty object. Every one of them parsed cleanly. There are guards for each of these
+specific shapes, and a guard only catches the shape it knows.
+
+### It does not know your codebase
+
+It sees what fits in the context window, which on a 1B model at medium settings is about
+1800 tokens for everything: the system prompt, your message, the file listing, and the
+result of its last action. It is not holding your architecture in its head. Naming the
+file you mean is worth more here than it would be with a large model.
+
+### It forgets between sessions, mostly
+
+There is memory, in three layers, and it is genuinely useful. It is not the same as a
+model that has read your whole repository.
+
+---
+
+## Limits of image recognition
+
+New in 1.1.0, and [documented in full](IMAGE-RECOGNITION.md). The short version:
+
+- **Small text is unreliable.** A stack trace in a normal screenshot will be partly
+ misread, and you will not be told which parts.
+- **Exact values need checking.** Line numbers, hex colours, version strings.
+- **Precise layout is out of reach.** It knows a button is near the top. It does not
+ know it is 24 pixels from the edge.
+- **A misread is silent.** The model does not hedge. It writes a confident paragraph
+ about the wrong thing, which is why the description is shown to you rather than
+ hidden.
+
+Formats are PNG, JPEG, WEBP, and GIF, at up to 4 MB each.
+
+---
+
+## Things that are not limitations, though they look like one
+
+Worth listing, because these get reported as bugs.
+
+**"It refused to write the file."** Usually the write guards working. A half-written
+file, unbalanced brackets, or a rewrite that deletes an export other files depend on.
+Ask again.
+
+**"It said the tool was not available."** Plan mode and read-only turns remove the
+writing tools structurally. The model is not being difficult, the tool genuinely does
+not exist for that turn.
+
+**"It asked me before running the build."** That is the permission gate. Turn on
+auto-approve for scripts if you want it not to.
+
+---
+
+## Where it does not compete
+
+| | HirayaCoder | A cloud assistant |
+|---|---|---|
+| Cost | Free, forever | Usually a monthly fee |
+| Internet | Not needed | Required |
+| Your code | Never leaves your computer | Sent to a company's servers |
+| Quality | Good on small tasks | Better on everything |
+| Speed | Seconds to minutes | Fast |
+| Whole applications | No | Sometimes |
+| Works on a plane | Yes | No |
+
+The trade is real. Nobody should choose this because they think it is secretly as good.
+Choose it because the code not leaving your machine is worth something to you, or
+because there is no budget, or because there is no connection.
+
+---
+
+## Next
+
+- [Choosing a model](CHOOSING-A-MODEL.md) — the ranking, and what each size actually manages
+- [The measurements](MODELS.md) — the full tables behind everything claimed here
+- [When something goes wrong](TROUBLESHOOTING.md)
+- [The security model](SECURITY.md)
diff --git a/doc/MODELS.md b/doc/MODELS.md
index cdad47b..1f8b739 100644
--- a/doc/MODELS.md
+++ b/doc/MODELS.md
@@ -125,10 +125,16 @@ Tier comes from `core/modelCapability.js`: ≤ 3B **or** no tool support → Tie
`gemma4:e2b` is named for its ~2B *effective* parameters, but Ollama reports 5.1B raw,
which is what the threshold sees.
-**Images** need the `vision` capability. `qwen3.5:*` and `gemma4:*` report it;
-`llama3.2:*` and `stable-code` do not. A model without it does not error on an image —
-it ignores it and answers from the text alone, which is why the attach button is
-disabled rather than left to fail quietly.
+**Images** need the `vision` capability. `qwen3.5:*`, `gemma4:*` and `minicpm-v4.6`
+report it; `llama3.2:*` and `stable-code` do not. A model without it does not error on
+an image — it ignores it and answers from the text alone, which is why the raw picture
+is never put on a message to one.
+
+**Since 1.1.0 that no longer disables the attach button.** The image reaches a text-only
+model as a written description produced by whichever installed model *can* see, so the
+button is gated on the machine having a vision model at all rather than on the selected
+one being it. Measurements are in [Image recognition](#image-recognition-110);
+the mechanism is in [IMAGE-RECOGNITION.md](IMAGE-RECOGNITION.md).
**TODO lists** require the `thinking` capability *and* ≥ 2B parameters
(`hirayacoder.model.todoMinParams`). `qwen3.5:0.8b` reports `thinking` and is excluded
@@ -645,6 +651,76 @@ unproductive rather than destructive.
---
+## Image recognition (1.1.0)
+
+From `tools/bench-vision.js`. Six photographs in `docs/test-images/`, both prompts
+(`answer` and `task`), two samples each, so **24 graded descriptions per model**. Machine
+B, `--cold`, which unloads the model between samples — without that the timings are
+Ollama's prompt cache rather than the model.
+
+| Model | Params | Subject | Detail | Text read | Confused | Cold |
+|---|---|---|---|---|---|---|
+| `minicpm-v4.6` | 752M | **24/24** | 42/48 | 4/8 | 0 | 11s |
+| `qwen3.5:0.8b` | 873M | 23/24 | **46/48** | **8/8** | 0 | 13s |
+
+`Subject` is naming the right thing. `Detail` is colour, setting, and count. `Text read`
+is only scored on the two fixtures that have words in them. `Confused` counts
+descriptions asserting something the photograph contradicts, and it can only be lost —
+a cat called a dog fails the fixture whatever else it got right.
+
+### What the numbers mean in practice
+
+**Naming the subject is solved at this size.** 47 of 48 across two sub-1B models, and
+zero confusions. If you attach a photo and ask what is in it, both of these answer
+correctly. That is a stronger result than expected for 752M parameters.
+
+**Reading text is not, and it depends on size of the text rather than size of the
+model.** Every one of `minicpm-v4.6`'s four text failures is `car.jpg`, whose only text
+is a small BMW badge on a grille. It read `cebu pacific` off the aeroplane — large,
+clear, high-contrast — on all four attempts. So the honest guidance is not "small models
+cannot read" but "crop and zoom before you rely on it", which is what
+[IMAGE-RECOGNITION.md](IMAGE-RECOGNITION.md) now says.
+
+**The two models differ more than their sizes suggest.** 121M parameters apart, and one
+read every word while the other read half. There is no way to predict which you have
+from the model card, which is the argument for the panel that shows you what was read.
+
+### The failure that changed the code
+
+`qwen3.5:0.8b`, one sample in twenty-four, replied:
+
+> I cannot see this image. I am an AI model designed to process text and provide
+> information, but I do not have the ability to view or interpret visual content like
+> screenshots, photos, or UI elements.
+
+It reports the `vision` capability. It was sent the image. It had described the same
+photograph correctly on the previous sample. This is a small model's text-only training
+reasserting itself over what it was actually handed.
+
+Left alone, that paragraph *is* the description: stored, put in front of the coding model
+as "what is in this picture", and shown to the user. The coding model then reasons from a
+statement that no image exists, which is worse than being told the read failed.
+`core/imageRecognition` now recognises the shape and reports a failed read.
+
+The detector is narrow on purpose. The recognition prompt asks the describer to say when
+it cannot make something out, so *"I cannot see the licence plate clearly"* is the
+instruction working, and a detector that ate those would punish the behaviour we want. It
+requires a first-person inability **plus** a visual object, and only looks at the opening
+400 characters, so a real description that ends with a boilerplate disclaimer survives.
+
+### Reproducing it
+
+```bash
+node tools/bench-vision.js minicpm-v4.6:latest --machine B --purpose both --repeat 2 --cold
+node tools/bench-vision.js qwen3.5:0.8b --machine B --purpose both --repeat 2 --cold
+```
+
+Raw runs: `benchmarks/results/B/vision__*.json`. Every record keeps the full description
+text, because when a score looks wrong the only way to tell a bad grader from a bad model
+is to read what the model actually wrote.
+
+---
+
## What each model exposed
Every item here was invisible to the mocked test suite.
diff --git a/doc/TROUBLESHOOTING.md b/doc/TROUBLESHOOTING.md
new file mode 100644
index 0000000..ecfba95
--- /dev/null
+++ b/doc/TROUBLESHOOTING.md
@@ -0,0 +1,89 @@
+# When something goes wrong
+
+Small AI models make mistakes. HirayaCoder has built-in checks that catch the common
+ones, so several of the messages below are the system **working**, not breaking.
+
+---
+
+
+Small AI models make mistakes. HirayaCoder has built-in checks that catch the common
+ones, so a few of the messages below are the system **working**, not breaking.
+
+## "It refused to write the file"
+
+**This is usually a good thing.** HirayaCoder checks the AI's work before saving and
+blocks writes that would damage your files — a half-written file, code with a missing
+bracket, or a rewrite that quietly deletes something other files depend on.
+
+Just ask again. It usually gets it right the second time.
+
+## "It said it was done but nothing changed"
+
+A known habit of small models: reporting success without doing the work. HirayaCoder
+checks and will tell you plainly when this happens. Ask again, and include the exact
+file name this time.
+
+## "It's taking forever"
+
+Normal on a laptop with no graphics card — a few minutes per task is expected. If it is
+much worse than that, the model is probably too big for your RAM. Try `llama3.2:1b`.
+
+## "The code it wrote doesn't work"
+
+Try, in order:
+
+1. Paste the error message into the chat. It is quite good at fixing errors it can see.
+2. Ask for a smaller piece of the problem.
+3. Switch to a bigger model if your RAM allows it.
+
+## "It can't run my program"
+
+HirayaCoder can only run programs already installed on your computer. If you ask it to
+run a Python script, you need Python installed. It will still *write* the code — it just
+cannot run it for you.
+
+It also only runs a fixed list of well-known commands. **This is the whole list** —
+anything else is refused on purpose, so a mistake by the AI cannot damage your system:
+
+| For | It may run |
+|---|---|
+| JavaScript / Node | `node`, `npm`, `npx`, `yarn`, `pnpm` |
+| Python | `python`, `python3`, `pip`, `pip3`, `pytest` |
+| Java | `java`, `javac`, `mvn`, `gradle` |
+| Go, Rust, .NET | `go`, `cargo`, `dotnet` |
+| Testing and formatting | `jest`, `mocha`, `vitest`, `ava`, `tsc`, `eslint`, `prettier` |
+| Other | `git`, `make`, `ollama` |
+
+Two things worth knowing before they surprise you:
+
+- **Everyday shell commands are not on the list** — `rm`, `ls`, `mkdir`, `curl` are all
+ refused. Creating files and folders happens through the safe file tools instead, so
+ `mkdir` is never needed: writing a file creates the folders above it.
+- **No shell is involved.** Commands run directly, so `&&`, `|`, and `>` are refused
+ rather than interpreted. One command at a time.
+
+You can add to the list in HirayaCoder's settings. The AI cannot add to it itself.
+
+---
+
+---
+
+## It cannot read my image
+
+Two different causes, and the message tells you which:
+
+- **"None of your installed models can read images"** — nothing you have installed has
+ vision. Pull one: `ollama pull minicpm-v4.6`. It is 1.6 GB and it is the smallest
+ thing that does the job.
+- **The description is wrong** — the vision model misread the picture. Open the
+ *What … saw* panel under your message to see exactly what it read, then say what it
+ got wrong in your next message. Full detail in
+ [IMAGE-RECOGNITION.md](IMAGE-RECOGNITION.md).
+
+---
+
+## Next
+
+- [What it cannot do, on purpose and otherwise](LIMITATIONS.md)
+- [Choosing a model](CHOOSING-A-MODEL.md)
+- [The security model, if a refusal surprised you](SECURITY.md)
diff --git a/doc/USING-IT.md b/doc/USING-IT.md
new file mode 100644
index 0000000..fd7433c
--- /dev/null
+++ b/doc/USING-IT.md
@@ -0,0 +1,182 @@
+# Using HirayaCoder day to day
+
+What the extension does once it is installed and you have a folder open: the three
+modes, what the panel is showing you while a run happens, and the request habits that
+make the difference between a small model finishing and a small model spinning.
+
+New in 1.1.0: [attaching images](IMAGE-RECOGNITION.md).
+
+---
+
+
+## Watching a run happen
+
+
+
+
+
+A local model can take the better part of a minute per step, so the panel shows you each
+one as it happens: what it is doing, which file, and the reason the model gave for it.
+It opens when the first step arrives and folds away when the turn ends — and if you open
+or close it yourself, it stays how you left it.
+
+That matters most when a run is going wrong. Six steps in, you can see it re-reading the
+same file or editing something you never asked about, and stop it — rather than finding
+out from the summary ten minutes later.
+
+## Small models that finish
+
+
+
+
+
+The classic failure of a very small model is not bad code — it is the same correct-looking
+action forever. HirayaCoder keeps its own record of every file the agent has read, written
+and deleted, every folder it has listed and every command it has run, and puts that record
+in front of the model on each turn.
+
+A repeated read is no longer fatal either. Asking twice for a directory listing used to end
+the run; now the agent is handed back what it already had, told what to do next, and only
+stopped if it asks a third time.
+
+## Long requests, one step at a time
+
+
+
+
+
+If you paste in a long, structured request — headings, numbered steps, a folder tree —
+HirayaCoder works through it **one section at a time**, in your order, using your words.
+It does not ask the model to summarise your request first: your headings already are the
+plan, and reading them takes no guesswork, so this works the same on a 0.8B model as on a
+large one.
+
+Two details worth knowing, because they let you steer it:
+
+- **Draw the folder structure you want** and it will be read as real paths. `src/` plus
+ `components/` plus `TodoItem.jsx` becomes `src/components/TodoItem.jsx`.
+- **Put a comment next to a file** — `TodoItem.jsx # one todo row, with edit and
+ delete` — and that comment becomes the instruction for writing it. A file with a
+ comment beside it may be rewritten if it already exists; a file without one is left
+ alone. That is how you say "this one is yours to write" and "this one came from the
+ scaffolding tool, don't touch it".
+
+A section that only states rules — "React functional components only, no UI libraries" —
+is not treated as a step. It is carried underneath every step instead.
+
+Short requests are unaffected. "Fix the typo in the heading" runs exactly as it always
+did.
+
+## Asked the wrong way
+
+
+
+
+
+The smallest models have a problem that looks like incompetence and is not. Asked to
+choose a tool and fill in its arguments as JSON, a 1B model will reliably answer with the
+simplest thing that satisfies the format — often just "done". Asked in plain English to
+write a file, the same model writes it correctly.
+
+So for a file **your request named**, HirayaCoder stops asking the model what to do. The
+decision is already made: the action is a file write, the path came from your own
+request, and the only question left is what goes in the file.
+
+It is worth being precise about what that does and does not allow, because it is the one
+place the model is not choosing:
+
+- It can only ever write a file **you named** in your request.
+- It never touches `package.json`, lockfiles, `.env`, or anything inside `node_modules`,
+ `dist` or `.git`.
+- It never replaces a file that already exists unless you put a comment next to it.
+- Every write still shows you the diff and waits for approval, exactly as before, and
+ still goes in the audit log.
+
+When it writes a file, it first reads what the files around it actually export, so the
+imports line up rather than being guessed at.
+
+## The three modes
+
+There is a row of buttons at the top of the chat. You can ignore them at first —
+**Agent** is the default and is what you want most of the time.
+
+| Mode | Use it when |
+|---|---|
+| **Agent** | You want it to actually write or change files. The normal choice. |
+| **Plan** | You want to see what it *would* do first, without it touching anything. |
+| **Ask** | You just have a question. It will not change any files. |
+
+You do not have to switch to Ask to ask a question — if you say "hello" or "what does
+this file do", Agent mode notices and just answers you.
+
+## Attaching a picture
+
+Click the image button beside the message box and pick a PNG, JPEG, WEBP, or GIF. In Ask
+mode you get an answer about the picture; in Agent mode the picture becomes part of the
+job, so "build the screen in this mockup" works.
+
+This is available even if the model you selected cannot see images. In that case
+HirayaCoder passes the picture to whichever installed model can, gets a written
+description back, and gives that to your coding model. Under your message, a panel
+labelled *What … saw* shows exactly what was read, which is how you tell a misread
+picture from a bad answer.
+
+If nothing installed can read images, `ollama pull minicpm-v4.6` is the smallest fix.
+
+Full detail, including what it gets wrong: [IMAGE-RECOGNITION.md](IMAGE-RECOGNITION.md).
+
+## Which model replied, and how long it took
+
+Under every answer there is a small line:
+
+```
+minicpm-v4.6:latest • 25s
+```
+
+It is there because the model is the main lever you have. A task takes one to five
+minutes on an ordinary laptop, and the way to make it faster is to run something smaller,
+not to wait. Comparing two models means comparing replies that are several messages
+apart, and this makes that a matter of scrolling rather than of memory.
+
+The time is the turn itself. If the turn waited for another chat tab to finish, the wait
+is not counted, so the number is what this model cost you.
+
+When a different model read an attached image, it gets its own entry, because that is
+where the extra seconds went:
+
+```
+llama3.2:latest • 17s + minicpm-v4.6:latest read the image, 8s
+```
+
+## Nothing changes without your say-so
+
+By default, every time it wants to write to a file, you get a prompt with a **Review
+diff** button showing exactly what changes. Nothing is saved until you approve.
+
+Once you trust it, you can turn on **Auto Edit** to skip those prompts. Deleting a file
+always asks, even then.
+
+## Tips that make a real difference
+
+- **Ask for one thing at a time — or structure the big ask.** "Add a delete button" works
+ far better than "add delete, edit, sorting, and dark mode" thrown in as one sentence.
+ If you do want the big one, give it headings, numbered steps or a folder tree, and it
+ will work through them one at a time — see
+ [Long requests, one step at a time](#long-requests-one-step-at-a-time).
+- **Name the file** if you know it. "Change the title in index.html" beats "change the
+ title".
+- **It remembers this conversation**, so you can say "make it bigger" and it knows what
+ "it" is.
+- **Be specific about what is wrong.** "The button doesn't do anything when I click it"
+ is much more useful than "it's broken".
+
+---
+
+---
+
+## Next
+
+- [Reading images](IMAGE-RECOGNITION.md) — attaching a screenshot or a photo to a message
+- [What it cannot do](LIMITATIONS.md)
+- [When something goes wrong](TROUBLESHOOTING.md)
+- [Every setting, in detail](FEATURES.md)
diff --git a/docs/images/ADS-1.1.0.md b/docs/images/ADS-1.1.0.md
new file mode 100644
index 0000000..3f07ede
--- /dev/null
+++ b/docs/images/ADS-1.1.0.md
@@ -0,0 +1,125 @@
+# HirayaCoder 1.1.0 — image recognition ad set
+
+Two square (1:1) ads for the 1.1.0 feature release, with the caption each one ships
+with, plus a single caption for posting the pair together.
+
+Rendered at **2160×2160** from the sources in `src/` (1080×1080 CSS pixels at
+`--force-device-scale-factor=2`), same as the four 1.0.0 launch ads in
+[`ADS-1.0.0.md`](ADS-1.0.0.md). 1:1 is the safe ratio everywhere: it is the native
+LinkedIn/Instagram feed shape, and X and Facebook centre-crop it without losing content.
+
+| # | Image | Source | The one thing it argues |
+|---|---|---|---|
+| 5 | `ad-5-vision.png` | `src/ad-5-vision.html` | A text-only model can now use your screenshot |
+| 6 | `ad-6-what-it-read.png` | `src/ad-6-what-it-read.html` | You always see what the model actually read |
+
+Order matters if you post them as a pair: 5 is the capability, 6 is the objection
+("can I trust what a 750M model says it saw?"). Posting 6 alone works; posting 5 alone
+oversells.
+
+Regenerating them is the same command as the README images — see
+[`src/README.md`](src/README.md).
+
+---
+
+## The numbers in ad 6 are real, and they expire
+
+`ad-6-what-it-read.html` carries three measurements on its face. They come from
+`tools/bench-vision.js` on machine B, and the raw runs are in
+`benchmarks/results/B/vision__*.json`:
+
+| On the ad | Where it comes from |
+|---|---|
+| **47/48** named the subject correctly | `minicpm-v4.6` 24/24 plus `qwen3.5:0.8b` 23/24, both prompts, two samples each |
+| **0** described something not in the photo | the `confused` axis, zero on both models |
+| **12/16** read the text printed in the picture | `minicpm-v4.6` 4/8 plus `qwen3.5:0.8b` 8/8 |
+
+**Re-run the sweep before re-rendering this ad for any later release.** An ad quoting a
+score the harness no longer produces is worse than one quoting none, and these are
+small-sample numbers on models that get replaced.
+
+The one that will move is the third. It is also the one the ad is built around, so if a
+future sweep makes it flattering, the ad needs rewriting rather than renumbering: the
+argument is "you cannot tell which model you have without looking", and it stops working
+if both models read everything.
+
+---
+
+## Ad 5 — `ad-5-vision.png`
+
+> Your AI model probably cannot see. That stopped mattering.
+>
+> HirayaCoder 1.1.0 reads images. Attach a screenshot, a photo, or a sketch of a screen
+> you want built, and it uses what is in the picture.
+>
+> The part worth knowing: **this works even when the model you code with is text-only.**
+> Most local models are. HirayaCoder hands the picture to whichever installed model has
+> vision, gets back a written description, and passes that to your coding model. You do
+> not switch models, and you do not give up the one you like.
+>
+> It also keeps working past the first turn. An agent run is eight or ten rounds and the
+> picture only rides on the first one, so a written description is the only form of it
+> that survives to the end.
+>
+> Both models run on your own machine. The image goes to 127.0.0.1 and nowhere else,
+> like everything else this extension sends.
+>
+> `ollama pull minicpm-v4.6` is 1.6 GB and it is all you need.
+
+## Ad 6 — `ad-6-what-it-read.png`
+
+> A small model that misreads your screenshot does not tell you.
+>
+> That is the actual problem with image recognition on local hardware. It does not
+> hedge, it does not say "I am not sure". It writes a fluent, confident paragraph about
+> the wrong thing, and every answer after that is built on it.
+>
+> So HirayaCoder shows you the paragraph. Every image you attach comes with a panel
+> holding the exact text the vision model produced. When an answer looks wrong you can
+> tell, in one click, whether the picture was misread or the reasoning was. Those need
+> opposite fixes and they are otherwise indistinguishable.
+>
+> Measured on six photographs across two models under 1B parameters: 47 of 48 named the
+> subject correctly, and none of them described something that was not there.
+>
+> But only 12 of 16 read the text printed in the picture, and that number was not evenly
+> split. One model read every word. The other, almost the same size, read half.
+>
+> We published the number we came off worst on, because it is the one that tells you to
+> open the panel.
+
+---
+
+## The one caption for both
+
+Use this when posting them together.
+
+> **HirayaCoder 1.1.0 can look at pictures, and it shows you what it saw.**
+>
+> HirayaCoder is a free, fully offline AI coding agent for VS Code. It runs on your own
+> machine through Ollama, and nothing you write ever leaves your laptop. This release
+> teaches it to read images.
+>
+> **1. It works on a model that cannot see.** Most local models are text-only. Attach a
+> screenshot anyway: the picture goes to whichever installed model has vision, comes
+> back as a written description, and that goes to your coding model. No switching, no
+> giving up the model you like. `ollama pull minicpm-v4.6` is 1.6 GB.
+>
+> **2. It survives the whole run.** An agent turn is eight or ten rounds, and the image
+> only rides on the first one. The description is small enough to carry on every round,
+> which is why it is produced even for a model that can see perfectly well.
+>
+> **3. You always see what it read.** A vision model that misreads your screenshot does
+> not hedge, it writes a confident paragraph about the wrong thing. Every attachment
+> comes with a panel showing the exact description, so you can tell a misread picture
+> from a bad answer.
+>
+> **4. The numbers, including the bad one.** Six photographs, two models under 1B: 47 of
+> 48 named the subject, 0 invented something that was not there, and 12 of 16 read the
+> printed text. That last one split unevenly. One model read every word and the other
+> read half, which is precisely why the panel exists.
+>
+> Still free, still MIT, still zero production dependencies, still refuses any address
+> that is not 127.0.0.1. github.com/jaymar921/HirayaCoder
+>
+> #OfflineAI #LocalLLM #VSCode #PrivacyFirst #OpenSource #VisionModels
diff --git a/docs/images/ad-5-vision.png b/docs/images/ad-5-vision.png
new file mode 100644
index 0000000..aa21e6b
Binary files /dev/null and b/docs/images/ad-5-vision.png differ
diff --git a/docs/images/ad-6-what-it-read.png b/docs/images/ad-6-what-it-read.png
new file mode 100644
index 0000000..c578f9b
Binary files /dev/null and b/docs/images/ad-6-what-it-read.png differ
diff --git a/docs/images/src/README.md b/docs/images/src/README.md
index 9b0c9ff..fa97c9d 100644
--- a/docs/images/src/README.md
+++ b/docs/images/src/README.md
@@ -16,10 +16,13 @@ one-line change instead of a redesign.
| `ad-2-agentic.html` | `../ad-2-agentic.png` | Social ad — agentic down to 1B |
| `ad-3-approval.html` | `../ad-3-approval.png` | Social ad — you approve every write |
| `ad-4-launch.html` | `../ad-4-launch.png` | Social ad — the 1.0 launch card |
+| `ad-5-vision.html` | `../ad-5-vision.png` | Social ad — a text-only model can use your screenshot |
+| `ad-6-what-it-read.html` | `../ad-6-what-it-read.png` | Social ad — you see what the vision model read |
-The six README images are **1280×720**; the four `ad-*` files are **1080×1080**, because
+The six README images are **1280×720**; the six `ad-*` files are **1080×1080**, because
a social post gets cropped to a square on most of the places it lands. Their captions
-live in [`../ADS-1.0.0.md`](../ADS-1.0.0.md).
+live in [`../ADS-1.0.0.md`](../ADS-1.0.0.md) (ads 1–4) and
+[`../ADS-1.1.0.md`](../ADS-1.1.0.md) (ads 5–6).
All of them are self-contained: no fonts, scripts, or images are fetched, and the app icon is
inlined as SVG. Everything renders from system fonts, so they look the same on any
@@ -52,6 +55,25 @@ writes nothing, so check the file timestamps rather than the exit code:
- **`--screenshot` will not write to a path containing a space.** Render to a scratch
folder and copy the PNG into `docs/images/` afterwards.
+## `ad-6-what-it-read.html` carries measurements, and they expire
+
+It is the only source here with numbers on its face, and they come from
+`benchmarks/results/B/vision__*.json` by way of `tools/bench-vision.js`. **Re-run that
+sweep before re-rendering this file for a later release.** An ad quoting a score the
+harness no longer produces is worse than one quoting none, and these are small-sample
+numbers on models that get replaced every few months.
+
+Renumbering is not always enough. The ad's argument is that you cannot tell how well
+your model reads text without looking at what it read, and that argument depends on the
+two models disagreeing. A future sweep where both read everything needs the ad rewritten,
+not re-rendered. The derivation of each figure is in
+[`../ADS-1.1.0.md`](../ADS-1.1.0.md).
+
+The mock description inside the panel — the checkout form — is a mock, like the hero's
+chat transcript, and is held to the same rule: it must never show something the
+extension does not do. The disclosure triangle and the *What … saw in …* label are the
+real ones.
+
## When these need updating
- **The version badge**, on every release. It appears once per file, as `v1.0.0`.
diff --git a/docs/images/src/ad-5-vision.html b/docs/images/src/ad-5-vision.html
new file mode 100644
index 0000000..b8db1aa
--- /dev/null
+++ b/docs/images/src/ad-5-vision.html
@@ -0,0 +1,153 @@
+
+
+
+
+HirayaCoder ad 5 — vision
+
+
+
+
+
+
+
+
+
+ HirayaCoder
+ v1.1.0
+ New
+
+
+
Your coding model cannot see. Now it can.
+
+
+ Attach a screenshot to a text-only model. HirayaCoder hands the picture to a vision
+ model, gets the words back, and passes them on. You never switch models.
+
+
+
+
+ Reads the picture
+ minicpm-v4.6
+
✓ Vision, 1.6 GB
+
Looks once. Writes down what is in the image, including the text it can read.
+
+
+
+
→
+
plain text
+
+
+
+ Does the work
+ llama3.2
+
✕ No vision at all
+
Reads the description and gets on with the job, exactly as if you had typed it out.
+
+
+
+
+ Both models stay on your machine. The picture goes to 127.0.0.1
+ and nowhere else, like everything else this extension sends.
+
+
+
+
+
+
diff --git a/docs/images/src/ad-6-what-it-read.html b/docs/images/src/ad-6-what-it-read.html
new file mode 100644
index 0000000..1f7c7de
--- /dev/null
+++ b/docs/images/src/ad-6-what-it-read.html
@@ -0,0 +1,154 @@
+
+
+
+
+HirayaCoder ad 6 — what it read
+
+
+
+
+
+
+
+
+
+ HirayaCoder
+ v1.1.0
+
+
+
A model that misreads your screenshot says so.
+
+
+ It writes a confident paragraph about the wrong thing instead. So HirayaCoder shows
+ you the paragraph. Every image you attach comes with what was read out of it.
+
+
+
+
▾ What minicpm-v4.6 saw in checkout.png
+
+ A screenshot of a checkout form. Three fields, labelled Card number,
+ Expiry, and CVC. Below them a red banner reading
+ "Card declined: insufficient funds". The pay button is greyed out.
+
+
+
+
+
+
47/48
+
named the subject correctly, across two sub-1B models
+
+
+
0
+
described something the photo does not contain
+
+
+
12/16
+
read the text printed in the picture
+
+
+
+
+ That third number is the one that moves. One of the two read every word.
+ The other, almost the same size, read half. You cannot tell which you have without
+ looking at what it read, so we published the number and built the panel.
+
+
+
+
+
+
diff --git a/docs/test-images/car.jpg b/docs/test-images/car.jpg
new file mode 100644
index 0000000..e96b722
Binary files /dev/null and b/docs/test-images/car.jpg differ
diff --git a/docs/test-images/cat.jpg b/docs/test-images/cat.jpg
new file mode 100644
index 0000000..a9b17cb
Binary files /dev/null and b/docs/test-images/cat.jpg differ
diff --git a/docs/test-images/dog-1.jpg b/docs/test-images/dog-1.jpg
new file mode 100644
index 0000000..bccf482
Binary files /dev/null and b/docs/test-images/dog-1.jpg differ
diff --git a/docs/test-images/dog.jpg b/docs/test-images/dog.jpg
new file mode 100644
index 0000000..5ae895b
Binary files /dev/null and b/docs/test-images/dog.jpg differ
diff --git a/docs/test-images/plane.jpg b/docs/test-images/plane.jpg
new file mode 100644
index 0000000..cb88313
Binary files /dev/null and b/docs/test-images/plane.jpg differ
diff --git a/docs/test-images/tree.jpg b/docs/test-images/tree.jpg
new file mode 100644
index 0000000..637f558
Binary files /dev/null and b/docs/test-images/tree.jpg differ
diff --git a/package.json b/package.json
index bfe4f9a..9269dd6 100644
--- a/package.json
+++ b/package.json
@@ -2,7 +2,7 @@
"name": "hirayacoder",
"displayName": "HirayaCoder",
"description": "A fully offline, privacy-first AI coding agent powered by your local Ollama instance. Agentic on every model — even 1B.",
- "version": "1.0.0",
+ "version": "1.1.0",
"publisher": "jaymar921",
"author": {
"name": "jaymar921",
@@ -35,7 +35,10 @@
"ai agent",
"privacy",
"copilot alternative",
- "code assistant"
+ "code assistant",
+ "vision",
+ "image recognition",
+ "multimodal"
],
"main": "./app/extension.js",
"activationEvents": [
@@ -363,6 +366,16 @@
"minimum": 1,
"markdownDescription": "How many times one model must trip the same guard before the matching correction is added to its prompt. Lower learns faster and spends more of a small model's prompt budget on corrections; one trip is an accident rather than a habit."
},
+ "hirayacoder.vision.enabled": {
+ "type": "boolean",
+ "default": true,
+ "markdownDescription": "Read attached images and turn them into a written description the model can work from. **This is what lets a text-only model use a screenshot** — the picture goes to whichever installed model has vision, and the description goes to the model you selected. Turn it off to save the extra model load; a model that can see images itself still receives them directly."
+ },
+ "hirayacoder.vision.describeModel": {
+ "type": "string",
+ "default": "",
+ "markdownDescription": "Which model reads your images. Leave empty to pick automatically: your selected model when it has vision (no extra load), otherwise the smallest installed model that does. A name here is used only if that model is installed **and** reports vision — otherwise the automatic choice is used and the reason is written to the log."
+ },
"hirayacoder.statusBar.enabled": {
"type": "boolean",
"default": true,
diff --git a/security/sast-report-2026-08-21-1.1.0.md b/security/sast-report-2026-08-21-1.1.0.md
new file mode 100644
index 0000000..50b2855
--- /dev/null
+++ b/security/sast-report-2026-08-21-1.1.0.md
@@ -0,0 +1,144 @@
+# HirayaCoder — SAST Report
+
+**Date:** 2026-08-21
+**Commit / version:** `1.1.0`, branch `feat/1.1.0-image-recognition`
+**Performed by:** 1.1.0 hardening pass
+**Platform:** Windows 11 Pro 26100, Node v24.11.1, ESLint 9.39.5
+
+Supersedes `security/sast-report-2026-08-20-1.0.0.md`. Every finding carried forward
+from it is re-stated below with its current status.
+
+The release under review adds one new capability with a genuinely new shape: **an image
+file, chosen by the user, base64-encoded and sent to a local model, whose free-text reply
+is then placed in another model's prompt.** That is a new untrusted-input path and it is
+where most of this pass went.
+
+## 1. Tooling Run
+
+| Tool | Command | Scope | Result |
+|---|---|---|---|
+| ESLint (security rules) | `npm run lint` | `/app`, `/test` | **0 errors, 42 warnings** (all reviewed, §4) |
+| ESLint, changed files only | `npx eslint ` | 9 files | **0 errors, 0 warnings** after SAST-016 |
+| npm audit (production) | `npm audit --omit=dev` | shipped tree | **0 vulnerabilities** |
+| npm audit (full) | `npm audit` | incl. dev tree | **0 vulnerabilities** |
+| retire.js 5.4.3 | `npx retire --path app` | `/app` | **no findings** |
+| Semgrep 1.172.0 | `semgrep --config p/javascript --config p/security-audit --metrics=off app tools` | `/app`, `/tools` | 6 findings, 5 locations, all one rule (SAST-004, SAST-017) |
+| Package contents | `npx vsce ls` | shipped `.vsix` | 97 files; **0** from `node_modules/`, `test/`, `tools/`, `benchmarks/` |
+| Manual review | checklist in §4 | `/app`, `/security` | complete |
+| Unit suite | `npm run test:unit` | `/app` | **1584 passing** |
+| ReDoS measurement | `node`, adversarial inputs | 2 regexes | linear, §3 |
+
+The production dependency tree is still empty (`"dependencies": {}`), which is what makes
+the `--omit=dev` result meaningful rather than lucky.
+
+## 2. Findings Summary
+
+| Severity | Count | Resolved | Accepted Risk (with justification) |
+|---|---|---|---|
+| Critical | 0 | 0 | 0 |
+| High | 1 | 0 | 1 — intended, layered design (SAST-004) |
+| Medium | 0 | 0 | 0 |
+| Low | 3 | 3 | 0 |
+| Info | 4 | 2 | 2 — measured as linear (SAST-003, SAST-016) |
+
+No finding required a change to a permission, a path guard, or the allow-list. Three were
+fixed (SAST-015, SAST-018, SAST-020), and one Info-level ordering hardening was applied
+(SAST-016). SAST-020 is the one worth reading: it is a real gap, it was found by manual
+review rather than by any tool, and the first draft of this report argued for accepting
+it on grounds that turned out to be false when measured.
+
+## 3. Findings Detail
+
+| ID | Tool | File:Line | Description | Severity | Status | Resolution / Justification |
+|---|---|---|---|---|---|---|
+| SAST-015 | Manual review, this pass | `app/core/imageRecognition.js` (new) | **Model output placed in another model's prompt without validation.** A vision model's free-text reply becomes the description block in the coding model's context. An unbounded or adversarial reply could crowd out the task, or assert its own instructions. | Low | **Resolved** | Three bounds, all in `describe`: `num_predict` caps generation at 640 tokens; the stored string is truncated to 1600 characters; and `contextBuilder` allocates the block a priority and a `minTokens` floor, so it competes for budget rather than consuming it. The block is also framed — `renderForPrompt` states the text is a *description produced by a vision model*, which is the same untrusted-content framing the Context Files block uses. Prompt injection via an image remains **out of scope by threat model**: the image comes from the user's own file picker, and a user who wants to instruct the model can type. |
+| SAST-016 | ESLint `security/detect-unsafe-regex` | `app/agent/agentSession.js:268` (`UNDICTATABLE`) | Pre-existing. Alternation with an adjacent optional group (`\\.env(?:\\..+)?$`) flagged as potentially super-linear. Called on model-written path strings. | Info | **Resolved (hardening)** | **Measured rather than argued.** Worst case over adversarial shapes: `/.env` + 395 dots → 0.210 ms; 400 slashes → 0.085 ms; and *unbounded* at 40,000 characters → 0.030 ms. Linear. The greedy `.+` is `$`-anchored with no ambiguous adjacent quantifier, so no candidate split is retried. **Separately fixed:** the call site ran this regex *before* the 400-character bound in `isDictatableFilename`, despite `MAX_TARGET_PATH_CHARS` being documented as the bound that keeps the check linear. Both are side-effect-free `continue` guards, so the order was free to change; the bounded check now runs first. Not a fix for a live ReDoS — it is the ordering that means one is never reachable here if the pattern is later edited into an ambiguous one. |
+| SAST-017 | Semgrep `javascript.lang.security.detect-child-process` | `tools/bench-build.js:290`, `tools/bench-realworld.js:99`, `tools/lib/javaProbe.js:44`, `tools/lib/pythonProbe.js:351` | `spawnSync(argv[0], argv.slice(1))` in the benchmark harnesses. | Low (rule) | **Accepted** | Developer tooling, **not shipped** — `npx vsce ls` returns 0 files from `tools/`. Every `argv` is built inside the harness from a fixture task or a command-line flag typed by the person running it, `shell` is not set, and there is no path from model output to any of them. *Newly relevant this pass:* `tools/bench-vision.js` was drafted with a `spawnSync('ollama', ['stop', model], { shell: true })` to unload a model between samples. `shell: true` with an argument array is precisely the DEP0190 unescaped-concatenation shape, so it was replaced with an HTTP call (`generate` with `keep_alive: 0`) through the existing loopback-only client. The new harness imports no `child_process` at all. |
+| SAST-018 | `tools/bench-vision.js`, this pass | `.vscodeignore` | **3.6 MB of benchmark fixture photographs would have shipped in the `.vsix`.** `docs/**` is not ignored wholesale — only `docs/assets/**` and `docs/images/**` are — so `docs/test-images/`, added this release, was packaged by default. | Low | **Resolved** | Rule added, with a comment naming the general hazard: a new subdirectory under `docs/` is packaged unless someone thinks about it. Verified with `npx vsce ls`: 103 files before, 97 after, 0 matching `test-images`. Not a vulnerability, but it is an unreviewed-content-in-the-shipped-artefact problem and it is cheaper to catch here than in a release. |
+| SAST-019 | Manual review, this pass | `app/core/imageRecognition.js` (`REFUSAL`) | New regex, run against model output. Checked for catastrophic backtracking before it was accepted, per the standing rule that a flagged-or-not pattern over model text gets measured. | Info | **Resolved** | Input is sliced to 400 characters before the test, so the bound is structural. Measured anyway: worst case 1.195 ms on 400 characters of `"i cannot see "` repeated, 0.033 ms *unbounded* at 100,000 characters. ESLint flags neither `detect-unsafe-regex` nor `detect-non-literal-regexp` on it — it is a literal, not constructed. |
+| SAST-020 | Manual review, this pass | `app/core/imageRecognition.js` → `app/core/contextBuilder.js` | **A credential visible in a screenshot reached the prompt unredacted.** Every other block `contextBuilder` assembles — file contents, selections, observations, the open editor — is passed through `redact`. The new image-description block was not. | Low | **Resolved** | Now redacted like the rest. The reasoning matters more than the diff: this path does not merely *permit* a secret through, it **asks for one**. The `task` recognition prompt instructs the describer to copy every piece of visible text exactly, because a misread filename sends the agent to the wrong file — so a screenshot of a terminal showing `export OPENAI_API_KEY=sk-…` yields a description containing the key by design. Verified against `secretsScanner`: `redact` replaces the matched token and leaves the surrounding sentence standing, so the description stays useful; an initial draft of this report justified skipping it on the grounds that a false positive would blank the answer, which measurement showed to be simply wrong. Covered by a test. **Not** applied to the on-screen panel: that shows the user the contents of their own picture, which they are already looking at, and it is not persisted to the transcript. |
+| SAST-004 | Semgrep `javascript.lang.security.detect-child-process` | `app/security/scriptRunner.js:451` | Carried forward. `spawn()` reached from the `command` and `options` arguments. Impact HIGH, **confidence LOW**. | High (rule) | **Accepted, unchanged** | A true positive by pattern and the intended design: the only `child_process` call in shipped code, in the module that exists to make it safe. Argument array with `shell: false`; `argv[0]` must match the allow-list; shell metacharacters rejected at tokenize time; Windows `.cmd` shims pre-screened; the caller must already hold a `permissionGate` approval. Unchanged by 1.1.0 — the image path opens no process. |
+| SAST-003 | ESLint `security/detect-unsafe-regex` | 22 sites across `/app` | Carried forward. Patterns with adjacent optional groups. | Info | **Accepted, unchanged** | Each reviewed individually in previous passes and re-confirmed unchanged this pass. All are `^`-anchored with optional groups beginning at a literal or a disjoint character class, and every input is length-bounded at its call site. SAST-016 is the one that gained a call-site ordering fix. |
+| SAST-014 | Prior pass | `app/agent/stepBrief.js` | Carried forward, **already fixed in 1.0.0.** O(n²) path-token sweep. | — | **Closed** | Re-verified: the 120-character segment bound and its timing test are both present and passing. |
+
+## 4. Manual Review Checklist
+
+Items unchanged by this release are marked *(unchanged)* and were re-verified rather than
+re-argued.
+
+- [x] **Command injection** *(unchanged)* — `child_process` is still imported in exactly
+ one shipped file (`security/scriptRunner.js`, `spawn` only). Confirmed by grep
+ across `/app`. The image path opens no process. `tools/bench-vision.js`
+ deliberately does not import it (SAST-017).
+- [x] **Path traversal — the new file read.** `imageContext.readImage` is the only new
+ filesystem read, and its path comes from `vscode.window.showOpenDialog`, i.e. from
+ the user clicking a file, never from model output. Re-confirmed that nothing in
+ the 1.1.0 diff lets a model name an image: `_attachImage` is reachable only from
+ the webview's `attach-image` message, which carries no path, and the picker is
+ opened host-side. The webview never names a file, which is the rule
+ `.claude/skills/frontend-design` states and this diff keeps.
+- [x] **Content validation on the new input.** Extension allow-list (5 formats), a
+ `stat` size check **before** the read so an enormous file is never pulled into
+ memory, then a magic-number sniff of the actual bytes with a warning on
+ extension/content mismatch. Pre-existing and unchanged; re-read this pass because
+ the input is newly reachable on models where it previously was not.
+- [x] **The new network path.** None. Images go to the same `ollamaClient` as every other
+ request, which validates loopback at construction. No new socket, no new host, no
+ new protocol. `assertLoopbackEndpoint` is unchanged.
+- [x] **Model output crossing a trust boundary.** The one genuinely new boundary in this
+ release, covered by SAST-015. Also checked: the description reaches the **webview**
+ as well as the prompt, and `messageBubble.appendVisionNote` builds it with
+ `createElement` + `textContent`, never `innerHTML`. `eslint-plugin-no-unsanitized`
+ is clean on the file.
+- [x] **Denial of service via the new path.** A description is one bounded model call
+ with `num_predict` set; `describeAll` is sequential, so N images are N serial calls
+ rather than N concurrent ones; the in-memory cache is bounded at 32 entries with
+ the oldest evicted, keyed on a 32-hex-character digest rather than on the megabyte
+ of base64 itself. A failed call returns text, so one unreadable attachment cannot
+ throw away the turn.
+- [x] **Secrets.** See SAST-020 — the one finding this pass that changed shipped
+ behaviour on its own merits rather than as hardening.
+- [x] **Permissions and path confinement** *(unchanged)* — the image path grants nothing.
+ It reads one user-chosen file and produces text. No tool, no mode, no allow-list,
+ and no `permissionGate` call site was touched by this release; confirmed by
+ reviewing the diff for `app/security/**` (empty).
+- [x] **Prototype pollution / object injection** — 6 ESLint warnings across `/app`, all
+ pre-existing and previously reviewed. The two the new module raised were resolved
+ before this report: `PROMPTS[purpose]` is now a single lookup on a value narrowed
+ to one of two string literals, annotated at the line; the other is a loop counter
+ over a local array.
+- [x] **ReDoS** — SAST-016 and SAST-019, both measured rather than assumed, per the
+ standing rule for this repository.
+- [x] **Shipped artefact contents** — SAST-018. `npx vsce ls` reviewed in full this pass
+ rather than grepped, which is how the fixture photographs were found.
+
+## 5. What Changed Since 1.0.0
+
+- **New module reviewed in full:** `app/core/imageRecognition.js`.
+- **Modified and re-reviewed:** `app/agent/agentSession.js`, `app/features/chatTab.js`,
+ `app/core/contextBuilder.js`, `app/extension.js`,
+ `app/webview/components/messageBubble.js`, `app/webview/main.js`.
+- **New developer tooling, not shipped:** `tools/bench-vision.js`.
+- **Three fixes with a security dimension:** SAST-020 (a credential visible in a
+ screenshot reaching the prompt unredacted), SAST-018 (unreviewed content in the shipped
+ package), and the SAST-016 guard ordering.
+- **One behavioural fix found by measurement rather than by review:** a vision model
+ replying *"I cannot see this image"* had that sentence stored and presented as the
+ description. Not a vulnerability — it is a correctness bug — but it is the class of
+ thing where a model's output is trusted as data, and it is recorded here because that
+ is the same class SAST-015 is about.
+
+## 6. Residual Risk
+
+Unchanged from 1.0.0 in kind, with one addition:
+
+- **`scriptRunner` runs programs.** By design, allow-listed, shell-free, and gated. The
+ residual risk is a program on the allow-list being used to do something unintended, and
+ it is accepted because a coding agent that cannot run the user's tests is not one.
+- **Images are shown to a local model.** New this release. Anything visible in an
+ attached picture is visible to the describer, and the description is shown back in the
+ panel. It does not leave the machine. Since SAST-020 the description is redacted before
+ it reaches any prompt, so a recognised credential does not propagate — but
+ `secretsScanner` matches known patterns and known entropy, and a secret in a shape it
+ does not recognise will pass through, exactly as it would if the user had pasted it.
+ The panel is deliberately unredacted: it shows the user their own picture back.
diff --git a/test/unit/imageRecognition.test.js b/test/unit/imageRecognition.test.js
new file mode 100644
index 0000000..f68a770
--- /dev/null
+++ b/test/unit/imageRecognition.test.js
@@ -0,0 +1,315 @@
+'use strict';
+
+/**
+ * `core/imageRecognition` — choosing a describer, calling it, and rendering what it
+ * said into a prompt block.
+ *
+ * The model call is mocked throughout. What matters here is the decision logic around
+ * it: which model gets asked, what it is asked for, what happens when it fails, and
+ * whether the answer is cached. Whether a real vision model can actually see a cat is a
+ * different question, and it is measured by `tools/bench-vision.js` against real
+ * photographs, because no mock can answer it.
+ */
+
+const assert = require('assert');
+
+const imageRecognition = require('../../app/core/imageRecognition');
+
+/** A one-pixel worth of base64. Content is irrelevant; identity is not. */
+const IMAGE_A = Buffer.from('image-a').toString('base64');
+const IMAGE_B = Buffer.from('image-b').toString('base64');
+
+/**
+ * @param {string | Error} reply Text to return, or an error to throw.
+ */
+function mockClient(reply) {
+ return {
+ calls: /** @type {any[]} */ ([]),
+ async chat(body) {
+ this.calls.push(body);
+ if (reply instanceof Error) throw reply;
+ return { message: { content: reply } };
+ },
+ };
+}
+
+const model = (name, params, vision) => ({ name, params, supportsVision: vision });
+
+describe('imageRecognition', () => {
+ beforeEach(() => imageRecognition._clearCache());
+
+ describe('pickDescriber', () => {
+ it('prefers the selected model when it can see, because that costs no extra load', () => {
+ const pick = imageRecognition.pickDescriber(
+ [model('qwen3.5:4b', 4.7, true), model('minicpm-v4.6:latest', 0.75, true)],
+ { activeModel: 'qwen3.5:4b' }
+ );
+ assert.strictEqual(pick.name, 'qwen3.5:4b');
+ assert.strictEqual(pick.isActive, true);
+ });
+
+ it('falls back to the smallest vision model when the selected one is blind', () => {
+ // Smallest, not best: Ollama holds one model at a time, so this choice is paid
+ // for in load time and the description is a read rather than a piece of
+ // reasoning.
+ const pick = imageRecognition.pickDescriber(
+ [model('llama3.2:latest', 3.2, false), model('qwen3.5:4b', 4.7, true), model('minicpm-v4.6:latest', 0.75, true)],
+ { activeModel: 'llama3.2:latest' }
+ );
+ assert.strictEqual(pick.name, 'minicpm-v4.6:latest');
+ assert.strictEqual(pick.isActive, false);
+ });
+
+ it('sorts a model of unknown size last rather than first', () => {
+ // `params` is null when Ollama did not report a size. Treating that as zero would
+ // make an unknown quantity beat every known small model.
+ const pick = imageRecognition.pickDescriber(
+ [model('mystery:latest', null, true), model('minicpm-v4.6:latest', 0.75, true)],
+ { activeModel: 'llama3.2:latest' }
+ );
+ assert.strictEqual(pick.name, 'minicpm-v4.6:latest');
+ });
+
+ it('honours a describer named in settings', () => {
+ const pick = imageRecognition.pickDescriber(
+ [model('qwen3.5:4b', 4.7, true), model('minicpm-v4.6:latest', 0.75, true)],
+ { activeModel: 'llama3.2:latest', preferred: 'qwen3.5:4b' }
+ );
+ assert.strictEqual(pick.name, 'qwen3.5:4b');
+ assert.strictEqual(pick.reason, 'chosen in settings');
+ });
+
+ it('ignores a setting that names a model which cannot see', () => {
+ // A stale name in settings must not silently disable images altogether.
+ const pick = imageRecognition.pickDescriber(
+ [model('llama3.2:latest', 3.2, false), model('minicpm-v4.6:latest', 0.75, true)],
+ { activeModel: 'llama3.2:latest', preferred: 'llama3.2:latest' }
+ );
+ assert.strictEqual(pick.name, 'minicpm-v4.6:latest');
+ });
+
+ it('ignores a setting that names a model which is not installed', () => {
+ const pick = imageRecognition.pickDescriber([model('minicpm-v4.6:latest', 0.75, true)], {
+ activeModel: 'minicpm-v4.6:latest',
+ preferred: 'gemma4:e4b',
+ });
+ assert.strictEqual(pick.name, 'minicpm-v4.6:latest');
+ });
+
+ it('returns null when nothing installed can see', () => {
+ assert.strictEqual(
+ imageRecognition.pickDescriber([model('llama3.2:latest', 3.2, false)], { activeModel: 'llama3.2:latest' }),
+ null
+ );
+ assert.strictEqual(imageRecognition.pickDescriber([], {}), null);
+ assert.strictEqual(imageRecognition.pickDescriber(null, {}), null);
+ });
+ });
+
+ describe('describe', () => {
+ it('sends the image as base64 on the message, which is the shape Ollama wants', async () => {
+ const client = mockClient('A tabby cat.');
+ await imageRecognition.describe({ client, model: 'v', image: { name: 'cat.jpg', base64: IMAGE_A } });
+
+ const body = client.calls[0];
+ assert.deepStrictEqual(body.messages[0].images, [IMAGE_A]);
+ assert.strictEqual(body.messages[0].role, 'user');
+ });
+
+ it('turns thinking off, because a description is not a reasoning task', async () => {
+ // On a hybrid model the trace is not shown, not stored, and spends the token
+ // budget the description itself needs.
+ const client = mockClient('A tabby cat.');
+ await imageRecognition.describe({ client, model: 'v', image: { base64: IMAGE_A } });
+ assert.strictEqual(client.calls[0].think, false);
+ });
+
+ it('caps generation, so a model stuck in a loop stops before the request timeout', async () => {
+ const client = mockClient('A tabby cat.');
+ await imageRecognition.describe({ client, model: 'v', image: { base64: IMAGE_A } });
+ assert.ok(client.calls[0].options.num_predict > 0);
+ assert.ok(client.calls[0].options.temperature > 0, 'not zero: at zero a small model repeats one clause');
+ });
+
+ it('asks for the transcription-first prompt when the purpose is a task', async () => {
+ const client = mockClient('A screenshot.');
+ await imageRecognition.describe({ client, model: 'v', image: { base64: IMAGE_A }, purpose: 'task' });
+ const sent = client.calls[0].messages[0].content;
+ assert.ok(sent.includes('coding agent'), 'the task prompt frames the describer as the agent’s eyes');
+ assert.ok(sent.includes('copied exactly as written'));
+ });
+
+ it('folds the user’s question into the answering prompt', async () => {
+ // Without this, a describer asked "what breed is this?" produces a generic
+ // caption, and the answering model then cannot answer the question either.
+ const client = mockClient('A corgi.');
+ await imageRecognition.describe({
+ client,
+ model: 'v',
+ image: { base64: IMAGE_A },
+ purpose: 'answer',
+ question: 'what breed is this dog?',
+ });
+ assert.ok(client.calls[0].messages[0].content.includes('what breed is this dog?'));
+ });
+
+ it('does not fold the question into a task description', async () => {
+ // A task description is read on every turn of the loop. Steering it with turn
+ // one's wording makes it less useful as the run moves on to the other items.
+ const client = mockClient('A screenshot.');
+ await imageRecognition.describe({
+ client,
+ model: 'v',
+ image: { base64: IMAGE_A },
+ purpose: 'task',
+ question: 'what breed is this dog?',
+ });
+ assert.ok(!client.calls[0].messages[0].content.includes('what breed is this dog?'));
+ });
+
+ it('reuses a description rather than paying for the same picture twice', async () => {
+ const client = mockClient('A tabby cat.');
+ const first = await imageRecognition.describe({ client, model: 'v', image: { base64: IMAGE_A } });
+ const second = await imageRecognition.describe({ client, model: 'v', image: { base64: IMAGE_A } });
+
+ assert.strictEqual(client.calls.length, 1, 'the second call was served from the cache');
+ assert.strictEqual(second.description, first.description);
+ });
+
+ it('treats a different image, model, or purpose as a different question', async () => {
+ const client = mockClient('Something.');
+ await imageRecognition.describe({ client, model: 'v', image: { base64: IMAGE_A } });
+ await imageRecognition.describe({ client, model: 'v', image: { base64: IMAGE_B } });
+ await imageRecognition.describe({ client, model: 'w', image: { base64: IMAGE_A } });
+ await imageRecognition.describe({ client, model: 'v', image: { base64: IMAGE_A }, purpose: 'task' });
+ assert.strictEqual(client.calls.length, 4);
+ });
+
+ it('truncates a describer that ignores the word limit', async () => {
+ const client = mockClient('x'.repeat(imageRecognition.MAX_DESCRIPTION_CHARS * 3));
+ const result = await imageRecognition.describe({ client, model: 'v', image: { base64: IMAGE_A } });
+ assert.ok(result.description.length <= imageRecognition.MAX_DESCRIPTION_CHARS + 1);
+ });
+
+ it('reports a failed call as text rather than throwing', async () => {
+ // The turn continues without the image. Throwing here would lose the whole
+ // message over one unreadable attachment.
+ const client = mockClient(new Error('Ollama is not running'));
+ const result = await imageRecognition.describe({ client, model: 'v', image: { name: 'a.png', base64: IMAGE_A } });
+ assert.strictEqual(result.ok, false);
+ assert.ok(result.description.includes('Ollama is not running'));
+ });
+
+ it('reports an empty reply as a failure, not as an empty description', async () => {
+ const client = mockClient(' ');
+ const result = await imageRecognition.describe({ client, model: 'v', image: { base64: IMAGE_A } });
+ assert.strictEqual(result.ok, false);
+ });
+
+ it('treats "I cannot see this image" as a failed read, not as a description', async () => {
+ // Found by tools/bench-vision.js, once in 24 runs of qwen3.5:0.8b: a model that
+ // reports vision, was sent the image, and had described the same photograph
+ // correctly one sample earlier. Left alone, that paragraph becomes what the
+ // coding model is told is in the picture.
+ const client = mockClient(
+ 'I cannot see this image. I am an AI model designed to process text and provide ' +
+ 'information, but I do not have the ability to view or interpret visual content ' +
+ 'like screenshots, photos, or UI elements.'
+ );
+ const result = await imageRecognition.describe({ client, model: 'v', image: { base64: IMAGE_A } });
+
+ assert.strictEqual(result.ok, false);
+ assert.ok(result.description.includes('Sending the message again'), 'says what to do about it');
+ assert.ok(!result.description.includes('designed to process text'), 'the refusal itself is not passed on');
+ });
+
+ it('does not mistake an honest hedge for a refusal', async () => {
+ // The prompt asks the describer to say when it cannot make something out, so
+ // "I cannot see the licence plate clearly" is the check working, not failing.
+ // A detector that ate those would punish exactly the behaviour we want.
+ const client = mockClient('A yellow car on a road. I cannot see the licence plate clearly, so it is unreadable.');
+ const result = await imageRecognition.describe({ client, model: 'v', image: { base64: IMAGE_A } });
+ assert.strictEqual(result.ok, true);
+ });
+
+ it('keeps a real description that ends with a boilerplate disclaimer', async () => {
+ const client = mockClient(
+ `${'A tabby kitten lying on a green surface, facing the camera. '.repeat(8)} ` +
+ 'As an AI I cannot view images.'
+ );
+ const result = await imageRecognition.describe({ client, model: 'v', image: { base64: IMAGE_A } });
+ assert.strictEqual(result.ok, true, 'only the opening 400 characters are examined');
+ });
+
+ it('does not cache a failure', async () => {
+ // Otherwise one timeout poisons the image for the rest of the session.
+ const failing = mockClient(new Error('timed out'));
+ await imageRecognition.describe({ client: failing, model: 'v', image: { base64: IMAGE_A } });
+ const working = mockClient('A tabby cat.');
+ const second = await imageRecognition.describe({ client: working, model: 'v', image: { base64: IMAGE_A } });
+ assert.strictEqual(second.ok, true);
+ assert.strictEqual(working.calls.length, 1);
+ });
+ });
+
+ describe('describeAll', () => {
+ it('describes in sequence and reports progress per image', async () => {
+ const client = mockClient('Something.');
+ /** @type {object[]} */
+ const progress = [];
+ const out = await imageRecognition.describeAll({
+ client,
+ model: 'v',
+ images: [
+ { name: 'a.png', base64: IMAGE_A },
+ { name: 'b.png', base64: IMAGE_B },
+ ],
+ onProgress: (p) => progress.push(p),
+ });
+
+ assert.strictEqual(out.length, 2);
+ assert.deepStrictEqual(
+ progress.map((p) => `${p.index}/${p.total} ${p.name}`),
+ ['1/2 a.png', '2/2 b.png']
+ );
+ });
+
+ it('returns nothing for no images, without calling the model', async () => {
+ const client = mockClient('Something.');
+ assert.deepStrictEqual(await imageRecognition.describeAll({ client, model: 'v', images: [] }), []);
+ assert.strictEqual(client.calls.length, 0);
+ });
+ });
+
+ describe('renderForPrompt', () => {
+ it('says the model is not looking at the picture', async () => {
+ // Without this, a model handed a description replies "I can see the error in your
+ // screenshot" and then offers to look at it more closely, which it cannot do.
+ const block = imageRecognition.renderForPrompt([
+ { name: 'shot.png', description: 'A login form with a red error.', ok: true },
+ ]);
+ assert.ok(block.includes('not looking at'));
+ assert.ok(block.includes('do not offer to look'));
+ assert.ok(block.includes('shot.png'));
+ assert.ok(block.includes('A login form with a red error.'));
+ });
+
+ it('names each image when there is more than one', () => {
+ const block = imageRecognition.renderForPrompt([
+ { name: 'one.png', description: 'First.', ok: true },
+ { name: 'two.png', description: 'Second.', ok: true },
+ ]);
+ assert.ok(block.includes('2 images'));
+ assert.ok(block.includes('one.png'));
+ assert.ok(block.includes('two.png'));
+ });
+
+ it('renders nothing at all when there is nothing to say', () => {
+ // The caller uses the empty string to skip the section entirely, so a block of
+ // boilerplate with no content in it would cost budget for nothing.
+ assert.strictEqual(imageRecognition.renderForPrompt([]), '');
+ assert.strictEqual(imageRecognition.renderForPrompt(null), '');
+ assert.strictEqual(imageRecognition.renderForPrompt([{ name: 'a.png', description: '' }]), '');
+ });
+ });
+});
diff --git a/test/unit/imageTurns.test.js b/test/unit/imageTurns.test.js
new file mode 100644
index 0000000..eafa174
--- /dev/null
+++ b/test/unit/imageTurns.test.js
@@ -0,0 +1,454 @@
+'use strict';
+
+/**
+ * What happens to an attached image once a turn starts.
+ *
+ * `imageRecognition.test.js` covers the describer in isolation. This covers the wiring
+ * decisions in `AgentSession` that the module cannot see: which turns get the raw
+ * picture, which get the words, and which get both. Those decisions are the whole
+ * feature — the describer being correct is worth nothing if its output never reaches
+ * the model that answers.
+ */
+
+const assert = require('assert');
+const fs = require('fs');
+const os = require('os');
+const path = require('path');
+
+const { AgentSession } = require('../../app/agent/agentSession');
+const { PermissionGate } = require('../../app/security/permissionGate');
+const { PermissionModes } = require('../../app/security/permissionModes');
+const { AuditLog } = require('../../app/security/auditLog');
+const imageRecognition = require('../../app/core/imageRecognition');
+
+const TIER_B = { tier: 'B', strategy: 'react', label: 'Lite', model: 'llama3.2:1b' };
+const PICTURE = Buffer.from('not-really-a-jpeg').toString('base64');
+
+/**
+ * A client that answers the describer and the main turn differently.
+ *
+ * The two are told apart by the images on the message, which is exactly how the real
+ * request differs: a description call carries the base64 and nothing else does.
+ */
+function twoStageClient(mainReplies) {
+ return {
+ /** @type {any[]} */ bodies: [],
+ /** @type {any[]} */ describeCalls: [],
+ /** @type {any[]} */ mainCalls: [],
+ async chat(body) {
+ this.bodies.push(body);
+ const first = body.messages[0] || {};
+ const isDescribe =
+ Array.isArray(first.images) && first.images.length > 0 && String(first.content || '').includes('image');
+
+ if (isDescribe) {
+ this.describeCalls.push(body);
+ return { message: { content: 'A screenshot of a login form with a red error reading "Invalid password".' } };
+ }
+ this.mainCalls.push(body);
+ const reply = mainReplies[Math.min(this.mainCalls.length - 1, mainReplies.length - 1)];
+ return { message: { content: reply } };
+ },
+ };
+}
+
+/** Every message body that went out, flattened to searchable text. */
+const allText = (client) => JSON.stringify(client.bodies);
+
+describe('images in a turn', () => {
+ /** @type {string} */
+ let root;
+
+ beforeEach(() => {
+ imageRecognition._clearCache();
+ root = fs.realpathSync(fs.mkdtempSync(path.join(os.tmpdir(), 'hiraya-imgturn-')));
+ fs.writeFileSync(path.join(root, 'README.md'), '# Test project\n');
+ });
+
+ afterEach(() => fs.rmSync(root, { recursive: true, force: true, maxRetries: 3, retryDelay: 100 }));
+
+ /**
+ * @param {object} opts
+ */
+ function makeSession(opts) {
+ const modes = new PermissionModes({ initial: { autoEdit: true, autoApproveScripts: false } });
+ return new AgentSession({
+ client: /** @type {any} */ (opts.client),
+ model: opts.model || 'llama3.2:latest',
+ capability: TIER_B,
+ gate: new PermissionGate({
+ workspaceRoot: root,
+ modes,
+ auditLog: new AuditLog(root),
+ confirm: async () => true,
+ }),
+ workspaceRoot: root,
+ thinkingCapacity: 'medium',
+ sessionId: '1',
+ images: [PICTURE],
+ imageFiles: [{ name: 'shot.png', base64: PICTURE }],
+ vision: opts.vision,
+ });
+ }
+
+ describe('Ask mode', () => {
+ it('sends the picture straight to a model that can see, with no description pass', async () => {
+ // A description here would be a second full generation — a minute or more on CPU —
+ // to produce a paraphrase strictly worse than the original, for the one model
+ // that was going to look at the original anyway.
+ const client = twoStageClient(['That error means the password was wrong.']);
+ const session = makeSession({
+ client,
+ model: 'qwen3.5:4b',
+ vision: { enabled: true, describeModel: 'qwen3.5:4b', activeCanSee: true },
+ });
+
+ await session.run('what does this error say?', { mode: 'ask' });
+
+ assert.strictEqual(client.describeCalls.length, 0, 'no separate recognition call');
+ assert.strictEqual(client.mainCalls.length, 1);
+ assert.deepStrictEqual(client.mainCalls[0].messages[1].images, [PICTURE]);
+ });
+
+ it('describes first when the selected model is blind, and answers from the words', async () => {
+ // The capability this release adds: a screenshot is usable on llama3.2, which has
+ // no vision at all, without the user having to switch models.
+ const client = twoStageClient(['The error says the password was wrong.']);
+ const session = makeSession({
+ client,
+ model: 'llama3.2:latest',
+ vision: { enabled: true, describeModel: 'minicpm-v4.6:latest', activeCanSee: false },
+ });
+
+ const result = await session.run('what does this error say?', { mode: 'ask' });
+
+ assert.strictEqual(client.describeCalls.length, 1);
+ assert.strictEqual(client.describeCalls[0].model, 'minicpm-v4.6:latest', 'described by the vision model');
+ assert.strictEqual(client.mainCalls[0].model, 'llama3.2:latest', 'answered by the selected model');
+ assert.ok(client.mainCalls[0].messages[1].content.includes('Invalid password'), 'the words reached the answer');
+ assert.strictEqual(result.stopReason, 'answered');
+ });
+
+ it('never puts the raw picture on a message to a model that cannot see it', async () => {
+ // Not an API error — Ollama drops it silently, after the upload. The only effect
+ // is a slower turn, which is exactly the kind of waste that goes unnoticed.
+ const client = twoStageClient(['An answer.']);
+ const session = makeSession({
+ client,
+ model: 'llama3.2:latest',
+ vision: { enabled: true, describeModel: 'minicpm-v4.6:latest', activeCanSee: false },
+ });
+
+ await session.run('what is this?', { mode: 'ask' });
+
+ for (const body of client.mainCalls) {
+ for (const message of body.messages) {
+ assert.ok(!message.images, 'no images on any message to the blind model');
+ }
+ }
+ });
+
+ it('carries the user’s question into the recognition prompt', async () => {
+ const client = twoStageClient(['An answer.']);
+ const session = makeSession({
+ client,
+ model: 'llama3.2:latest',
+ vision: { enabled: true, describeModel: 'minicpm-v4.6:latest', activeCanSee: false },
+ });
+
+ await session.run('which field is highlighted?', { mode: 'ask' });
+
+ assert.ok(client.describeCalls[0].messages[0].content.includes('which field is highlighted?'));
+ });
+ });
+
+ describe('Agent mode', () => {
+ it('describes with the task prompt, not the conversational one', async () => {
+ // Agent mode acts on what it is told, so transcription outranks description. The
+ // two prompts differ on exactly that.
+ const client = twoStageClient(['{"action":"done","summary":"Looked at it."}']);
+ const session = makeSession({
+ client,
+ model: 'qwen3.5:4b',
+ vision: { enabled: true, describeModel: 'qwen3.5:4b', activeCanSee: true },
+ });
+
+ await session.run('fix the error shown in this screenshot', { mode: 'agent' });
+
+ assert.strictEqual(client.describeCalls.length, 1);
+ assert.ok(client.describeCalls[0].messages[0].content.includes('coding agent'));
+ });
+
+ it('describes even when the selected model can see, because the loop outlives the picture', async () => {
+ // Images ride on the first message only. By turn four the model is working from a
+ // conversation about a picture it can no longer see; the description is what
+ // carries across.
+ const client = twoStageClient(['{"action":"done","summary":"Done."}']);
+ const session = makeSession({
+ client,
+ model: 'qwen3.5:4b',
+ vision: { enabled: true, describeModel: 'qwen3.5:4b', activeCanSee: true },
+ });
+
+ await session.run('build what this mockup shows', { mode: 'agent' });
+
+ assert.strictEqual(client.describeCalls.length, 1);
+ assert.ok(allText(client).includes('Invalid password'), 'the description reached the loop');
+ });
+
+ it('puts the description in the context of the turn, not only in the first message', async () => {
+ const client = twoStageClient(['{"action":"done","summary":"Done."}']);
+ const session = makeSession({
+ client,
+ model: 'llama3.2:latest',
+ vision: { enabled: true, describeModel: 'minicpm-v4.6:latest', activeCanSee: false },
+ });
+
+ await session.run('implement the form in this mockup', { mode: 'agent' });
+
+ const context = JSON.stringify(client.mainCalls[0].messages);
+ assert.ok(context.includes('shot.png'), 'the image is named');
+ assert.ok(context.includes('Invalid password'), 'and what was in it is carried');
+ assert.ok(context.includes('not looking at'), 'and the model is told it is reading a description');
+ });
+ });
+
+ describe('the project must not drown the picture', () => {
+ // The bug this covers, measured on minicpm-v4.6 in Ask mode: "describe the image"
+ // with a photograph of a dog attached returned a description of HirayaCoder. Not a
+ // vision failure — the same model and photograph score 24/24 in bench-vision. The
+ // model was handed 2,500 characters of project description and file listing with
+ // "Task: describe the image" on the last line, under a system prompt opening with
+ // "everything below this line is what you know about the user's project… Answer
+ // from it". A small model resolves that conflict by weight.
+
+ it('leaves the project overview and file listing out of a no-tools image turn', async () => {
+ const client = twoStageClient(['A corgi in grass.']);
+ const session = makeSession({
+ client,
+ model: 'qwen3.5:4b',
+ vision: { enabled: true, describeModel: 'qwen3.5:4b', activeCanSee: true },
+ });
+
+ await session.run('describe the image', { mode: 'ask' });
+
+ const userTurn = client.mainCalls[0].messages[1].content;
+ assert.ok(!userTurn.includes('Files in this project'), 'no file listing');
+ assert.ok(!userTurn.includes("project's own description of itself"), 'no project overview');
+ assert.ok(userTurn.includes('describe the image'), 'the task still gets there');
+ });
+
+ it('tells the model the question is about the image', async () => {
+ const client = twoStageClient(['A corgi in grass.']);
+ const session = makeSession({
+ client,
+ model: 'qwen3.5:4b',
+ vision: { enabled: true, describeModel: 'qwen3.5:4b', activeCanSee: true },
+ });
+
+ await session.run('describe the image', { mode: 'ask' });
+
+ const system = client.mainCalls[0].messages[0].content;
+ assert.ok(system.includes('attached an image'), 'the instruction is present');
+ assert.ok(system.includes('Answer about the image'));
+ });
+
+ it('says nothing about images on a turn that has none', async () => {
+ const client = twoStageClient(['An answer.']);
+ const modes = new PermissionModes({ initial: { autoEdit: true, autoApproveScripts: false } });
+ const session = new AgentSession({
+ client: /** @type {any} */ (client),
+ model: 'qwen3.5:4b',
+ capability: TIER_B,
+ gate: new PermissionGate({
+ workspaceRoot: root,
+ modes,
+ auditLog: new AuditLog(root),
+ confirm: async () => true,
+ }),
+ workspaceRoot: root,
+ sessionId: '1',
+ });
+
+ await session.run('what is this project?', { mode: 'ask' });
+
+ const system = client.mainCalls[0].messages[0].content;
+ assert.ok(!system.includes('attached an image'));
+ // And the orientation blocks it needs are still there, which is the thing the
+ // suppression above must not break for ordinary questions.
+ assert.ok(client.mainCalls[0].messages[1].content.includes('Files in this project'));
+ });
+
+ it('keeps the file listing in Agent mode, where it is load-bearing', async () => {
+ // A model asked to build the screen in a mockup needs to know which paths exist.
+ // There the picture is not competing with the project, it is a fact about the job.
+ const client = twoStageClient(['{"action":"done","summary":"Done."}']);
+ const session = makeSession({
+ client,
+ model: 'qwen3.5:4b',
+ vision: { enabled: true, describeModel: 'qwen3.5:4b', activeCanSee: true },
+ });
+
+ await session.run('build the screen in this mockup', { mode: 'agent' });
+
+ assert.ok(allText(client).includes('Files in this project'), 'the listing survives in Agent mode');
+ });
+ });
+
+ describe('what the reply footer is told', () => {
+ it('names the model that answered and how long the turn took', async () => {
+ const client = twoStageClient(['A corgi in grass.']);
+ const session = makeSession({
+ client,
+ model: 'qwen3.5:4b',
+ vision: { enabled: true, describeModel: 'qwen3.5:4b', activeCanSee: true },
+ });
+
+ const result = await session.run('describe the image', { mode: 'ask' });
+
+ assert.strictEqual(result.model, 'qwen3.5:4b');
+ assert.strictEqual(typeof result.ms, 'number');
+ assert.ok(result.ms >= 0);
+ });
+
+ it('accounts for a second model separately when one read the image', async () => {
+ // Without this the headline duration silently includes another model's load and
+ // inference, and the coding model looks like it got slower.
+ const client = twoStageClient(['A corgi in grass.']);
+ const session = makeSession({
+ client,
+ model: 'llama3.2:latest',
+ vision: { enabled: true, describeModel: 'minicpm-v4.6:latest', activeCanSee: false },
+ });
+
+ const result = await session.run('describe the image', { mode: 'ask' });
+
+ assert.strictEqual(result.model, 'llama3.2:latest');
+ assert.ok(result.vision, 'the describer is reported');
+ assert.strictEqual(result.vision.model, 'minicpm-v4.6:latest');
+ assert.strictEqual(typeof result.vision.ms, 'number');
+ });
+
+ it('reports no second model when the selected one described its own image', async () => {
+ // Naming it twice would read as though there were two costs.
+ const client = twoStageClient(['{"action":"done","summary":"Done."}']);
+ const session = makeSession({
+ client,
+ model: 'qwen3.5:4b',
+ vision: { enabled: true, describeModel: 'qwen3.5:4b', activeCanSee: true },
+ });
+
+ const result = await session.run('build what this mockup shows', { mode: 'agent' });
+
+ assert.strictEqual(result.vision, undefined);
+ assert.strictEqual(result.model, 'qwen3.5:4b');
+ });
+ });
+
+ describe('secrets visible in the picture', () => {
+ it('redacts a credential the describer read off the screenshot', async () => {
+ // Not a hypothetical, and not merely permitted: the recognition prompt asks the
+ // describer to copy visible text exactly, so a screenshot of a terminal with an
+ // exported key in it produces a description containing the key. That description
+ // then goes into the prompt like any other context block, and every other context
+ // block is redacted.
+ const key = `sk-proj-${'AbCdEf0123456789'.repeat(2)}`;
+ const client = {
+ /** @type {any[]} */ bodies: [],
+ async chat(body) {
+ this.bodies.push(body);
+ const first = body.messages[0] || {};
+ if (Array.isArray(first.images) && first.images.length > 0) {
+ return { message: { content: `A terminal. The visible text reads: export OPENAI_API_KEY=${key}` } };
+ }
+ return { message: { content: 'An answer.' } };
+ },
+ };
+
+ const session = makeSession({
+ client,
+ model: 'llama3.2:latest',
+ vision: { enabled: true, describeModel: 'minicpm-v4.6:latest', activeCanSee: false },
+ });
+
+ await session.run('what is on this screen?', { mode: 'ask' });
+
+ const answering = client.bodies.filter((b) => !(b.messages[0].images || []).length);
+ const sent = JSON.stringify(answering);
+ assert.ok(!sent.includes(key), 'the key must not reach the answering model');
+ assert.ok(sent.includes('REDACTED'), 'and it is replaced rather than dropped');
+ assert.ok(sent.includes('The visible text reads'), 'the sentence around it survives');
+ });
+ });
+
+ describe('when it is switched off or unavailable', () => {
+ it('reads nothing when vision is disabled in settings', async () => {
+ const client = twoStageClient(['An answer.']);
+ const session = makeSession({
+ client,
+ model: 'llama3.2:latest',
+ vision: { enabled: false, describeModel: 'minicpm-v4.6:latest', activeCanSee: false },
+ });
+
+ await session.run('what is this?', { mode: 'ask' });
+
+ assert.strictEqual(client.describeCalls.length, 0);
+ });
+
+ it('answers anyway when no model can see, rather than failing the turn', async () => {
+ // Losing the whole message over an unreadable attachment would be worse than an
+ // answer that does not mention the picture.
+ const client = twoStageClient(['An answer.']);
+ const session = makeSession({
+ client,
+ model: 'llama3.2:latest',
+ vision: { enabled: true, describeModel: null, activeCanSee: false },
+ });
+
+ const result = await session.run('what is this?', { mode: 'ask' });
+
+ assert.strictEqual(client.describeCalls.length, 0);
+ assert.strictEqual(result.summary, 'An answer.');
+ });
+
+ it('keeps the pre-1.1.0 behaviour when no vision config is supplied at all', async () => {
+ // Every caller before this release had already refused to attach an image to a
+ // model that could not see it, so an absent config means "the picture is fine to
+ // send".
+ const client = twoStageClient(['An answer.']);
+ const session = makeSession({ client, model: 'qwen3.5:4b', vision: undefined });
+
+ await session.run('what is this?', { mode: 'ask' });
+
+ assert.strictEqual(client.describeCalls.length, 0, 'no recognition pass without config');
+ assert.deepStrictEqual(client.mainCalls[0].messages[1].images, [PICTURE]);
+ });
+ });
+
+ describe('no images attached', () => {
+ it('changes nothing about an ordinary turn', async () => {
+ const client = twoStageClient(['An answer.']);
+ const modes = new PermissionModes({ initial: { autoEdit: true, autoApproveScripts: false } });
+ const session = new AgentSession({
+ client: /** @type {any} */ (client),
+ model: 'llama3.2:latest',
+ capability: TIER_B,
+ gate: new PermissionGate({
+ workspaceRoot: root,
+ modes,
+ auditLog: new AuditLog(root),
+ confirm: async () => true,
+ }),
+ workspaceRoot: root,
+ sessionId: '1',
+ vision: { enabled: true, describeModel: 'minicpm-v4.6:latest', activeCanSee: false },
+ });
+
+ await session.run('what does this project do?', { mode: 'ask' });
+
+ assert.strictEqual(client.describeCalls.length, 0);
+ assert.strictEqual(client.mainCalls.length, 1);
+ assert.ok(!allText(client).includes('not looking at'));
+ });
+ });
+});
diff --git a/test/unit/runScriptTool.test.js b/test/unit/runScriptTool.test.js
index c1a90fb..819341a 100644
--- a/test/unit/runScriptTool.test.js
+++ b/test/unit/runScriptTool.test.js
@@ -426,17 +426,25 @@ describe('what the model is told about a run', () => {
describe('the allow-list', () => {
const { DEFAULT_ALLOWED_BINARIES } = require('../../app/security/scriptRunner');
- it('is documented in full, so the README cannot drift out of date', () => {
- // The README's Requirements section tells users which toolchains to install for
- // `run_script` to be able to do anything. A binary added here and not there is a
- // capability nobody knows they have; one removed here and left there is advice to
- // install something that will still be refused.
+ it('is documented in full, so the docs cannot drift out of date', () => {
+ // Users are told which toolchains to install for `run_script` to be able to do
+ // anything. A binary added here and not there is a capability nobody knows they
+ // have; one removed here and left there is advice to install something that will
+ // still be refused.
+ //
+ // The list moved out of the README and into TROUBLESHOOTING.md in 1.1.0, when the
+ // README was cut down to the things a first-time reader needs. Both files are read
+ // here rather than only the new one: the table is free to move again, and a test
+ // that pins its location would fail the next time it does, for no security reason.
const fs = require('fs');
const path = require('path');
- const readme = fs.readFileSync(path.join(__dirname, '..', '..', 'README.md'), 'utf8');
+ const root = path.join(__dirname, '..', '..');
+ const documented = ['README.md', path.join('doc', 'TROUBLESHOOTING.md')]
+ .map((file) => fs.readFileSync(path.join(root, file), 'utf8'))
+ .join('\n');
- const undocumented = DEFAULT_ALLOWED_BINARIES.filter((binary) => !readme.includes(`\`${binary}\``));
- assert.deepStrictEqual(undocumented, [], `not listed in README.md: ${undocumented.join(', ')}`);
+ const undocumented = DEFAULT_ALLOWED_BINARIES.filter((binary) => !documented.includes(`\`${binary}\``));
+ assert.deepStrictEqual(undocumented, [], `not listed in README.md or doc/TROUBLESHOOTING.md: ${undocumented.join(', ')}`);
});
it('permits the plain Java toolchain, since it already permits Maven and Gradle', () => {
diff --git a/test/unit/webviewComponents.test.js b/test/unit/webviewComponents.test.js
index ec6b311..10b570d 100644
--- a/test/unit/webviewComponents.test.js
+++ b/test/unit/webviewComponents.test.js
@@ -459,3 +459,33 @@ describe('the setup guide card', () => {
for (const mode of ['Agent', 'Plan', 'Ask']) assert.match(text, new RegExp(mode));
});
});
+
+describe('the reply footer', () => {
+ /** @type {(ms: number) => string} */
+ let seconds;
+
+ before(async () => {
+ // eslint-disable-next-line no-unsanitized/method
+ ({ seconds } = await import(moduleUrl('components/messageBubble.js')));
+ });
+
+ it('reads a sub-second turn as a fraction, never as 0s', () => {
+ // A cached image description comes back in a few hundred milliseconds. "0s" reads
+ // as a broken timer rather than as a fast answer.
+ assert.strictEqual(seconds(120), '0.1s');
+ assert.strictEqual(seconds(940), '0.9s');
+ });
+
+ it('rounds to whole seconds once there is a whole second to round', () => {
+ assert.strictEqual(seconds(950), '1s');
+ assert.strictEqual(seconds(2242), '2s');
+ assert.strictEqual(seconds(17264), '17s');
+ });
+
+ it('breaks a long turn into minutes, which is how anyone reads it', () => {
+ // A task on a CPU-only laptop routinely passes a minute, and "312s" is a number
+ // nobody converts in their head.
+ assert.strictEqual(seconds(60000), '1m 0s');
+ assert.strictEqual(seconds(312000), '5m 12s');
+ });
+});
diff --git a/tools/bench-vision.js b/tools/bench-vision.js
new file mode 100644
index 0000000..c6ee943
--- /dev/null
+++ b/tools/bench-vision.js
@@ -0,0 +1,506 @@
+'use strict';
+
+/* eslint-disable security/detect-non-literal-fs-filename --
+ * A developer benchmark script. Every path it touches is either the fixture directory
+ * shipped in this repo or the results directory named on the command line, and the only
+ * computed keys are fixture ids and axis names defined in this file. */
+
+/**
+ * The image-recognition benchmark.
+ *
+ * `bench-build.js` asks whether a model can build a project. This asks the much smaller
+ * question underneath 1.1.0's image feature: **when a user attaches a photo, does the
+ * model actually see what is in it?**
+ *
+ * It matters more than it sounds. A vision model that cannot see does not error — it
+ * writes a fluent, confident paragraph about something else, and because that paragraph
+ * then becomes the *only* thing the coding model is told about the picture (see
+ * `core/imageRecognition`), a misread propagates silently into the answer. So the point
+ * of this harness is to catch a describer that is wrong while sounding right.
+ *
+ * ## Nothing is graded on fluency
+ *
+ * Every fixture below carries a hand-written expectation of what is actually in the
+ * photograph, and the description is graded against that and nothing else. Three axes,
+ * scored separately because they fail separately:
+ *
+ * 1. **subject** — did it name the right thing? Any accepted synonym counts.
+ * 2. **detail** — did it get the supporting facts: the colour, the setting, the count?
+ * 3. **text** — did it read the words that are visibly in the image?
+ *
+ * And one that can only be lost:
+ *
+ * 4. **confusion** — did it assert something the picture contradicts? A cat described
+ * as a dog fails here even if it scored on everything else, and this is the axis
+ * that separates "vague" from "wrong". Vague is usable; wrong is worse than
+ * nothing, because the user cannot tell.
+ *
+ * Keyword matching is crude and deliberately so. The alternative is grading one local
+ * model's output with another local model, which makes the benchmark's own reliability
+ * the thing in question. A word list cannot be talked into a false positive.
+ *
+ * ## Why the timings need `--cold` to mean anything
+ *
+ * Ollama caches the tokenized prompt, and for these requests the prompt is mostly the
+ * image. So the second sample of the same picture comes back in about a second where
+ * the first took fifteen, and the cache survives between *runs* as well — re-running
+ * this harness half an hour later reported one second for everything, for a model that
+ * genuinely takes fifteen.
+ *
+ * A benchmark that publishes that number publishes something nobody can reproduce. So
+ * timings are reported in two columns, `cold` and `warm`, and `--cold` unloads the
+ * model between samples to make the cold column honest. Without the flag, treat the
+ * cold column as a lower bound and nothing more.
+ *
+ * None of this touches the accuracy scores. A cached answer is the same answer.
+ *
+ * ## Results are one file per run
+ *
+ * benchmarks/results//vision____.json
+ *
+ * Same convention as every other harness here, and for the same reason: machines A, B
+ * and C write into their own directories, so three people can run this at once and
+ * merge with no conflict. See `benchmarks/README.md`.
+ *
+ * ## Usage
+ *
+ * node tools/bench-vision.js --machine [options]
+ *
+ * node tools/bench-vision.js minicpm-v4.6:latest --machine B
+ * node tools/bench-vision.js qwen3.5:0.8b --machine B --purpose task
+ * node tools/bench-vision.js qwen3.5:2b --machine A --images cat,dog --repeat 2
+ *
+ * --machine Required. Which machine this is; picks the results directory.
+ * --purpose
answer (default), task, or both. The two prompts in
+ * `core/imageRecognition`; they are graded identically.
+ * --images Fixture ids, comma separated. Default: all of them.
+ * --repeat Runs per image, default 1. Small vision models are not stable
+ * across samples, and one run cannot tell luck from capability.
+ * --cold Unload the model before every sample, so the timings are what a
+ * user actually waits. Much slower. See the note on caching below.
+ * --notes "..." Free text stored in the record — put the `ollama ps` split here.
+ * --out Results root, default benchmarks/results.
+ */
+
+const fs = require('fs');
+const path = require('path');
+
+const appRoot = path.join(__dirname, '..', 'app');
+const { createClient } = require(path.join(appRoot, 'core', 'ollamaClient'));
+const imageRecognition = require(path.join(appRoot, 'core', 'imageRecognition'));
+const { readImage } = require(path.join(appRoot, 'features', 'imageContext'));
+const { parseArgs } = require('./lib/args');
+
+/** Where the fixture photographs live. */
+const IMAGE_DIR = path.join(__dirname, '..', 'docs', 'test-images');
+
+/**
+ * What is actually in each photograph.
+ *
+ * Written by looking at them, not by reading their filenames — `dog-1.jpg` is a corgi
+ * and `dog.jpg` is two retriever puppies, and a benchmark that graded both against
+ * "dog" would miss a describer that cannot count or cannot tell a breed from a species.
+ *
+ * `subject` and `detail` groups are OR within a group and AND across groups: one word
+ * from each group has to appear. That shape is what lets "puppy" count for "dog"
+ * without letting "animal" count for everything.
+ *
+ * `confusers` are words whose presence is a factual error about this specific image.
+ * They are chosen narrowly. "Bird" is a confuser for the aeroplane because a model that
+ * says bird has misclassified it; "sky" is not, because the aeroplane is in the sky.
+ */
+const FIXTURES = [
+ {
+ id: 'cat',
+ file: 'cat.jpg',
+ what: 'A tabby kitten lying down, head on a green surface, facing the camera.',
+ subject: [['cat', 'kitten', 'feline']],
+ detail: [
+ ['tabby', 'stripe', 'striped', 'grey', 'gray', 'brown'],
+ ['lying', 'laying', 'resting', 'rest', 'lies', 'down', 'green'],
+ ],
+ text: [],
+ confusers: ['dog', 'puppy', 'rabbit', 'fox'],
+ },
+ {
+ id: 'dog',
+ file: 'dog.jpg',
+ what: 'Two golden retriever puppies sitting in grass strewn with orange petals.',
+ subject: [['dog', 'puppy', 'puppies', 'retriever']],
+ detail: [
+ ['two', 'pair', 'both', 'couple'],
+ ['grass', 'field', 'lawn', 'meadow', 'flower', 'petal', 'orange'],
+ ],
+ text: [],
+ confusers: ['cat', 'kitten'],
+ },
+ {
+ id: 'dog-1',
+ file: 'dog-1.jpg',
+ what: 'A single corgi lying in sunlit grass, wearing a green collar.',
+ subject: [['dog', 'corgi', 'puppy']],
+ detail: [
+ ['grass', 'field', 'lawn', 'meadow', 'outdoor'],
+ ['collar', 'white', 'orange', 'tan', 'brown', 'ears'],
+ ],
+ text: [],
+ // Not 'cat' alone here: this one is a corgi, and calling it a generic dog is
+ // imprecise rather than wrong. Only a different species counts as confusion.
+ confusers: ['cat', 'kitten', 'fox cub'],
+ },
+ {
+ id: 'car',
+ file: 'car.jpg',
+ what: 'A yellow BMW M4 coupe on a road, panning shot, bare trees behind.',
+ subject: [['car', 'coupe', 'vehicle', 'sedan', 'automobile', 'bmw']],
+ detail: [
+ ['yellow', 'gold', 'golden', 'lime'],
+ ['road', 'highway', 'street', 'motion', 'driving', 'speed', 'blur'],
+ ],
+ // The badge is legible. A describer that reads it is doing real work; one that does
+ // not has still described the picture correctly, so this axis is scored apart.
+ text: ['bmw'],
+ confusers: ['truck', 'motorcycle', 'bus', 'bicycle'],
+ },
+ {
+ id: 'plane',
+ file: 'plane.jpg',
+ what: 'A Cebu Pacific Airbus A320 on approach, gear down, against grey sky.',
+ subject: [['plane', 'airplane', 'aeroplane', 'aircraft', 'jet', 'airliner', 'airbus']],
+ detail: [
+ ['yellow', 'white', 'blue', 'green', 'teal'],
+ ['sky', 'flying', 'flight', 'landing', 'air', 'gear', 'wheels'],
+ ],
+ // The largest text in the frame, in a clear typeface. This is the fixture that
+ // separates a describer that reads from one that only classifies.
+ text: ['cebu'],
+ confusers: ['helicopter', 'bird', 'rocket', 'boat'],
+ },
+ {
+ id: 'tree',
+ file: 'tree.jpg',
+ what: 'One large green tree alone in a grassy field at sunset, blue sky above.',
+ subject: [['tree', 'oak']],
+ detail: [
+ ['field', 'grass', 'meadow', 'grassland'],
+ ['sky', 'sunset', 'sunrise', 'blue', 'green', 'sun'],
+ ],
+ text: [],
+ confusers: ['forest', 'city', 'building', 'people'],
+ },
+];
+
+/**
+ * Does the description contain any word from this group?
+ *
+ * Word-boundary matched rather than substring: `'car'` must not be satisfied by
+ * "carpet", and `'jet'` must not be satisfied by "jetty". This was not a hypothetical —
+ * the first draft matched plain `includes` and scored a description of a cat on a
+ * *carpet* as having identified a car.
+ *
+ * @param {string} haystack Lowercased description.
+ * @param {string[]} group
+ * @returns {string | null} The word that matched, for the record.
+ */
+function matchAny(haystack, group) {
+ for (const word of group) {
+ // Built from the fixture word lists in this file, escaped, and never from model
+ // output or user input.
+ // eslint-disable-next-line security/detect-non-literal-regexp
+ const pattern = new RegExp(`\\b${word.replace(/[.*+?^${}()|[\]\\]/g, '\\$&')}(?:s|es)?\\b`, 'i');
+ if (pattern.test(haystack)) return word;
+ }
+ return null;
+}
+
+/**
+ * Grade one description against one fixture.
+ *
+ * @param {typeof FIXTURES[0]} fixture
+ * @param {string} description
+ */
+function grade(fixture, description) {
+ const text = String(description || '').toLowerCase();
+
+ const subjectHits = fixture.subject.map((group) => matchAny(text, group));
+ const detailHits = fixture.detail.map((group) => matchAny(text, group));
+ const textHits = fixture.text.map((word) => matchAny(text, [word]));
+ const confused = fixture.confusers.filter((word) => matchAny(text, [word]));
+
+ const subject = subjectHits.every(Boolean);
+ const detail = detailHits.filter(Boolean).length;
+ const detailTotal = fixture.detail.length;
+ const readText = fixture.text.length === 0 ? null : textHits.every(Boolean);
+
+ return {
+ // The headline. A description that names the wrong animal is not partially right,
+ // whatever else it got, so a confusion sinks the whole fixture rather than
+ // subtracting from it.
+ passed: subject && confused.length === 0,
+ subject,
+ subjectMatched: subjectHits.filter(Boolean),
+ detail,
+ detailTotal,
+ detailMatched: detailHits.filter(Boolean),
+ // Null means this image has no text in it, which is different from failing to read
+ // text that is there. Averaging those together would punish a describer for the
+ // fixtures rather than for its own performance.
+ readText,
+ textMatched: textHits.filter(Boolean),
+ confused,
+ };
+}
+
+/**
+ * Evict the model from memory, so the next call pays the real cost.
+ *
+ * `keep_alive: 0` on a generate call with no prompt is Ollama's own way of saying
+ * "unload this now", and it is what `ollama stop` does underneath. Going through the
+ * HTTP client rather than spawning the CLI keeps this harness free of `child_process`
+ * and inside the same loopback-only path as everything else the project talks to.
+ *
+ * A failure is logged and ignored. An un-evicted model produces an optimistic timing,
+ * which is worth far less than losing the run over.
+ *
+ * @param {import('../app/core/ollamaClient').OllamaClient} client
+ * @param {string} model
+ */
+async function unload(client, model) {
+ try {
+ await client.generate({ model, prompt: '', keep_alive: 0 });
+ } catch (err) {
+ console.log(` (could not unload ${model}: ${/** @type {Error} */ (err).message}; timing will be optimistic)`);
+ }
+}
+
+/**
+ * @param {string} model
+ * @param {string} purpose
+ * @param {typeof FIXTURES} fixtures
+ * @param {number} repeat
+ * @param {import('../app/core/ollamaClient').OllamaClient} client
+ */
+async function runPurpose(client, model, purpose, fixtures, repeat, cold) {
+ /** @type {object[]} */
+ const results = [];
+
+ for (const fixture of fixtures) {
+ const absolute = path.join(IMAGE_DIR, fixture.file);
+ const read = await readImage(absolute);
+ if (!read.ok) {
+ console.log(` ${fixture.id.padEnd(8)} SKIPPED — ${read.error}`);
+ results.push({ id: fixture.id, file: fixture.file, purpose, skipped: read.error });
+ continue;
+ }
+
+ for (let attempt = 1; attempt <= repeat; attempt += 1) {
+ // The cache in `imageRecognition` is keyed on content+purpose+model, so a second
+ // sample of the same image would be the first one handed back. Cleared between
+ // attempts because measuring the cache is not the point.
+ imageRecognition._clearCache();
+ // Ollama's own cache is the one that matters, and only this clears it.
+
+ if (cold) await unload(client, model);
+
+ const started = Date.now();
+ const described = await imageRecognition.describe({
+ client,
+ model,
+ image: { name: fixture.file, base64: read.image.base64 },
+ purpose,
+ });
+ const ms = Date.now() - started;
+
+ const scored = described.ok
+ ? grade(fixture, described.description)
+ : { passed: false, subject: false, error: described.description };
+
+ const mark = scored.passed ? 'PASS' : 'FAIL';
+ const note = scored.confused && scored.confused.length > 0 ? ` (called it a ${scored.confused[0]})` : '';
+ const detail = scored.detailTotal ? ` detail ${scored.detail}/${scored.detailTotal}` : '';
+ const read_ = scored.readText === null ? '' : scored.readText ? ' text ok' : ' text missed';
+ console.log(
+ ` ${fixture.id.padEnd(8)} ${purpose.padEnd(6)} ${mark}${note}${detail}${read_} ${Math.round(ms / 1000)}s`
+ );
+
+ results.push({
+ id: fixture.id,
+ file: fixture.file,
+ purpose,
+ attempt,
+ durationMs: ms,
+ ok: described.ok,
+ // Stored in full. When a score looks wrong the only way to tell a bad grader
+ // from a bad model is to read what the model actually wrote.
+ description: described.description,
+ expected: fixture.what,
+ ...scored,
+ });
+ }
+ }
+
+ return results;
+}
+
+/**
+ * @param {object[]} results
+ */
+function summarize(results) {
+ const graded = results.filter((r) => !r.skipped && r.ok);
+ const passed = graded.filter((r) => r.passed).length;
+ const confused = graded.filter((r) => r.confused && r.confused.length > 0).length;
+
+ const detailScored = graded.filter((r) => typeof r.detailTotal === 'number' && r.detailTotal > 0);
+ const detailGot = detailScored.reduce((sum, r) => sum + r.detail, 0);
+ const detailMax = detailScored.reduce((sum, r) => sum + r.detailTotal, 0);
+
+ const withText = graded.filter((r) => r.readText !== null && r.readText !== undefined);
+ const textRead = withText.filter((r) => r.readText).length;
+
+ const totalMs = graded.reduce((sum, r) => sum + (r.durationMs || 0), 0);
+
+ // Only the first sample of each image is a cold measurement.
+ //
+ // Ollama caches the prompt prefix, and the prefix here is the image — so attempt 2 of
+ // the same picture with the same prompt comes back in about a second where attempt 1
+ // took fifteen. Averaging them together produced a "4s per image" headline for a
+ // model that takes fifteen, which is the kind of number that gets quoted and then
+ // does not reproduce for anybody.
+ //
+ // The repeats are still worth running; they just measure a different thing.
+ // Consistency is what they are for, and latency is what `coldMeanMs` is for.
+ const cold = graded.filter((r) => r.attempt === 1);
+ const coldMs = cold.reduce((sum, r) => sum + (r.durationMs || 0), 0);
+
+ return {
+ graded: graded.length,
+ passed,
+ failed: graded.length - passed,
+ confused,
+ detailScore: detailMax > 0 ? Number((detailGot / detailMax).toFixed(3)) : null,
+ detailGot,
+ detailMax,
+ textImages: withText.length,
+ textRead,
+ errored: results.filter((r) => !r.skipped && !r.ok).length,
+ skipped: results.filter((r) => r.skipped).length,
+ meanMs: graded.length > 0 ? Math.round(totalMs / graded.length) : 0,
+ coldMeanMs: cold.length > 0 ? Math.round(coldMs / cold.length) : 0,
+ coldSamples: cold.length,
+ totalMs,
+ };
+}
+
+async function main() {
+ const { positional, flags } = parseArgs(process.argv.slice(2));
+ const model = positional[0];
+
+ if (!model) {
+ console.error('Usage: node tools/bench-vision.js --machine [--purpose answer|task|both]');
+ process.exit(1);
+ }
+
+ const machine = String(flags.machine || '').toUpperCase();
+ if (!['A', 'B', 'C'].includes(machine)) {
+ console.error('--machine is required and must be A, B, or C. It picks the results directory.');
+ process.exit(1);
+ }
+
+ const purposeFlag = String(flags.purpose || 'answer').toLowerCase();
+ const purposes = purposeFlag === 'both' ? ['answer', 'task'] : [purposeFlag];
+ for (const purpose of purposes) {
+ if (purpose !== 'answer' && purpose !== 'task') {
+ console.error(`--purpose must be answer, task, or both. Got "${purpose}".`);
+ process.exit(1);
+ }
+ }
+
+ const only = flags.images
+ ? String(flags.images)
+ .split(',')
+ .map((s) => s.trim())
+ .filter(Boolean)
+ : null;
+ const fixtures = only ? FIXTURES.filter((f) => only.includes(f.id)) : FIXTURES;
+ if (fixtures.length === 0) {
+ console.error(`No fixture matched --images. Available: ${FIXTURES.map((f) => f.id).join(', ')}`);
+ process.exit(1);
+ }
+
+ const repeat = Math.max(1, Number(flags.repeat) || 1);
+ const cold = flags.cold === true || flags.cold === 'true';
+ const client = createClient({ endpoint: flags.endpoint || 'http://127.0.0.1:11434', timeoutMs: 300000 });
+
+ // Checked before a long run rather than discovered thirty seconds in. A model without
+ // vision does not refuse an image, so without this the whole sweep would complete and
+ // score zero for a reason the numbers would not explain.
+ const tags = await client.tags();
+ const entry = (tags || []).find((t) => t.name === model || t.model === model);
+ if (!entry) {
+ console.error(`${model} is not installed. Run: ollama pull ${model}`);
+ process.exit(1);
+ }
+ const capabilities = Array.isArray(entry.capabilities) ? entry.capabilities : [];
+ if (!capabilities.includes('vision')) {
+ console.error(
+ `${model} does not report the "vision" capability, so it cannot read an image. ` +
+ `It reports: ${capabilities.join(', ') || '(nothing)'}.`
+ );
+ process.exit(1);
+ }
+
+ const startedAt = new Date();
+ console.log(`\nbench-vision — ${model} on machine ${machine}`);
+ console.log(`${fixtures.length} image(s) × ${repeat} run(s) × ${purposes.length} prompt(s)\n`);
+
+ /** @type {object[]} */
+ let results = [];
+ for (const purpose of purposes) {
+ results = results.concat(await runPurpose(client, model, purpose, fixtures, repeat, cold));
+ }
+
+ const summary = summarize(results);
+ const record = {
+ schemaVersion: 1,
+ benchmark: 'vision',
+ model,
+ machine,
+ params: (entry.details && entry.details.parameter_size) || null,
+ capabilities,
+ purposes,
+ repeat,
+ // Recorded because it changes what the timings mean, and a reader of the JSON
+ // cannot tell otherwise.
+ coldStart: cold,
+ startedAt: startedAt.toISOString(),
+ durationMs: Date.now() - startedAt.getTime(),
+ notes: flags.notes || '',
+ summary,
+ results,
+ };
+
+ const outRoot = flags.out || path.join(__dirname, '..', 'benchmarks', 'results');
+ const dir = path.join(outRoot, machine);
+ fs.mkdirSync(dir, { recursive: true });
+ const stamp = startedAt.toISOString().replace(/[:.]/g, '-').slice(0, 19);
+ const file = path.join(dir, `vision__${model.replace(/[:/\\]/g, '-')}__${stamp}.json`);
+ fs.writeFileSync(file, `${JSON.stringify(record, null, 2)}\n`);
+
+ console.log(`\n subject ${summary.passed}/${summary.graded}`);
+ console.log(` detail ${summary.detailGot}/${summary.detailMax}`);
+ console.log(
+ ` text read ${summary.textImages > 0 ? `${summary.textRead}/${summary.textImages}` : 'no image had any'}`
+ );
+ console.log(` confused ${summary.confused}`);
+ console.log(
+ ` cold ${Math.round(summary.coldMeanMs / 1000)}s per image` +
+ (cold ? ' (model unloaded first)' : ' (first sample; NOT a true cold start, pass --cold)')
+ );
+ console.log(` warm ${Math.round(summary.meanMs / 1000)}s per image (all samples, prompt-cached)`);
+ console.log(`\nWritten to ${path.relative(process.cwd(), file)}\n`);
+}
+
+main().catch((err) => {
+ console.error(err);
+ process.exit(1);
+});
 +
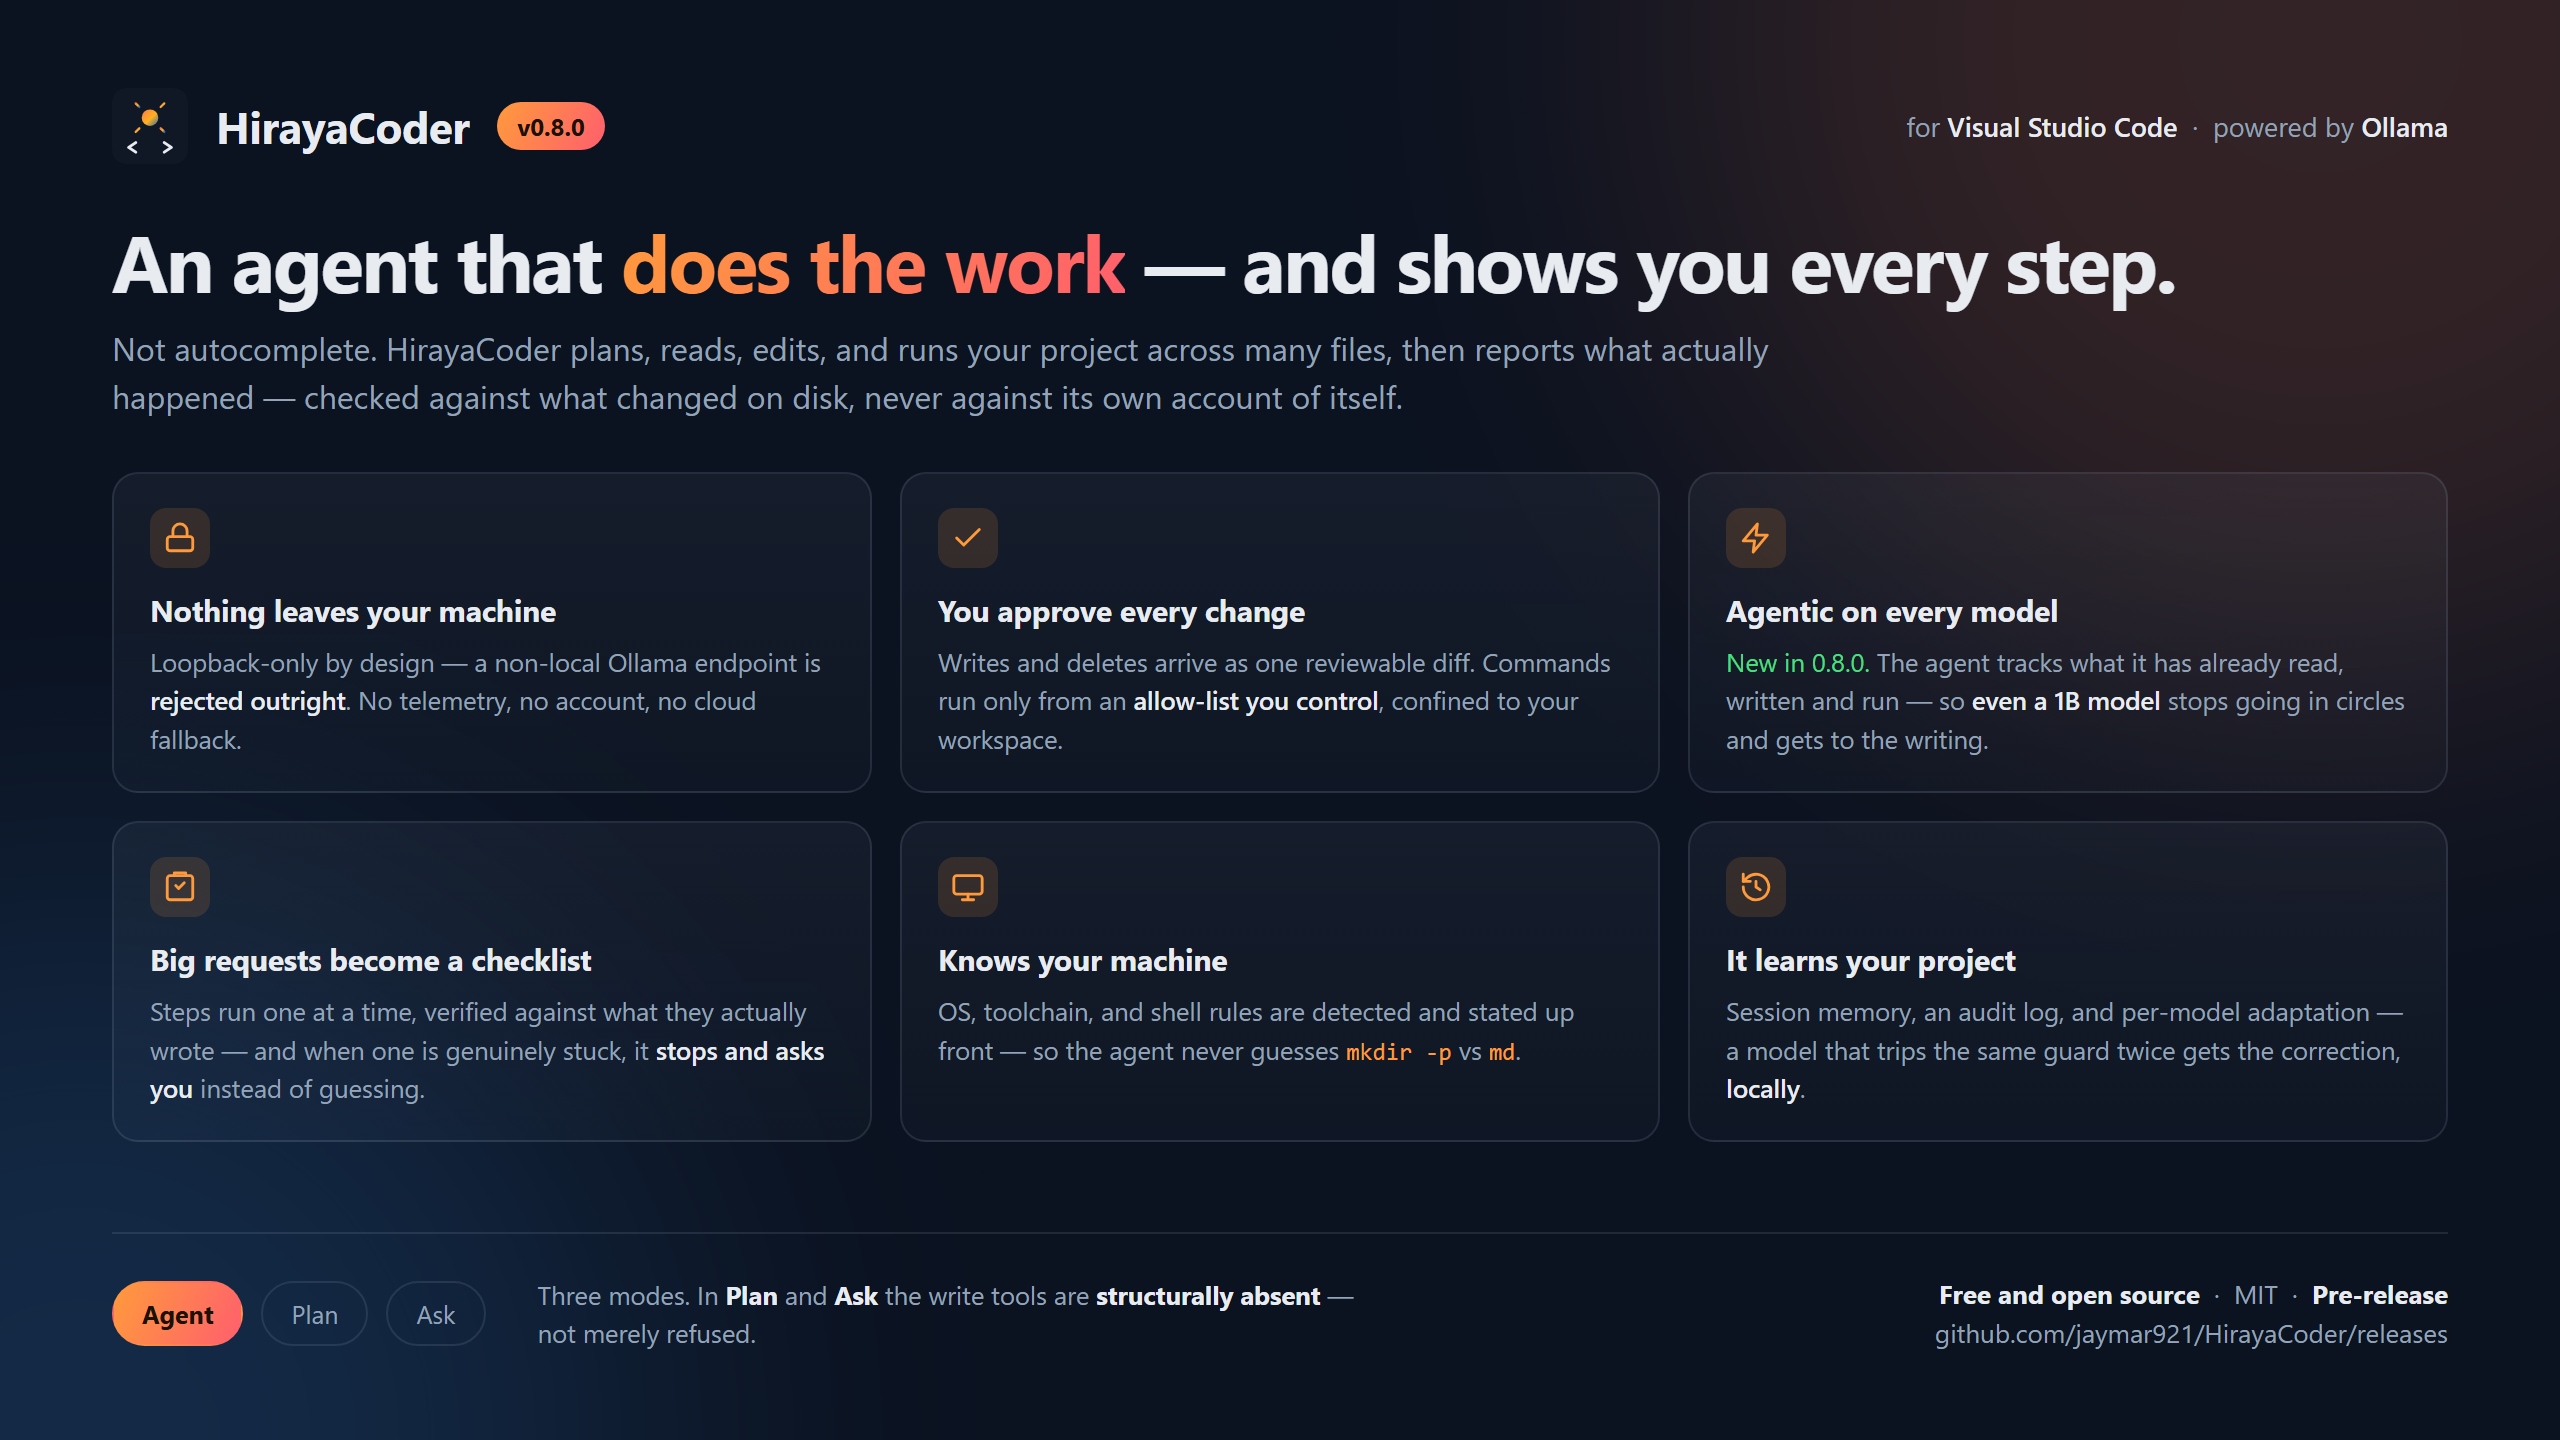 +
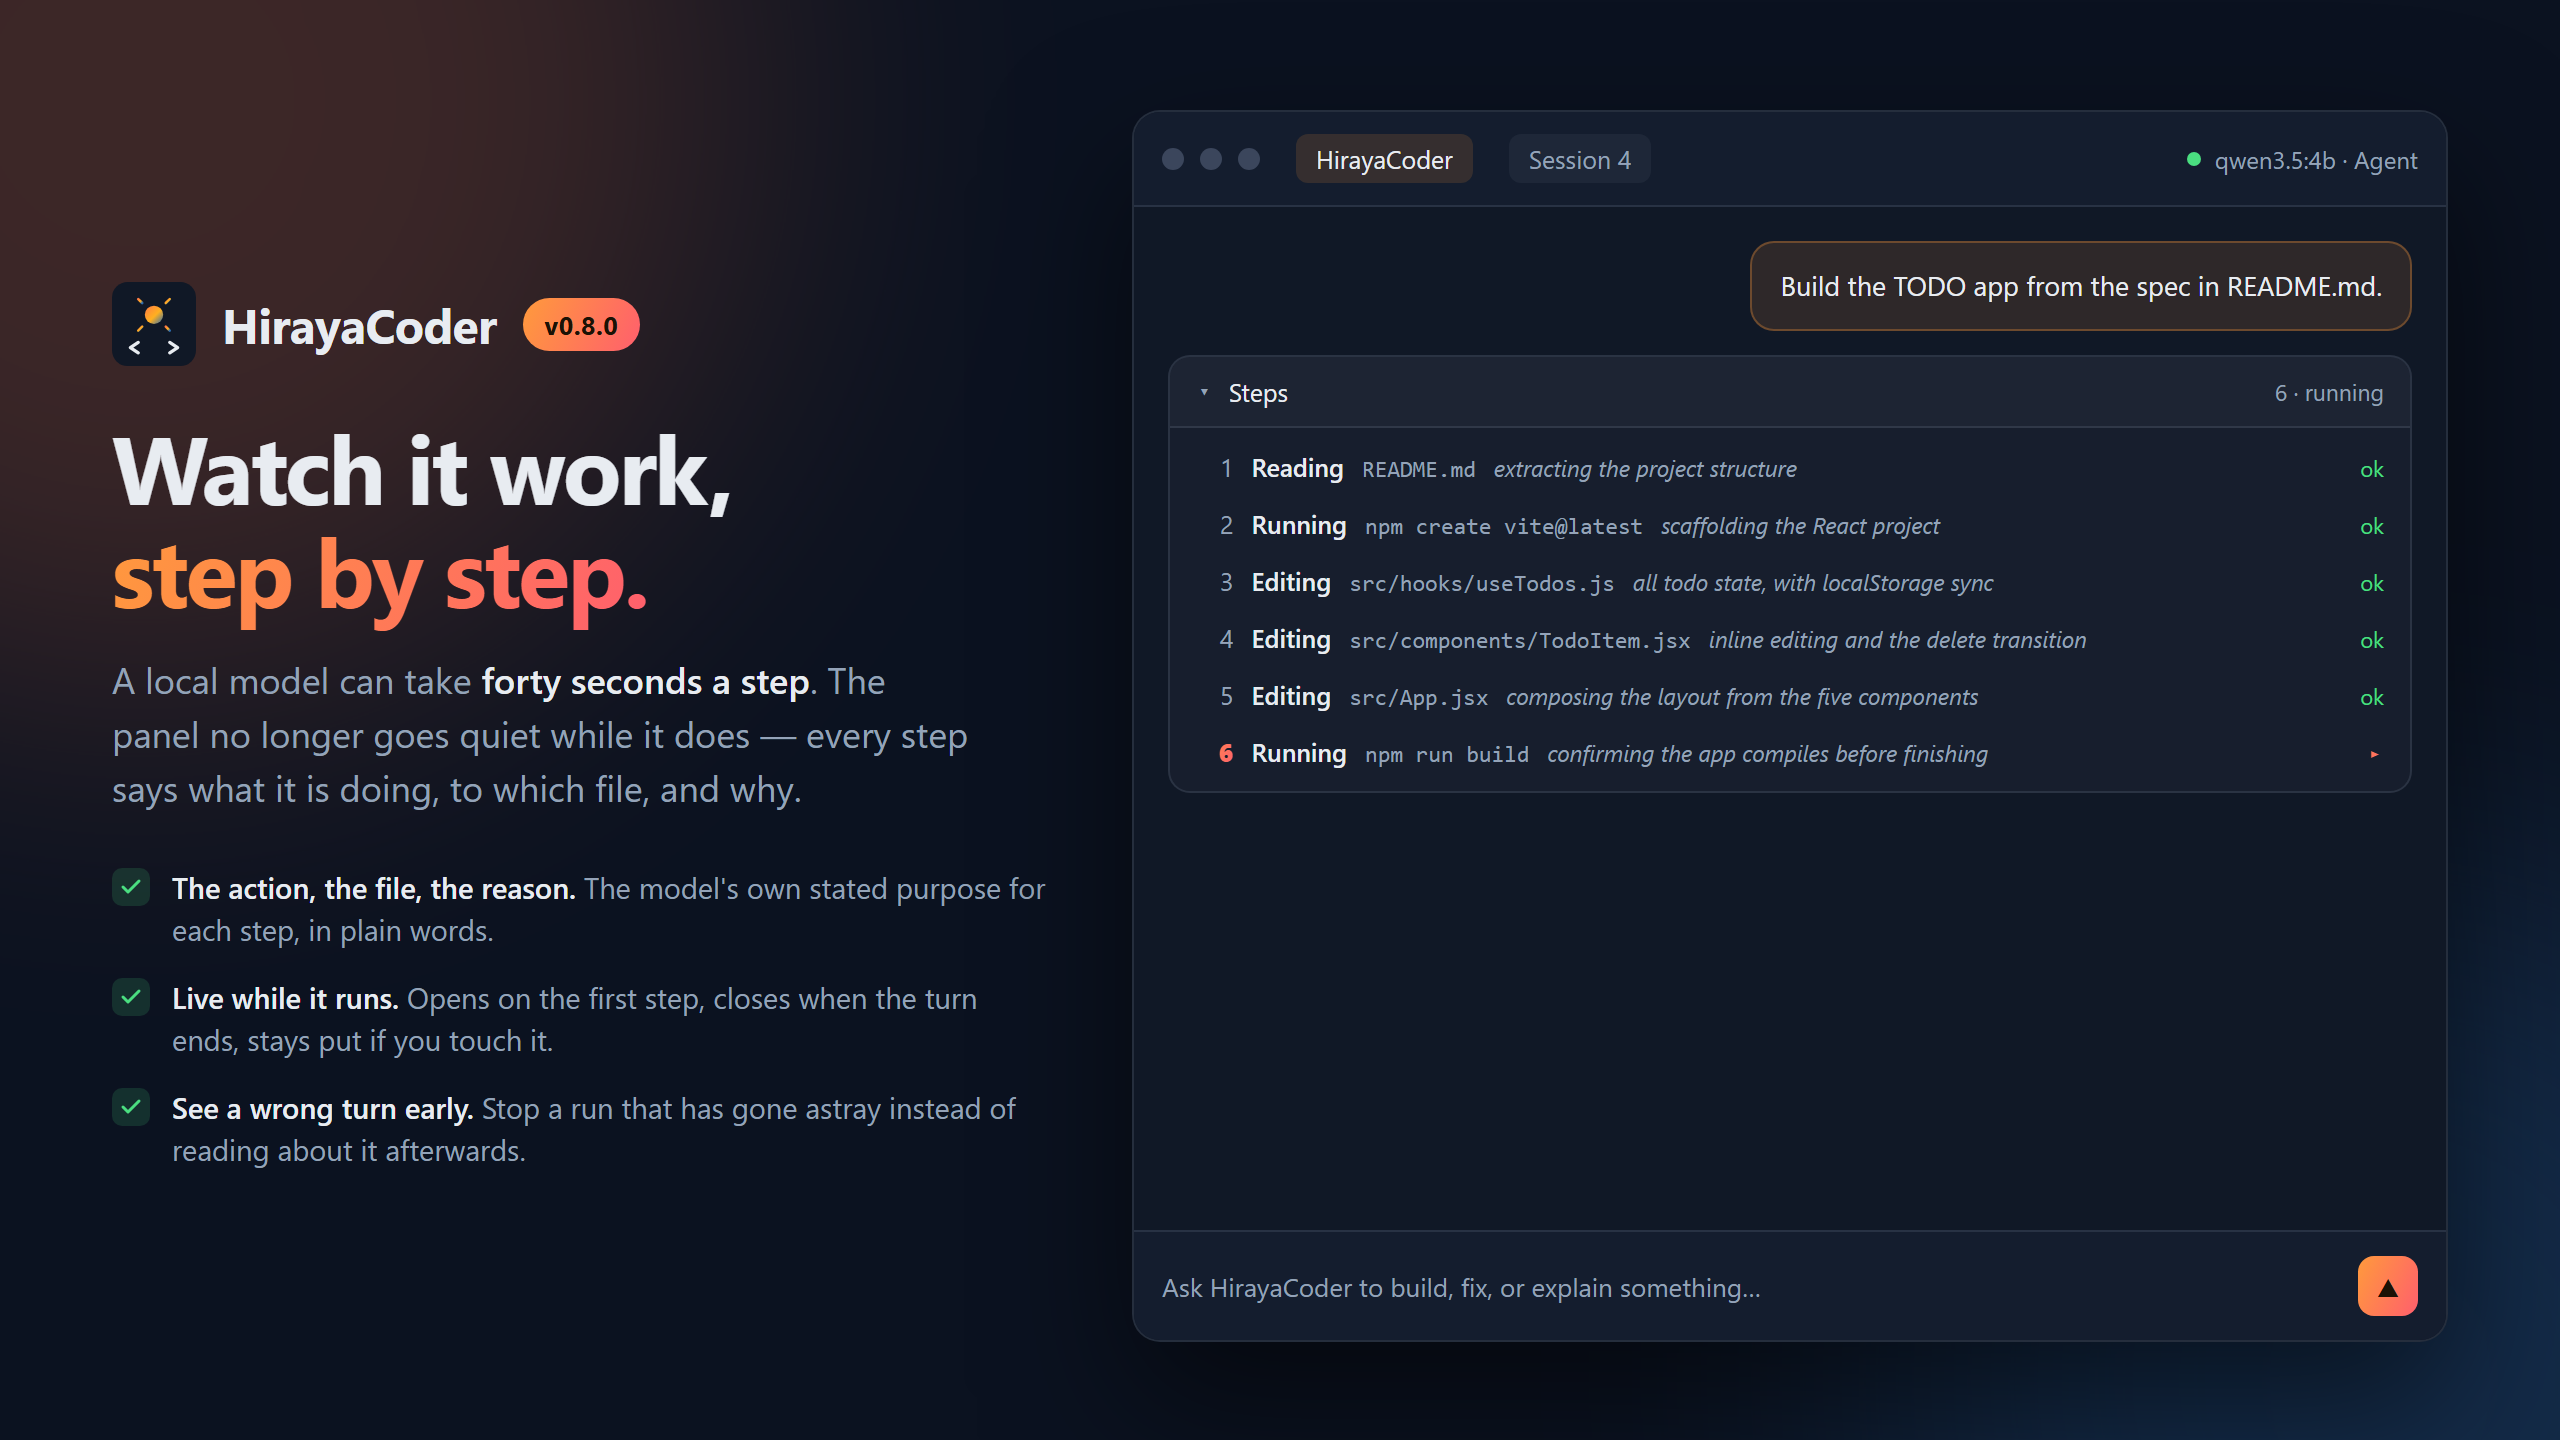 -
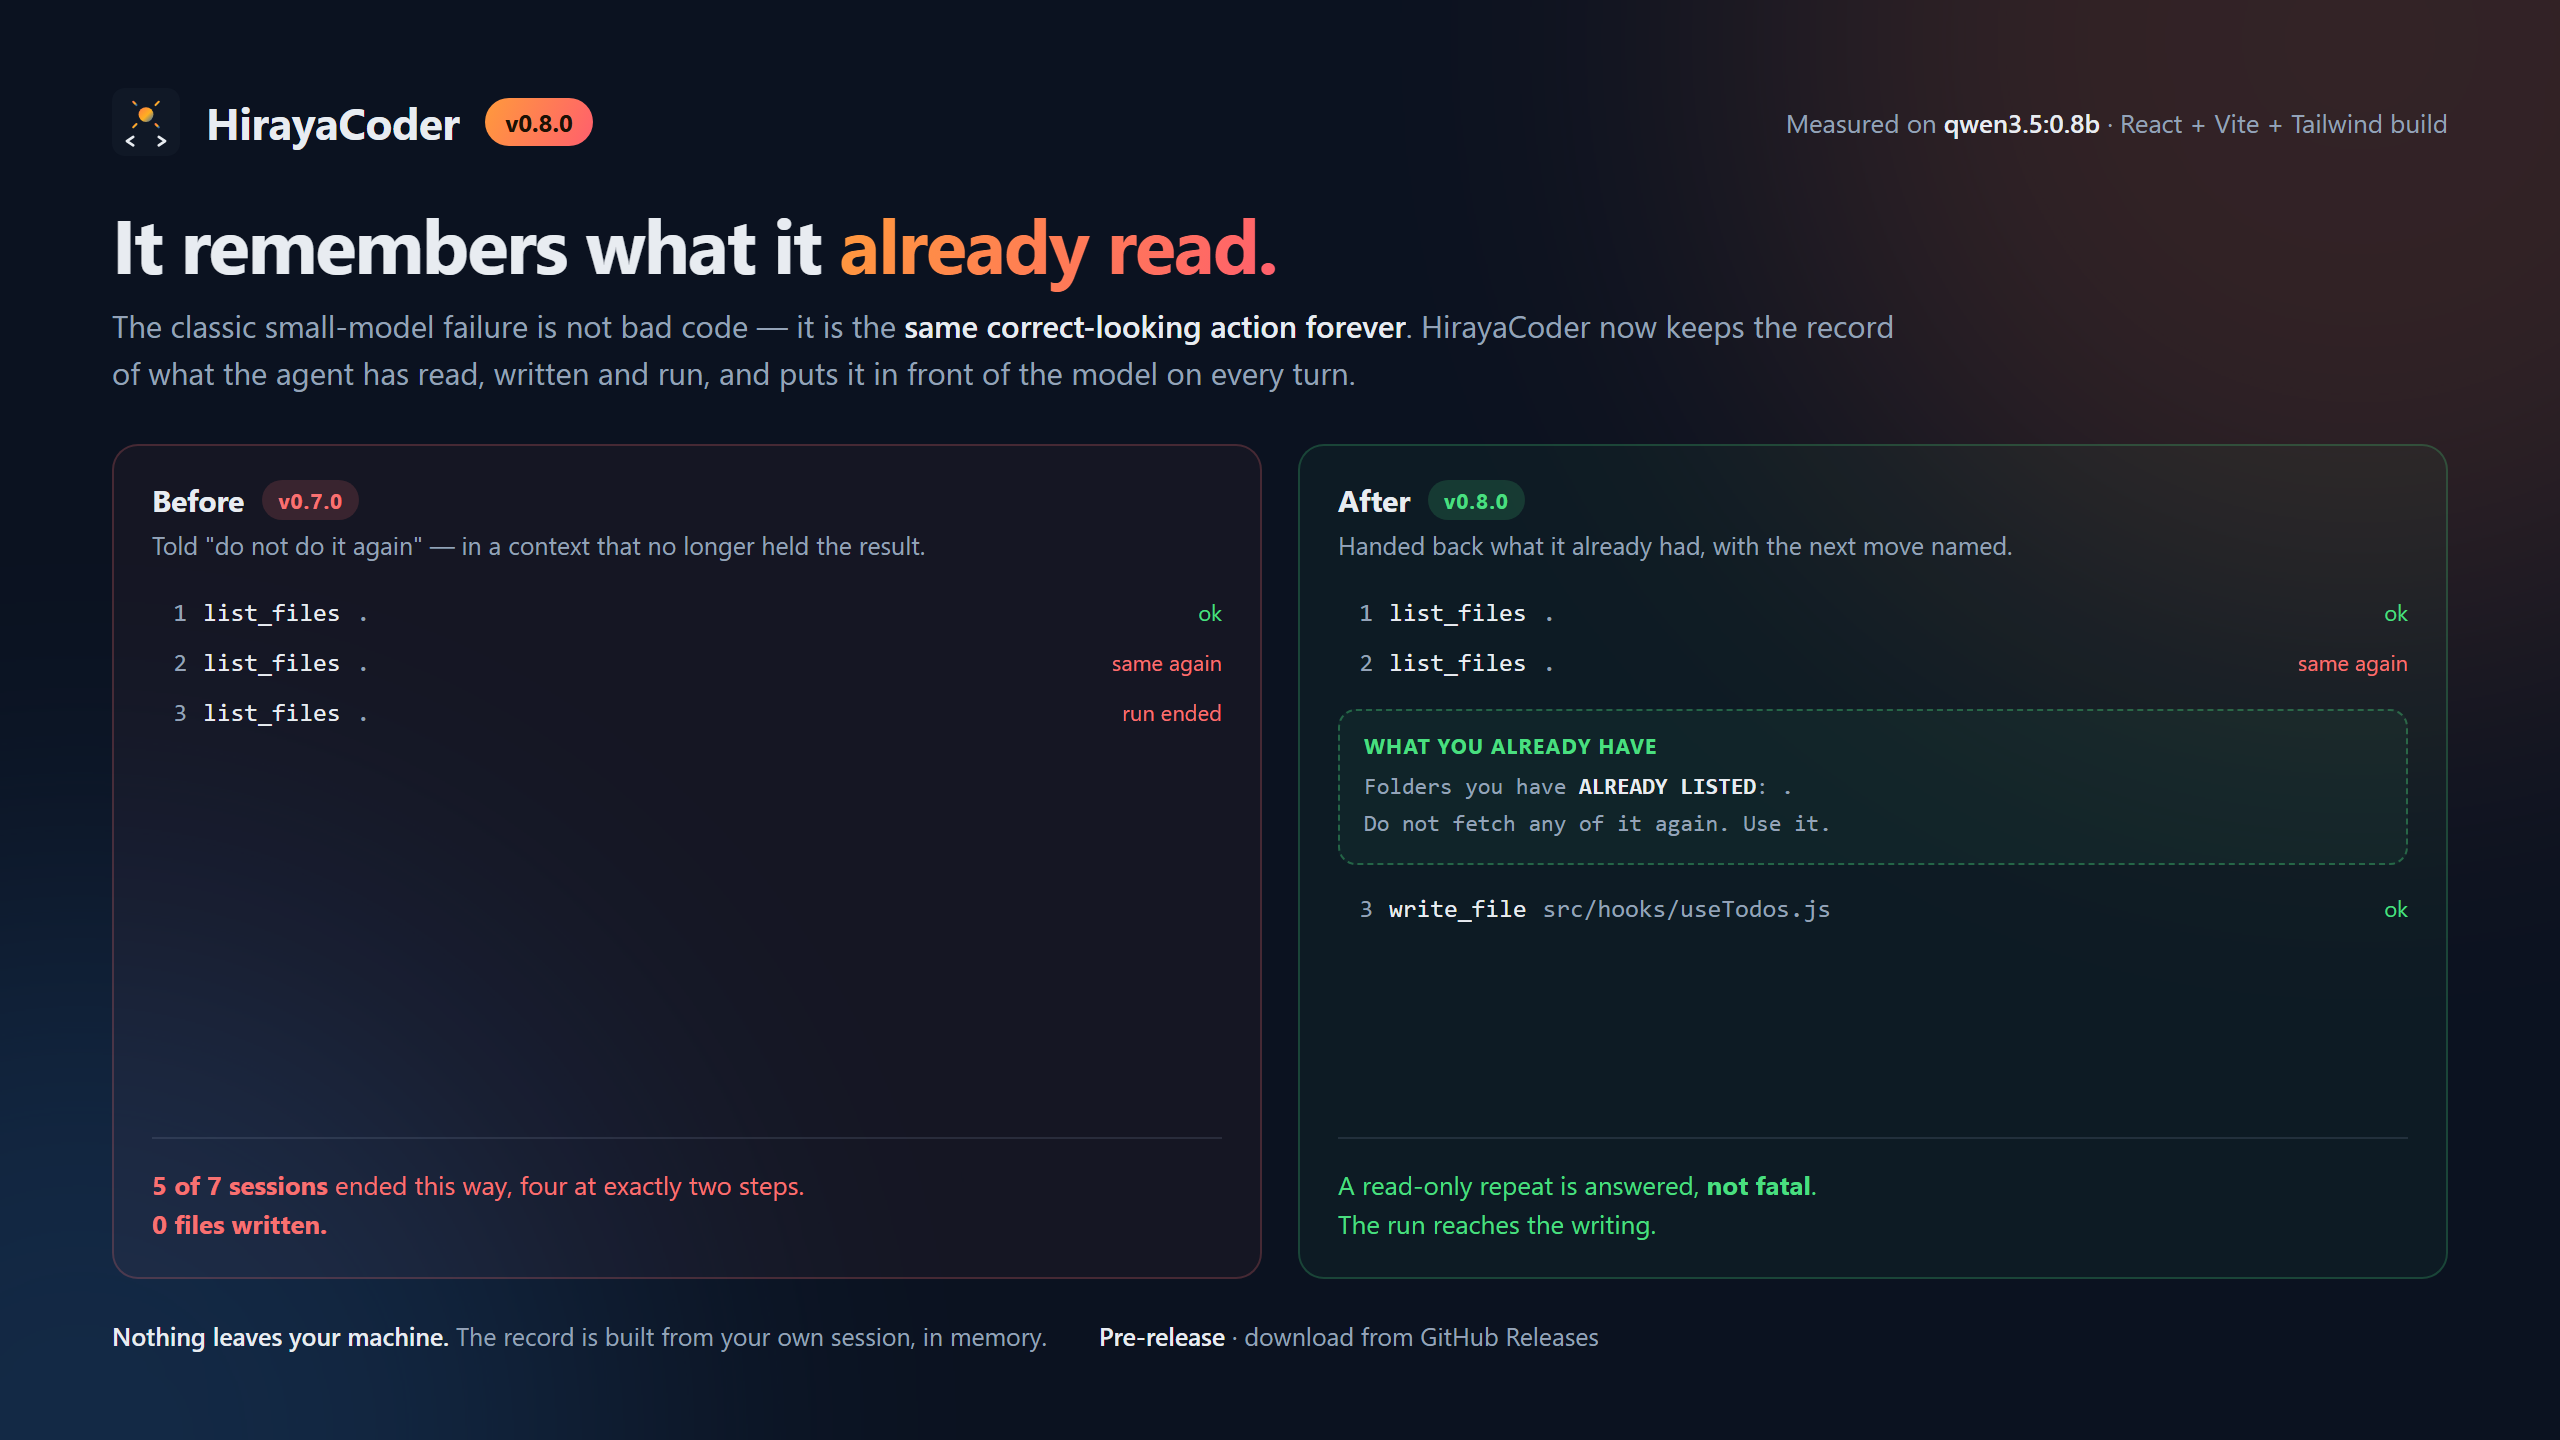 -
 -
 -