diff --git a/docs.json b/docs.json
index f6c91950..4959be6a 100644
--- a/docs.json
+++ b/docs.json
@@ -113,7 +113,7 @@
"lfm/key-concepts/tool-use",
"lfm/key-concepts/vision-capabilities",
"lfm/key-concepts/audio-capabilities",
- "lfm/key-concepts/omni-capabilities",
+ "lfm/key-concepts/speech-generation",
"lfm/key-concepts/speculative-decoding"
]
},
@@ -334,6 +334,10 @@
]
},
"redirects": [
+ {
+ "source": "/lfm/key-concepts/omni-capabilities",
+ "destination": "/lfm/key-concepts/audio-capabilities"
+ },
{
"source": "/lfm/key-concepts/tool-search",
"destination": "/lfm/key-concepts/tool-use"
diff --git a/guides/migration-guide.mdx b/guides/migration-guide.mdx
index 814320f8..ccfe5493 100644
--- a/guides/migration-guide.mdx
+++ b/guides/migration-guide.mdx
@@ -3,7 +3,7 @@ title: "Migration Guide"
description: "Move from Qwen, Llama, or Gemma to LFMs while avoiding the common migration pitfalls."
---
-import { ToolCallTokenExample } from "/snippets/key-concepts/tool-call-token-example.mdx";
+import { LFM25ToolCallExample } from "/snippets/key-concepts/lfm25-tool-call-example.mdx";
This guide is for teams already running Qwen, Llama, or Gemma who want to evaluate Liquid Foundation Models (LFMs) as replacements. LFMs load and serve through the same frameworks you already use, so most migrations are a model ID and configuration change. The details that usually matter are:
- deployment runtime choice (see [Deployment runtimes](#deployment-runtimes)),
@@ -76,7 +76,7 @@ LFM3 emits XML tool calls, using a superset of the `qwen3_coder` format:
LFM2 and LFM2.5 use the earlier tool-call format, typically a Pythonic call list:
-
+
Serving runtimes can parse these native formats into OpenAI-compatible `tool_calls`. A client that reads raw generated text must handle the format for its selected model.
diff --git a/images/lfm/key-concepts/vision-capabilities/cell-13-output-5.png b/images/lfm/key-concepts/vision-capabilities/cell-13-output-5.png
index b47f79b6..63fac188 100644
Binary files a/images/lfm/key-concepts/vision-capabilities/cell-13-output-5.png and b/images/lfm/key-concepts/vision-capabilities/cell-13-output-5.png differ
diff --git a/images/lfm/key-concepts/vision-capabilities/cell-15-output-6.png b/images/lfm/key-concepts/vision-capabilities/cell-15-output-6.png
index ae662934..a424307c 100644
Binary files a/images/lfm/key-concepts/vision-capabilities/cell-15-output-6.png and b/images/lfm/key-concepts/vision-capabilities/cell-15-output-6.png differ
diff --git a/images/lfm/key-concepts/vision-capabilities/lfm3-grounding.png b/images/lfm/key-concepts/vision-capabilities/lfm3-grounding.png
index c3a660da..93639717 100644
Binary files a/images/lfm/key-concepts/vision-capabilities/lfm3-grounding.png and b/images/lfm/key-concepts/vision-capabilities/lfm3-grounding.png differ
diff --git a/images/lfm/key-concepts/vision-capabilities/lfm3-pointing.png b/images/lfm/key-concepts/vision-capabilities/lfm3-pointing.png
index db36f20a..61ca7d15 100644
Binary files a/images/lfm/key-concepts/vision-capabilities/lfm3-pointing.png and b/images/lfm/key-concepts/vision-capabilities/lfm3-pointing.png differ
diff --git a/lfm/key-concepts/audio-capabilities.mdx b/lfm/key-concepts/audio-capabilities.mdx
index 6714f208..abc86106 100644
--- a/lfm/key-concepts/audio-capabilities.mdx
+++ b/lfm/key-concepts/audio-capabilities.mdx
@@ -1,11 +1,11 @@
---
title: "Audio Capabilities"
-description: "Use LFM3-Audio for speech recognition, text-to-speech, speech translation, spoken chat, speech-to-text chat, audio understanding, and tool calling from spoken requests."
+description: "Recognize and translate speech, answer spoken questions, and understand speech, music, and other sounds."
---
-LFM3-Audio is a single end-to-end speech model: it listens to audio, reads text, and answers in text, speech, or interleaved text and speech. One model covers speech recognition, text-to-speech, speech translation, spoken chat, and tool calling from spoken requests.
+Audio-capable models can transcribe and translate speech, answer spoken questions, and identify sounds and events in a recording.
-The examples below use [LFM3-Audio-2B](/lfm/models/lfm3-audio-2b) with Transformers. For images and video as well as audio, see [Omni Capabilities](/lfm/key-concepts/omni-capabilities).
+Use this page for speech and audio input. Where the code differs between audio and omni models, pick a model type in the tabs. The choice applies to every example on the page. Speech output has its own [Speech Generation](/lfm/key-concepts/speech-generation) guide.
## Setup
@@ -15,13 +15,14 @@ Install Transformers and the packages used by the examples. `librosa` and `sound
pip install "transformers>=5.20.2" accelerate datasets librosa soundfile
```
-Load the model and processor with `trust_remote_code=True`. The processor bundles the audio codec, which turns generated speech codes into a 24 kHz waveform. Access it as `processor.audio_tokenizer` and move it to the model's device. Keep the codec in its own precision; don't cast it to bfloat16.
+Load the model and processor with `trust_remote_code=True`. The processor bundles the audio codec (`processor.audio_tokenizer`), which turns generated speech codes into a 24 kHz waveform.
```python
import torch
+import soundfile as sf
from transformers import AutoModelForMultimodalLM, AutoProcessor
-model_id = "LiquidAI/LFM3-Audio-2B"
+model_id = "LiquidAI/LFM3-Audio-2B" # or "LiquidAI/LFM3-Omni-2B"
device = "cuda" if torch.cuda.is_available() else "cpu"
dtype = torch.bfloat16 if device == "cuda" else torch.float32
@@ -32,60 +33,13 @@ processor = AutoProcessor.from_pretrained(model_id, trust_remote_code=True)
codec = processor.audio_tokenizer.to(device=device).eval()
```
-### Output modes
-
-Every task is a chat conversation, and the system prompt describes the task. Text output is the default: generation starts in text mode and switches to speech or interleaved output when the model emits an output-mode token.
-
-To select a mode from the start, prefill the assistant turn: put one of the prefixes below in a final assistant message and let the model continue it.
-
-| Assistant prefill | Behavior |
-|---|---|
-| None | Start in text mode. The model can still emit a token that switches modes. |
-| `<\|audio_start\|>` | Start speech-only output, for example text-to-speech, until an end-of-audio frame. |
-| `<\|mixed_start\|>` | Start interleaved text and speech, alternating blocks of 6 text tokens and 12 speech frames. |
-| `` | Begin a thinking block. The answer follows the closing ``. |
-| `` | Supply an empty thinking block, so the answer starts immediately. |
-
-The thinking prefixes are for text-only answers. For those, also pass `suppress_mixed=True` and `suppress_audio_out=True` to `generate()`, so the model doesn't switch to speech.
-
-### Helper
-
-The helper below runs one assistant turn and returns the text and the speech waveform, if any. When you pass `prefill`, it sets `continue_final_message=True`, so generation continues the prefilled message instead of starting a new assistant turn. For speech and interleaved output, pass `SPEECH_SAMPLING`. These values are also the defaults in the model's `generation_config.json`; passing them explicitly keeps the examples reproducible.
-
-```python
-import soundfile as sf
-
-SAMPLE_RATE_OUT = 24_000 # the codec decodes to 24 kHz
-SPEECH_SAMPLING = dict(audio_temperature=1.0, audio_top_k=128, audio_repetition_penalty=1.1, audio_repetition_window=4096)
-
-
-@torch.inference_mode()
-def generate(conversation, prefill=None, max_new_tokens=512, **generate_kwargs):
- """Runs one assistant turn. Returns (text, waveform or None)."""
- if prefill is not None:
- conversation = conversation + [{"role": "assistant", "content": prefill}]
- inputs = processor.apply_chat_template(
- conversation,
- add_generation_prompt=prefill is None,
- continue_final_message=prefill is not None,
- tokenize=True,
- return_dict=True,
- return_tensors="pt",
- ).to(device)
- outputs = model.generate(**inputs, max_new_tokens=max_new_tokens, **generate_kwargs)
- text = processor.decode(outputs.sequences[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
- waveform = None
- if outputs.audio_codes is not None and outputs.audio_lengths[0] > 0:
- codes = outputs.audio_codes[:1, :, : outputs.audio_lengths[0]]
- waveform = codec.decode(codes).audio_values[0].float().cpu().numpy().squeeze()
- return text, waveform
-```
+Every task is a chat conversation, and the system prompt describes the task. Answers are in text by default. Some examples first record a spoken input with [text-to-speech](/lfm/key-concepts/speech-generation#text-to-speech). Where the code differs between audio and omni models, the examples have a tab for each.
## Speech recognition
-Use the system prompt `Perform ASR in .` with the English name of the language, or `Perform ASR.` to let the model detect it.
+Use the system prompt `Perform ASR in .` with the English name of the language. Pass audio in the user turn as `{"type": "audio", "audio": ...}`, where the value is a file path or URL. The processor resamples it to 16 kHz mono.
-Pass audio in the user turn as `{"type": "audio", "audio": ...}`, where the value is a file path or URL. The processor resamples it to 16 kHz mono. This example transcribes a LibriSpeech clip:
+This example transcribes a LibriSpeech clip:
```python
import io
@@ -99,10 +53,24 @@ speech, sr = sf.read(io.BytesIO(sample["audio"]["bytes"]))
sf.write("librispeech.wav", speech, sr)
print("Reference:", sample["text"])
-transcript, _ = generate([
+messages = [
{"role": "system", "content": "Perform ASR in English."},
{"role": "user", "content": [{"type": "audio", "audio": "librispeech.wav"}]},
-])
+]
+
+# Apply chat template
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+with torch.inference_mode():
+ outputs = model.generate(**inputs, max_new_tokens=512)
+
+transcript = processor.decode(outputs.sequences[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
print("Transcript:", transcript)
```
@@ -115,9 +83,11 @@ Transcript: Mr. Quilter is the apostle of the middle classes, and we are glad to
## Live speech recognition
-Live speech recognition transcribes speech while it is still being spoken, instead of waiting for the full recording. Use the system prompt `Perform live ASR.`. It currently supports English only.
+Live speech recognition requires an audio model with live recognition support. Check the model page before you use this example.
-The model processes audio in chunks of about 0.96 s and writes the text for each chunk as soon as the chunk arrives. `model.transcribe_live()` runs one chunk at a time and returns a state that you pass to the next call. In an application, you open a microphone stream into the model and a text stream out of it. This example simulates the microphone by feeding the LibriSpeech clip in 100 ms pieces:
+Live speech recognition transcribes speech while it is still being spoken, instead of waiting for the full recording. Use the system prompt `Perform live ASR.`. Check the model page for supported languages.
+
+The model processes audio in short chunks and writes the text for each chunk as soon as the chunk arrives. `model.transcribe_live()` runs one chunk at a time and returns a state that you pass to the next call. In an application, you open a microphone stream into the model and a text stream out of it. This example simulates the microphone by feeding the LibriSpeech clip in 100 ms pieces:
```python
import librosa
@@ -179,123 +149,178 @@ Mr. Quilter is the apostle of the middle classes, and we're glad to welcome his
For streams longer than 30 seconds, pass `input_ids=prompt` again to start a new text context. The encoder keeps following the audio stream.
-## Text-to-speech
+## Speech translation
+
+Models with speech translation support can translate speech into text. Name the source and target languages in the system prompt, for example `Convert the speech in {source} to written {target}.` or `Translate the following speech from {source} to {target} in text form.` Try the phrasing that works best for your data.
-Use the system prompt `Perform TTS in using a voice.` and prefill `<|audio_start|>`.
+For text-to-text translation, use a [text model](/lfm/models/text-models) instead.
-Supported languages and accents: Arabic, Danish, German, Greek, British English, American English, Finnish, French, Hebrew, Italian, Japanese, Korean, Dutch, Polish, Portuguese, Spanish, Swedish, Turkish, and Chinese.
+This example first records a French sentence with text-to-speech:
```python
-torch.manual_seed(0)
-_, tts_en = generate(
- [
- {"role": "system", "content": "Perform TTS in American English using a female voice."},
- {"role": "user", "content": "I made a little plan for today: go for a walk, find a new workout playlist, and try a new cake recipe"},
- ],
- prefill="<|audio_start|>",
- **SPEECH_SAMPLING,
-)
-sf.write("tts_en.wav", tts_en, SAMPLE_RATE_OUT)
-
-_, tts_fr = generate(
- [
- {"role": "system", "content": "Perform TTS in French using a male voice."},
- {"role": "user", "content": "On pourrait inventer une nouvelle recette ce soir. Si le résultat est étrange, on lui donnera un nom très chic."},
- ],
- prefill="<|audio_start|>",
- **SPEECH_SAMPLING,
-)
-sf.write("tts_fr.wav", tts_fr, SAMPLE_RATE_OUT)
+tts_messages = [
+ {"role": "system", "content": "Perform TTS in French using a male voice."},
+ {"role": "user", "content": "On pourrait inventer une nouvelle recette ce soir. Si le résultat est étrange, on lui donnera un nom très chic."},
+]
```
-As a quick check, let the model transcribe its own French speech:
+
+
```python
-transcript, _ = generate([
- {"role": "system", "content": "Perform ASR in French."},
- {"role": "user", "content": [{"type": "audio", "audio": "tts_fr.wav"}]},
-])
-print("Transcript:", transcript)
-```
+# Apply chat template
+inputs = processor.apply_chat_template(
+ tts_messages + [{"role": "assistant", "content": "<|audio_start|>"}],
+ continue_final_message=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
-**Output**
+torch.manual_seed(0)
+with torch.inference_mode():
+ outputs = model.generate(
+ **inputs,
+ max_new_tokens=512,
+ audio_temperature=1.0,
+ audio_top_k=128,
+ audio_repetition_penalty=1.1,
+ audio_repetition_window=4096,
+ )
-```text
-Transcript: On pourrait inventer une nouvelle recette ce soir. Si le résultat est étrange, on lui donnera un nom très chic.
+codes = outputs.audio_codes[:1, :, : outputs.audio_lengths[0]]
+with torch.inference_mode():
+ speech = codec.decode(codes).audio_values[0].float().cpu().numpy().squeeze()
+sf.write("tts_fr.wav", speech, 24_000)
```
-## Speech translation
+
+
-LFM3-Audio translates speech into text. Translation works best into or out of English. Name the source and target languages in the system prompt, for example `Convert the speech in {source} to written {target}.` or `Translate the following speech from {source} to {target} in text form.` The model was trained on many phrasings, so pick the one that works best for your data.
+```python
+# Apply chat template
+inputs = processor.apply_chat_template(
+ tts_messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
-For text-to-text translation, use the text model [LFM3-1.7B](/lfm/models/lfm3-1.7b) instead.
+torch.manual_seed(0)
+with torch.inference_mode():
+ outputs = model.generate(
+ **inputs,
+ max_new_tokens=512,
+ generation_mode="audio",
+ audio_temperature=0.4,
+ audio_repetition_penalty=1.2,
+ audio_repetition_window=64,
+ )
-This example translates the French clip from the text-to-speech example into English:
+codes = outputs.audio_codes[:1, :, : outputs.audio_lengths[0]]
+with torch.inference_mode():
+ speech = codec.decode(codes).audio_values[0].float().cpu().numpy().squeeze()
+sf.write("tts_fr.wav", speech, 24_000)
+```
+
+
+
+
+Then translate the recording into English:
```python
-translation, _ = generate([
+messages = [
{"role": "system", "content": "Convert the speech in French to written English."},
{"role": "user", "content": [{"type": "audio", "audio": "tts_fr.wav"}]},
-])
+]
+
+# Apply chat template
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+with torch.inference_mode():
+ outputs = model.generate(**inputs, max_new_tokens=512)
+
+translation = processor.decode(outputs.sequences[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
print("Translation:", translation)
```
**Output**
```text
-Translation: We could invent a new recipe this evening. If the result is strange, it will be given a very fancy name.
+Translation: We could invent a new recipe tonight. If the result is strange, we will give it a very fancy name.
```
-## Spoken chat
+## Speech-to-text chat
-With the system prompt `Respond with interleaved text and audio.` and the `<|mixed_start|>` prefill, the model answers conversationally in text and speech at the same time, so speech can start playing before the full answer is written. Keep the system prompt exactly as shown, and give any further instructions in the user turn.
+In this mode, the model behaves like a text LLM that also accepts speech. No system prompt is needed.
This example first records a spoken question with text-to-speech, then asks it:
```python
-_, question = generate(
- [
- {"role": "system", "content": "Perform TTS in American English using a male voice."},
- {"role": "user", "content": "I want to move more, but I have not found an activity I enjoy. How can I try a few options and build a small habit?"},
- ],
- prefill="<|audio_start|>",
- **SPEECH_SAMPLING,
-)
-sf.write("question.wav", question, SAMPLE_RATE_OUT)
-
-reply, reply_speech = generate(
- [
- {"role": "system", "content": "Respond with interleaved text and audio."},
- {"role": "user", "content": [{"type": "audio", "audio": "question.wav"}]},
- ],
- prefill="<|mixed_start|>",
- max_new_tokens=1024,
- **SPEECH_SAMPLING,
-)
-print("Text:", reply)
-sf.write("reply.wav", reply_speech, SAMPLE_RATE_OUT)
+tts_messages = [
+ {"role": "system", "content": "Perform TTS in American English using a male voice."},
+ {"role": "user", "content": "I want to move more, but I have not found an activity I enjoy. How can I try a few options and build a small habit?"},
+]
+messages = [
+ {"role": "user", "content": [{"type": "audio", "audio": "question.wav"}]},
+]
```
-**Output** (text part; the speech is saved to `reply.wav`)
+
+
-```text
-Text: Try a short trial of each activity, like a weekend hike, a cooking class, or a volunteer shift, and note how much fun you had each time. Pick the one that feels most appealing and commit to doing it for just one week to see if it sticks. Does a one‑week trial of a single activity sound doable?
-```
+Record the question:
-For streaming applications, `model.generate()` accepts `streamer` for text tokens and `audio_streamer` for speech frames, and the codec decodes those frames incrementally, so speech can be played as it is generated.
+```python
+# Apply chat template
+inputs = processor.apply_chat_template(
+ tts_messages + [{"role": "assistant", "content": "<|audio_start|>"}],
+ continue_final_message=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
-## Speech-to-text chat
+torch.manual_seed(0)
+with torch.inference_mode():
+ outputs = model.generate(
+ **inputs,
+ max_new_tokens=512,
+ audio_temperature=1.0,
+ audio_top_k=128,
+ audio_repetition_penalty=1.1,
+ audio_repetition_window=4096,
+ )
+
+codes = outputs.audio_codes[:1, :, : outputs.audio_lengths[0]]
+with torch.inference_mode():
+ speech = codec.decode(codes).audio_values[0].float().cpu().numpy().squeeze()
+sf.write("question.wav", speech, 24_000)
+```
-In this mode, the model behaves like a text LLM that also accepts speech. No system prompt is needed. Prefill `` to let the model reason first; it closes the reasoning with ``, and the answer follows. Pass `suppress_mixed=True` and `suppress_audio_out=True` to keep the answer in text.
+Prefill `` to let the model reason first. It closes the reasoning with ``, and the answer follows. Pass `suppress_mixed=True` and `suppress_audio_out=True` to keep the answer in text:
```python
-text, _ = generate(
- [{"role": "user", "content": [{"type": "audio", "audio": "question.wav"}]}],
- prefill="",
- max_new_tokens=2048,
- suppress_mixed=True,
- suppress_audio_out=True,
-)
+# Apply chat template
+inputs = processor.apply_chat_template(
+ messages + [{"role": "assistant", "content": ""}],
+ continue_final_message=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+with torch.inference_mode():
+ outputs = model.generate(**inputs, max_new_tokens=2048, suppress_mixed=True, suppress_audio_out=True)
+
+text = processor.decode(outputs.sequences[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
thinking, _, answer = text.partition("")
print("Thinking:", thinking.strip())
print("Answer:", answer.strip())
@@ -310,162 +335,190 @@ Thinking: We need to answer the question: "I want to move more, but I have not f
* **Goal:** Move more.
* **Problem:** Hasn't found an activity they enjoy.
* **Solution Needed:** How to try a few options and build a small habit.
+
+2. **Deconstruct the Problem:**
...
-Answer: It is completely normal to struggle to find an activity you enjoy when you want to move more. The key to overcoming this is to break the process into tiny, manageable steps and focus on the *process* rather than the *result*.
+Answer: It is completely normal to feel stuck when you aren't finding an activity you enjoy, especially when you want to move more. The key to building a habit is to start small, focus on the process rather than the outcome, and find ways to make movement feel fun.
...
```
-To skip thinking, prefill an empty `` block, so the answer starts immediately:
+To skip thinking, prefill an empty `` block instead, so the answer starts immediately.
+
+
+
+
+Record the question:
```python
-answer, _ = generate(
- [{"role": "user", "content": [{"type": "audio", "audio": "question.wav"}]}],
- prefill="",
- max_new_tokens=1024,
- suppress_mixed=True,
- suppress_audio_out=True,
-)
-print("Answer:", answer.strip())
+# Apply chat template
+inputs = processor.apply_chat_template(
+ tts_messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+torch.manual_seed(0)
+with torch.inference_mode():
+ outputs = model.generate(
+ **inputs,
+ max_new_tokens=512,
+ generation_mode="audio",
+ audio_temperature=0.4,
+ audio_repetition_penalty=1.2,
+ audio_repetition_window=64,
+ )
+
+codes = outputs.audio_codes[:1, :, : outputs.audio_lengths[0]]
+with torch.inference_mode():
+ speech = codec.decode(codes).audio_values[0].float().cpu().numpy().squeeze()
+sf.write("question.wav", speech, 24_000)
```
+Then ask it:
+
+```python
+# Apply chat template
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+with torch.inference_mode():
+ outputs = model.generate(**inputs, max_new_tokens=1024)
+
+answer = processor.decode(outputs.sequences[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+print("Answer:", answer)
+```
+
+**Output** (truncated)
+
+```text
+Answer: It is completely normal to feel stuck when you want to move more but can't find an activity you enjoy. The key to building a small habit is to stop looking for a "perfect" activity and start looking for **micro-habits**—tiny, doable actions that take just a few minutes and build momentum.
+...
+```
+
+
+
+
## Audio understanding
Text and audio can be mixed in the same user turn, for example a recording plus a written question about it. Questions can address speech, music, background sounds, or events.
+This example asks a question about the LibriSpeech clip from [Speech recognition](#speech-recognition):
+
```python
-answer, _ = generate(
- [{"role": "user", "content": [
+messages = [{
+ "role": "user",
+ "content": [
{"type": "audio", "audio": "librispeech.wav"},
{"type": "text", "text": "Who or what is the speaker talking about, and what is their attitude towards it?"},
- ]}],
- prefill="",
- max_new_tokens=512,
- suppress_mixed=True,
- suppress_audio_out=True,
-)
+ ],
+}]
+```
+
+
+
+
+```python
+# Apply chat template
+inputs = processor.apply_chat_template(
+ messages + [{"role": "assistant", "content": ""}],
+ continue_final_message=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+with torch.inference_mode():
+ outputs = model.generate(**inputs, max_new_tokens=512, suppress_mixed=True, suppress_audio_out=True)
+
+answer = processor.decode(outputs.sequences[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
print("Answer:", answer.strip())
```
**Output**
```text
-Answer: The speaker is talking about **Mr. Quilter**, who is described as "the apostle of the middle classes." The speaker's attitude is one of welcome and approval—"we're glad to welcome his gospel," indicating a positive, supportive stance toward Mr. Quilter's message.
+Answer: The speaker is talking about **Mr. Quilter**, who is described as “the apostle of the middle classes.” The speaker’s attitude is one of welcome and approval—“we’re glad to welcome his gospel,” indicating a positive, supportive stance toward Mr. Quilter’s message.
```
-## Tool calling
+
+
-This example turns one spoken request into two function calls: cancel a streaming-platform subscription at the end of the billing period, then subscribe to a podcast platform's Max plan with monthly billing. StreamBox and PodSpace are fictional services, and the example only prints the proposed calls.
+```python
+# Apply chat template
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
-List the tools in the system prompt, between `` and ``, one JSON object per line. The user asks by voice, and the model returns one `` block per call.
+with torch.inference_mode():
+ outputs = model.generate(**inputs, max_new_tokens=512)
-```python
-import json
-
-tools = [
- {
- "name": "cancel_subscription",
- "description": "Cancel the signed-in user's subscription to a streaming platform at the specified time.",
- "parameters": {
- "type": "object",
- "properties": {
- "platform": {"type": "string", "description": "Name of the streaming platform, for example StreamBox."},
- "effective_when": {
- "type": "string",
- "enum": ["immediately", "end_of_billing_period"],
- },
- },
- "required": ["platform", "effective_when"],
- },
- },
- {
- "name": "subscribe_to_podcast_platform",
- "description": "Subscribe the signed-in user to a podcast platform with the chosen plan and billing frequency.",
- "parameters": {
- "type": "object",
- "properties": {
- "platform": {"type": "string", "description": "Name of the podcast platform, for example PodSpace."},
- "plan": {"type": "string", "enum": ["basic", "plus", "max"]},
- "billing_frequency": {"type": "string", "enum": ["monthly", "annual"]},
- },
- "required": ["platform", "plan", "billing_frequency"],
- },
- },
-]
-tool_prompt = (
- "Return tool calls for both requested actions, in the order requested. "
- "Do not claim that an action has completed without a tool result.\n"
- "List of tools:\n\n" + "\n".join(json.dumps(t) for t in tools) + "\n"
-)
-
-# Record the spoken request
-_, request = generate(
- [
- {"role": "system", "content": "Perform TTS in British English using a female voice."},
- {"role": "user", "content": "Please cancel my StreamBox subscription starting December first. Then subscribe me to PodSpace on the Max plan, billed monthly."},
- ],
- prefill="<|audio_start|>",
- **SPEECH_SAMPLING,
-)
-sf.write("request.wav", request, SAMPLE_RATE_OUT)
-
-call, _ = generate(
- [
- {"role": "system", "content": tool_prompt},
- {"role": "user", "content": [{"type": "audio", "audio": "request.wav"}]},
- ],
- max_new_tokens=512,
- suppress_mixed=True,
- suppress_audio_out=True,
-)
-print(call)
+answer = processor.decode(outputs.sequences[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+print("Answer:", answer.strip())
```
**Output**
```text
-
-
-
-StreamBox
-
-
-end_of_billing_period
-
-
-
-
-
-
-PodSpace
-
-
-max
-
-
-monthly
-
-
-
+Answer: The speaker is talking about Mr. Quilter, whom he describes as the "apostle of the middle classes." His attitude is one of warm welcome and gladness, as he explicitly states, "And we're glad to welcome his gospel."
```
-Generated calls use the LFM3 `` XML format. Your application parses and executes the calls and returns the results as `tool` messages. See [Tool Use](/lfm/key-concepts/tool-use) for the full workflow. Don't prefill a thinking block for tool calls; the model calls tools without reasoning first.
+
+
-To get a spoken answer once the tool results are in, start the system prompt with `Respond with function calls, and interleaved text and audio.\n\n`, followed by any instructions and the tool list, and don't pass `suppress_mixed` or `suppress_audio_out`. The model then either calls tools or answers in interleaved text and speech. The model card's [tool calling example](https://huggingface.co/LiquidAI/LFM3-Audio-2B) shows the full loop, including returning tool results.
+For multiple choice, use the system prompt `Answer questions about the provided audio clip. Base every answer only on what can be heard.` and end the user turn with `Please choose the answer from the options.`
+
+```python
+messages = [
+ {"role": "system", "content": "Answer questions about the provided audio clip. Base every answer only on what can be heard."},
+ {"role": "user", "content": [
+ {"type": "audio", "audio": "librispeech.wav"},
+ {"type": "text", "text": "What does the speaker welcome?\nA. A new law\nB. Mr. Quilter's gospel\nC. A visiting choir\nD. The end of the middle classes\nPlease choose the answer from the options."},
+ ]},
+]
+
+# Apply chat template
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+with torch.inference_mode():
+ outputs = model.generate(**inputs, max_new_tokens=512)
+
+answer = processor.decode(outputs.sequences[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+print(answer)
+```
+
+**Output**
+
+```text
+Mr. Quilter's gospel
+```
## FAQ
**Which model should I use?**
-Use `LFM3-Audio-2B` for speech and audio tasks: transcription, speech synthesis, translation, spoken chat, audio understanding, and spoken tool calls. Use `LFM3-Omni-2B` when the request also involves images or video. See [Omni Capabilities](/lfm/key-concepts/omni-capabilities).
+Choose an audio model for speech-only tasks. Choose an omni model when the request also includes images or video, such as [a spoken question about a photo](/lfm/key-concepts/vision-capabilities#ask-about-an-image-by-voice) or [a video's soundtrack](/lfm/key-concepts/vision-capabilities#use-the-soundtrack).
**What audio input is supported?**
-Audio files are resampled to 16 kHz mono on load. Speech output is a 24 kHz waveform.
-
-**Can the model stream speech?**
-
-Yes. LFM3-Audio-2B uses a causal audio encoder that supports live audio input (see [Live speech recognition](#live-speech-recognition)), and its audio codec supports streaming decoding. In Transformers, pass `streamer` and `audio_streamer` to `model.generate()`.
+The processors in these examples resample audio files to 16 kHz mono on load.
**Does the model reason before answering?**
-For text-only answers, prefill `` to let the model reason first, or `` to answer directly.
+Some audio models can reason before answering. Where supported, prefill `` to request reasoning or `` to answer directly, as in [Speech-to-text chat](#speech-to-text-chat).
diff --git a/lfm/key-concepts/chat-template.mdx b/lfm/key-concepts/chat-template.mdx
index bd019753..62e9627c 100644
--- a/lfm/key-concepts/chat-template.mdx
+++ b/lfm/key-concepts/chat-template.mdx
@@ -1,27 +1,40 @@
---
title: "Chat Template"
-description: "The chat template defines how conversations are structured using special tokens and roles. LFM3 uses a ChatML-like chat template to structure conversations as follows:"
+description: "Learn how chat templates structure conversations with roles and special tokens for text, image, and audio messages."
---
-import { ChatMLExample } from "/snippets/key-concepts/chatml-example.mdx";
+import { LFM3ChatPrompt } from "/snippets/key-concepts/lfm3-chat-prompt.mdx";
+import { LFM25ChatPrompt } from "/snippets/key-concepts/lfm25-chat-prompt.mdx";
-```
-<|startoftext|><|im_start|>system
-You are a helpful assistant trained by Liquid AI.<|im_end|>
-<|im_start|>user
-Explain how a heat pump works.<|im_end|>
-<|im_start|>assistant
-
-```
+A chat template turns a conversation into the text the model reads. The examples below show how the template formats messages and generation prompts.
+
+## Message structure
+
+Compare the generation prompts for the same system message and user request:
+
+
+
+
+
+
+
+
+
+
+
+
+
Conversations are formatted using special tokens:
-* **`<|startoftext|>`** — Start of the conversation.
-* **`<|im_start|>`** — Start of the message. Always followed by the role name (`system`, `user`, `assistant`, or `tool`) and a line break.
-* **`<|im_end|>`** — End of the message.
-* **``** / **``** — Start and end of the model's reasoning, at the beginning of an assistant turn.
+| Special token | Meaning |
+|---|---|
+| `<\|startoftext\|>` | Start of the conversation. |
+| `<\|im_start\|>` | Start of the message. Always followed by the role name (`system`, `user`, `assistant`, or `tool`) and a line break. |
+| `<\|im_end\|>` | End of the message. |
+| `` / `` | Start and end of the model's reasoning, at the beginning of an assistant turn. See [Thinking](/lfm/key-concepts/thinking). |
-LFM3 supports four conversation roles:
+LFM models support four conversation roles:
* **`system`** — (Optional) Defines who the assistant is and how it should respond.
* **`user`** — Messages from the user containing questions and instructions.
@@ -30,10 +43,6 @@ LFM3 supports four conversation roles:
The complete chat template definition can be found in the `chat_template.jinja` file in each model's Hugging Face repository.
-
-Using LFM2 or LFM2.5? See [LFM2 and LFM2.5](#lfm2-and-lfm2-5) for their chat template.
-
-
## Text Models
We recommend storing your conversation as a list of dictionaries as follows:
@@ -41,11 +50,14 @@ We recommend storing your conversation as a list of dictionaries as follows:
```python
messages = [
{"role": "system", "content": "You are a helpful assistant trained by Liquid AI."},
- {"role": "user", "content": "Explain how a heat pump works."}
+ {"role": "user", "content": "What is C. elegans?"}
]
```
-You can then apply LFM3's chat template using the [`.apply_chat_template()`](https://huggingface.co/docs/transformers/main/en/chat_templating#using-applychattemplate) method from Transformers:
+You can then apply the model's chat template using the [`.apply_chat_template()`](https://huggingface.co/docs/transformers/main/en/chat_templating#using-applychattemplate) method from Transformers:
+
+
+
```python
from transformers import AutoTokenizer
@@ -61,29 +73,69 @@ prompt = tokenizer.apply_chat_template(
print(prompt)
```
-Output:
+**Output**
+
+
+
+
+
+```python
+from transformers import AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained("LiquidAI/LFM2.5-1.2B-Instruct")
+
+# Apply chat template
+prompt = tokenizer.apply_chat_template(
+ messages,
+ tokenize=False,
+ add_generation_prompt=True
+)
+print(prompt)
```
-<|startoftext|><|im_start|>system
-You are a helpful assistant trained by Liquid AI.<|im_end|>
-<|im_start|>user
-Explain how a heat pump works.<|im_end|>
-<|im_start|>assistant
-
-```
+
+**Output**
+
+
+
+
+
### Reasoning
+
+
+
Thinking models reason before they answer, so the template opens every assistant turn with ``. Two arguments to `apply_chat_template()` control this:
* **`enable_thinking`** (default `True`) — On models that can switch thinking off, `enable_thinking=False` fills in an empty `` block instead, so the model starts on the answer straight away. Models that always think don't support `False`.
* **`preserve_thinking`** (default `False`) — The template removes the reasoning from assistant turns before the latest user message. Set `preserve_thinking=True` to keep it in the prompt.
+
+
+
+LFM2.5 thinking models always think, and their templates have no `enable_thinking` argument. Depending on the model, the template opens the assistant turn with `` or the model writes it itself. Either way, the reply contains a closing `` before the answer.
+
+For LFM2.5-8B-A1B and LFM2.5-24B-A2B, reasoning before the latest user message is removed by default, while reasoning from later assistant turns stays. LFM2.5-1.2B-Thinking instead retains only the last assistant message's reasoning by default. Set `preserve_thinking=True` to retain reasoning from all assistant messages; LFM2.5-1.2B-Thinking also accepts the older name `keep_past_thinking`.
+
+
+
+
See [Thinking](/lfm/key-concepts/thinking) for how to use thinking, separate the reasoning from the answer, and check which models can switch thinking off.
## Vision Models
-LFM3-VL models follow the same chat template with additional support for images and videos. Each image is rendered as `<|vision_start|><|image|><|vision_end|>` and each video as `<|vision_start|><|video|><|vision_end|>`. The processor's `.apply_chat_template()` method inserts these tokens automatically, so do not include them in your message content.
+Vision models follow the same chat template with additional support for images. When creating conversations for vision models, use a structured format with `content` as a list containing image and text entries. You can then apply the chat template using the processor's `.apply_chat_template()` method.
+
+
+
+
+| Special token | Meaning |
+|---|---|
+| `<\|vision_start\|><\|image\|><\|vision_end\|>` | Each image is rendered as these tokens. |
+| `<\|vision_start\|><\|video\|><\|vision_end\|>` | Each video is rendered as these tokens. |
+
+The processor's `.apply_chat_template()` method inserts these tokens automatically, so do not include them in your message content.
```python
from transformers import AutoProcessor
@@ -110,9 +162,9 @@ prompt = processor.apply_chat_template(
print(prompt)
```
-Output:
+**Output**
-```
+```text
<|startoftext|><|im_start|>system
You are a helpful assistant trained by Liquid AI.<|im_end|>
<|im_start|>user
@@ -121,112 +173,128 @@ You are a helpful assistant trained by Liquid AI.<|im_end|>
```
-## Audio and Omni Models
+
+
+
+| Special token | Meaning |
+|---|---|
+| `` | When formatted, images are represented with this sentinel token, which is automatically replaced with image tokens by the processor. |
-LFM3-Omni follows the same chat template. Every input audio clip, image, and video sits inside a `<|vision_start|>` / `<|vision_end|>` span, which `apply_chat_template()` inserts for you. Audio clips render as `<|vision_start|><|audio|><|vision_end|>`.
+```python
+from transformers import AutoProcessor
+
+processor = AutoProcessor.from_pretrained("LiquidAI/LFM2.5-VL-1.6B")
+
+messages = [
+ {"role": "system", "content": "You are a helpful assistant trained by Liquid AI."},
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "url": "http://images.cocodataset.org/val2017/000000039769.jpg"},
+ {"type": "text", "text": "What species is in this picture?"},
+ ],
+ },
+]
+# Apply chat template
+prompt = processor.apply_chat_template(
+ messages,
+ tokenize=False,
+ add_generation_prompt=True
+)
+print(prompt)
```
+
+**Output**
+
+```text
<|startoftext|><|im_start|>system
-Perform ASR in English.<|im_end|>
+You are a helpful assistant trained by Liquid AI.<|im_end|>
<|im_start|>user
-<|vision_start|><|audio|><|vision_end|><|im_end|>
+What species is in this picture?<|im_end|>
<|im_start|>assistant
```
-In the answer, `<|audio_start|>` opens speech and `<|mixed_start|>` opens interleaved text and speech. LFM3-Omni-2B is a non-reasoning model: its template opens every assistant turn with an empty `` block. See [LFM3-Audio-2B](/lfm/models/lfm3-audio-2b) and [LFM3-Omni-2B](/lfm/models/lfm3-omni-2b) for the recommended system prompts.
-
-## LFM2 and LFM2.5
+
+
-LFM2 and LFM2.5 use a ChatML-like chat template. Unlike LFM3, most of their templates don't open the assistant turn with `` (see [LFM2.5 Thinking Models](#lfm2-5-thinking-models)):
+## Audio and Omni Models
-
+Audio and omni models follow the same chat template. The processor's `.apply_chat_template()` method inserts the audio tokens for you.
-### LFM2 Text Models
+| Special token | Meaning |
+|---|---|
+| `<\|audio\|>` | An input audio clip. Depending on the model, it sits inside a `<\|vision_start\|>` / `<\|vision_end\|>` span, like images and video. |
+| `<\|audio_start\|>` | Opens speech in the answer. |
+| `<\|mixed_start\|>` | Opens interleaved text and speech in the answer. |
+| `` | Empty block that the template of a non-reasoning model opens every assistant turn with. |
-We recommend storing your conversation as a list of dictionaries as follows:
+For example, an audio model and an omni model can format the same audio transcription request:
```python
messages = [
- {"role": "system", "content": "You are a helpful assistant."},
- {"role": "user", "content": "What is machine learning?"}
+ {"role": "system", "content": "Perform ASR in English."},
+ {"role": "user", "content": [{"type": "audio", "audio": "speech.wav"}]},
]
```
-You can then apply LFM2's chat template using the [`.apply_chat_template()`](https://huggingface.co/docs/transformers/main/en/chat_templating#using-applychattemplate) method from Transformers:
+
+
```python
-from transformers import AutoTokenizer
+from transformers import AutoProcessor
-tokenizer = AutoTokenizer.from_pretrained("LiquidAI/LFM2.5-1.2B-Instruct")
+processor = AutoProcessor.from_pretrained("LiquidAI/LFM3-Audio-2B", trust_remote_code=True)
# Apply chat template
-prompt = tokenizer.apply_chat_template(
+prompt = processor.apply_chat_template(
messages,
tokenize=False,
- add_generation_prompt=True
+ add_generation_prompt=True,
)
print(prompt)
```
-Output:
+**Output**
-```
+```text
<|startoftext|><|im_start|>system
-You are a helpful assistant.<|im_end|>
+Perform ASR in English.<|im_end|>
<|im_start|>user
-What is machine learning?<|im_end|>
+<|audio|><|im_end|>
<|im_start|>assistant
```
-### LFM2.5 Thinking Models
-
-LFM2.5 thinking models always think, and their templates have no `enable_thinking` argument. Depending on the model, the template opens the assistant turn with `` or the model writes it itself. Either way, the reply contains a closing `` before the answer.
-
-For LFM2.5-8B-A1B and LFM2.5-24B-A2B, reasoning before the latest user message is removed by default, while reasoning from later assistant turns stays. LFM2.5-1.2B-Thinking instead retains only the last assistant message's reasoning by default. Set `preserve_thinking=True` to retain reasoning from all assistant messages; LFM2.5-1.2B-Thinking also accepts the older name `keep_past_thinking`. See [Thinking](/lfm/key-concepts/thinking#multi-turn-conversations) for guidance on agent conversations.
-
-### LFM2 Vision Models
-
-LFM2-VL models follow the same chat template with additional support for images. When formatted, images are represented with a sentinel token (``), which is automatically replaced with image tokens by the processor.
-
-When creating conversations for vision models, use a structured format with `content` as a list containing image and text entries:
-
-```python
-image = load_image("path/to/image.jpg") # or use PIL Image
-
-messages = [
- {
- "role": "user",
- "content": [
- {"type": "image", "image": image}, # PIL Image or loaded image
- {"type": "text", "text": "What is in this image?"},
- ],
- },
-]
-```
-
-You can then apply the chat template using the processor's `.apply_chat_template()` method:
+
+
```python
from transformers import AutoProcessor
-from transformers.image_utils import load_image
-processor = AutoProcessor.from_pretrained("LiquidAI/LFM2.5-VL-1.6B")
+processor = AutoProcessor.from_pretrained("LiquidAI/LFM3-Omni-2B", trust_remote_code=True)
# Apply chat template
prompt = processor.apply_chat_template(
- conversation,
+ messages,
tokenize=False,
- add_generation_prompt=True
+ add_generation_prompt=True,
)
print(prompt)
```
-Output:
+**Output**
-```
+```text
<|startoftext|><|im_start|>system
-You are a helpful multimodal assistant by Liquid AI.<|im_end|>
+Perform ASR in English.<|im_end|>
<|im_start|>user
-What is in this image?<|im_end|>
+<|vision_start|><|audio|><|vision_end|><|im_end|>
<|im_start|>assistant
+
```
+
+
+
+
+See [Speech Generation](/lfm/key-concepts/speech-generation#choose-the-output-modality) for choosing the output modality, and [Audio Capabilities](/lfm/key-concepts/audio-capabilities) for recommended system prompts.
+
diff --git a/lfm/key-concepts/omni-capabilities.mdx b/lfm/key-concepts/omni-capabilities.mdx
deleted file mode 100644
index 0c6bdd5c..00000000
--- a/lfm/key-concepts/omni-capabilities.mdx
+++ /dev/null
@@ -1,438 +0,0 @@
----
-title: "Omni Capabilities"
-description: "Use LFM3-Omni to understand text, images, video, and audio in one model, and answer in text, speech, or interleaved text and speech."
----
-
-LFM3-Omni is a single end-to-end model that understands text, images, video, and audio, and answers in text, speech, or interleaved text and speech. One small model replaces a separate speech recognition model, vision-language model, LLM, and text-to-speech model.
-
-The examples below use [LFM3-Omni-2B](/lfm/models/lfm3-omni-2b) with Transformers. They cover:
-
-- **Speech:** recognition, synthesis, speech-to-text translation, and spoken chat
-- **Images:** captioning and visual question answering, asked in text or by voice, answered in text or speech
-- **Video:** questions about a clip, using the frames alone or the frames and their soundtrack
-- **Audio understanding:** open-ended and multiple-choice questions about a recording
-- **Tool calling:** function calls from an image and a spoken request
-- **Output control:** let the model choose its output modality, or force text, speech, or interleaved output
-
-For speech-only workloads, see [Audio Capabilities](/lfm/key-concepts/audio-capabilities).
-
-## Setup
-
-Install Transformers and the packages used by the examples. `torchcodec` decodes video and the soundtrack of a video. A GPU is recommended; the model runs in bfloat16.
-
-```bash
-pip install "transformers>=5.20.2" accelerate datasets torchcodec pillow librosa soundfile
-```
-
-The processor bundles the tokenizer, the image, video, and audio preprocessors, and the audio codec (`processor.audio_tokenizer`), which turns generated speech codes into a 24 kHz waveform.
-
-```python
-import torch
-from transformers import AutoModelForMultimodalLM, AutoProcessor
-
-model_id = "LiquidAI/LFM3-Omni-2B"
-device = "cuda" if torch.cuda.is_available() else "cpu"
-dtype = torch.bfloat16 if device == "cuda" else torch.float32
-
-model = AutoModelForMultimodalLM.from_pretrained(
- model_id, dtype=dtype, device_map=device, trust_remote_code=True
-).eval()
-processor = AutoProcessor.from_pretrained(model_id, trust_remote_code=True)
-codec = processor.audio_tokenizer.to(device=device).eval()
-```
-
-### Helper
-
-Every example below is a chat conversation. The helper renders it, loading any image, video, or audio it names, then generates and returns the text reply and the speech, if any.
-
-The model chooses its output modality itself, guided by the system prompt. Pass `generation_mode="text"`, `"audio"`, or `"interleaved"` to force one.
-
-Text output is greedy. Speech uses `audio_temperature=0.4`, `audio_repetition_penalty=1.2`, and `audio_repetition_window=64`. These are also the defaults in the model's `generation_config.json`; the helper passes them explicitly to keep the examples reproducible.
-
-```python
-import soundfile as sf
-
-SR = 24_000 # generated speech is 24 kHz
-
-
-@torch.inference_mode()
-def generate(conversation, generation_mode=None, max_new_tokens=512, **processor_kwargs):
- inputs = processor.apply_chat_template(
- conversation,
- add_generation_prompt=True,
- tokenize=True,
- return_dict=True,
- return_tensors="pt",
- processor_kwargs=processor_kwargs,
- ).to(model.device)
- out = model.generate(
- **inputs,
- max_new_tokens=max_new_tokens,
- generation_mode=generation_mode,
- audio_temperature=0.4,
- audio_repetition_penalty=1.2,
- audio_repetition_window=64,
- )
- prompt_len = inputs["input_ids"].shape[1]
- reply = processor.decode(out.sequences[0, prompt_len : out.sequence_lengths[0]], skip_special_tokens=True)
- speech = None
- if out.audio_lengths[0] > 0:
- speech = codec.decode(out.audio_codes[:1, :, : out.audio_lengths[0]]).audio_values[0].float().cpu().numpy().squeeze()
- return reply, speech
-```
-
-## Speech
-
-### Text-to-speech
-
-Use the system prompt `Perform TTS in {language} using a {female|male} voice.` and pass `generation_mode="audio"`. For English, say `American English` or `British English`. Supported languages: English (American and British), Arabic, Chinese, Danish, Dutch, Finnish, French, German, Greek, Hebrew, Italian, Japanese, Korean, Polish, Portuguese, Spanish, Swedish, and Turkish.
-
-```python
-torch.manual_seed(0)
-_, speech = generate([
- {"role": "system", "content": "Perform TTS in American English using a female voice."},
- {"role": "user", "content": "What is this tiny garden visitor doing?"},
-], generation_mode="audio")
-sf.write("question.wav", speech, SR)
-
-_, speech_de = generate([
- {"role": "system", "content": "Perform TTS in German using a male voice."},
- {"role": "user", "content": "Heute probieren wir etwas Neues: Wir malen Tiere mit geschlossenen Augen. Mein erster Versuch sieht aus wie eine Kartoffel mit Ohren."},
-], generation_mode="audio")
-sf.write("german.wav", speech_de, SR)
-```
-
-### Speech recognition
-
-Use the system prompt `Perform ASR in {language}.` Pass audio in the user turn as `{"type": "audio", "audio": }`. It's resampled to 16 kHz mono on load.
-
-```python
-for path, language in [("question.wav", "English"), ("german.wav", "German")]:
- transcript, _ = generate([
- {"role": "system", "content": f"Perform ASR in {language}."},
- {"role": "user", "content": [{"type": "audio", "audio": path}]},
- ])
- print(f"[{language}] {transcript}")
-```
-
-**Output**
-
-```text
-[English] What is this tiny garden visitor doing?
-[German] Heute probieren wir etwas Neues. Wir malen Tiere mit geschlossenen Augen. Mein erster Versuch sieht aus wie eine Kartoffel mit Ohren.
-```
-
-### Speech translation
-
-LFM3-Omni translates speech into text. Translation works best into or out of English. Name the source and target languages in the system prompt, for example `Convert the speech in {source} to written {target}.` or `Please translate the following spoken {source} into {target} text.` The model was trained on many phrasings, so pick the one that works best for your data.
-
-```python
-translation, _ = generate([
- {"role": "system", "content": "Convert the speech in German to written English."},
- {"role": "user", "content": [{"type": "audio", "audio": "german.wav"}]},
-])
-print("Translation:", translation)
-```
-
-**Output**
-
-```text
-Translation: Today we are trying something new. We paint animals with closed eyes. My first attempt looks like a potato with ears.
-```
-
-### Spoken chat
-
-Use the system prompt `Respond with interleaved text and audio.` The model answers with text and speech interleaved, so speech can start playing before the full answer is written. The question can be text or speech. Keep the system prompt exactly as shown, and give any further instructions in the user turn.
-
-```python
-reply, speech = generate(
- [
- {"role": "system", "content": "Respond with interleaved text and audio."},
- {"role": "user", "content": "I want to move more, but I have not found an activity I enjoy. How can I try a few options and build a small habit? Give me two practical ideas in short, friendly sentences."},
- ],
- max_new_tokens=1024,
-)
-print(reply)
-sf.write("reply.wav", speech, SR)
-```
-
-**Output** (text part; the speech is saved to `reply.wav`)
-
-```text
-Try a short walk in a new neighborhood each day and notice how it feels. Then pick a weekly community class that interests you and attend for a few sessions.
-```
-
-For plain text chat, use no system prompt, or `Respond with text.`
-
-```python
-reply, _ = generate([{"role": "user", "content": "Write a haiku about a small model that can see and hear."}])
-print(reply)
-```
-
-**Output**
-
-```text
-Tiny lens, keen eye,
-Hear the world in whispers,
-Small model, awake.
-```
-
-## Images
-
-Images are processed at their native resolution. Recommended system prompts: `Describe the provided image.` for captions, and `Answer questions about the provided image. Base every answer only on what can be seen.` for questions.
-
-```python
-from transformers.image_utils import load_image
-
-image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg")
-image.save("bee.jpg")
-
-caption, _ = generate([
- {"role": "system", "content": "Describe the provided image."},
- {"role": "user", "content": [{"type": "image", "image": "bee.jpg"}]},
-])
-print(caption)
-```
-
-**Output**
-
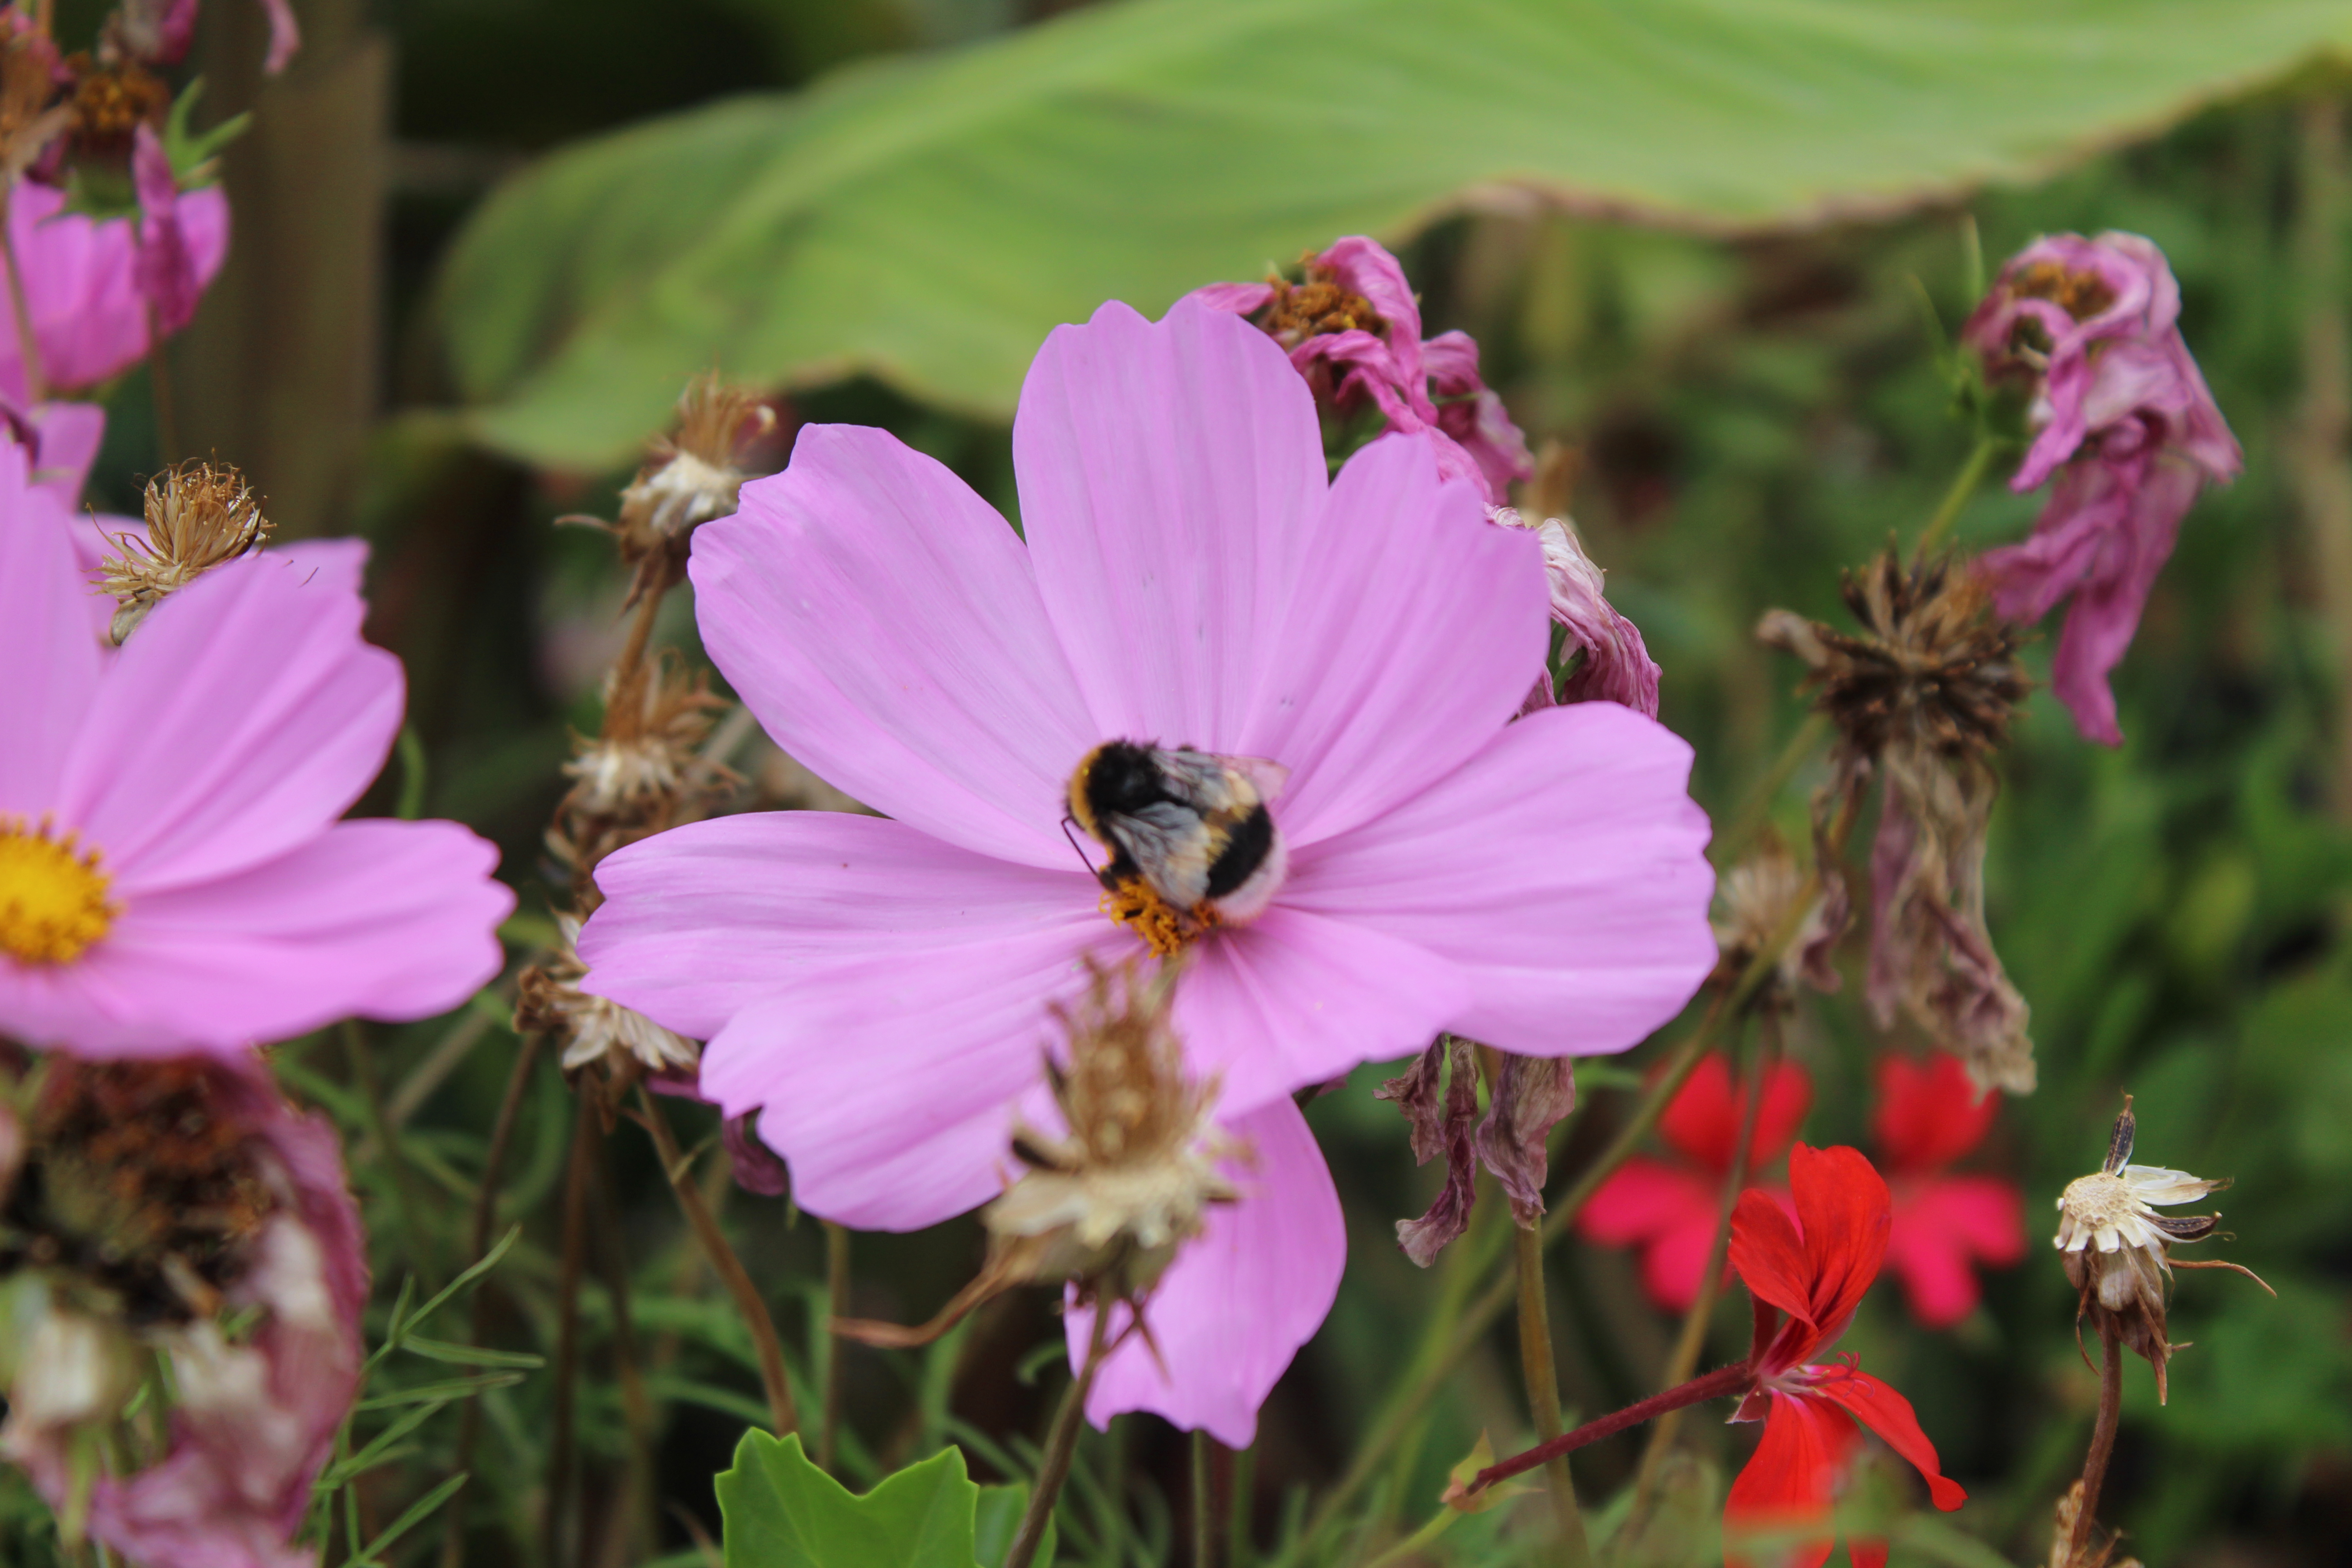
-
-
-```text
-This is a close‑up (macro) photograph of a garden scene dominated by pink cosmos flowers. The central subject is a fully open, light‑pink cosmos with five broad, slightly ruffled petals radiating from a bright yellow disc of stamens; perched right in the middle of that disc is a fuzzy bumblebee, black with a band of orange‑yellow on its thorax and pale, hairy wings, actively foraging on the orange center. To the left, a second, similar pink cosmos is in soft focus, its yellow center just visible, and behind it are several dried, brown, spent flower heads with withered petals. In the lower right, a small, vivid red cosmos blooms with its five pointed petals, accompanied by a small pale, withered bud on a thin reddish stem. The background is rendered in smooth, out‑of‑focus green, with a large, broad green leaf arcing across the top of the frame and finer green foliage filling the lower area, giving the image a shallow depth of field that isolates the pollinating bee and the pink bloom in sharp detail.
-```
-
-The question can also be asked by voice, with the recording in place of the text. This example uses the spoken question from the text-to-speech example. When the answer should be in a different modality from the question, add an output instruction after the task prompt, for example `Respond with text.`
-
-```python
-answer, _ = generate([
- {"role": "system", "content": "Answer questions about the provided image. Base every answer only on what can be seen. Respond with text."},
- {"role": "user", "content": [{"type": "image", "image": "bee.jpg"}, {"type": "audio", "audio": "question.wav"}]},
-])
-print(answer)
-```
-
-**Output**
-
-```text
-The tiny garden visitor is a **bee** (a bumblebee, identifiable by its black body with yellow-orange bands and fuzzy white abdomen) perched on the center of the pink cosmos flower. It is **feeding on the flower's nectar** — its head is positioned directly over the orange, pollen‑bearing center of the bloom, with its antennae extended toward the stamens as it collects nectar. In short, the bee is visiting the flower to feed on its nectar.
-```
-
-Or ask in text and get a spoken answer:
-
-```python
-answer, speech = generate([
- {"role": "system", "content": "Answer questions about the provided image. Base every answer only on what can be seen. Respond with interleaved text and audio."},
- {"role": "user", "content": [{"type": "image", "image": "bee.jpg"}, {"type": "text", "text": "Is this insect useful for the garden? Why?"}]},
-])
-print(answer)
-sf.write("bee_answer.wav", speech, SR)
-```
-
-**Output** (text part; the speech is saved to `bee_answer.wav`)
-
-```text
-Yes, this insect is useful for the garden because it is a bee, and bees pollinate flowers, helping plants reproduce and grow.
-```
-
-## Video
-
-Video is sampled at 2 frames per second. Consecutive frames are paired, and each pair is prefixed with its timestamp. Use the system prompt `Answer questions about the video using what you see and hear.`
-
-To include the soundtrack, pass `load_audio_from_video=True` and `use_audio_in_video=True`. The processor reads the video's audio track and interleaves it with the frames, so each pair of frames is followed by the sound that goes with it.
-
-```python
-from huggingface_hub import hf_hub_download
-
-video = hf_hub_download("raushan-testing-hf/videos-test", "sample_demo_1.mp4", repo_type="dataset")
-
-
-@torch.inference_mode()
-def ask_video(question, use_audio=False):
- extra = dict(load_audio_from_video=True, processor_kwargs={"use_audio_in_video": True}) if use_audio else {}
- inputs = processor.apply_chat_template(
- [
- {"role": "system", "content": "Answer questions about the video using what you see and hear."},
- {"role": "user", "content": [{"type": "video", "video": video}, {"type": "text", "text": question}]},
- ],
- add_generation_prompt=True, tokenize=True, return_dict=True, return_tensors="pt", **extra,
- ).to(model.device)
- out = model.generate(**inputs, max_new_tokens=256, generation_mode="text")
- return processor.decode(out.sequences[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
-
-
-print("Frames only:\n", ask_video("What happens in this video?"))
-print("\nFrames and soundtrack:\n", ask_video("What happens in this video, and what can you hear?", use_audio=True))
-```
-
-**Output** (frames only)
-
-
-
-```text
-The video shows a young toddler sitting on a bed and playing with an open book. The child, who has blonde hair, is wearing dark-framed glasses, a light blue sleeveless top, and pink pants, and is barefoot with legs stretched out on the bed. At the start, the child is looking down at the open book, then raises both hands and claps them together in a playful gesture. After a moment, the child lowers their hands, grabs the book with both hands, and begins turning the pages, flipping through the pages while continuing to look at them. The setting is a bedroom, with a crib visible in the background, a white blanket and clothing scattered on the bed, and a small framed photo on a surface to the right. A "clideo.com" watermark appears in the bottom right corner throughout the clip.
-```
-
-## Audio understanding
-
-Open-ended questions about sounds, music, and speech need no system prompt: put the audio and the question in the user turn.
-
-```python
-answer, _ = generate([
- {"role": "user", "content": [
- {"type": "audio", "audio": "german.wav"},
- {"type": "text", "text": "What language is spoken, is the speaker a man or a woman, and what is the message about?"},
- ]},
-])
-print(answer)
-```
-
-**Output**
-
-```text
-The speaker is speaking German. He is a man, and the message is an introduction to a new activity: painting animals with closed eyes. He begins by saying, "Today we try something new. We paint animals with closed eyes." He then adds, "My first attempt looks like a potato with ears," describing his initial result humorously.
-```
-
-For multiple choice, use the system prompt `Answer questions about the provided audio clip. Base every answer only on what can be heard.` and end the user turn with `Please choose the answer from the options.`
-
-```python
-answer, _ = generate([
- {"role": "system", "content": "Answer questions about the provided audio clip. Base every answer only on what can be heard."},
- {"role": "user", "content": [
- {"type": "audio", "audio": "german.wav"},
- {"type": "text", "text": "What activity does the speaker suggest?\nA. Cooking a new recipe\nB. Drawing animals with closed eyes\nC. Planting flowers\nD. Learning a dance\nPlease choose the answer from the options."},
- ]},
-])
-print(answer)
-```
-
-**Output**
-
-```text
-Drawing animals with closed eyes
-```
-
-## Tool calling
-
-This example shows the model a restaurant photo and asks by voice to book a table. The model reads the restaurant name from the sign and combines it with the city, date, time, party size, and reservation name from the spoken request. The example only prints the proposed call and doesn't make a reservation.
-
-Pass the `book_table` schema to `apply_chat_template()` with `tools=...`. The model returns the call between `` and ``.
-
-```python
-from datetime import date, timedelta
-from urllib.request import Request, urlopen
-from PIL import Image
-
-tools = [{
- "name": "book_table",
- "description": "Book a table at a restaurant using its name and city.",
- "parameters": {
- "type": "object",
- "properties": {
- "restaurant_name": {"type": "string"},
- "city": {"type": "string"},
- "date": {"type": "string", "description": "Local date, YYYY-MM-DD."},
- "time": {"type": "string", "description": "Local time, HH:MM in 24-hour format."},
- "party_size": {"type": "integer", "minimum": 1},
- "reservation_name": {"type": "string"},
- },
- "required": ["restaurant_name", "city", "date", "time", "party_size", "reservation_name"],
- },
-}]
-
-photo_url = "https://upload.wikimedia.org/wikipedia/commons/8/80/Cafe_de_Flore_Paris_France.jpg"
-with urlopen(Request(photo_url, headers={"User-Agent": "LFM3Cookbook"}), timeout=30) as response:
- Image.open(response).convert("RGB").save("restaurant.jpg")
-
-# Record the spoken request
-booking_date = date.today() + timedelta(days=7)
-_, spoken_request = generate([
- {"role": "system", "content": "Perform TTS in British English using a male voice."},
- {"role": "user", "content": f"Please book a table for two at this restaurant in Paris on {booking_date:%B %d, %Y} at seven in the evening, under Alex Taylor."},
-], generation_mode="audio")
-sf.write("request.wav", spoken_request, SR)
-
-inputs = processor.apply_chat_template(
- [
- {"role": "system", "content": "Use the tools to help the user complete their goal."},
- {"role": "user", "content": [
- {"type": "image", "image": "restaurant.jpg"},
- {"type": "audio", "audio": "request.wav"},
- ]},
- ],
- tools=tools, add_generation_prompt=True, tokenize=True, return_dict=True, return_tensors="pt",
-).to(model.device)
-with torch.inference_mode():
- out = model.generate(**inputs, max_new_tokens=512, generation_mode="text")
-print(processor.decode(out.sequences[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True))
-```
-
-**Output**
-
-
-
-Photo: [Café de Flore, Paris](https://commons.wikimedia.org/wiki/File:Cafe_de_Flore_Paris_France.jpg) by ayustety, [CC BY-SA 2.0](https://creativecommons.org/licenses/by-sa/2.0/).
-
-```text
-
-
-
-Café de Flore
-
-
-Paris
-
-
-2026-11-01
-
-
-19:00
-
-
-2
-
-
-Alex Taylor
-
-
-
-```
-
-Your application parses and executes the call and returns the result as a `tool` message. See [Tool Use](/lfm/key-concepts/tool-use) for the full workflow.
-
-## Output modality
-
-`generation_mode` overrides the output modality the model would choose on its own. Use `generation_mode="audio"` (speech only) for reading text aloud. For open-ended answers, prefer `"interleaved"`. This example answers the same question in text and in interleaved text and speech:
-
-```python
-conversation = [
- {"role": "user", "content": [{"type": "image", "image": "bee.jpg"}, {"type": "text", "text": "Describe this picture in one sentence."}]},
-]
-for mode in ["text", "interleaved"]:
- torch.manual_seed(0)
- reply, speech = generate(conversation, generation_mode=mode)
- print(f"{mode}: {reply}")
- if speech is not None:
- sf.write(f"{mode}.wav", speech, SR)
-```
-
-**Output**
-
-```text
-text: A bright pink cosmos flower, with a black-and-yellow bumblebee perched on its yellow center, is the sharp focal point of this close-up, surrounded by softly blurred pink blooms, dried brown flower heads, a single vivid red flower, and large green leaves in the background.
-interleaved: A bright pink cosmos flower with a fuzzy bumblebee perched on its yellow center is the focal point, surrounded by other pink blooms, a small red flower, and blurred green leaves in the background.
-```
-
-## FAQ
-
-**When should I use LFM3-Omni-2B instead of LFM3-Audio-2B?**
-
-Use LFM3-Omni-2B when a request involves images or video, such as spoken questions about a photo or questions about a video and its soundtrack. For speech-only workloads, use [LFM3-Audio-2B](/lfm/key-concepts/audio-capabilities).
-
-**What input formats are supported?**
-
-Audio files are resampled to 16 kHz mono on load. Images are processed at their native resolution. Video is sampled at 2 frames per second. Speech output is a 24 kHz waveform.
-
-**Does the model reason before answering?**
-
-No. LFM3-Omni-2B is a non-reasoning model.
diff --git a/lfm/key-concepts/speech-generation.mdx b/lfm/key-concepts/speech-generation.mdx
new file mode 100644
index 00000000..221dc7b5
--- /dev/null
+++ b/lfm/key-concepts/speech-generation.mdx
@@ -0,0 +1,351 @@
+---
+title: "Speech Generation"
+description: "Generate speech, carry on spoken conversations, and answer questions in text, speech, or both."
+---
+
+Speech-capable models can answer in text, speech, or interleaved text and speech. This guide covers text-to-speech, spoken chat, and spoken answers about images.
+
+Use an audio model for speech-only tasks. Use an omni model to [answer questions about a photo in speech](#answer-in-speech).
+
+The examples generate speech as a 24 kHz waveform. For speech input, see [Audio Capabilities](/lfm/key-concepts/audio-capabilities).
+
+## Setup
+
+Load the model and processor as shown in [Audio Capabilities](/lfm/key-concepts/audio-capabilities#setup). Where the code differs between audio and omni models, pick a model type in the tabs. The choice applies to every example on the page.
+
+Speech output uses each model's recommended sampling parameters. They are also the defaults in the model's `generation_config.json`; the examples pass them explicitly to keep the results reproducible. Check the model page for the values.
+
+## Choose the output modality
+
+
+
+
+Generation starts in text mode and switches to speech or interleaved output when the model emits an output-mode token. To select a mode from the start, prefill the assistant turn: add an assistant message with one of the prefixes below and pass `continue_final_message=True` to `apply_chat_template()`.
+
+| Assistant prefill | Behavior |
+|---|---|
+| None | Start in text mode. The model can still emit a token that switches modes. |
+| `<\|audio_start\|>` | Start speech-only output, for example text-to-speech, until an end-of-audio frame. |
+| `<\|mixed_start\|>` | Start interleaved text and speech, alternating blocks of text tokens and speech frames. |
+| `` | Begin a thinking block. The answer follows the closing ``. |
+| `` | Supply an empty thinking block, so the answer starts immediately. |
+
+The thinking prefixes are for text-only answers. For those, also pass `suppress_mixed=True` and `suppress_audio_out=True` to `model.generate()`, so the model doesn't switch to speech.
+
+
+
+
+The model chooses its output modality itself, guided by the system prompt. Pass `generation_mode` to `model.generate()` to override that choice: `"text"`, `"audio"` (speech only), or `"interleaved"`. Use `"audio"` for reading text aloud. For open-ended answers, prefer `"interleaved"`.
+
+
+
+
+## Text-to-speech
+
+Use the system prompt `Perform TTS in using a voice.` For English, say `American English` or `British English`.
+
+Check the model page for supported languages and voices.
+
+This example speaks a sentence in American English:
+
+```python
+messages = [
+ {"role": "system", "content": "Perform TTS in American English using a female voice."},
+ {"role": "user", "content": "I made a little plan for today: go for a walk, find a new workout playlist, and try a new cake recipe."},
+]
+```
+
+
+
+
+Prefill `<|audio_start|>`:
+
+```python
+# Apply chat template
+inputs = processor.apply_chat_template(
+ messages + [{"role": "assistant", "content": "<|audio_start|>"}],
+ continue_final_message=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+torch.manual_seed(0)
+with torch.inference_mode():
+ outputs = model.generate(
+ **inputs,
+ max_new_tokens=512,
+ audio_temperature=1.0,
+ audio_top_k=128,
+ audio_repetition_penalty=1.1,
+ audio_repetition_window=4096,
+ )
+
+codes = outputs.audio_codes[:1, :, : outputs.audio_lengths[0]]
+with torch.inference_mode():
+ speech = codec.decode(codes).audio_values[0].float().cpu().numpy().squeeze()
+sf.write("tts_en.wav", speech, 24_000)
+```
+
+
+
+
+Pass `generation_mode="audio"`:
+
+```python
+# Apply chat template
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+torch.manual_seed(0)
+with torch.inference_mode():
+ outputs = model.generate(
+ **inputs,
+ max_new_tokens=512,
+ generation_mode="audio",
+ audio_temperature=0.4,
+ audio_repetition_penalty=1.2,
+ audio_repetition_window=64,
+ )
+
+codes = outputs.audio_codes[:1, :, : outputs.audio_lengths[0]]
+with torch.inference_mode():
+ speech = codec.decode(codes).audio_values[0].float().cpu().numpy().squeeze()
+sf.write("tts_en.wav", speech, 24_000)
+```
+
+
+
+
+To check the result, pass the file to the [speech recognition](/lfm/key-concepts/audio-capabilities#speech-recognition) example.
+
+## Spoken chat
+
+Use the system prompt `Respond with interleaved text and audio.` The model answers conversationally in text and speech at the same time, so speech can start playing before the full answer is written. Keep the system prompt exactly as shown, and give any further instructions in the user turn.
+
+This example first records a spoken question with text-to-speech, then asks it and saves the spoken reply to `reply.wav`:
+
+```python
+tts_messages = [
+ {"role": "system", "content": "Perform TTS in American English using a male voice."},
+ {"role": "user", "content": "I want to move more, but I have not found an activity I enjoy. How can I try a few options and build a small habit?"},
+]
+messages = [
+ {"role": "system", "content": "Respond with interleaved text and audio."},
+ {"role": "user", "content": [{"type": "audio", "audio": "question.wav"}]},
+]
+```
+
+
+
+
+Record the question:
+
+```python
+# Apply chat template
+inputs = processor.apply_chat_template(
+ tts_messages + [{"role": "assistant", "content": "<|audio_start|>"}],
+ continue_final_message=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+torch.manual_seed(0)
+with torch.inference_mode():
+ outputs = model.generate(
+ **inputs,
+ max_new_tokens=512,
+ audio_temperature=1.0,
+ audio_top_k=128,
+ audio_repetition_penalty=1.1,
+ audio_repetition_window=4096,
+ )
+
+codes = outputs.audio_codes[:1, :, : outputs.audio_lengths[0]]
+with torch.inference_mode():
+ speech = codec.decode(codes).audio_values[0].float().cpu().numpy().squeeze()
+sf.write("question.wav", speech, 24_000)
+```
+
+Then ask it. Prefill `<|mixed_start|>`:
+
+```python
+# Apply chat template
+inputs = processor.apply_chat_template(
+ messages + [{"role": "assistant", "content": "<|mixed_start|>"}],
+ continue_final_message=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+with torch.inference_mode():
+ outputs = model.generate(
+ **inputs,
+ max_new_tokens=1024,
+ audio_temperature=1.0,
+ audio_top_k=128,
+ audio_repetition_penalty=1.1,
+ audio_repetition_window=4096,
+ )
+
+reply = processor.decode(outputs.sequences[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+print("Text:", reply)
+
+codes = outputs.audio_codes[:1, :, : outputs.audio_lengths[0]]
+with torch.inference_mode():
+ speech = codec.decode(codes).audio_values[0].float().cpu().numpy().squeeze()
+sf.write("reply.wav", speech, 24_000)
+```
+
+**Output** (text part; the speech is saved to `reply.wav`)
+
+```text
+Text: Try picking three low‑commitment activities you like, like a short hike, a cooking class, or a language meetup, and schedule a 30‑minute trial each week. Keep a simple log of what you did and how you felt, then after a month notice which one feels most rewarding and keep it. Does that sound doable for you?
+```
+
+
+
+
+
+Record the question:
+
+```python
+# Apply chat template
+inputs = processor.apply_chat_template(
+ tts_messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+torch.manual_seed(0)
+with torch.inference_mode():
+ outputs = model.generate(
+ **inputs,
+ max_new_tokens=512,
+ generation_mode="audio",
+ audio_temperature=0.4,
+ audio_repetition_penalty=1.2,
+ audio_repetition_window=64,
+ )
+
+codes = outputs.audio_codes[:1, :, : outputs.audio_lengths[0]]
+with torch.inference_mode():
+ speech = codec.decode(codes).audio_values[0].float().cpu().numpy().squeeze()
+sf.write("question.wav", speech, 24_000)
+```
+
+Then ask it. Pass `generation_mode="interleaved"`:
+
+```python
+# Apply chat template
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+with torch.inference_mode():
+ outputs = model.generate(
+ **inputs,
+ max_new_tokens=1024,
+ generation_mode="interleaved",
+ audio_temperature=0.4,
+ audio_repetition_penalty=1.2,
+ audio_repetition_window=64,
+ )
+
+reply = processor.decode(outputs.sequences[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+print("Text:", reply)
+
+codes = outputs.audio_codes[:1, :, : outputs.audio_lengths[0]]
+with torch.inference_mode():
+ speech = codec.decode(codes).audio_values[0].float().cpu().numpy().squeeze()
+sf.write("reply.wav", speech, 24_000)
+```
+
+**Output**
+
+```text
+Text: Gotcha, trying a few different things is a great way to find what clicks. You could pick two or three activities that sound interesting, schedule a short trial session each week, and note how you feel afterward. Keep a simple log of what you did and what you enjoyed, then after a couple of weeks look for patterns and pick one to make a habit of. And remember, it’s normal for the first few tries not to feel excited, so stay curious and give yourself space to explore.
+```
+
+
+
+
+## Answer in speech
+
+Spoken answers about images require an omni model with image input and speech output. Load it as shown in [Audio Capabilities](/lfm/key-concepts/audio-capabilities#setup).
+
+An omni model can answer a question about an image in speech. Add an output instruction after the task prompt, for example `Respond with interleaved text and audio.` This example asks in text about a sample photo:
+
+```python
+from transformers.image_utils import load_image
+
+load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg").save("bee.jpg")
+
+messages = [
+ {"role": "system", "content": "Answer questions about the provided image. Base every answer only on what can be seen. Respond with interleaved text and audio."},
+ {"role": "user", "content": [{"type": "image", "image": "bee.jpg"}, {"type": "text", "text": "Is this insect useful for the garden? Why?"}]},
+]
+
+# Apply chat template
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+with torch.inference_mode():
+ outputs = model.generate(
+ **inputs,
+ max_new_tokens=512,
+ audio_temperature=0.4,
+ audio_repetition_penalty=1.2,
+ audio_repetition_window=64,
+ )
+
+answer = processor.decode(outputs.sequences[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+print(answer)
+
+codes = outputs.audio_codes[:1, :, : outputs.audio_lengths[0]]
+with torch.inference_mode():
+ speech = codec.decode(codes).audio_values[0].float().cpu().numpy().squeeze()
+sf.write("bee_answer.wav", speech, 24_000)
+```
+
+**Output** (text part; the speech is saved to `bee_answer.wav`)
+
+```text
+Yes, this insect is useful for the garden because it is a bee, and bees pollinate flowers, helping plants reproduce and grow. They are essential for the health and productivity of many garden plants, including the cosmos and red flowers in the image.
+```
+
+## Stream speech
+
+For streaming applications, `model.generate()` accepts `streamer` for text tokens and `audio_streamer` for speech frames. The codec decodes those frames incrementally, so speech can be played as it is generated.
+
+## FAQ
+
+**Which model should I use?**
+
+Choose an audio model for speech-only workloads or an omni model when the spoken answer is about an image or a video. See the [model library](/lfm/models/complete-library) for current options.
+
+**What audio format is the speech output?**
+
+A 24 kHz mono waveform. The examples save it as WAV with `soundfile`.
+
+**Does the model reason before speaking?**
+
+The examples on this page do not use thinking for speech output. Check [Thinking](/lfm/key-concepts/thinking) for reasoning support and controls when requesting a text answer.
diff --git a/lfm/key-concepts/thinking.mdx b/lfm/key-concepts/thinking.mdx
index c480a31e..b4e6b7b9 100644
--- a/lfm/key-concepts/thinking.mdx
+++ b/lfm/key-concepts/thinking.mdx
@@ -19,6 +19,9 @@ Thinking is on by default for the models in the [support table](#thinking-models
### Text
+
+
+
```python
from transformers import AutoModelForCausalLM, AutoTokenizer
@@ -48,6 +51,43 @@ output_ids = model.generate(
text = tokenizer.decode(output_ids[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
```
+
+
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model_id = "LiquidAI/LFM2.5-1.2B-Thinking"
+model = AutoModelForCausalLM.from_pretrained(model_id, dtype="bfloat16", device_map="auto")
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+
+messages = [{"role": "user", "content": "A shop sells pens at $3 each or 4 for $10. What is the lowest cost for 11 pens?"}]
+
+# Apply chat template
+inputs = tokenizer.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+output_ids = model.generate(
+ **inputs,
+ do_sample=True,
+ temperature=0.05,
+ top_k=50,
+ repetition_penalty=1.05,
+ max_new_tokens=16384,
+)
+text = tokenizer.decode(output_ids[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+```
+
+Models that always think have no `enable_thinking` switch, so leave it out. See [Thinking models](#thinking-models).
+
+
+
+
`text` holds the reasoning followed by the answer. See [Separate the reasoning from the answer](#separate-the-reasoning-from-the-answer) to split them.
### Images and text
@@ -368,24 +408,20 @@ To switch thinking off, set `enable_thinking=False`. The chat template then fill
The table covers the text and vision thinking models discussed above. [LFM3-Audio-2B](/lfm/models/lfm3-audio-2b) also supports optional reasoning through an explicit assistant prefill; see [Speech-to-text chat](/lfm/key-concepts/audio-capabilities#speech-to-text-chat) for examples.
-For direct answers without reasoning, the following models are options:
-
-- **Text:** [LFM2.5-1.2B-Instruct](/lfm/models/lfm25-1.2b-instruct) for chat and general tasks, or [LFM2.5-350M](/lfm/models/lfm25-350m) and [LFM2.5-230M](/lfm/models/lfm25-230m) for extraction and lightweight on-device pipelines.
-- **Vision:** [LFM2.5-VL-1.6B](/lfm/models/lfm25-vl-1.6b) or [LFM2.5-VL-450M](/lfm/models/lfm25-vl-450m) for fast captioning and visual questions, and [LFM2.5-VL-3B](/lfm/models/lfm25-vl-3b) for document layout.
-- **Audio, video and speech:** [LFM3-Omni-2B](/lfm/models/lfm3-omni-2b).
+If you don't want reasoning, choose a non-thinking model from the [model library](/lfm/models/complete-library) for the modality and task you need.
## FAQ
-Not every model has a supported thinking-off switch. Use the controls documented for your model in the [support table](#thinking-models). LFM3-1.7B accepts `enable_thinking=False`, but answers in that mode can be inconsistent, especially on tasks that need reasoning. We recommend leaving thinking on and testing any change on your own task. If you need direct answers, consider the non-thinking alternatives listed below the table.
+Not every model has a supported thinking-off switch. Use the controls documented for your model in the [support table](#thinking-models). LFM3-1.7B accepts `enable_thinking=False`, but answers in that mode can be inconsistent, especially on tasks that need reasoning. We recommend leaving thinking on and testing any change on your own task. If you need direct answers, consider a non-thinking model from the [model library](/lfm/models/complete-library).
-Current LFM models have one thinking mode, with no effort levels and no trained thinking budget.
+The thinking models in the [model support table](#thinking-models) have one thinking mode, with no effort levels and no trained thinking budget.
-No chat template reads a reasoning-effort value, so options such as llama.cpp's `--reasoning-effort` don't change the output. llama.cpp's `--reasoning-budget N` with `N` greater than 0 cuts the reasoning off after `N` tokens. The models weren't trained for this, so test it on your task before you rely on it.
+Their chat templates don't read a reasoning-effort value, so options such as llama.cpp's `--reasoning-effort` don't change the output for these models. llama.cpp's `--reasoning-budget N` with `N` greater than 0 cuts the reasoning off after `N` tokens. These models weren't trained for this, so test it on your task before you rely on it.
diff --git a/lfm/key-concepts/tool-use.mdx b/lfm/key-concepts/tool-use.mdx
index c8647e86..b29a8a30 100644
--- a/lfm/key-concepts/tool-use.mdx
+++ b/lfm/key-concepts/tool-use.mdx
@@ -1,24 +1,49 @@
---
title: "Tool Use"
-description: "LFM3, LFM2.5, and LFM2 models support tool use (function calling), enabling models to interact with APIs, databases, and external services to provide accurate, up-to-date information."
+description: "Learn tool call formats, tool search for large catalogs, and function calling from text, images, and speech."
---
-import { ToolCallTokenExample } from "/snippets/key-concepts/tool-call-token-example.mdx";
+import { LFM3ToolCallExample } from "/snippets/key-concepts/lfm3-tool-call-example.mdx";
+import { LFM25ToolCallExample } from "/snippets/key-concepts/lfm25-tool-call-example.mdx";
+
+Tool calling (function calling) lets a compatible model use APIs, databases, and other external services to give accurate, up-to-date answers. The examples cover text, vision, audio, and omni models.
## Overview
The tool use workflow follows four steps:
-1. **Define** tools by passing them to [`.apply_chat_template()`](https://huggingface.co/docs/transformers/en/chat_extras#passing-tools) with `tools=...`. The template places them in the system prompt between `` and ``.
-2. **Generate** a response where the model writes each call between `` and ``, with the function name in a `` tag and each argument in a `` tag.
+1. **Define** tools by passing them to [`.apply_chat_template()`](https://huggingface.co/docs/transformers/en/chat_extras#passing-tools) with `tools=...`.
+2. **Generate** a response where the model writes each call in its tool call format.
3. **Execute** the function and return results as a `tool` role message.
4. **Regenerate** to let the model interpret results and respond to the user.
-
-LFM3's tool call format has changed from the custom LFM2/LFM2.5 format to a superset of `qwen3_coder`. Using LFM2 or LFM2.5? See [LFM2 and LFM2.5](#lfm2-and-lfm25).
-
+## Tool call format
+
+
+
+
+This format is a superset of `qwen3_coder`. The chat template places tool definitions in the system prompt between `` and ``. The model writes each call between `` and ``, with the function name in a `` tag and each argument in a `` tag:
+
+
+
+
+
+
+This format lists tool definitions in the system prompt. The model writes each call between `<|tool_call_start|>` and `<|tool_call_end|>`, as a Pythonic function call by default:
+
+
-## Complete Example
+Add "Output function calls as JSON" to your system prompt for JSON format. Depending on the model, the chat template also wraps tool definitions in `<|tool_list_start|>`/`<|tool_list_end|>` and tool responses in `<|tool_response_start|>`/`<|tool_response_end|>`.
+
+
+
+
+## Text Models
+
+This example runs the full workflow: define the tools, generate a tool call, execute it, and generate the final answer.
+
+
+
Start by loading the model and defining your tools and conversation:
@@ -79,15 +104,7 @@ response = tokenizer.decode(
After its reasoning, the model outputs a tool call in XML:
-```
-
-
-
-12345
-
-
-
-```
+
Parse the tool call and execute the function in your application. Add the parsed assistant call to history as a `tool_calls` entry, then append the result as a `tool` message. `function.arguments` must be a Python mapping, so decode JSON strings with `json.loads()` before applying the template.
@@ -111,62 +128,729 @@ messages.append({
messages.append({"role": "tool", "content": json.dumps(get_candidate_status("12345"))})
```
-Generate again, passing the same tool schemas, so the model can interpret the tool result and respond to the user. Keep the assistant's content and reasoning from the current tool-use turn in the history.
+Generate again, passing the same tool schemas, so the model can interpret the tool result and respond to the user. Keep the assistant's content and reasoning from the current tool-use turn in the history.
+
+```python
+inputs = tokenizer.apply_chat_template(
+ messages,
+ tools=tools,
+ add_generation_prompt=True,
+ return_dict=True,
+ return_tensors="pt"
+)
+
+outputs = model.generate(
+ **inputs.to(model.device),
+ do_sample=True,
+ temperature=0.1,
+ top_k=50,
+ repetition_penalty=1.1,
+ max_new_tokens=1024,
+)
+
+final = tokenizer.decode(
+ outputs[0][len(inputs["input_ids"][0]):],
+ skip_special_tokens=True
+)
+```
+
+The full conversation now looks like this:
+
+```text
+<|startoftext|><|im_start|>system
+
+{"name": "get_candidate_status", "description": "Retrieves the current status of a candidate in the recruitment process", "parameters": {...}}
+<|im_end|>
+<|im_start|>user
+What is the current status of candidate ID 12345?<|im_end|>
+<|im_start|>assistant
+The user wants the status of candidate 12345. I will call get_candidate_status.
+
+
+12345
+
+
+<|im_end|>
+<|im_start|>tool
+
+[{"candidate_id": "12345", "status": "Interview Scheduled", "position": "Clinical Research Associate", "date": "2023-11-20"}]
+<|im_end|>
+<|im_start|>assistant
+The tool says the interview is scheduled for 2023-11-20.The candidate with ID 12345 is currently in the "Interview Scheduled" stage for the position of Clinical Research Associate, with an interview date set for 2023-11-20.<|im_end|>
+```
+
+
+
+
+Start by loading the model and defining your tools and conversation:
+
+```python
+import json
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model = AutoModelForCausalLM.from_pretrained(
+ "LiquidAI/LFM2.5-1.2B-Instruct",
+ dtype="bfloat16",
+ device_map="auto"
+)
+tokenizer = AutoTokenizer.from_pretrained("LiquidAI/LFM2.5-1.2B-Instruct")
+
+tools = [{
+ "name": "get_candidate_status",
+ "description": "Retrieves the current status of a candidate in the recruitment process",
+ "parameters": {
+ "type": "object",
+ "properties": {
+ "candidate_id": {
+ "type": "string",
+ "description": "Unique identifier for the candidate",
+ }
+ },
+ "required": ["candidate_id"],
+ },
+}]
+
+messages = [
+ {"role": "system", "content": f"List of tools: {json.dumps(tools)}"},
+ {"role": "user", "content": "What is the current status of candidate ID 12345?"},
+]
+```
+
+Generate the first response. The model may decide to call a tool:
+
+```python
+# Apply chat template
+inputs = tokenizer.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ return_dict=True,
+ return_tensors="pt"
+)
+
+outputs = model.generate(
+ **inputs.to(model.device),
+ do_sample=True,
+ temperature=0.1,
+ top_k=50,
+ repetition_penalty=1.05,
+ max_new_tokens=256,
+)
+
+response = tokenizer.decode(
+ outputs[0][len(inputs["input_ids"][0]):],
+ skip_special_tokens=False
+)
+```
+
+The model outputs a tool call wrapped in special tokens:
+
+
+
+Parse the tool call and execute the function in your application. Add the model's response to the history, then append the result as a `tool` message:
+
+```python
+# Mock function (replace with actual API call in production)
+def get_candidate_status(candidate_id: str):
+ return [{
+ "candidate_id": candidate_id,
+ "status": "Interview Scheduled",
+ "position": "Clinical Research Associate",
+ "date": "2023-11-20",
+ }]
+
+messages.append({"role": "assistant", "content": response})
+messages.append({"role": "tool", "content": json.dumps(get_candidate_status("12345"))})
+```
+
+Generate again so the model can interpret the tool result and respond to the user:
+
+```python
+# Apply chat template
+inputs = tokenizer.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ return_dict=True,
+ return_tensors="pt"
+)
+
+outputs = model.generate(
+ **inputs.to(model.device),
+ do_sample=True,
+ temperature=0.1,
+ top_k=50,
+ repetition_penalty=1.05,
+ max_new_tokens=256,
+)
+
+final = tokenizer.decode(
+ outputs[0][len(inputs["input_ids"][0]):],
+ skip_special_tokens=True
+)
+```
+
+The full conversation now looks like this:
+
+```text
+<|startoftext|><|im_start|>system
+List of tools: [{"name": "get_candidate_status", ...}]<|im_end|>
+<|im_start|>user
+What is the current status of candidate ID 12345?<|im_end|>
+<|im_start|>assistant
+<|tool_call_start|>[get_candidate_status(candidate_id="12345")]<|tool_call_end|>
+Checking the current status of candidate ID 12345.<|im_end|>
+<|im_start|>tool
+[{"candidate_id": "12345", "status": "Interview Scheduled", ...}]<|im_end|>
+<|im_start|>assistant
+The candidate with ID 12345 is currently in the "Interview Scheduled" stage.<|im_end|>
+```
+
+
+
+
+With either model family, you can also pass Python functions with docstrings to `.apply_chat_template()` with `tools=...`. Transformers converts them to JSON schemas:
+
+```python
+def get_current_temperature(location: str, unit: str):
+ """
+ Get the current temperature at a location.
+
+ Args:
+ location: The location to get the temperature for, in the format "City, Country"
+ unit: The unit to return the temperature in. (choices: ["celsius", "fahrenheit"])
+ """
+ return 22.
+
+# Apply chat template
+inputs = tokenizer.apply_chat_template(
+ [{"role": "user", "content": "What's the weather in San Francisco?"}],
+ tools=[get_current_temperature],
+ add_generation_prompt=True,
+ return_dict=True,
+ return_tensors="pt"
+)
+```
+
+## Vision Models
+
+Vision models can use what they see to choose a tool and fill in its arguments. In this example, the model sees a photo of two cats and routes a request to the most relevant of two tools.
+
+This example shows how to define the tools and generate the tool call. Executing the call and generating the final answer work the same as in [Text Models](#text-models).
+
+Load the vision model as shown in [Vision Capabilities](/lfm/key-concepts/vision-capabilities#setup). This example uses the same image and request for both model families:
+
+
+
+```python
+from transformers.image_utils import load_image
+
+input_image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/coco_sample.png")
+messages = [{
+ "role": "user",
+ "content": [
+ {"type": "image", "image": input_image},
+ {"type": "text", "text": "Find a care guide for the animals in this image. Choose the best tool for this request."},
+ ],
+}]
+```
+
+
+
+
+Pass the tool schemas with `tools=...`:
+
+```python
+tools = [
+ {
+ "type": "function",
+ "function": {
+ "name": "search_pet_care",
+ "description": "Search for care guidance for an animal visible in an image.",
+ "parameters": {
+ "type": "object",
+ "properties": {
+ "animal": {"type": "string", "description": "The animal visible in the image"},
+ "topic": {"type": "string", "description": "The care topic to search for"},
+ },
+ "required": ["animal", "topic"],
+ },
+ },
+ },
+ {
+ "type": "function",
+ "function": {
+ "name": "search_replacement_remote",
+ "description": "Search for replacement remote controls or remote-control accessories visible in an image.",
+ "parameters": {
+ "type": "object",
+ "properties": {
+ "item": {"type": "string", "description": "The remote-control item to search for"},
+ "quantity": {"type": "integer", "description": "How many matching items are visible"},
+ },
+ "required": ["item"],
+ },
+ },
+ },
+]
+
+# Apply chat template
+inputs = processor.apply_chat_template(
+ messages,
+ tools=tools,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+with torch.inference_mode():
+ outputs = model.generate(
+ **inputs,
+ do_sample=True,
+ temperature=0.1,
+ top_k=50,
+ repetition_penalty=1.1,
+ max_new_tokens=8192,
+ )
+
+text = processor.decode(outputs[0, inputs["input_ids"].shape[1]:], skip_special_tokens=False)
+answer = text.partition("")[2].replace("<|im_end|>", "").strip()
+print(answer)
+```
+
+**Output**
+
+```text
+
+
+
+cat
+
+
+care
+
+
+
+```
+
+
+
+
+
+Pass the tool schemas with `tools=...`:
+
+```python
+tools = [
+ {
+ "name": "search_pet_care",
+ "description": "Search for care guidance for an animal visible in an image.",
+ "parameters": {
+ "type": "object",
+ "properties": {
+ "animal": {"type": "string", "description": "The animal visible in the image"},
+ "topic": {"type": "string", "description": "The care topic to search for"},
+ },
+ "required": ["animal", "topic"],
+ },
+ },
+ {
+ "name": "search_replacement_remote",
+ "description": "Search for replacement remote controls or remote-control accessories visible in an image.",
+ "parameters": {
+ "type": "object",
+ "properties": {
+ "item": {"type": "string", "description": "The remote-control item to search for"},
+ "quantity": {"type": "integer", "description": "How many matching items are visible"},
+ },
+ "required": ["item"],
+ },
+ },
+]
+
+# Apply chat template
+inputs = processor.apply_chat_template(
+ messages,
+ tools=tools,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+with torch.inference_mode():
+ outputs = model.generate(
+ **inputs,
+ do_sample=True,
+ temperature=0.2,
+ top_k=50,
+ repetition_penalty=1.0,
+ max_new_tokens=256,
+ )
+
+text = processor.decode(outputs[0, inputs["input_ids"].shape[1]:], skip_special_tokens=False)
+answer = text.replace("<|im_end|>", "").strip()
+print(answer)
+```
+
+**Output**
+
+```text
+<|tool_call_start|>[search_pet_care(animal='cat', topic='sleep')]<|tool_call_end|>
+```
+
+
+
+
+## Audio and Omni Models
+
+Spoken tool calls require an audio or omni model with tool-calling support. Load it as shown in [Audio Capabilities](/lfm/key-concepts/audio-capabilities#setup).
+
+Audio and omni models with tool-calling support can take spoken requests and return tool calls. This example turns one spoken request into two function calls: cancel a streaming-platform subscription at the end of the billing period, then subscribe to a podcast platform's Max plan with monthly billing. StreamBox and PodSpace are fictional services, and the example only prints the proposed calls.
+
+This example shows how to define the tools and generate the tool calls. Executing the calls and generating the final answer work the same as in [Text Models](#text-models).
+
+The example first records the spoken request with [text-to-speech](/lfm/key-concepts/speech-generation#text-to-speech). Define the request, the tools, and the instructions:
+
+```python
+import json
+
+tools = [
+ {
+ "name": "cancel_subscription",
+ "description": "Cancel the signed-in user's subscription to a streaming platform at the specified time.",
+ "parameters": {
+ "type": "object",
+ "properties": {
+ "platform": {"type": "string", "description": "Name of the streaming platform, for example StreamBox."},
+ "effective_when": {
+ "type": "string",
+ "enum": ["immediately", "end_of_billing_period"],
+ },
+ },
+ "required": ["platform", "effective_when"],
+ },
+ },
+ {
+ "name": "subscribe_to_podcast_platform",
+ "description": "Subscribe the signed-in user to a podcast platform with the chosen plan and billing frequency.",
+ "parameters": {
+ "type": "object",
+ "properties": {
+ "platform": {"type": "string", "description": "Name of the podcast platform, for example PodSpace."},
+ "plan": {"type": "string", "enum": ["basic", "plus", "max"]},
+ "billing_frequency": {"type": "string", "enum": ["monthly", "annual"]},
+ },
+ "required": ["platform", "plan", "billing_frequency"],
+ },
+ },
+]
+instructions = (
+ "Return tool calls for both requested actions, in the order requested. "
+ "Do not claim that an action has completed without a tool result."
+)
+
+tts_messages = [
+ {"role": "system", "content": "Perform TTS in British English using a female voice."},
+ {"role": "user", "content": "Please cancel my StreamBox subscription starting December first. Then subscribe me to PodSpace on the Max plan, billed monthly."},
+]
+```
+
+
+
+
+Record the request:
+
+```python
+# Apply chat template
+inputs = processor.apply_chat_template(
+ tts_messages + [{"role": "assistant", "content": "<|audio_start|>"}],
+ continue_final_message=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+torch.manual_seed(0)
+with torch.inference_mode():
+ outputs = model.generate(
+ **inputs,
+ max_new_tokens=512,
+ audio_temperature=1.0,
+ audio_top_k=128,
+ audio_repetition_penalty=1.1,
+ audio_repetition_window=4096,
+ )
+
+codes = outputs.audio_codes[:1, :, : outputs.audio_lengths[0]]
+with torch.inference_mode():
+ speech = codec.decode(codes).audio_values[0].float().cpu().numpy().squeeze()
+sf.write("request.wav", speech, 24_000)
+```
+
+List the tools in the system prompt, between `` and ``, one JSON object per line:
+
+```python
+messages = [
+ {
+ "role": "system",
+ "content": instructions + "\nList of tools:\n\n" + "\n".join(json.dumps(t) for t in tools) + "\n",
+ },
+ {"role": "user", "content": [{"type": "audio", "audio": "request.wav"}]},
+]
+
+# Apply chat template
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+with torch.inference_mode():
+ outputs = model.generate(**inputs, max_new_tokens=512, suppress_mixed=True, suppress_audio_out=True)
+
+call = processor.decode(outputs.sequences[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+print(call)
+```
+
+**Output**
+
+```text
+
+
+
+StreamBox
+
+
+end_of_billing_period
+
+
+
+
+
+
+PodSpace
+
+
+max
+
+
+monthly
+
+
+
+```
+
+Don't prefill a thinking block for tool calls; the model calls tools without reasoning first.
+
+To get a spoken answer once the tool results are in, start the system prompt with `Respond with function calls, and interleaved text and audio.\n\n`, followed by any instructions and the tool list, and don't pass `suppress_mixed` or `suppress_audio_out`. The model then either calls tools or answers in interleaved text and speech. The model card's [tool calling example](https://huggingface.co/LiquidAI/LFM3-Audio-2B) shows the full loop, including returning tool results.
+
+
+
+
+Record the request:
+
+```python
+# Apply chat template
+inputs = processor.apply_chat_template(
+ tts_messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+torch.manual_seed(0)
+with torch.inference_mode():
+ outputs = model.generate(
+ **inputs,
+ max_new_tokens=512,
+ generation_mode="audio",
+ audio_temperature=0.4,
+ audio_repetition_penalty=1.2,
+ audio_repetition_window=64,
+ )
+
+codes = outputs.audio_codes[:1, :, : outputs.audio_lengths[0]]
+with torch.inference_mode():
+ speech = codec.decode(codes).audio_values[0].float().cpu().numpy().squeeze()
+sf.write("request.wav", speech, 24_000)
+```
+
+Pass the tool schemas to `apply_chat_template()` with `tools=...`:
+
+```python
+messages = [
+ {"role": "system", "content": instructions},
+ {"role": "user", "content": [{"type": "audio", "audio": "request.wav"}]},
+]
+
+# Apply chat template
+inputs = processor.apply_chat_template(
+ messages,
+ tools=tools,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+with torch.inference_mode():
+ outputs = model.generate(**inputs, max_new_tokens=512, generation_mode="text")
+
+call = processor.decode(outputs.sequences[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+print(call)
+```
+
+**Output**
+
+```text
+
+
+
+StreamBox
+
+
+end_of_billing_period
+
+
+
+```
+
+**Image and speech together**
+
+An omni model can also combine what it sees and hears in one tool call. This example shows the model a restaurant photo and asks by voice to book a table. The model reads the restaurant name from the sign and combines it with the city, date, time, party size, and reservation name from the spoken request. The example only prints the proposed call and doesn't make a reservation.
+
+The example records the spoken request with a booking date one week from today:
+
+```python
+from datetime import date, timedelta
+
+booking_date = date.today() + timedelta(days=7)
+tts_messages = [
+ {"role": "system", "content": "Perform TTS in British English using a male voice."},
+ {"role": "user", "content": f"Please book a table for two at this restaurant in Paris on {booking_date:%B %d, %Y} at seven in the evening, under Alex Taylor."},
+]
+
+# Apply chat template
+inputs = processor.apply_chat_template(
+ tts_messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+torch.manual_seed(0)
+with torch.inference_mode():
+ outputs = model.generate(
+ **inputs,
+ max_new_tokens=512,
+ generation_mode="audio",
+ audio_temperature=0.4,
+ audio_repetition_penalty=1.2,
+ audio_repetition_window=64,
+ )
+
+codes = outputs.audio_codes[:1, :, : outputs.audio_lengths[0]]
+with torch.inference_mode():
+ speech = codec.decode(codes).audio_values[0].float().cpu().numpy().squeeze()
+sf.write("booking.wav", speech, 24_000)
+```
+
+Then show the photo and ask:
```python
-inputs = tokenizer.apply_chat_template(
+from urllib.request import Request, urlopen
+from PIL import Image
+
+tools = [{
+ "name": "book_table",
+ "description": "Book a table at a restaurant using its name and city.",
+ "parameters": {
+ "type": "object",
+ "properties": {
+ "restaurant_name": {"type": "string"},
+ "city": {"type": "string"},
+ "date": {"type": "string", "description": "Local date, YYYY-MM-DD."},
+ "time": {"type": "string", "description": "Local time, HH:MM in 24-hour format."},
+ "party_size": {"type": "integer", "minimum": 1},
+ "reservation_name": {"type": "string"},
+ },
+ "required": ["restaurant_name", "city", "date", "time", "party_size", "reservation_name"],
+ },
+}]
+
+photo_url = "https://upload.wikimedia.org/wikipedia/commons/8/80/Cafe_de_Flore_Paris_France.jpg"
+with urlopen(Request(photo_url, headers={"User-Agent": "LFM3Cookbook"}), timeout=30) as response:
+ Image.open(response).convert("RGB").save("restaurant.jpg")
+
+messages = [
+ {"role": "system", "content": "Use the tools to help the user complete their goal."},
+ {"role": "user", "content": [
+ {"type": "image", "image": "restaurant.jpg"},
+ {"type": "audio", "audio": "booking.wav"},
+ ]},
+]
+
+# Apply chat template
+inputs = processor.apply_chat_template(
messages,
tools=tools,
add_generation_prompt=True,
+ tokenize=True,
return_dict=True,
- return_tensors="pt"
-)
+ return_tensors="pt",
+).to(model.device)
-outputs = model.generate(
- **inputs.to(model.device),
- do_sample=True,
- temperature=0.1,
- top_k=50,
- repetition_penalty=1.1,
- max_new_tokens=1024,
-)
+with torch.inference_mode():
+ outputs = model.generate(**inputs, max_new_tokens=512, generation_mode="text")
-final = tokenizer.decode(
- outputs[0][len(inputs["input_ids"][0]):],
- skip_special_tokens=True
-)
+call = processor.decode(outputs.sequences[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+print(call)
```
-The full conversation now looks like this:
+**Output**
-```
-<|startoftext|><|im_start|>system
-
-{"name": "get_candidate_status", "description": "Retrieves the current status of a candidate in the recruitment process", "parameters": {...}}
-<|im_end|>
-<|im_start|>user
-What is the current status of candidate ID 12345?<|im_end|>
-<|im_start|>assistant
-The user wants the status of candidate 12345. I will call get_candidate_status.
-
-
-12345
+
+
+Photo: [Café de Flore, Paris](https://commons.wikimedia.org/wiki/File:Cafe_de_Flore_Paris_France.jpg) by ayustety, [CC BY-SA 2.0](https://creativecommons.org/licenses/by-sa/2.0/).
+
+```text
+
+
+
+Café de Flore
+
+
+Paris
+
+
+2026-11-20
+
+
+19:00
+
+
+2
+
+
+Alex Taylor
-<|im_end|>
-<|im_start|>tool
-
-[{"candidate_id": "12345", "status": "Interview Scheduled", "position": "Clinical Research Associate", "date": "2023-11-20"}]
-<|im_end|>
-<|im_start|>assistant
-The tool says the interview is scheduled for 2023-11-20.The candidate with ID 12345 is currently in the "Interview Scheduled" stage for the position of Clinical Research Associate, with an interview date set for 2023-11-20.<|im_end|>
+
```
+
+
+
## Defer Loading and Tool Search
+Check the model's chat template for deferred tools and `tool_reference` support before using this workflow.
+
Every tool definition in `` is part of the prompt. With a few tools that's fine, but an agent on a phone, in a car, or in a smart home may have hundreds or thousands of tools, far more than fit in the context window.
-LFM3 solves this with **deferred tools** and **tool search**:
+Models that support this workflow handle large tool catalogs with **deferred tools** and **tool search**:
- **Defer loading:** mark a tool with `"defer_loading": True`. The chat template leaves its definition out of the system prompt, but the tool stays in your `tools` list, so your application still knows its schema.
- **Tool search:** give the model one tool that is always loaded. We recommend naming it `search_tools`. When none of its loaded tools fit a request, the model calls the search tool. Your application runs the search and returns the matching tools as `tool_reference` parts. The chat template adds their definitions to the tool response inside ``, and the model can call them from then on.
@@ -176,15 +860,13 @@ This has two benefits:
- **Shorter prompts:** only the always-loaded tools are in the system prompt. Deferred tools enter the context only when the model needs them.
- **Stable prompt prefix:** discovered tools arrive in the tool response, so the system prompt never changes. Inference engines can keep reusing the cached prefix as the conversation grows.
-### How it works
+The workflow:
1. Pass all tools, deferred or not, in `tools` on every request. The chat template raises an error if a `tool_reference` names a tool that isn't in `tools`.
2. In the system prompt, tell the model when to search.
3. When the model calls the search tool, run your search and return a `tool` message with one `tool_reference` part per matching tool.
4. The model calls the discovered tool. Run it and return the result as usual.
-### Returning search results as `tool_reference`
-
When the model calls `search_tools`, return the matching tool names as `tool_reference` content parts. You can put text before them:
```python
@@ -216,8 +898,6 @@ Found 2 tools.
The model can now call `get_weather` like any other tool, in this turn and in later ones, without searching again.
-### Complete Example
-
This example uses a keyword search over a small catalog. In production, replace `search_catalog()` with your own search, for example over tool descriptions with an embedding model.
```python
@@ -314,7 +994,7 @@ for _ in range(5):
The system prompt lists only `search_tools`. After the search, the definition of `get_weather` appears in the tool response, and the model calls it:
-```
+```text
<|startoftext|><|im_start|>system
You only have one tool right now: search_tools, which searches a catalog of many more tools. If none of your current tools can handle a request, call search_tools to find one, then call the tool it returns.
@@ -354,18 +1034,7 @@ Edinburgh
If your search returns full tool definitions instead of names, pass them in the tool message's `additional_tools` field, for example `{"role": "tool", "additional_tools": [weather_schema]}`. The chat template renders them the same way.
-Defer loading works with vLLM, SGLang, and LFM3-compatible llama.cpp builds. For llama.cpp, use a GGUF with the current chat template or load it with `--chat-template-file`.
-
-## Vision, Audio, and Omni Models
-
-[LFM3-VL-2B](/lfm/models/lfm3-vl-2b), [LFM3-Audio-2B](/lfm/models/lfm3-audio-2b), and [LFM3-Omni-2B](/lfm/models/lfm3-omni-2b) use the same tool call format. Pass the tool list to the processor's `.apply_chat_template()` with `tools=...`. With LFM3-Audio-2B and LFM3-Omni-2B, the user can ask in text or in speech, and the model can also respond with text or speech alongside its tool calls:
-
-```python
-inputs = processor.apply_chat_template(
- [{"role": "user", "content": "What's the weather in Boston?"}],
- tools=tools, add_generation_prompt=True, tokenize=True, return_dict=True, return_tensors="pt",
-).to(model.device)
-```
+Defer loading works with vLLM, SGLang, and compatible llama.cpp builds. For llama.cpp, use a GGUF with the current chat template or load it with `--chat-template-file`.
## Best Practices
@@ -373,220 +1042,4 @@ Tool definitions consume context tokens since they're inserted as text. For larg
To manage this effectively, only include tools relevant to the current request. Write clear, concise descriptions. Group related tools and remove unused ones when they're not needed.
-With LFM3, use [defer loading and tool search](#defer-loading-and-tool-search) for large tool catalogs, so only the tools the model needs enter the context.
-
-## LFM2 and LFM2.5
-
-The tool use workflow follows four steps:
-
-1. **Define** tools as JSON in the system prompt or via [`.apply_chat_template()`](https://huggingface.co/docs/transformers/en/chat_extras#passing-tools)
-2. **Generate** a response where the model outputs function calls between special tokens
-3. **Execute** the function and return results as a `tool` role message
-4. **Regenerate** to let the model interpret results and respond to the user
-
-LFM2.5 wraps tool calls in `<|tool_call_start|>` and `<|tool_call_end|>` tokens. LFM2 additionally wraps tool definitions in `<|tool_list_start|>`/`<|tool_list_end|>` and responses in `<|tool_response_start|>`/`<|tool_response_end|>`.
-
-By default, models generate Pythonic function calls. Add "Output function calls as JSON" to your system prompt for JSON format.
-
-### LFM2 Defining Tools
-
-You have two options for providing tool definitions.
-
-**Option 1: JSON in the system prompt (recommended)**
-
-```python
-tools_json = [{
- "name": "get_candidate_status",
- "description": "Retrieves the current status of a candidate in the recruitment process",
- "parameters": {
- "type": "object",
- "properties": {
- "candidate_id": {
- "type": "string",
- "description": "Unique identifier for the candidate"
- }
- },
- "required": ["candidate_id"]
- }
-}]
-
-messages = [
- {"role": "system", "content": f"List of tools: {json.dumps(tools_json)}"},
- {"role": "user", "content": "What is the current status of candidate ID 12345?"}
-]
-```
-
-**Option 2: Python functions via [`.apply_chat_template()`](https://huggingface.co/docs/transformers/en/chat_extras#passing-tools)**
-
-```python
-def get_current_temperature(location: str, unit: str):
- """
- Get the current temperature at a location.
-
- Args:
- location: The location to get the temperature for, in the format "City, Country"
- unit: The unit to return the temperature in. (choices: ["celsius", "fahrenheit"])
- """
- return 22.
-
-messages = [{"role": "user", "content": "What's the weather in San Francisco?"}]
-
-inputs = tokenizer.apply_chat_template(
- messages,
- tools=[get_current_temperature],
- add_generation_prompt=True,
- return_dict=True,
- return_tensors="pt"
-)
-```
-
-### LFM2 Complete Example
-
-Start by loading the model and defining your tools and conversation:
-
-```python
-import json
-from transformers import AutoModelForCausalLM, AutoTokenizer
-
-model = AutoModelForCausalLM.from_pretrained(
- "LiquidAI/LFM2.5-1.2B-Instruct",
- dtype="bfloat16",
- device_map="auto"
-)
-tokenizer = AutoTokenizer.from_pretrained("LiquidAI/LFM2.5-1.2B-Instruct")
-
-tools = [{
- "name": "get_candidate_status",
- "description": "Retrieves the current status of a candidate in the recruitment process",
- "parameters": {
- "type": "object",
- "properties": {
- "candidate_id": {
- "type": "string",
- "description": "Unique identifier for the candidate",
- }
- },
- "required": ["candidate_id"],
- },
-}]
-
-messages = [
- {"role": "system", "content": f"List of tools: {json.dumps(tools)}"},
- {"role": "user", "content": "What is the current status of candidate ID 12345?"},
-]
-```
-
-Generate the first response. The model may decide to call a tool:
-
-```python
-inputs = tokenizer.apply_chat_template(
- messages,
- add_generation_prompt=True,
- return_dict=True,
- return_tensors="pt"
-)
-
-outputs = model.generate(**inputs.to(model.device), max_new_tokens=256)
-
-response = tokenizer.decode(
- outputs[0][len(inputs["input_ids"][0]):],
- skip_special_tokens=False
-)
-```
-
-The model outputs a tool call wrapped in special tokens:
-
-
-
-Parse the tool call and execute the function externally. Here we use a mock function that simulates what would typically be an API call to your recruitment system:
-
-```python
-# Mock function (replace with actual API call in production)
-def get_candidate_status(candidate_id: str):
- return [{
- "candidate_id": candidate_id,
- "status": "Interview Scheduled",
- "position": "Clinical Research Associate",
- "date": "2023-11-20",
- }]
-
-messages.append({"role": "assistant", "content": response})
-messages.append({"role": "tool", "content": json.dumps(get_candidate_status("12345"))})
-```
-
-Generate again so the model can interpret the tool result and respond to the user:
-
-```python
-inputs = tokenizer.apply_chat_template(
- messages,
- add_generation_prompt=True,
- return_dict=True,
- return_tensors="pt"
-)
-
-outputs = model.generate(**inputs.to(model.device), max_new_tokens=256)
-
-final = tokenizer.decode(
- outputs[0][len(inputs["input_ids"][0]):],
- skip_special_tokens=True
-)
-```
-
-The full conversation now looks like this:
-
-```
-<|startoftext|><|im_start|>system
-List of tools: [{"name": "get_candidate_status", ...}]<|im_end|>
-<|im_start|>user
-What is the current status of candidate ID 12345?<|im_end|}
-<|im_start|>assistant
-<|tool_call_start|>[get_candidate_status(candidate_id="12345")]<|tool_call_end|>
-Checking the current status of candidate ID 12345.<|im_end|>
-<|im_start|>tool
-[{"candidate_id": "12345", "status": "Interview Scheduled", ...}]<|im_end|>
-<|im_start|>assistant
-The candidate with ID 12345 is currently in the "Interview Scheduled" stage.<|im_end|>
-```
-
-### LFM2 Vision Models
-
-LFM2-VL and LFM2.5-VL vision models support text-only function calling. Use the tokenizer from the processor:
-
-```python
-from transformers import AutoProcessor, AutoModelForImageTextToText
-
-processor = AutoProcessor.from_pretrained("LiquidAI/LFM2.5-VL-1.6B")
-model = AutoModelForImageTextToText.from_pretrained(
- "LiquidAI/LFM2.5-VL-1.6B",
- device_map="auto",
- dtype="bfloat16"
-)
-
-tools = [{
- "name": "get_weather",
- "description": "Get current weather for a location",
- "parameters": {
- "type": "object",
- "properties": {"location": {"type": "string"}},
- "required": ["location"]
- }
-}]
-
-messages = [{"role": "user", "content": "What's the weather in Paris?"}]
-
-inputs = processor.tokenizer.apply_chat_template(
- messages,
- tools=tools,
- add_generation_prompt=True,
- return_tensors="pt",
- return_dict=True,
-)
-
-input_ids = inputs["input_ids"].to(model.device)
-outputs = model.generate(input_ids, max_new_tokens=256)
-
-response = processor.tokenizer.decode(
- outputs[0, input_ids.shape[1]:],
- skip_special_tokens=False
-)
-```
+Where supported, use [defer loading and tool search](#defer-loading-and-tool-search) for large tool catalogs, so only the tools the model needs enter the context.
diff --git a/lfm/key-concepts/vision-capabilities.mdx b/lfm/key-concepts/vision-capabilities.mdx
index ddfdef72..6418f962 100644
--- a/lfm/key-concepts/vision-capabilities.mdx
+++ b/lfm/key-concepts/vision-capabilities.mdx
@@ -1,31 +1,28 @@
---
title: "Vision Capabilities"
-description: "Use LFM3-VL and LFM2.5-VL models for image and video understanding, multi-image prompting, OCR, layout annotations, pointing, grounding, and vision-guided tool calling."
+description: "Describe images and videos, compare images, read text, parse layouts, and locate objects."
---
-LFM vision models' capabilities enable the model to analyze and understand images and, with LFM3-VL, videos.
-These models support common vision-language tasks such as describing images, answering questions about visual content, comparing multiple images, reading text, and localizing objects. They also support tool calling, including examples where an image helps determine the tool arguments.
+Vision models analyze images and video. They describe scenes, answer questions about visual content, compare images, read text, and locate objects. Omni models can also take a spoken question about an image or use a video's soundtrack.
-LFM3-VL is the latest generation: it reasons step by step before answering, takes video as input, and points at objects natively. The examples below show how to send images and videos to LFM3-VL models.
+Pick a model family in the tabs below. The choice applies to every example on the page.
-
-Using LFM2.5-VL? See [LFM2.5-VL](#lfm25-vl) for its examples, including document layout annotations.
-
+For tool calls based on an image, see [Tool Use](/lfm/key-concepts/tool-use#vision-models).
-Install PyTorch, Transformers, and the image and video packages used by the examples. `torchvision` and `Pillow` are required by the LFM3-VL image processor, and `torchcodec` decodes videos. `torchcodec` needs FFmpeg.
+## Setup
-```python
-# Install PyTorch and acceleration libraries
-%pip install -q torch torchvision torchcodec accelerate
+Install PyTorch, Transformers, and the image packages used by the examples. `torchvision` and `Pillow` are required by the image processor, and `opencv-python` draws the layout boxes.
+
+The examples use the recommended sampling parameters for the model shown. For another model, use the values from its model page.
-# Install image helper libraries
-%pip install -q pillow
+
+
-# Install Transformers
-%pip install -q "transformers>=5.21.0"
+```python
+%pip install -q torch torchvision accelerate pillow opencv-python "transformers>=5.21.0"
```
-Load the model with `AutoProcessor` and `AutoModelForImageTextToText`. LFM3-VL ships its model code in the checkpoint, so pass `trust_remote_code=True`.
+Load the model with `AutoProcessor` and `AutoModelForImageTextToText`:
```python
import torch
@@ -42,41 +39,40 @@ model = AutoModelForImageTextToText.from_pretrained(
)
```
-LFM3-VL thinks in a `` block before it answers, and reasoning can be long. The helper below generates with the recommended sampling parameters (`temperature=0.1`, `top_k=50`, `repetition_penalty=1.1`), then splits the reasoning from the answer.
+Thinking models reason in a `` block before they answer, so the examples in this tab leave room for long outputs and split the reasoning from the answer. See [Thinking](/lfm/key-concepts/thinking) for details.
+
+
+
+
+```python
+%pip install -q torch torchvision accelerate pillow opencv-python "transformers>=5.10.1"
+```
+
+Load the model with `AutoProcessor` and `AutoModelForImageTextToText`:
```python
-def generate(messages, max_new_tokens=8192, **template_kwargs):
- inputs = processor.apply_chat_template(
- messages,
- add_generation_prompt=True,
- tokenize=True,
- return_dict=True,
- return_tensors="pt",
- **template_kwargs,
- ).to(model.device)
-
- with torch.inference_mode():
- outputs = model.generate(
- **inputs,
- do_sample=True,
- temperature=0.1,
- top_k=50,
- repetition_penalty=1.1,
- max_new_tokens=max_new_tokens,
- )
-
- text = processor.decode(outputs[0, inputs["input_ids"].shape[1]:], skip_special_tokens=False)
- text = text.replace("<|im_end|>", "").strip()
- reasoning, separator, answer = text.partition("")
- if not separator:
- return "", text
- return reasoning.replace("", "").strip(), answer.strip()
+import torch
+from transformers import AutoProcessor, AutoModelForImageTextToText
+
+MODEL_ID = "LiquidAI/LFM2.5-VL-3B"
+
+processor = AutoProcessor.from_pretrained(MODEL_ID)
+model = AutoModelForImageTextToText.from_pretrained(
+ MODEL_ID,
+ device_map="auto",
+ dtype="bfloat16",
+)
```
+
+
+
## Single-image prompt
Provide one image and a text question in the same user message. This pattern is useful for captioning, visual question answering, and scene understanding.
+
+
```python
from transformers.image_utils import load_image
@@ -92,61 +88,100 @@ messages = [
],
}
]
+```
+
+
+
-reasoning, answer = generate(messages)
-print("Reasoning:\n", reasoning, "\n")
-print("Answer:\n", answer)
+```python
+# Apply chat template
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+with torch.inference_mode():
+ outputs = model.generate(
+ **inputs,
+ do_sample=True,
+ temperature=0.1,
+ top_k=50,
+ repetition_penalty=1.1,
+ max_new_tokens=8192,
+ )
+
+text = processor.decode(outputs[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+reasoning, _, answer = text.partition("")
+print("Reasoning:\n", reasoning.replace("", "").strip(), "\n")
+print("Answer:\n", answer.strip())
```
**Output**
-
-
```text
Reasoning:
The user wants a concise description of the image, limited to two sentences. I need to observe the key elements: two tabby cats sleeping on a pink/magenta surface (likely a couch or blanket), and two remote controls nearby. Let me look carefully.
Left cat: stretched out, head near a white remote control, eyes closed, lying on its side/back with paws extended. Right cat: larger, also tabby, curled/stretched with head down, near another remote control. The background is a bright pink fabric/couch.
-I should produce two concise sentences capturing these details without over-explaining. Avoid listing every detail; keep it tight.
+I should produce two concise sentences capturing these details without over-explaining. Avoid speculation beyond what's visible. Mention the remotes as a quirky detail.
-Draft: "Two tabby cats are asleep on a bright pink couch or blanket, each stretched out in a relaxed pose. A white remote control lies near the smaller cat's head, while a second remote rests between the two cats."
+Draft: "Two tabby cats are asleep on a bright pink couch or blanket, each stretched out in a relaxed pose. A white remote control lies near the smaller cat on the left, while a second remote rests between the two cats."
-That's two sentences, accurate and concise. Good.
+That's two sentences, accurate and concise. Good.
Answer:
- Two tabby cats are curled up asleep on a vivid pink couch or blanket, each stretched out in a relaxed, sprawling pose. A white remote control lies beside the smaller cat's head, with a second remote resting between the two cats.
+ Two tabby cats are curled up asleep on a vivid pink couch or blanket, each stretched out in a relaxed, sprawling pose. A white remote control lies beside the smaller cat on the left, with a second remote resting between the two cats.
```
-## Answer without reasoning
-
-For simple questions, set `enable_thinking=False` to skip the reasoning and get a direct answer with lower latency.
+
+
```python
-messages = [
- {
- "role": "user",
- "content": [
- {"type": "image", "image": input_image},
- {"type": "text", "text": "How many cats are in this image? Answer with a number."},
- ],
- }
-]
+# Apply chat template
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
-_, answer = generate(messages, enable_thinking=False)
+with torch.inference_mode():
+ outputs = model.generate(
+ **inputs,
+ do_sample=True,
+ temperature=0.2,
+ top_k=50,
+ repetition_penalty=1.0,
+ max_new_tokens=256,
+ )
+
+answer = processor.decode(outputs[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
print(answer)
```
**Output**
```text
-2
+Two cats are sleeping on a pink couch next to two remote controls.
```
+
+
+
## Multi-image prompt
You can include multiple images in a single prompt. Label each image in the prompt, such as `Media-1` and `Media-2`, to make cross-image references clearer.
+
+
+
+
+
```python
img_urls = [
"https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/p-blog/candy.JPG",
@@ -166,332 +201,49 @@ messages = [
],
}
]
-
-_, answer = generate(messages)
-print(answer)
-```
-
-## OCR
-
-LFM3-VL can read text in document images and screenshots.
-
-```python
-img_url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/enterprise/audit-logs.png"
-document_image = load_image(img_url)
-
-messages = [
- {
- "role": "user",
- "content": [
- {"type": "image", "image": document_image},
- {
- "type": "text",
- "text": "Read this audit log screenshot. Identify the page heading, table columns, visible rows, users, actions, timestamps, and other structured fields. Transcribe the visible text in reading order.",
- },
- ],
- }
-]
-
-_, answer = generate(messages)
-print(answer)
-```
-
-**Output** (truncated)
-
-
-
-```text
-**Page Heading:** Audit log
-
-**Table / Section Header:** Events log *(with a “Download as JSON” button on the right)*
-
-...
-
-**Visible Rows (in reading order):**
-
-1. **clboetticher** — `org.update_join_settings`
- - *Action:* enabled join requests with manual approval and set default role to write
- - *Location:* United States, Austin · *ID:* 136.62.181.0 · *On Oct 15*
-
-2. **clboetticher** — `repo.delete`
- - *Action:* deleted a model: enterprise-explorers/test_model
- - *Location:* United States, Austin · *ID:* 136.62.181.0 · *On Oct 10*
-
-3. **clboetticher** — `repo.create`
- - *Action:* created a public model: enterprise-explorers/test_model
- - *Location:* United States, Austin · *ID:* 136.62.181.0 · *On Oct 10*
-
-4. **System** — `billing.renew_subscription`
- - *Action:* System Automatic subscription renewal for hf/enterprise-free
- - *Location:* Unknown Location · *On Oct 7*
-
-5. **derek-thomas** — `resource_group.add_users`
- - *Action:* added users to resource group Read access members: derek-thomas (read)
- - *Location:* United Arab Emirates, Abu Dhabi · *ID:* 217.164.173.0 · *On Sep 17*
-
-6. **erikrigner** — `resource_group.change_role`
- - *Action:* changed role for user erikrigner in resource group Read access members from write to admin
- - *Location:* Sweden, Norrköping · *ID:* 2a02:1406:59d60:1dfd:0:0 · *On Sep 16*
-
-...
-```
-
-## Pointing
-
-Pointing asks the model to locate visible objects with a single point each. LFM3-VL points natively as `{"point_2d": [x, y]}`, with `x` and `y` as integers normalized to `[0, 1000]`. This example asks for a point on each cat and each remote control, then draws the points.
-
-```python
-import json
-import re
-from IPython.display import display
-from PIL import ImageDraw
-
-def parse_json(answer):
- match = re.search(r"\[.*\]", answer, flags=re.DOTALL)
- return json.loads(match.group(0)) if match else []
-
-messages = [
- {
- "role": "user",
- "content": [
- {"type": "image", "image": input_image},
- {
- "type": "text",
- "text": 'Point to each cat and each remote control. Answer in JSON as a list of points: [{"point_2d": [x, y], "label": ""}, ...], with x and y as integers normalized to 0-1000.',
- },
- ],
- }
-]
-
-_, answer = generate(messages)
-print(answer)
-
-points = parse_json(answer)
-annotated = input_image.copy()
-draw = ImageDraw.Draw(annotated)
-width, height = annotated.size
-for point in points:
- x, y = point["point_2d"]
- px, py = x / 1000 * width, y / 1000 * height
- draw.ellipse((px - 8, py - 8, px + 8, py + 8), fill="red", outline="white", width=2)
- draw.text((px + 12, py - 8), point.get("label", ""), fill="red")
-display(annotated)
-```
-
-**Output**
-
-```text
-[{"point_2d": [260, 500], "label": "cat"}, {"point_2d": [720, 400], "label": "cat"}, {"point_2d": [168, 195], "label": "remote control"}, {"point_2d": [550, 270], "label": "remote control"}]
-```
-
-
-
-## Object detection and grounding
-
-Grounding asks the model to localize visible objects with bounding boxes. This example uses the same image, asks for boxes in `[xmin, ymin, xmax, ymax]` format normalized to `[0, 1000]`, then draws the returned boxes.
-
-> **Coordinate format:** Convert normalized coordinates back to pixels with `x / 1000 * width` and `y / 1000 * height`. Points and boxes are approximate, so visually inspect the result before using coordinates in downstream workflows.
-
-```python
-system_prompt = """When asked for bounding boxes for objects, return a valid JSON array.
-Each array item must be an object with:
-- bbox_2d: [xmin, ymin, xmax, ymax] normalized integer coordinates in [0, 1000]
-- label: a concise label you choose for the predicted object or region
-
-Return one item per visible matching object or region. Return [] if none are visible."""
-
-messages = [
- {"role": "system", "content": system_prompt},
- {
- "role": "user",
- "content": [
- {"type": "image", "image": input_image},
- {"type": "text", "text": "Provide bounding boxes for the two cats and the two remote controls."},
- ],
- },
-]
-
-_, answer = generate(messages)
-print(answer)
-
-objects = parse_json(answer)
-annotated = input_image.copy()
-draw = ImageDraw.Draw(annotated)
-for obj in objects:
- xmin, ymin, xmax, ymax = obj["bbox_2d"]
- box = (xmin / 1000 * width, ymin / 1000 * height, xmax / 1000 * width, ymax / 1000 * height)
- draw.rectangle(box, outline="red", width=3)
- draw.text((box[0] + 4, box[1] + 4), obj.get("label", ""), fill="red")
-display(annotated)
-```
-
-**Output**
-
-```text
-[{"bbox_2d": [15, 113, 497, 987], "label": "cat"}, {"bbox_2d": [536, 46, 999, 776], "label": "cat"}, {"bbox_2d": [62, 145, 276, 245], "label": "remote control"}, {"bbox_2d": [519, 156, 585, 393], "label": "remote control"}]
-```
-
-
-
-## Video understanding
-
-LFM3-VL takes video as input. Videos are processed at their native resolution: they are sampled at 2 frames per second, consecutive frames are paired, and each frame is prefixed with its timestamp. Pass a local video path with `{"type": "video", "video": ...}`. This example uses a short clip from the Hugging Face test videos.
-
-```python
-from huggingface_hub import hf_hub_download
-
-video_path = hf_hub_download("raushan-testing-hf/videos-test", "sample_demo_1.mp4", repo_type="dataset")
-
-messages = [
- {
- "role": "user",
- "content": [
- {"type": "video", "video": video_path},
- {"type": "text", "text": "Describe what happens in this video."},
- ],
- }
-]
-
-_, answer = generate(messages)
-print(answer)
```
-**Output**
-
-
-
-```text
-In this short home-video clip, a young blonde toddler is sitting on a bed covered with a patterned quilt, apparently "reading" a small paperback book. The baby is dressed in a light blue/mint sleeveless top and pink pants, and is wearing a pair of large dark-framed eyeglasses that make her look like a little reader. Behind her you can see a wooden crib or chair and some folded clothes and fabric on the bed.
-
-At the start, the child holds the open book in her lap and gazes down at the pages. Around the middle of the clip she becomes animated—she lifts her hands and claps/waves them excitedly, as if reacting to something or getting absorbed in her activity. After a moment she brings her hands back down to the book and begins turning the pages one by one, looking attentively at the text as though reading. She continues to flip through the pages and study them until the end of the clip. Overall, the video shows a baby wearing glasses sitting on a bed and pretending to read, pausing briefly to clap her hands before going back to turning the pages of the book.
-```
-
-To also use a video's soundtrack, use LFM3-Omni-2B. See [Omni Capabilities](/lfm/key-concepts/omni-capabilities#video).
-
-## Tool calling
-
-In this example, the model sees an image and can route the request to the most relevant tool. Pass the tool schemas to `apply_chat_template()` with `tools=...`. LFM3-VL writes each call between `` and ``, with the function name in a `` tag and each argument in a `` tag.
+
+
```python
-tools = [
- {
- "type": "function",
- "function": {
- "name": "search_pet_care",
- "description": "Search for care guidance for an animal visible in an image.",
- "parameters": {
- "type": "object",
- "properties": {
- "animal": {"type": "string", "description": "The animal visible in the image"},
- "topic": {"type": "string", "description": "The care topic to search for"},
- },
- "required": ["animal", "topic"],
- },
- },
- },
- {
- "type": "function",
- "function": {
- "name": "search_replacement_remote",
- "description": "Search for replacement remote controls or remote-control accessories visible in an image.",
- "parameters": {
- "type": "object",
- "properties": {
- "item": {"type": "string", "description": "The remote-control item to search for"},
- "quantity": {"type": "integer", "description": "How many matching items are visible"},
- },
- "required": ["item"],
- },
- },
- },
-]
+# Apply chat template
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
-messages = [
- {
- "role": "user",
- "content": [
- {"type": "image", "image": input_image},
- {"type": "text", "text": "Find a care guide for the animals in this image. Choose the best tool for this request."},
- ],
- }
-]
+with torch.inference_mode():
+ outputs = model.generate(
+ **inputs,
+ do_sample=True,
+ temperature=0.1,
+ top_k=50,
+ repetition_penalty=1.1,
+ max_new_tokens=8192,
+ )
-_, answer = generate(messages, tools=tools)
+text = processor.decode(outputs[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+answer = text.partition("")[2].strip()
print(answer)
```
**Output**
```text
-
-
-
-cat
-
-
-care
-
-
-
-```
-
-Execute the call in your application, add the parsed call to the conversation as a `tool_calls` entry, and return the result as a `tool` message. See [Tool Use](/lfm/key-concepts/tool-use) for the full workflow.
-
-## LFM2.5-VL
-
-LFM2.5-VL models answer directly without a reasoning trace and use the LFM2.5 tool call format. LFM2.5-VL-3B also returns document layout annotations.
-
-Install PyTorch, Transformers, and the image-processing packages used by the examples. `torchvision` and `Pillow` are required by the LFM2.5-VL image processor, and `opencv-python` is used to draw grounding and layout boxes.
-
-```python
-# Install PyTorch and acceleration libraries
-%pip install -q torch torchvision accelerate
+**Media-1:** An open hand cradles a small cluster of glossy, multicolored beads—turquoise, orange, and green—some stamped with dark engraved symbols.
-# Install image helper libraries
-%pip install -q pillow opencv-python
-
-# Install Transformers
-%pip install -q "transformers>=5.10.1"
-```
-
-Load the model with `AutoProcessor` and `AutoModelForImageTextToText`, matching the standard LFM2.5-VL documentation examples. Start with `LiquidAI/LFM2.5-VL-450M` or `LiquidAI/LFM2.5-VL-1.6B` for fast iteration. Use LFM2.5-VL-3B for the strongest grounding, layout parsing, and tool-calling examples.
-
-```python
-from transformers import AutoProcessor, AutoModelForImageTextToText
-
-MODEL_ID = "LiquidAI/LFM2.5-VL-3B" # "LiquidAI/LFM2.5-VL-450M", "LiquidAI/LFM2.5-VL-1.6B", "LiquidAI/LFM2.5-VL-3B"
-
-processor = AutoProcessor.from_pretrained(MODEL_ID)
-model = AutoModelForImageTextToText.from_pretrained(
- MODEL_ID,
- device_map="auto",
- dtype="bfloat16",
-)
+**Media-2:** Two tabby cats are sprawled out asleep on a vivid pink couch, with a couple of TV remotes resting nearby.
```
-### LFM2.5-VL single-image prompt
-
-Provide one image and a text question in the same user message. This pattern is useful for captioning, visual question answering, and scene understanding.
+
+
```python
-import torch
-from IPython.display import display
-from transformers.image_utils import load_image
-
-img_url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/coco_sample.png"
-input_image = load_image(img_url)
-display(input_image)
-
-messages = [
- {
- "role": "user",
- "content": [
- {"type": "image", "image": input_image},
- {"type": "text", "text": "Describe this image in two concise sentences."},
- ],
- }
-]
-
+# Apply chat template
inputs = processor.apply_chat_template(
messages,
add_generation_prompt=True,
@@ -510,49 +262,50 @@ with torch.inference_mode():
max_new_tokens=256,
)
-output = processor.batch_decode(outputs[:, inputs["input_ids"].shape[1]:], skip_special_tokens=True)[0]
-print(output)
+answer = processor.decode(outputs[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+print(answer)
```
**Output**
-
-
```text
-Two cats are sleeping on a pink couch with two remote controls.
+Media-1: A person holds a handful of colorful M&Ms featuring bee and leaf designs in their palm.
+
+Media-2: Two cats are peacefully sleeping on a pink couch, each with a remote control nearby.
```
-### LFM2.5-VL multi-image prompt
-**Model support:** This capability is best supported by LFM2.5-VL-3B.
+
+
-You can include multiple images in a single prompt. Label each image in the prompt, such as `Media-1` and `Media-2`, to make cross-image references clearer.
+## OCR
-```python
-import torch
-from IPython.display import display
-from transformers.image_utils import load_image
+LFM vision models read text in document images and screenshots. OCR works best when text is legible and the image is not blurry, rotated, or heavily compressed. For dense documents, crop to the relevant page or region when possible.
-img_urls = [
- "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/p-blog/candy.JPG",
- "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/coco_sample.png",
-]
-input_images = [load_image(img_url) for img_url in img_urls]
-for input_image in input_images:
- display(input_image)
+
+
+```python
+img_url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/enterprise/audit-logs.png"
+document_image = load_image(img_url)
messages = [
{
"role": "user",
"content": [
- {"type": "text", "text": "Media-1\n"},
- {"type": "image", "image": input_images[0]},
- {"type": "text", "text": "\nMedia-2\n"},
- {"type": "image", "image": input_images[1]},
- {"type": "text", "text": "\nCaption Media-1 and Media-2 separately. Keep each caption to one sentence."},
+ {"type": "image", "image": document_image},
+ {
+ "type": "text",
+ "text": "Read this audit log screenshot. Identify the page heading, table columns, visible rows, users, actions, timestamps, and other structured fields. Transcribe the visible text in reading order.",
+ },
],
}
]
+```
+
+
+
+```python
+# Apply chat template
inputs = processor.apply_chat_template(
messages,
add_generation_prompt=True,
@@ -565,59 +318,52 @@ with torch.inference_mode():
outputs = model.generate(
**inputs,
do_sample=True,
- temperature=0.2,
+ temperature=0.1,
top_k=50,
- repetition_penalty=1.0,
- max_new_tokens=256,
+ repetition_penalty=1.1,
+ max_new_tokens=8192,
)
-output = processor.batch_decode(outputs[:, inputs["input_ids"].shape[1]:], skip_special_tokens=True)[0]
-print(output)
+text = processor.decode(outputs[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+answer = text.partition("")[2].strip()
+print(answer)
```
-**Output**
-
-
-
-
-
+**Output** (truncated)
```text
-Media-1: A person is holding a collection of colorful M&M's with various designs on them.
-
-Media-2: Two cats are peacefully sleeping on a pink couch, each with a remote control nearby.
+**Page heading:** Audit log
+
+**Table:** Events log (with a “Download as JSON” button on the right)
+
+**Table columns:**
+- User
+- Event / Action
+- Description / Message
+- Location
+- IP Address
+- Timestamp
+
+**Visible rows:**
+
+| User | Event / Action | Description | Location | IP Address | Timestamp |
+|------|----------------|-------------|-----------|------------|-----------|
+| cbooetticher | org.update_join_settings | cbooetticher enabled join requests with manual approval and set default role to write | United States, Austin | 136.62.181.0 | On Oct 15 |
+| cbooetticher | repo.delete | cbooetticher deleted a model: enterprise-explorers/test_model | United States, Austin | 136.62.181.0 | On Oct 10 |
+| cbooetticher | repo.create | cbooetticher created a public model: enterprise-explorers/test_model | United States, Austin | 136.62.181.0 | On Oct 10 |
+| System | billing.renew_subscription | System Automatic subscription renewal for hf/enterprise-free | Unknown Location | – | On Oct 7 |
+| derek-thomas | resource_group.add_users | derek-thomas added users to resource group Read access members: derek-thomas (read) | United Arab Emirates, Abu Dhabi | 217.164.173.0 | On Sep 17 |
+| erikrigner | resource_group.change_role | erikrigner changed role for user erikrigner in resource group Read access members from write to admin | Sweden, Norrköping | 2a02:1406:59:d60:0:dfd:0:0 | On Sep 16 |
+
+**Other structured fields noted:**
+...
```
-### LFM2.5-VL OCR
-
-**Model support:** This capability is best supported by LFM2.5-VL-3B.
-
-LFM2.5-VL can read text in document images and, with LFM2.5-VL-3B, return structured layout annotations, which can be used to visualize the parsed layout regions.
-
-> **Image quality:** OCR and layout parsing work best when text is legible and the image is not blurry, rotated, or heavily compressed. For dense documents, crop to the relevant page or region when possible.
+
+
```python
-import torch
-from IPython.display import display
-from transformers.image_utils import load_image
-
-img_url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/enterprise/audit-logs.png"
-input_image = load_image(img_url)
-display(input_image)
-
-messages = [
- {
- "role": "user",
- "content": [
- {"type": "image", "image": input_image},
- {
- "type": "text",
- "text": "Read this audit log screenshot. Identify the page heading, table columns, visible rows, users, actions, timestamps, and other structured fields. Transcribe the visible text in reading order.",
- },
- ],
- }
-]
-
+# Apply chat template
inputs = processor.apply_chat_template(
messages,
add_generation_prompt=True,
@@ -630,69 +376,59 @@ with torch.inference_mode():
outputs = model.generate(
**inputs,
do_sample=True,
- temperature=0.1,
+ temperature=0.2,
top_k=50,
- repetition_penalty=1.05,
+ repetition_penalty=1.0,
max_new_tokens=512,
)
-generated_ids = outputs[:, inputs["input_ids"].shape[1] :]
-output = processor.batch_decode(generated_ids, skip_special_tokens=True)[0]
-print(output)
+answer = processor.decode(outputs[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+print(answer)
```
**Output**
-
-
```text
Audit log
-| Events log |
-| --- |
-| clboetticher org.update_join_settings |
-| clboetticher enabled join requests with manual approval and set default role to write |
-| United States, Austin · 136.62.181.0 · On Oct 15 |
-| clboetticher repo.delete |
-| clboetticher deleted a model: enterprise-explorers/test_model |
-| United States, Austin · 136.62.181.0 · On Oct 10 |
-| clboetticher repo.create |
-| clboetticher created a public model: enterprise-explorers/test_model |
-| United States, Austin · 136.62.181.0 · On Oct 10 |
-| System billing.renew_subscription |
-| System Automatic subscription renewal for hf/enterprise-free |
-| Unknown Location · On Oct 7 |
-| derek-thomas resource_group.add_users |
-| derek-thomas added users to resource group Read access members: derek-thomas (read) |
-| United Arab Emirates, Abu Dhabi · 217.164.173.0 · On Sep 17 |
-| erikrigner resource_group.change_role |
-| erikrigner changed role for user erikrigner in resource group Read access members from write to admin |
-| Sweden, Norrköping · 2a02:1406:59:5d60:1dfd:0:0 · On Sep 16 |
-```
-
-### Document layout annotations
-
-For document understanding tasks, LFM2.5-VL-3B can return OCR with layout annotations. Each region contains a label, normalized bounding box, and content:
+| Events log | Download as JSON |
+| --- | --- |
+| clboetticher org.update_join_settings | |
+| clboetticher enabled join requests with manual approval and set default role to write | United States, Austin · 136.62.181.0 · On Oct 15 |
+| clboetticher repo.delete | |
+| clboetticher deleted a model: enterprise-explorers/test_model | United States, Austin · 136.62.181.0 · On Oct 10 |
+| clboetticher repo.create | |
+| clboetticher created a public model: enterprise-explorers/test_model | United States, Austin · 136.62.181.0 · On Oct 10 |
+| System billing.renew_subscription | |
+| System Automatic subscription renewal for hf/enterprise-free | Unknown Location · On Oct 7 |
+| derek-thomas resource_group.add_users | |
+| derek-thomas added users to resource group Read access members: derek-thomas (read) | United Arab Emirates, Abu Dhabi · 217.164.173.0 · On Sep 17 |
+| erikrigner resource_group.change_role | |
+| erikrigner changed role for user erikrigner in resource group Read access members from write to admin | Sweden, Norrköping · 2a02:1406:59:5d60:1dfd:0:0 · On Sep 16 |
+```
+
+
+
+
+## Document layout annotations
+
+Layout annotations require a vision model with layout support. Check the model page before you use this example.
+
+For document understanding tasks, a compatible vision model can return OCR with layout annotations. Each region contains a label, normalized bounding box, and content:
```text
image_index=")[2].strip()
+print(answer)
+
+points = json.loads(re.search(r"\[.*\]", answer, flags=re.DOTALL).group(0))
+annotated = input_image.copy()
+draw = ImageDraw.Draw(annotated)
+width, height = annotated.size
+for point in points:
+ x, y = point["point_2d"]
+ px, py = x / 1000 * width, y / 1000 * height
+ draw.ellipse((px - 8, py - 8, px + 8, py + 8), fill="red", outline="white", width=2)
+ draw.text((px + 12, py - 8), point.get("label", ""), fill="red")
+display(annotated)
+```
+
+**Output**
+
+```text
+[{"point_2d": [258, 542], "label": "cat"}, {"point_2d": [770, 420], "label": "cat"}, {"point_2d": [168, 196], "label": "remote control"}, {"point_2d": [551, 272], "label": "remote control"}]
+```
+
+
+
+## Object detection and grounding
+
+Grounding asks the model to localize visible objects with bounding boxes. This example uses the cat photo from [Single-image prompt](#single-image-prompt), asks for boxes in `[xmin, ymin, xmax, ymax]` format normalized to `[0, 1000]`, then draws the returned boxes.
+
+Convert normalized coordinates back to pixels with `x / 1000 * width` and `y / 1000 * height`. Boxes are approximate, so visually inspect the result before using coordinates in downstream workflows.
+
+```python
+import json
+import re
+from IPython.display import display
+from PIL import ImageDraw
system_prompt = """When asked for bounding boxes for objects, return a valid JSON array.
Each array item must be an object with:
-- image_id: the 0-based index of the image
- bbox_2d: [xmin, ymin, xmax, ymax] normalized integer coordinates in [0, 1000]
- label: a concise label you choose for the predicted object or region
@@ -823,7 +614,47 @@ messages = [
],
},
]
+```
+
+
+
+
+```python
+# Apply chat template
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+with torch.inference_mode():
+ outputs = model.generate(
+ **inputs,
+ do_sample=True,
+ temperature=0.1,
+ top_k=50,
+ repetition_penalty=1.1,
+ max_new_tokens=8192,
+ )
+
+text = processor.decode(outputs[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+answer = text.partition("")[2].strip()
+print(answer)
+```
+
+**Output**
+
+```text
+[{"bbox_2d": [15, 110, 497, 987], "label": "cat"}, {"bbox_2d": [533, 46, 999, 776], "label": "cat"}, {"bbox_2d": [62, 145, 276, 245], "label": "remote control"}, {"bbox_2d": [519, 156, 585, 393], "label": "remote control"}]
+```
+
+
+
+```python
+# Apply chat template
inputs = processor.apply_chat_template(
messages,
add_generation_prompt=True,
@@ -842,92 +673,166 @@ with torch.inference_mode():
max_new_tokens=256,
)
-output = processor.batch_decode(
- outputs[:, inputs["input_ids"].shape[1]:],
- skip_special_tokens=True,
-)[0]
-print(output)
+answer = processor.decode(outputs[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+print(answer)
+```
-objects = json.loads(output)
-print(objects)
+**Output**
-image = np.array(input_image).copy()
-height, width = image.shape[:2]
+```text
+[{"image_id": 0, "bbox_2d": [543, 49, 1000, 774], "label": "cat on the right"}, {"image_id": 0, "bbox_2d": [10, 112, 496, 986], "label": "cat on the left"}, {"image_id": 0, "bbox_2d": [523, 158, 581, 399], "label": "remote on the right"}, {"image_id": 0, "bbox_2d": [63, 151, 276, 244], "label": "remote on the left"}]
+```
+
+
+
+Then draw the boxes:
+
+```python
+objects = json.loads(re.search(r"\[.*\]", answer, flags=re.DOTALL).group(0))
+annotated = input_image.copy()
+draw = ImageDraw.Draw(annotated)
+width, height = annotated.size
for obj in objects:
xmin, ymin, xmax, ymax = obj["bbox_2d"]
- pt1 = (round(xmin / 1000 * width), round(ymin / 1000 * height))
- pt2 = (round(xmax / 1000 * width), round(ymax / 1000 * height))
- cv2.rectangle(image, pt1, pt2, color=(255, 0, 0), thickness=3)
- cv2.putText(image, obj["label"], (pt1[0], max(20, pt1[1] - 8)), cv2.FONT_HERSHEY_SIMPLEX, 0.8, (255, 0, 0), 2)
+ box = (xmin / 1000 * width, ymin / 1000 * height, xmax / 1000 * width, ymax / 1000 * height)
+ draw.rectangle(box, outline="red", width=3)
+ draw.text((box[0] + 4, box[1] + 4), obj.get("label", ""), fill="red")
+display(annotated)
+```
-display(Image.fromarray(image))
+
+
+
+
+
+
+
+
+
+
+
+
+
+## Ask about an image by voice
+
+Spoken questions about an image require an omni model with image and audio input. Load it as shown in [Audio Capabilities](/lfm/key-concepts/audio-capabilities#setup).
+
+An omni model can understand images and speech in the same turn, so the question can be a recording instead of text.
+
+Recommended system prompts: `Describe the provided image.` for captions, and `Answer questions about the provided image. Base every answer only on what can be seen.` for questions. When the answer should be in a different modality from the question, add an output instruction after the task prompt, for example `Respond with text.`
+
+This example first records a spoken question with [text-to-speech](/lfm/key-concepts/speech-generation#text-to-speech), then asks it about a photo:
+
+```python
+tts_messages = [
+ {"role": "system", "content": "Perform TTS in American English using a female voice."},
+ {"role": "user", "content": "What is this tiny garden visitor doing?"},
+]
+
+# Apply chat template
+inputs = processor.apply_chat_template(
+ tts_messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+torch.manual_seed(0)
+with torch.inference_mode():
+ outputs = model.generate(
+ **inputs,
+ max_new_tokens=512,
+ generation_mode="audio",
+ audio_temperature=0.4,
+ audio_repetition_penalty=1.2,
+ audio_repetition_window=64,
+ )
+
+codes = outputs.audio_codes[:1, :, : outputs.audio_lengths[0]]
+with torch.inference_mode():
+ speech = codec.decode(codes).audio_values[0].float().cpu().numpy().squeeze()
+sf.write("question.wav", speech, 24_000)
+```
+
+
+
+```python
+from transformers.image_utils import load_image
+
+load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg").save("bee.jpg")
+
+messages = [
+ {"role": "system", "content": "Answer questions about the provided image. Base every answer only on what can be seen. Respond with text."},
+ {"role": "user", "content": [{"type": "image", "image": "bee.jpg"}, {"type": "audio", "audio": "question.wav"}]},
+]
+
+# Apply chat template
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+with torch.inference_mode():
+ outputs = model.generate(**inputs, max_new_tokens=512, generation_mode="text")
+
+answer = processor.decode(outputs.sequences[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+print(answer)
```
**Output**
```text
-[{"image_id": 0, "bbox_2d": [540, 49, 1000, 774], "label": "cat on the right"}, {"image_id": 0, "bbox_2d": [10, 112, 497, 986], "label": "cat on the left"}, {"image_id": 0, "bbox_2d": [523, 158, 581, 398], "label": "remote on the right"}, {"image_id": 0, "bbox_2d": [63, 150, 276, 244], "label": "remote on the left"}]
-[{'image_id': 0, 'bbox_2d': [540, 49, 1000, 774], 'label': 'cat on the right'}, {'image_id': 0, 'bbox_2d': [10, 112, 497, 986], 'label': 'cat on the left'}, {'image_id': 0, 'bbox_2d': [523, 158, 581, 398], 'label': 'remote on the right'}, {'image_id': 0, 'bbox_2d': [63, 150, 276, 244], 'label': 'remote on the left'}]
-```
+The tiny garden visitor in the image is a **bee** (a bumblebee, identifiable by its black body with yellow-orange bands and fuzzy white abdomen) perched on the center of a pink cosmos flower.
+
+Specifically, it is **feeding on nectar** — the bee is resting on the bright orange-yellow disc (the central cluster of stamens) of the bloom, using its proboscis to sip nectar from the flower. This is a typical pollination activity: bees gather nectar and pollen from flowers like this cosmos, and in doing so they transfer pollen, helping the plant reproduce.
-
+So, in short: the "tiny garden visitor" is **collecting nectar from a flower**.
+```
-### LFM2.5-VL tool calling
+To get a spoken answer instead, see [Speech Generation](/lfm/key-concepts/speech-generation#answer-in-speech).
-**Model support:** This capability is best supported by LFM2.5-VL-3B.
+## Video understanding
-In this example, the model sees an image and can route the request to the most relevant tool. The tool schemas are generic enough to adapt to real catalog, search, or workflow APIs.
+Video-capable models can answer questions using a clip's frames. Check the model page for the default frame rate and frame limits. Install `torchcodec` and FFmpeg for video decoding in addition to the packages in [Setup](#setup):
```python
-import torch
-from IPython.display import display
-from transformers.image_utils import load_image
+%pip install -q torchcodec
+```
-img_url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/coco_sample.png"
-input_image = load_image(img_url)
-display(input_image)
+### Describe a video
-tools = [
- {
- "name": "search_pet_care",
- "description": "Search for care guidance for an animal visible in an image.",
- "parameters": {
- "type": "object",
- "properties": {
- "animal": {"type": "string", "description": "The animal visible in the image"},
- "topic": {"type": "string", "description": "The care topic to search for"},
- },
- "required": ["animal", "topic"],
- },
- },
- {
- "name": "search_replacement_remote",
- "description": "Search for replacement remote controls or remote-control accessories visible in an image.",
- "parameters": {
- "type": "object",
- "properties": {
- "item": {"type": "string", "description": "The remote-control item to search for"},
- "quantity": {"type": "integer", "description": "How many matching items are visible"},
- },
- "required": ["item"],
- },
- },
-]
+Pass a local path with `{"type": "video", "video": ...}`. This example downloads a short [sample clip](https://huggingface.co/datasets/raushan-testing-hf/videos-test):
+
+
+
+```python
+from huggingface_hub import hf_hub_download
+
+video_path = hf_hub_download("raushan-testing-hf/videos-test", "sample_demo_1.mp4", repo_type="dataset")
messages = [
{
"role": "user",
"content": [
- {"type": "image", "image": input_image},
- {"type": "text", "text": "Find a care guide for the animals in this image. Choose the best tool for this request."},
+ {"type": "video", "video": video_path},
+ {"type": "text", "text": "Describe what happens in this video."},
],
}
]
+```
+
+
+
+```python
+# Apply chat template
inputs = processor.apply_chat_template(
messages,
- tools=tools,
add_generation_prompt=True,
tokenize=True,
return_dict=True,
@@ -938,53 +843,97 @@ with torch.inference_mode():
outputs = model.generate(
**inputs,
do_sample=True,
- temperature=0.2,
+ temperature=0.1,
top_k=50,
- repetition_penalty=1.0,
- max_new_tokens=256,
+ repetition_penalty=1.1,
+ max_new_tokens=8192,
)
-output = processor.tokenizer.decode(
- outputs[0, inputs["input_ids"].shape[1]:],
- skip_special_tokens=False,
-)
-print(output)
+text = processor.decode(outputs[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+answer = text.partition("")[2].strip()
+print(answer)
```
**Output**
-
+```text
+In this short home-video clip, a young blonde toddler—wearing dark-framed eyeglasses, a light blue/mint sleeveless top, and pink pants—is seated on a bed covered with a patterned quilt. The child is holding an open paperback book on her lap, apparently "reading." At the start she gazes down at the pages, but then she lifts both hands up in front of her face and claps/waves them excitedly for a couple of seconds. After that brief gesture, she brings her attention back to the book, gripping the edges of the pages and turning/flipping through them while continuing to look down at the text. The background shows a bedroom setting with a wooden crib or railing, some white clothing draped nearby, a television/monitor, and a striped shirt hanging at the right, and the footage carries a "clideo.com" watermark. Overall, the video depicts a baby in glasses sitting on a bed, fiddling with and turning the pages of a book, with a little pause where she claps her hands before resuming her "reading."
+```
+
+
+
+
+These models do not take video input. To ask about a short clip, extract frames and pass them as images, as in [Multi-image prompt](#multi-image-prompt).
+
+
+
+
+### Use the soundtrack
+
+Soundtrack input requires an omni model with video and audio input. Load it as shown in [Audio Capabilities](/lfm/key-concepts/audio-capabilities#setup).
+
+An omni model can also use a video's soundtrack. Pass `load_audio_from_video=True` and `processor_kwargs={"use_audio_in_video": True}` so the processor interleaves the soundtrack with the frames:
+
+```python
+messages = [
+ {"role": "system", "content": "Answer questions about the video using what you see and hear."},
+ {
+ "role": "user",
+ "content": [
+ {"type": "video", "video": video_path},
+ {"type": "text", "text": "What happens in this video, and what can you hear?"},
+ ],
+ },
+]
+
+# Apply chat template
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+ load_audio_from_video=True,
+ processor_kwargs={"use_audio_in_video": True},
+).to(model.device)
+
+with torch.inference_mode():
+ outputs = model.generate(**inputs, max_new_tokens=256, generation_mode="text")
+
+answer = processor.decode(outputs.sequences[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+print(answer)
+```
+
+**Output**
```text
-<|tool_call_start|>[search_pet_care(animal="cat", topic="sleeping")]<|tool_call_end|><|im_end|>
+In this video, a young toddler with blonde hair, wearing dark-framed glasses and a light blue sleeveless top, sits on a bed and reads an open picture book. The child holds the pages with both hands, turns them, and occasionally looks up and smiles or laughs while talking. In the background, there's a crib, a white blanket, and some clothing, and a "clideo.com" watermark appears in the bottom right corner.
+
+The only sound is the child's voice: she speaks in a high-pitched, playful tone, saying things like "Where?", "I want to look at the...", "Yeah, there's...", and "I want to...", as if narrating or asking questions about the book she's reading. Her laughter and excited speech match the animated way she turns the pages and glances up at the camera.
```
## FAQ
-**Which LFM vision model should I use?**
+**Which vision model should I use?**
-Use `LFM3-VL-2B` for most use cases, including video understanding, harder visual questions that benefit from reasoning, pointing, and grounding. Among LFM2.5-VL models, use `LFM2.5-VL-450M` or `LFM2.5-VL-1.6B` for fast image captioning and visual question answering, and `LFM2.5-VL-3B` for document layout parsing.
+Choose a vision model based on the task: a smaller model for fast captioning and visual questions, a model with layout support for documents, or a thinking model for harder questions and spatial tasks. Choose an omni model when the request also involves speech or a video's soundtrack. See the [model library](/lfm/models/complete-library) for current options.
**Can I turn off reasoning?**
-Yes, for LFM3-VL. Pass `enable_thinking=False` to `apply_chat_template()` for direct answers with lower latency. LFM2.5-VL models always answer directly.
-
-**What image and video formats are supported?**
-
-LFM vision models work with common image formats such as JPEG and PNG. In the examples above, images are loaded from Hugging Face URLs with `transformers.image_utils.load_image`. LFM3-VL also takes video files that `torchcodec` can decode, such as MP4.
+On models that support switching thinking off, pass `enable_thinking=False` to `apply_chat_template()` for direct answers with lower latency. See [Thinking](/lfm/key-concepts/thinking) for support and controls.
-**Can the models point at or localize objects?**
+**What image formats are supported?**
-Yes. Prompt LFM3-VL to return points as `{"point_2d": [x, y]}` or bounding boxes as `bbox_2d: [xmin, ymin, xmax, ymax]`, with coordinates normalized to `[0, 1000]`. LFM2.5-VL returns bounding boxes in the same format. Boxes and points are approximate and can vary with prompt wording, image resolution, and generation settings. For workflows that require precise localization, inspect the returned coordinates and validate them against the original image.
+LFM vision models work with common image formats such as JPEG and PNG. In the examples above, images are loaded from Hugging Face URLs with `transformers.image_utils.load_image`.
-**Can the models parse documents?**
+**What video formats are supported?**
-Yes. LFM3-VL reads visible text in documents and screenshots. `LFM2.5-VL-3B` can also return document layout annotations, including region labels, bounding boxes, and extracted content.
+The video examples accept files that `torchcodec` can decode, such as MP4.
-**Can the models call tools based on an image?**
+**How precise are points and boxes?**
-Yes. You can provide tool schemas through the chat template and ask the model to choose the relevant tool based on the visual content. LFM3-VL uses the LFM3 `` format, and LFM2.5-VL uses the LFM2.5 format. See [Tool Use](/lfm/key-concepts/tool-use).
+Boxes and points are approximate and can vary with prompt wording, image resolution, and generation settings. For workflows that require precise localization, inspect the returned coordinates and validate them against the original image.
**Can the models generate or edit images?**
-No. LFM vision models are image and video understanding models. They can analyze images and videos, answer questions, read text, localize objects, parse layouts, and route tool calls, but they do not generate or edit images.
+No. LFM vision models are image and video understanding models. They can analyze images, answer questions, read text, localize objects, parse layouts, and route tool calls, but they do not generate or edit images.
diff --git a/lfm/models/audio-models.mdx b/lfm/models/audio-models.mdx
index d5123b69..ac171bd1 100644
--- a/lfm/models/audio-models.mdx
+++ b/lfm/models/audio-models.mdx
@@ -65,7 +65,15 @@ Learn how to use these models in your application:
- Speech recognition, speech synthesis, voice chat, translation, audio understanding, and spoken tool calling.
+ Transcribe and translate speech, answer spoken questions, and ask about speech, music, and sounds.
+
+
+
+ Text-to-speech, spoken chat, and spoken answers, with control over the output modality.
+
+
+
+ Call functions from text, images, and speech.
diff --git a/lfm/models/lfm3-audio-2b.mdx b/lfm/models/lfm3-audio-2b.mdx
index 8993b487..9e71a279 100644
--- a/lfm/models/lfm3-audio-2b.mdx
+++ b/lfm/models/lfm3-audio-2b.mdx
@@ -40,7 +40,7 @@ LFM3-Audio-2B is a compact, fully featured audio model that runs locally on lapt
Transcribe and synthesize speech in 18 languages
-
+
Questions about speech, sounds, and events in recordings
@@ -221,7 +221,7 @@ LFM3-Audio-2B is a compact, fully featured audio model that runs locally on lapt
print(text.strip())
```
- For more examples, see [Audio Capabilities](/lfm/key-concepts/audio-capabilities).
+ For more examples, see [Audio Capabilities](/lfm/key-concepts/audio-capabilities) and [Speech generation](/lfm/key-concepts/speech-generation).
diff --git a/lfm/models/lfm3-omni-2b.mdx b/lfm/models/lfm3-omni-2b.mdx
index 730898f8..2cbc44fa 100644
--- a/lfm/models/lfm3-omni-2b.mdx
+++ b/lfm/models/lfm3-omni-2b.mdx
@@ -153,7 +153,7 @@ LFM3-Omni-2B is Liquid AI's first omni model: a single end-to-end model that und
reply = processor.decode(out.sequences[0, inputs["input_ids"].shape[1] :], skip_special_tokens=True)
```
- For more examples, see [Omni Capabilities](/lfm/key-concepts/omni-capabilities).
+ For more examples, see [Audio Capabilities](/lfm/key-concepts/audio-capabilities), [Speech generation](/lfm/key-concepts/speech-generation), and [Vision Capabilities](/lfm/key-concepts/vision-capabilities) for images and video.
diff --git a/lfm/models/lfm3-vl-2b.mdx b/lfm/models/lfm3-vl-2b.mdx
index f13f665b..28e94b3c 100644
--- a/lfm/models/lfm3-vl-2b.mdx
+++ b/lfm/models/lfm3-vl-2b.mdx
@@ -77,6 +77,7 @@ LFM3-VL-2B is a vision-language model in the LFM3 family designed for on-device
}
]
+ # Apply chat template
inputs = processor.apply_chat_template(
messages,
add_generation_prompt=True,
diff --git a/lfm/models/omni-models.mdx b/lfm/models/omni-models.mdx
index ff599303..4e33d0d2 100644
--- a/lfm/models/omni-models.mdx
+++ b/lfm/models/omni-models.mdx
@@ -48,8 +48,16 @@ Learn how to use these models in your application:
-
- Speech, images, video with its soundtrack, audio understanding, and tool calling in one model.
+
+ Describe and compare images, read text, parse document layouts, point at objects, and detect objects.
+
+
+
+ Transcribe and translate speech, answer spoken questions, and ask about speech, music, and sounds.
+
+
+
+ Text-to-speech, spoken chat, and spoken answers, with control over the output modality.
diff --git a/lfm/models/vision-models.mdx b/lfm/models/vision-models.mdx
index 897bf198..2afe786a 100644
--- a/lfm/models/vision-models.mdx
+++ b/lfm/models/vision-models.mdx
@@ -77,7 +77,15 @@ Learn how to use these models in your application:
- Image and video understanding, multi-image prompts, OCR, layout annotations, pointing, grounding, and vision-guided tool calling.
+ Describe and compare images, read text, parse document layouts, point at objects, and detect objects.
+
+
+
+ Describe videos and answer questions about them, from the frames alone or with the soundtrack.
+
+
+
+ Call functions from text, images, and speech.
diff --git a/link-snapshot.yaml b/link-snapshot.yaml
index ca86101b..89093b68 100644
--- a/link-snapshot.yaml
+++ b/link-snapshot.yaml
@@ -175,6 +175,7 @@ active:
- /lfm/key-concepts/models
- /lfm/key-concepts/omni-capabilities
- /lfm/key-concepts/speculative-decoding
+ - /lfm/key-concepts/speech-generation
- /lfm/key-concepts/text-generation-and-prompting
- /lfm/key-concepts/thinking
- /lfm/key-concepts/tool-search
diff --git a/snippets/key-concepts/lfm25-chat-prompt.mdx b/snippets/key-concepts/lfm25-chat-prompt.mdx
new file mode 100644
index 00000000..5466480c
--- /dev/null
+++ b/snippets/key-concepts/lfm25-chat-prompt.mdx
@@ -0,0 +1,9 @@
+export const LFM25ChatPrompt = () => (
+
+{`<|startoftext|><|im_start|>system
+You are a helpful assistant trained by Liquid AI.<|im_end|>
+<|im_start|>user
+What is C. elegans?<|im_end|>
+<|im_start|>assistant`}
+
+);
diff --git a/snippets/key-concepts/tool-call-token-example.mdx b/snippets/key-concepts/lfm25-tool-call-example.mdx
similarity index 58%
rename from snippets/key-concepts/tool-call-token-example.mdx
rename to snippets/key-concepts/lfm25-tool-call-example.mdx
index 806342ab..8779852a 100644
--- a/snippets/key-concepts/tool-call-token-example.mdx
+++ b/snippets/key-concepts/lfm25-tool-call-example.mdx
@@ -1,5 +1,5 @@
-export const ToolCallTokenExample = () => (
-
+export const LFM25ToolCallExample = () => (
+
{`<|tool_call_start|>[get_candidate_status(candidate_id="12345")]<|tool_call_end|>`}
);
diff --git a/snippets/key-concepts/lfm3-chat-prompt.mdx b/snippets/key-concepts/lfm3-chat-prompt.mdx
new file mode 100644
index 00000000..f822bec8
--- /dev/null
+++ b/snippets/key-concepts/lfm3-chat-prompt.mdx
@@ -0,0 +1,10 @@
+export const LFM3ChatPrompt = () => (
+
+{`<|startoftext|><|im_start|>system
+You are a helpful assistant trained by Liquid AI.<|im_end|>
+<|im_start|>user
+What is C. elegans?<|im_end|>
+<|im_start|>assistant
+`}
+
+);
diff --git a/snippets/key-concepts/lfm3-tool-call-example.mdx b/snippets/key-concepts/lfm3-tool-call-example.mdx
new file mode 100644
index 00000000..747b0cfd
--- /dev/null
+++ b/snippets/key-concepts/lfm3-tool-call-example.mdx
@@ -0,0 +1,11 @@
+export const LFM3ToolCallExample = () => (
+
+{`
+
+
+12345
+
+
+`}
+
+);
 +
 +